How CBRN Risk Evaluations Get Built for Frontier Models
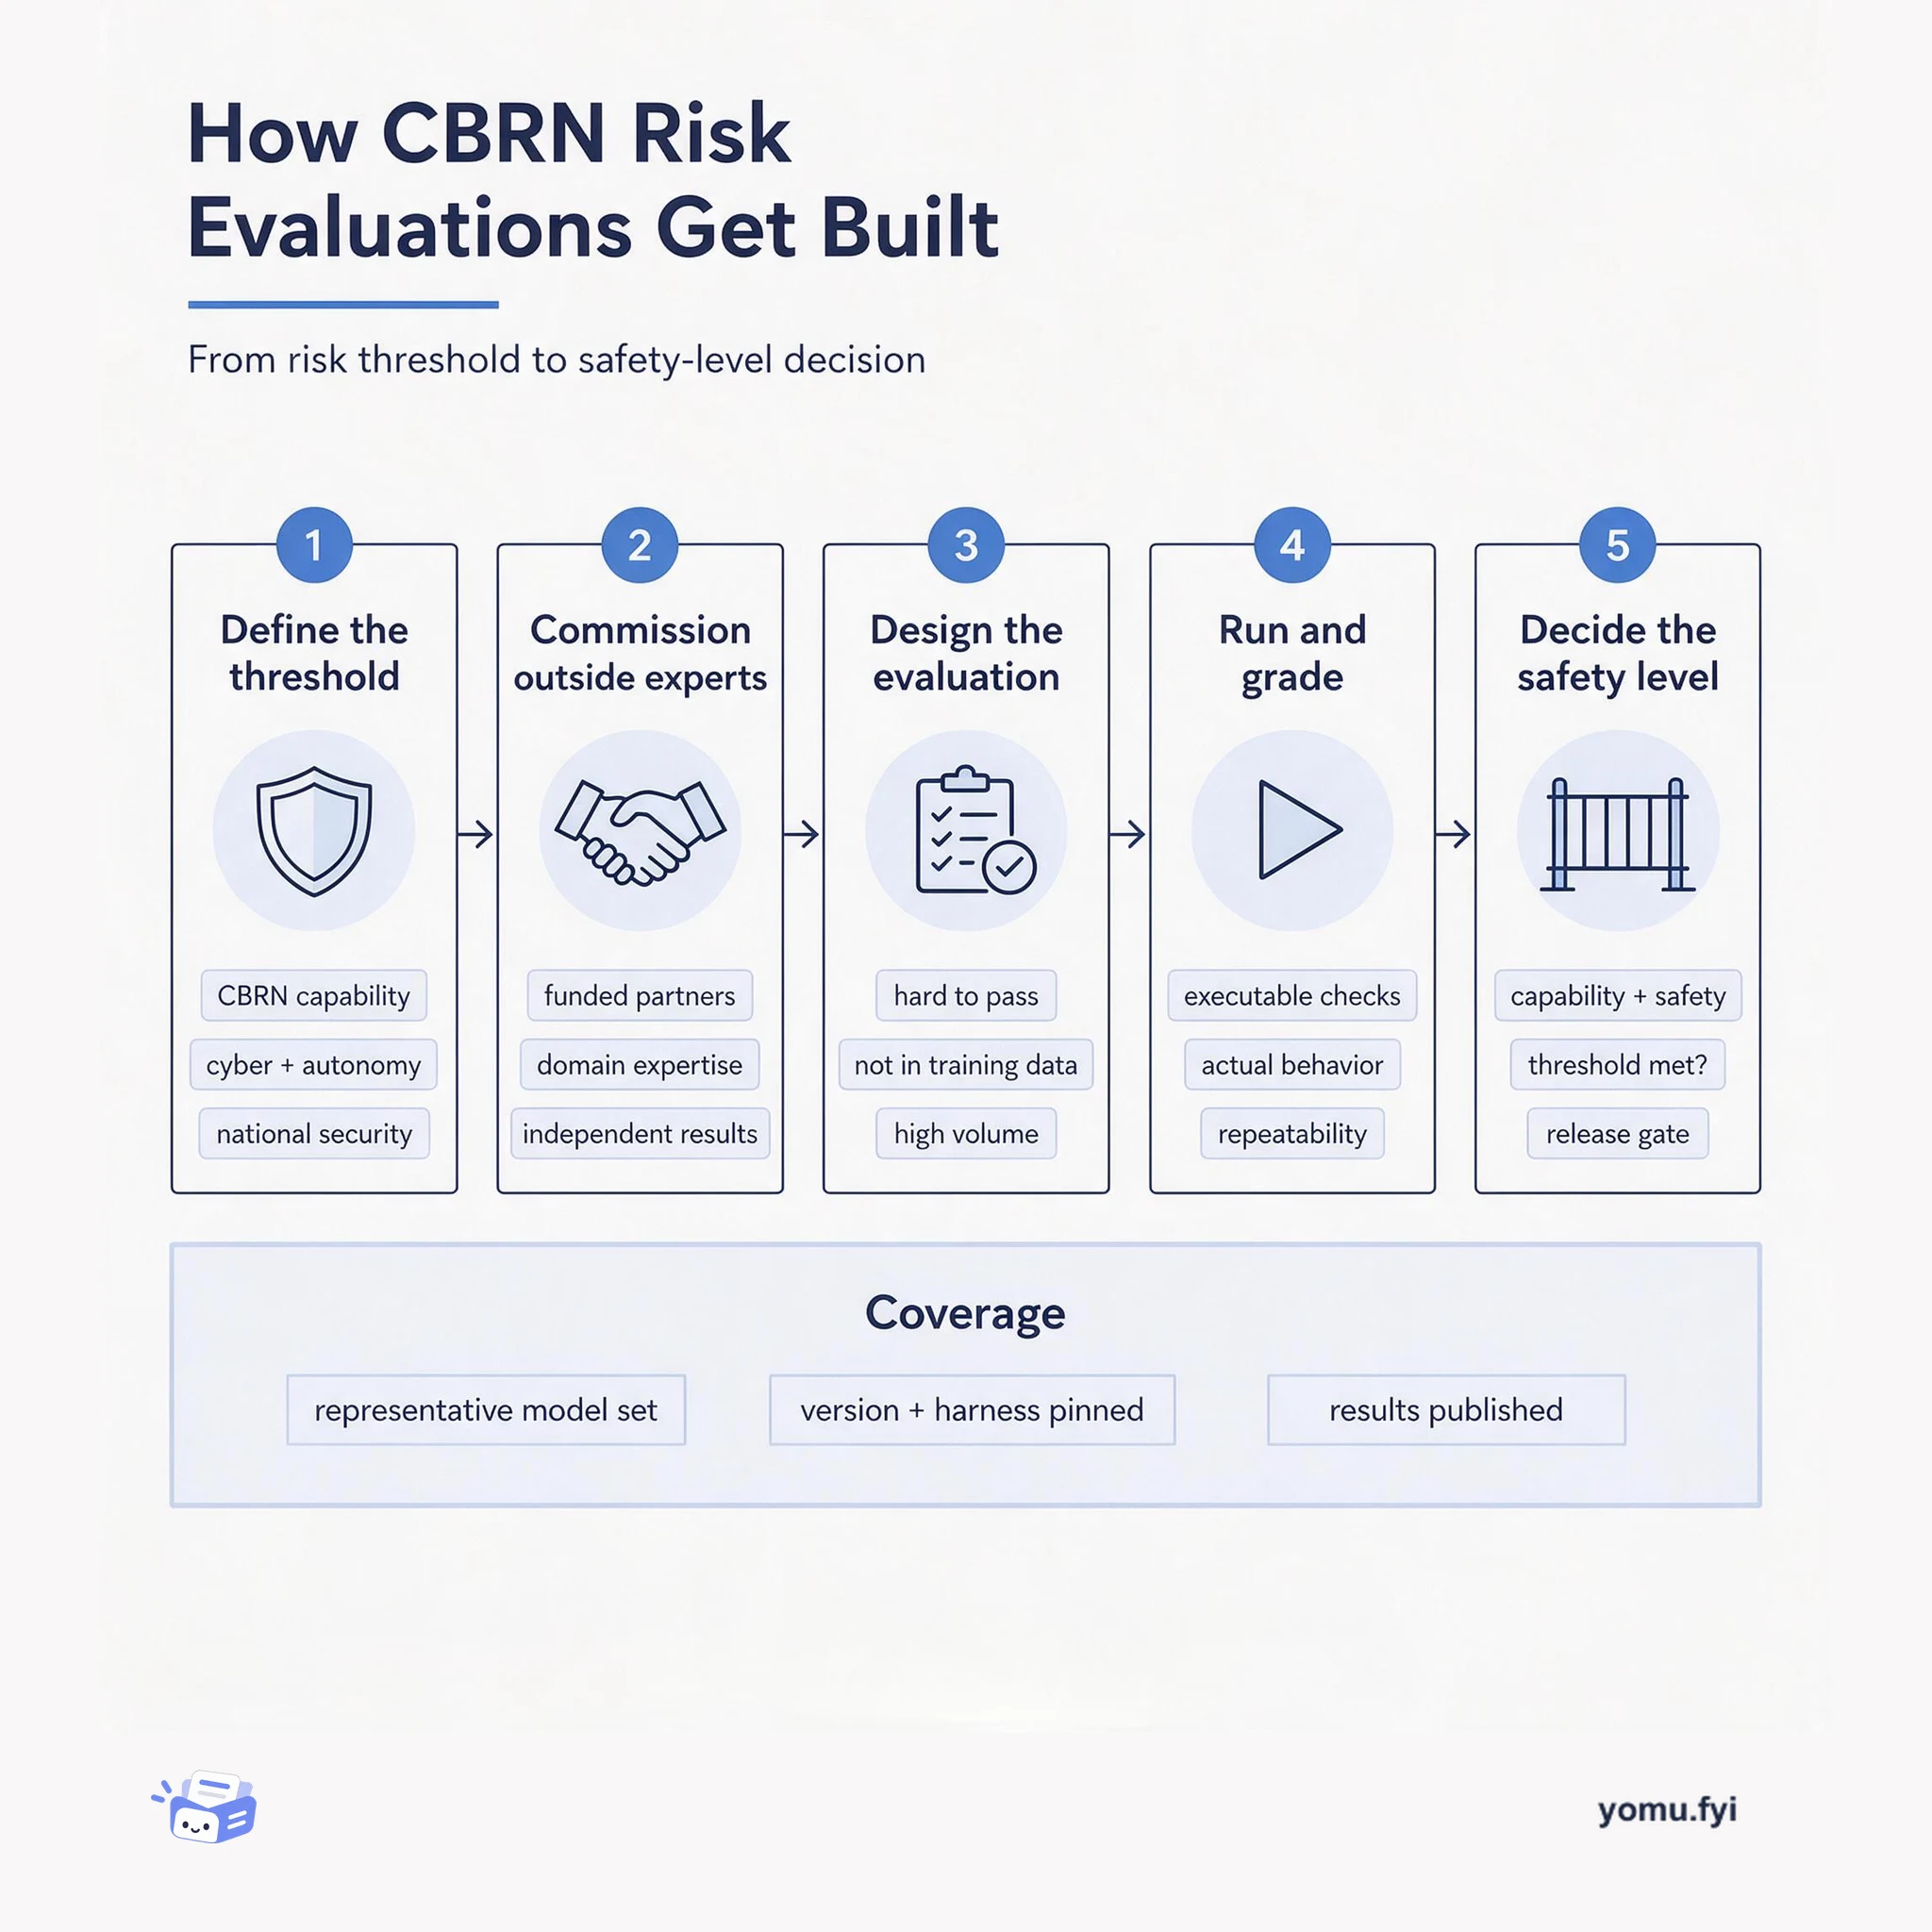
A five-stage walkthrough of how CBRN risk evaluations are commissioned, designed, graded, and converted into safety-level decisions for frontier AI models.
 AnthropicAnthropicAnnouncement
Anthropic announced a new initiative to fund third-party organizations to develop evaluations for measuring advanced AI capabilities and safety risks. The initiative prioritizes three areas: AI Safety Level assessments for cybersecurity, CBRN, model autonomy, and other national security risks; advanced capability and safety metrics including science, harmfulness, multilingual, and societal impacts; and infrastructure, tools, and methods for evaluation development. The company seeks evaluations that are sufficiently difficult, not in training data, efficient, high-volume, and developed with domain expertise. Anthropic offers funding and direct collaboration with its domain experts from Frontier Red Team and other teams. The goal is to catalyze a robust third-party evaluation ecosystem to address the current limited landscape where demand for high-quality safety evaluations outpaces supply.
The current landscape for AI model evaluations is limited, with demand for high-quality, safety-relevant evaluations outpacing supply. Developing such evaluations remains challenging, and a robust third-party ecosystem is needed to assess advanced AI capabilities and risks.
Anthropic is funding third-party organizations to develop evaluations for measuring advanced AI capabilities and safety risks. The initiative focuses on three priority areas: AI Safety Level assessments (cybersecurity, CBRN, model autonomy, national security, social manipulation, misalignment), advanced capability and safety metrics (science, harmfulness, multilingual, societal impacts), and infrastructure/tools for evaluation development (templates, no-code platforms, human trials). Anthropic offers funding and direct collaboration with its domain experts from Frontier Red Team, Finetuning, Trust & Safety, and other teams.
Anthropic is prioritizing evaluations for AI Safety Level assessments covering cybersecurity, CBRN, model autonomy, national security, social manipulation, and misalignment risks.
The initiative seeks evaluations that are sufficiently difficult, not in training data, efficient, high-volume, and developed with domain expertise.
Anthropic offers funding and direct collaboration with its domain experts from Frontier Red Team and other teams to help refine evaluations.
Anthropic is prioritizing three areas: AI Safety Level assessments (cybersecurity, CBRN, model autonomy, national security, social manipulation, misalignment), advanced capability and safety metrics (science, harmfulness, multilingual, societal impacts), and infrastructure/tools for evaluation development.
Proposals can be submitted through the application form provided in the post. Anthropic reviews submissions on a rolling basis and follows up with selected proposals to discuss next steps.
Good evaluations should be sufficiently difficult, not in training data, efficient, scalable, high-volume, developed with domain expertise, diverse in format, have expert baselines, good documentation, start small and iterate, and be based on realistic safety-relevant threat modeling.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A five-stage walkthrough of how CBRN risk evaluations are commissioned, designed, graded, and converted into safety-level decisions for frontier AI models.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
