Anthropic
 is offering Claude for Enterprise and Claude for Government to all three branches of the U.S. government for $1, removing cost barriers to AI adoption. The offer builds on Claude’s addition to the GSA schedule and supports FedRAMP High workloads for sensitive unclassified data. Government partners already using Claude include the Department of Defense, Lawrence Livermore National Laboratory with 10,000 daily users, and the District of Columbia Department of Health. The package includes frontier models with continuous updates and technical support for one year, with coordination underway with GSA for implementation. This expanded access aims to accelerate AI adoption across the federal government for scientific research, national security, and constituent services.
 Hugging Face
Granite Switch 4.1 models combine chat, general and specialized decisions, and speech-to-text from a single hosted endpoint. The 8B and 30B models include a new Decision aLoRA for general-purpose decision-making and a Guardian aLoRA that outperforms Jev 1.13 and other closed models on safety tasks. They also embed Granite-Speech-5.0-Turbo-CTC, the fastest ASR model on the OpenASR Leaderboard, enabling efficient transcription. All components are composed into one model using cache-efficient Activated LoRAs, taking up about the same GPU VRAM as the base model alone, and the KV cache from base generation can be reused for any subsequent adapter decisions. Granite Switch 4.1 can switch between chat, decision, and spoken requests quickly, and a 3B variant achieved 60-100 decisions per second playing Doom, compared to Jev’s 10, while also narrating and answering questions.
 Meta
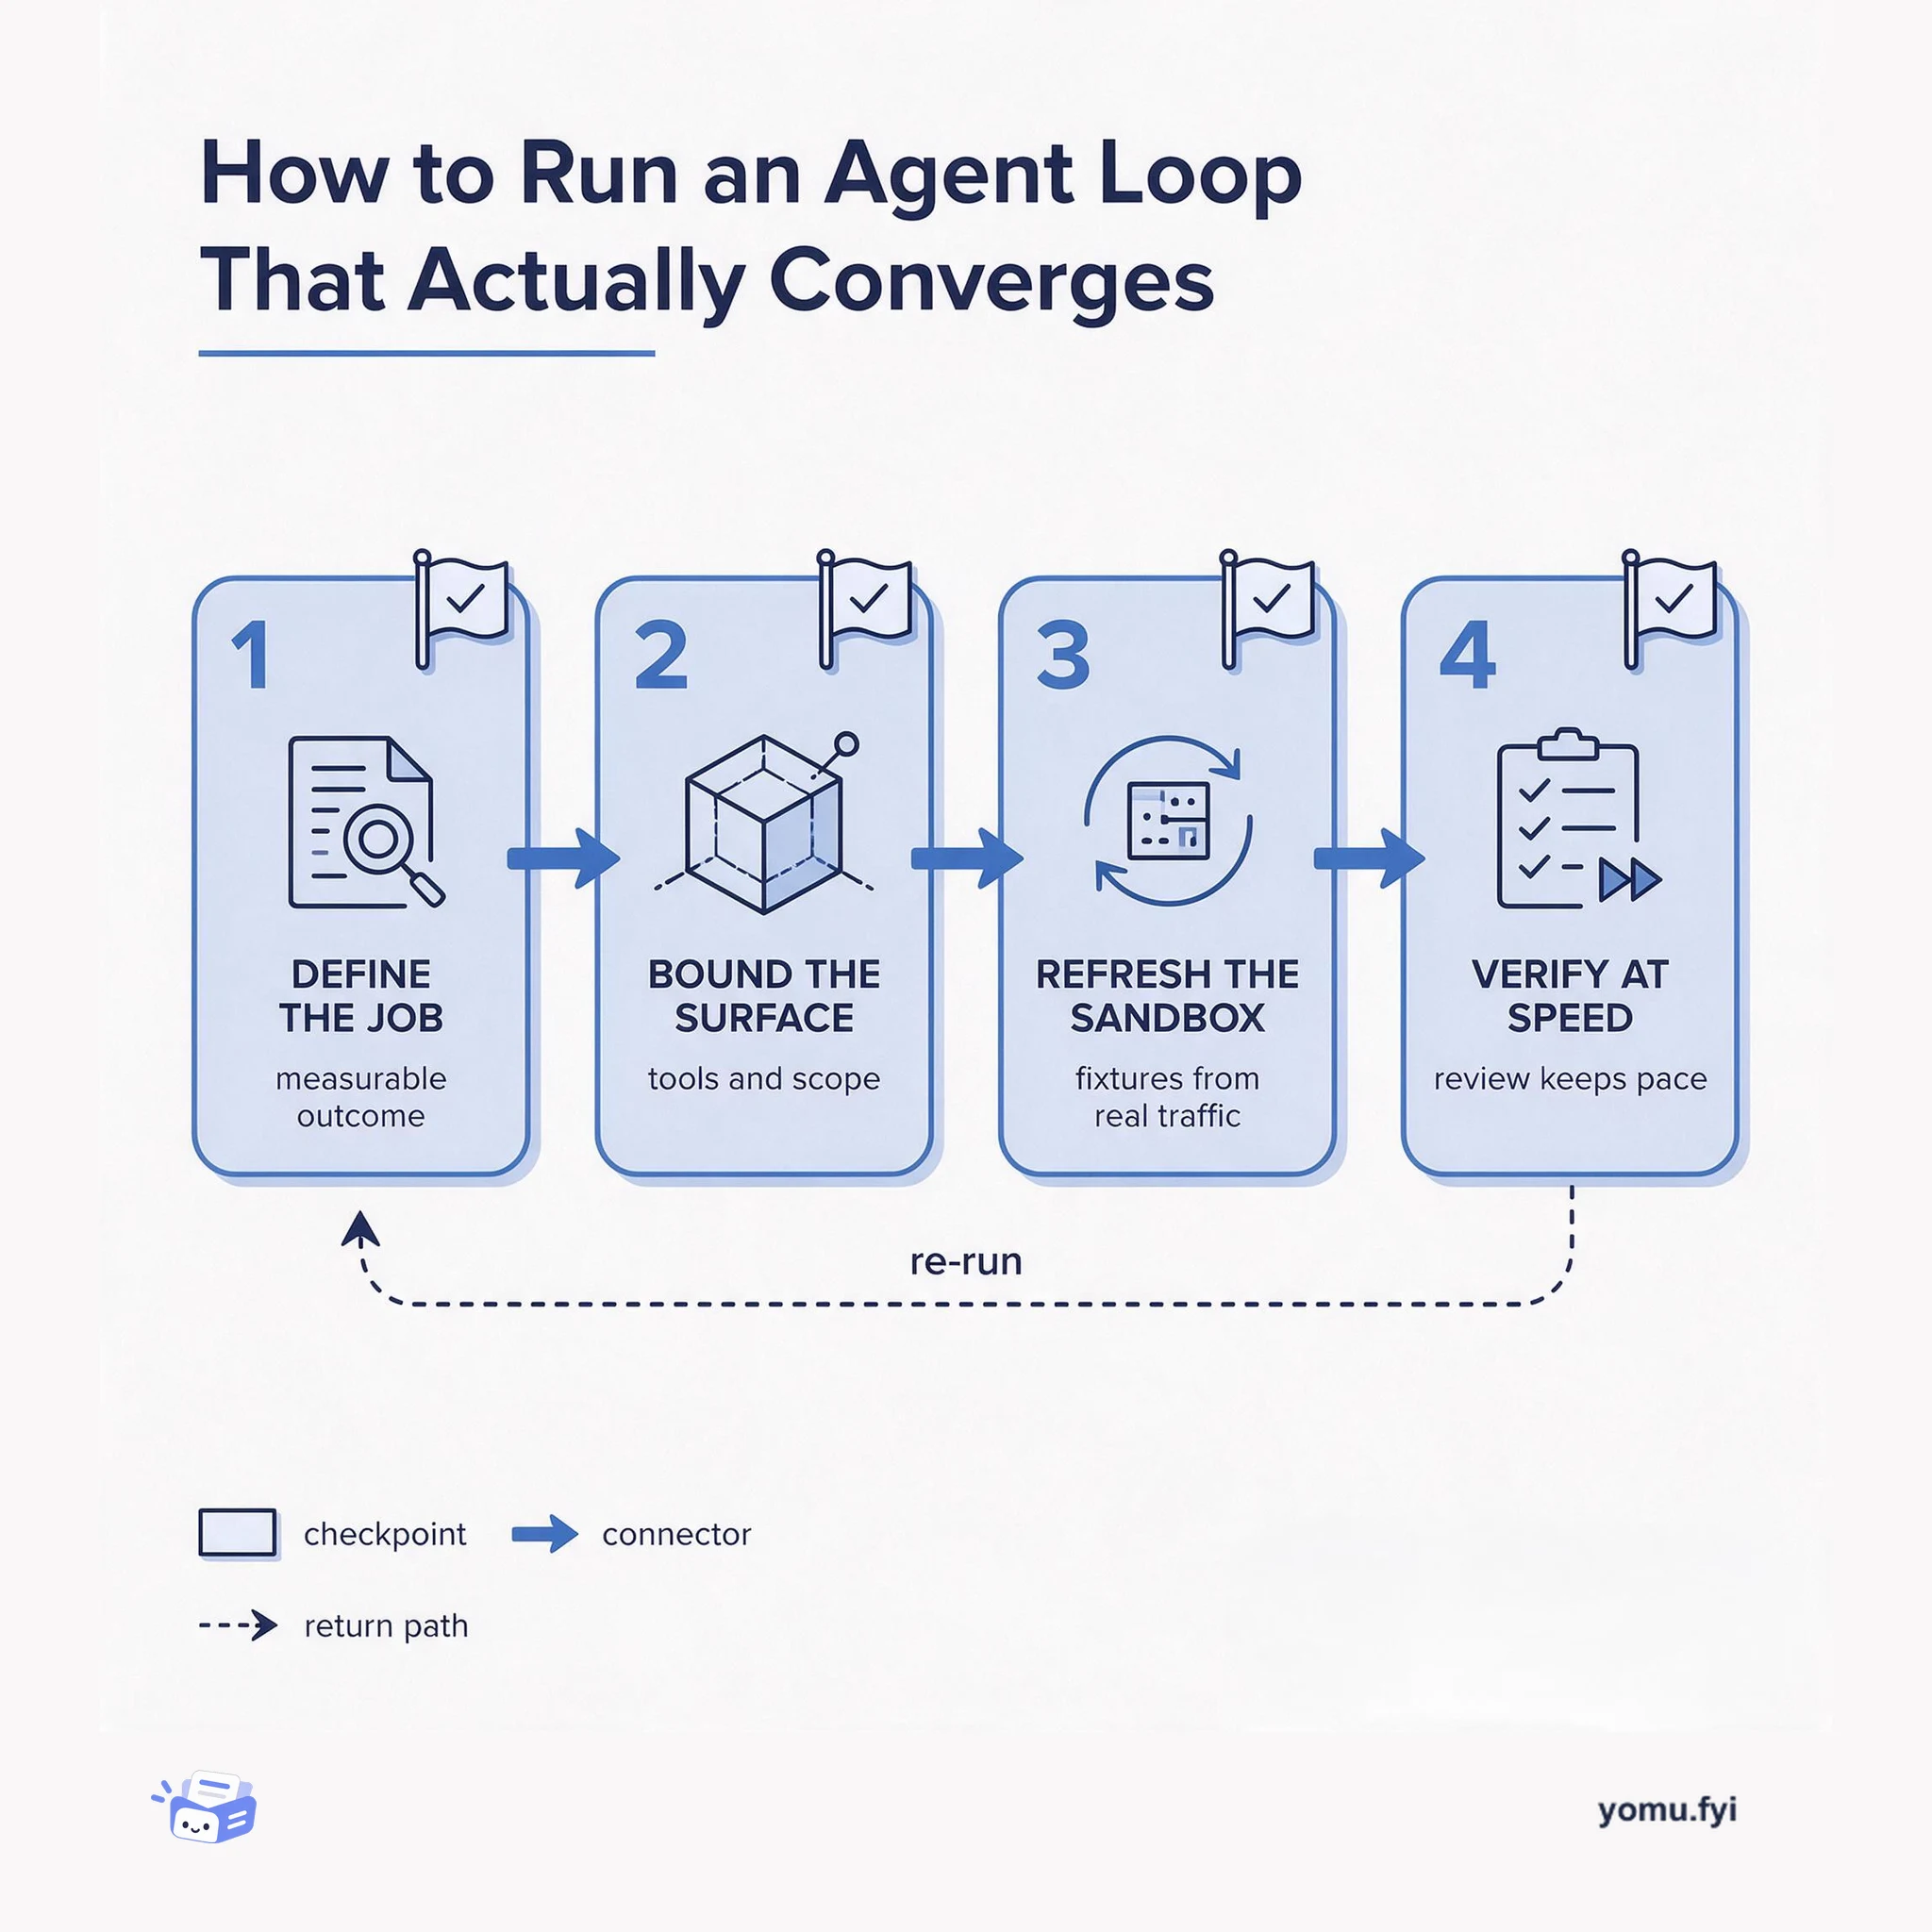
Meta built Forum using AI-native engineering, treating an AI agent as a development participant rather than a faster typing tool. The team shifted from human-in-the-loop to human-on-the-loop, where the agent autonomously plans, implements, builds, tests, and corrects its work while the engineer sets goals and approves outcomes. Success was measured by verified, production-ready results, not code volume, with automated verification signals like build status and unit tests filtering output before review. Meta adapted the codebase for legibility, gave agents tools to inspect live view hierarchy directly instead of descriptions, and created a separate sandbox build to isolate prototype code from production. This approach helped Forum reach core feature parity with Facebook Groups in eight weeks and caught a memory issue during development that roughly halved memory use and page faults.
Meta
The 2026 FIFA World Cup produced the largest planned stress test of Meta’s infrastructure, with WhatsApp setting an all-time record of over 30 million messages per second during the final and delivering 8.4 billion messages in its peak five-minute window. Traffic analysis revealed that surges in sharing primarily occurred during breaks and final whistles, not during active gameplay, shaping capacity decisions. Instagram and Facebook saw live video watch time spike 90% and 242% respectively, while recommendation traffic rose 80% week-over-week. To absorb these spikes, Meta layered pre-provisioned capacity buffers, country-level graceful degradation, cascade prevention, and early warning signals across all serving tiers. Notably, the team did not shift load between regions or freeze deployments, relying instead on year-round reliability enhancements and phased runbook execution.
 Databricks
FactSet’s Text-to-Formula (TTF) system converts natural-language investment queries from professionals into correct FactSet Query Language (FQL) formulas. Initially built on retrieval-augmented generation (RAG), the approach hit a quality ceiling as queries became more specialized and formulas more complex. FactSet adopted fine-tuned open models within a Compound AI architecture, reducing end-to-end latency by about 60 percent and improving quality for complex formulas. Fine-tuning runs on Databricks AI Runtime with serverless GPU infrastructure, where engineers choose compute based on prompt length and output needs, and the pipeline integrates with MLflow, the Lakehouse, and Lakeflow Jobs for a unified workflow. This setup cut model setup, training, and deployment from days to hours, enabling the team to retrain every two to three weeks as new data and models become available.