The post describes design tradeoffs and workarounds encountered while building the open-source Bulk Executor tool for Amazon DynamoDB on AWS Glue. Core requirements included real-time local-script feel, scaling to hundreds of parallel workers without user infrastructure management, and easy command extensibility. AWS Glue was chosen for serverless parallelism and a built-in DynamoDB connector, but the connector simplified data types, losing distinctions like string set versus list of strings. Challenges included estimating costs for provisioned tables, handling job termination with ^C, and streaming output via CloudWatch Live Tail which samples events and delivers out-of-order. Solutions included a two-phase cost estimate for deletes, programmatic interrupt handling, writing large output to S3 with a preview, mandating point-in-time recovery for mutating commands, and using AI for testing and linting; the team also migrated from AWS Glue 4 to 5 and 6 for faster startup and 30 percent lower DPU costs.
Context
This is a follow-up to the introduction of the open-source Bulk Executor tool for Amazon DynamoDB. It shares design tradeoffs, surprises, and workarounds encountered during development, aimed at developers building similar tooling on AWS Glue.
Approach / What changed
The team built a Python CLI that submits AWS Glue jobs to run Spark commands against DynamoDB tables. AWS Glue provides serverless parallel execution across workers, and its built-in DynamoDB connector reads/writes DataFrames. The client handles cost estimation, interrupt propagation, output streaming via CloudWatch Live Tail with reordering and a silence-based completion monitor, and mandates point-in-time recovery for mutating commands. AI tooling generated stress tests for connector migration and an AI linter checks consistency across documentation, role creation, and IAM policy checks.
Takeaways
1
AWS Glue’s built-in DynamoDB connector simplifies data types, losing distinctions like string set versus list of strings, which can affect commands relying on type fidelity.
2
CloudWatch Live Tail streams job output but samples at 500 events per second and can deliver events out of order, requiring a reordering layer and a silence-based completion monitor.
3
Cost estimation for provisioned tables uses a heuristic of two-thirds of on-demand price because 100% utilization is rarely achievable; delete costs are estimated in two phases.
FAQ
How does Bulk Executor handle job termination with ^C?
The Python client catches the interrupt signal programmatically, sets an interrupted flag, and a watcher loop directs the AWS Glue job to stop before the client exits cleanly, ensuring both sides stop with one ^C.
Why does Bulk Executor require point-in-time recovery for mutating commands?
To allow rollback if a --where clause deletes more than intended. The revert-export command uses PITR-driven incremental export to undo writes in place.
How does Bulk Executor estimate costs for delete commands?
It estimates read cost upfront using table metadata (updated every ~6 hours). For provisioned tables, it uses a heuristic of two-thirds of the on-demand price. After scanning to find matching items, it estimates write cost based on the deletion set size.
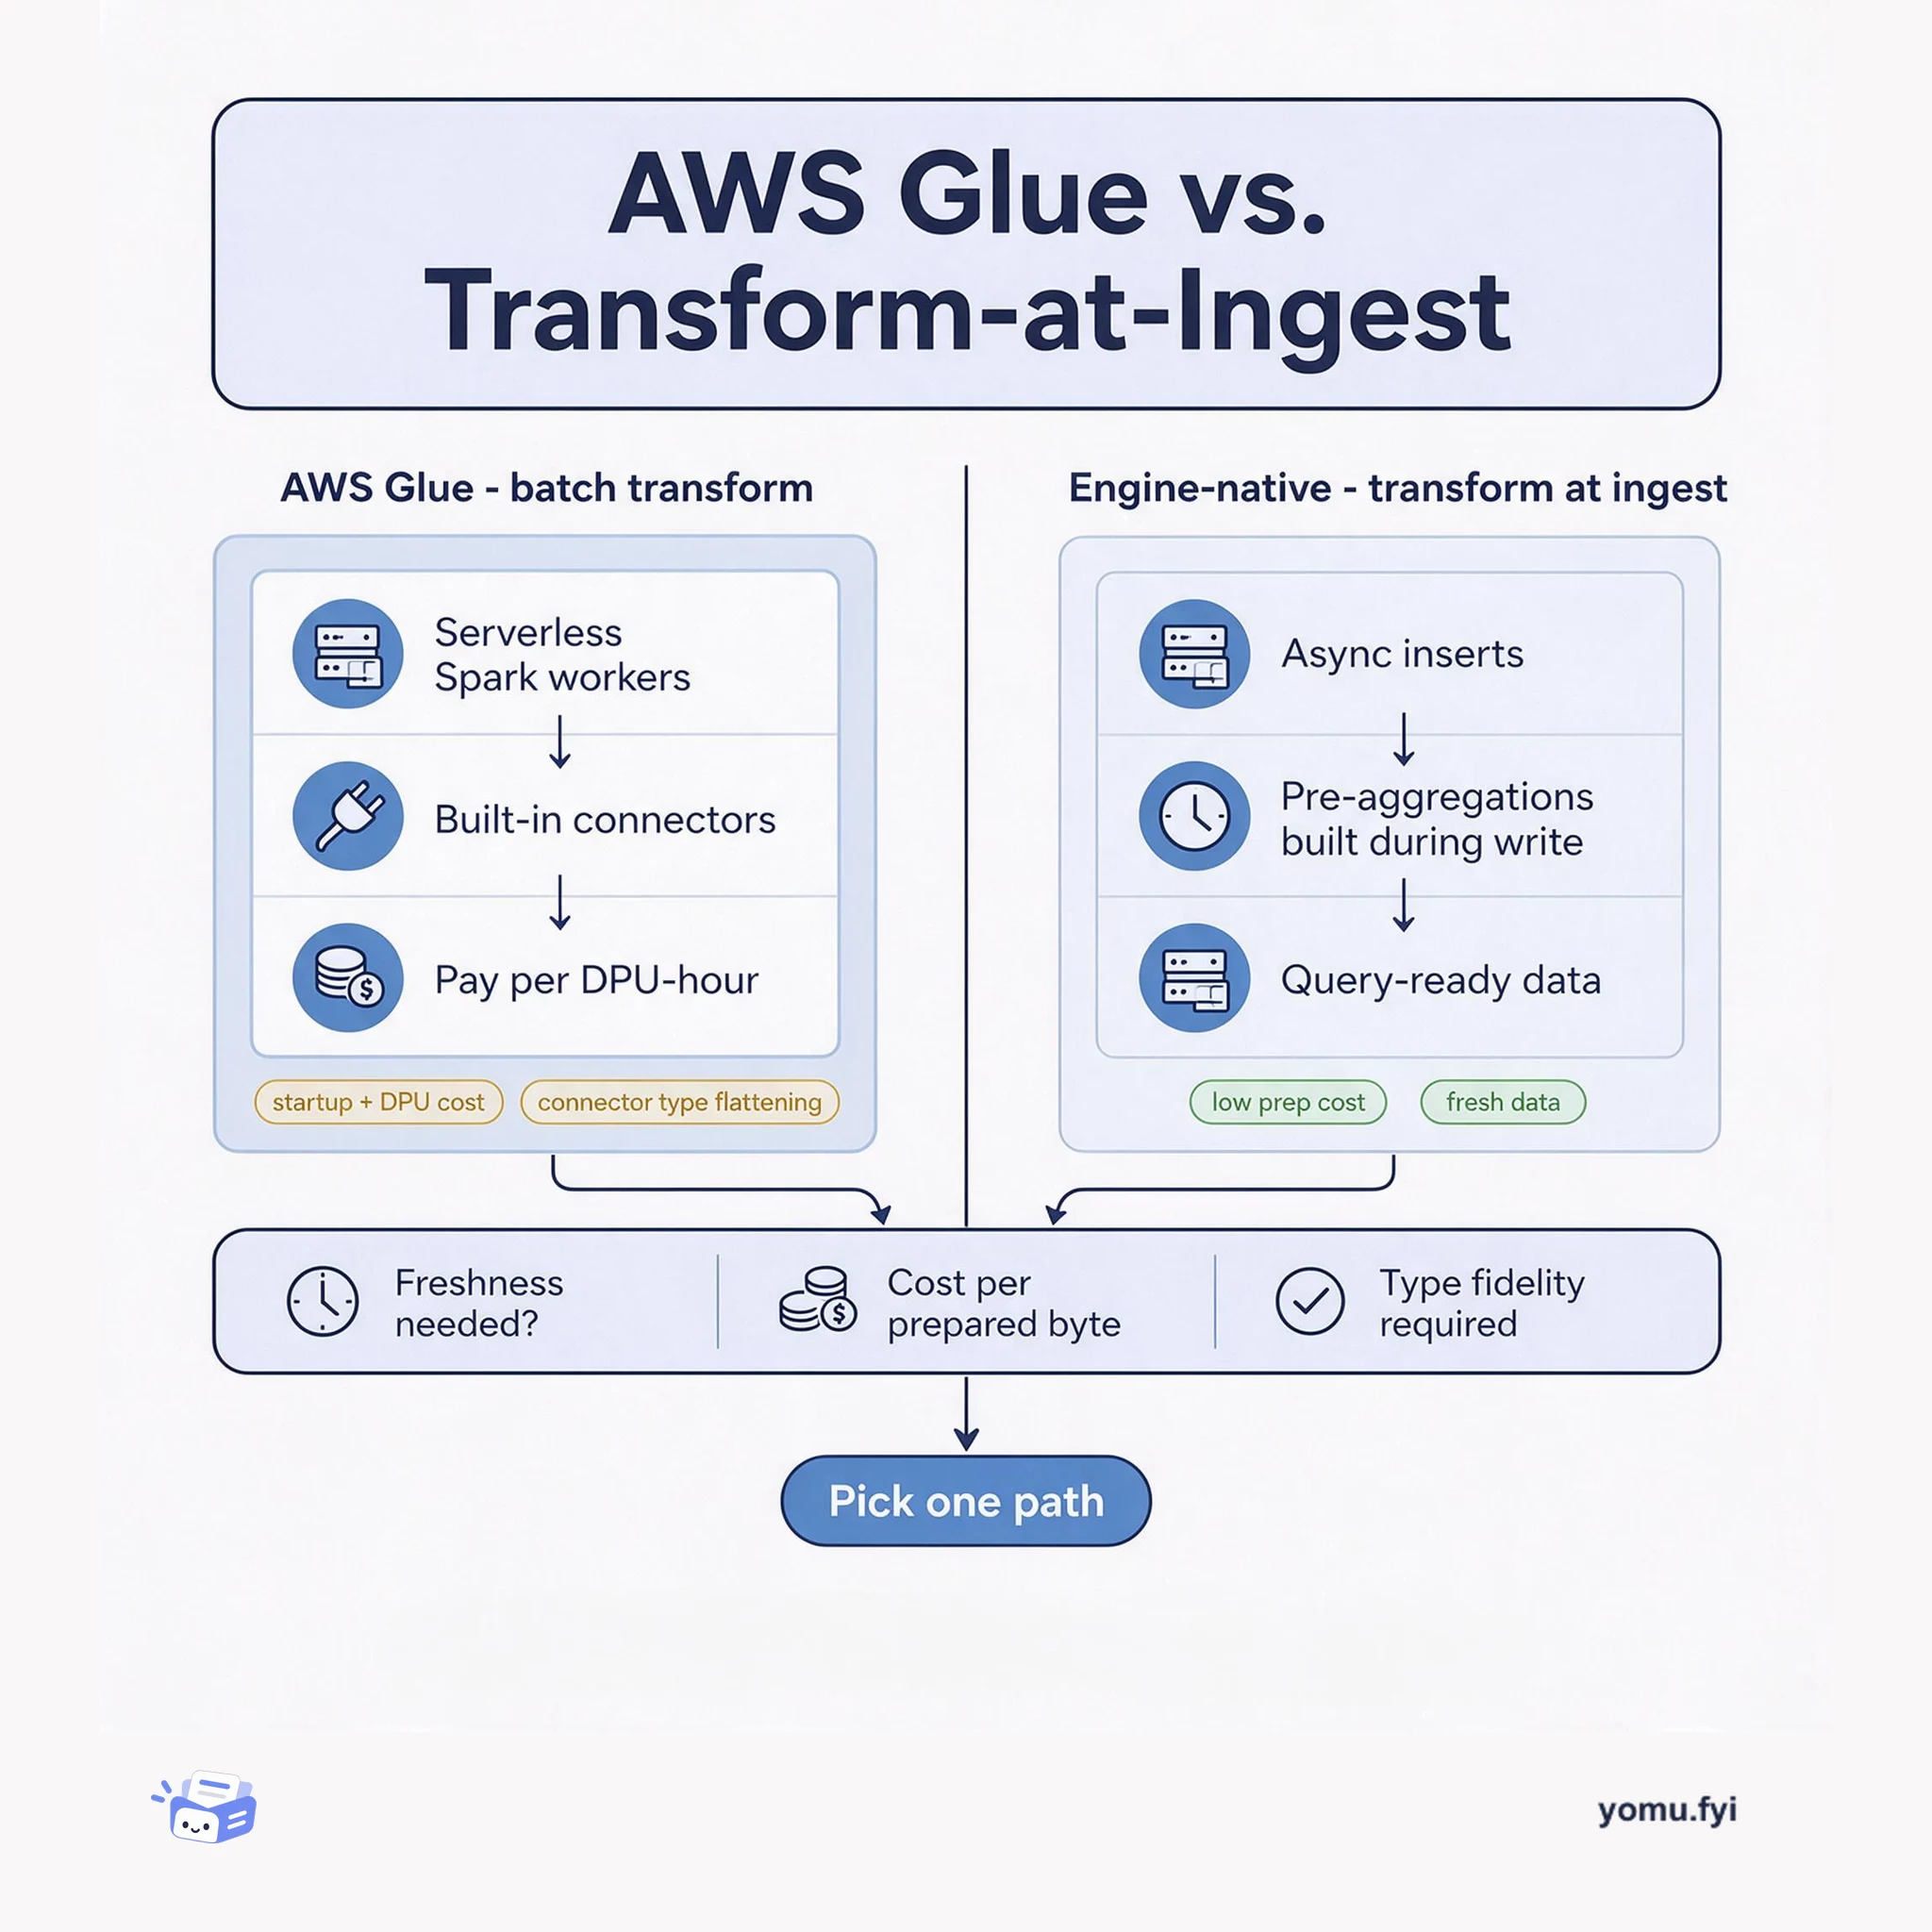
AWS Glue runs serverless Spark jobs that transform data in batches; engine-native pipelines transform during ingestion. This comparison shows how to pick between them by freshness, cost, and data fidelity.
Keep reading
Related reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.