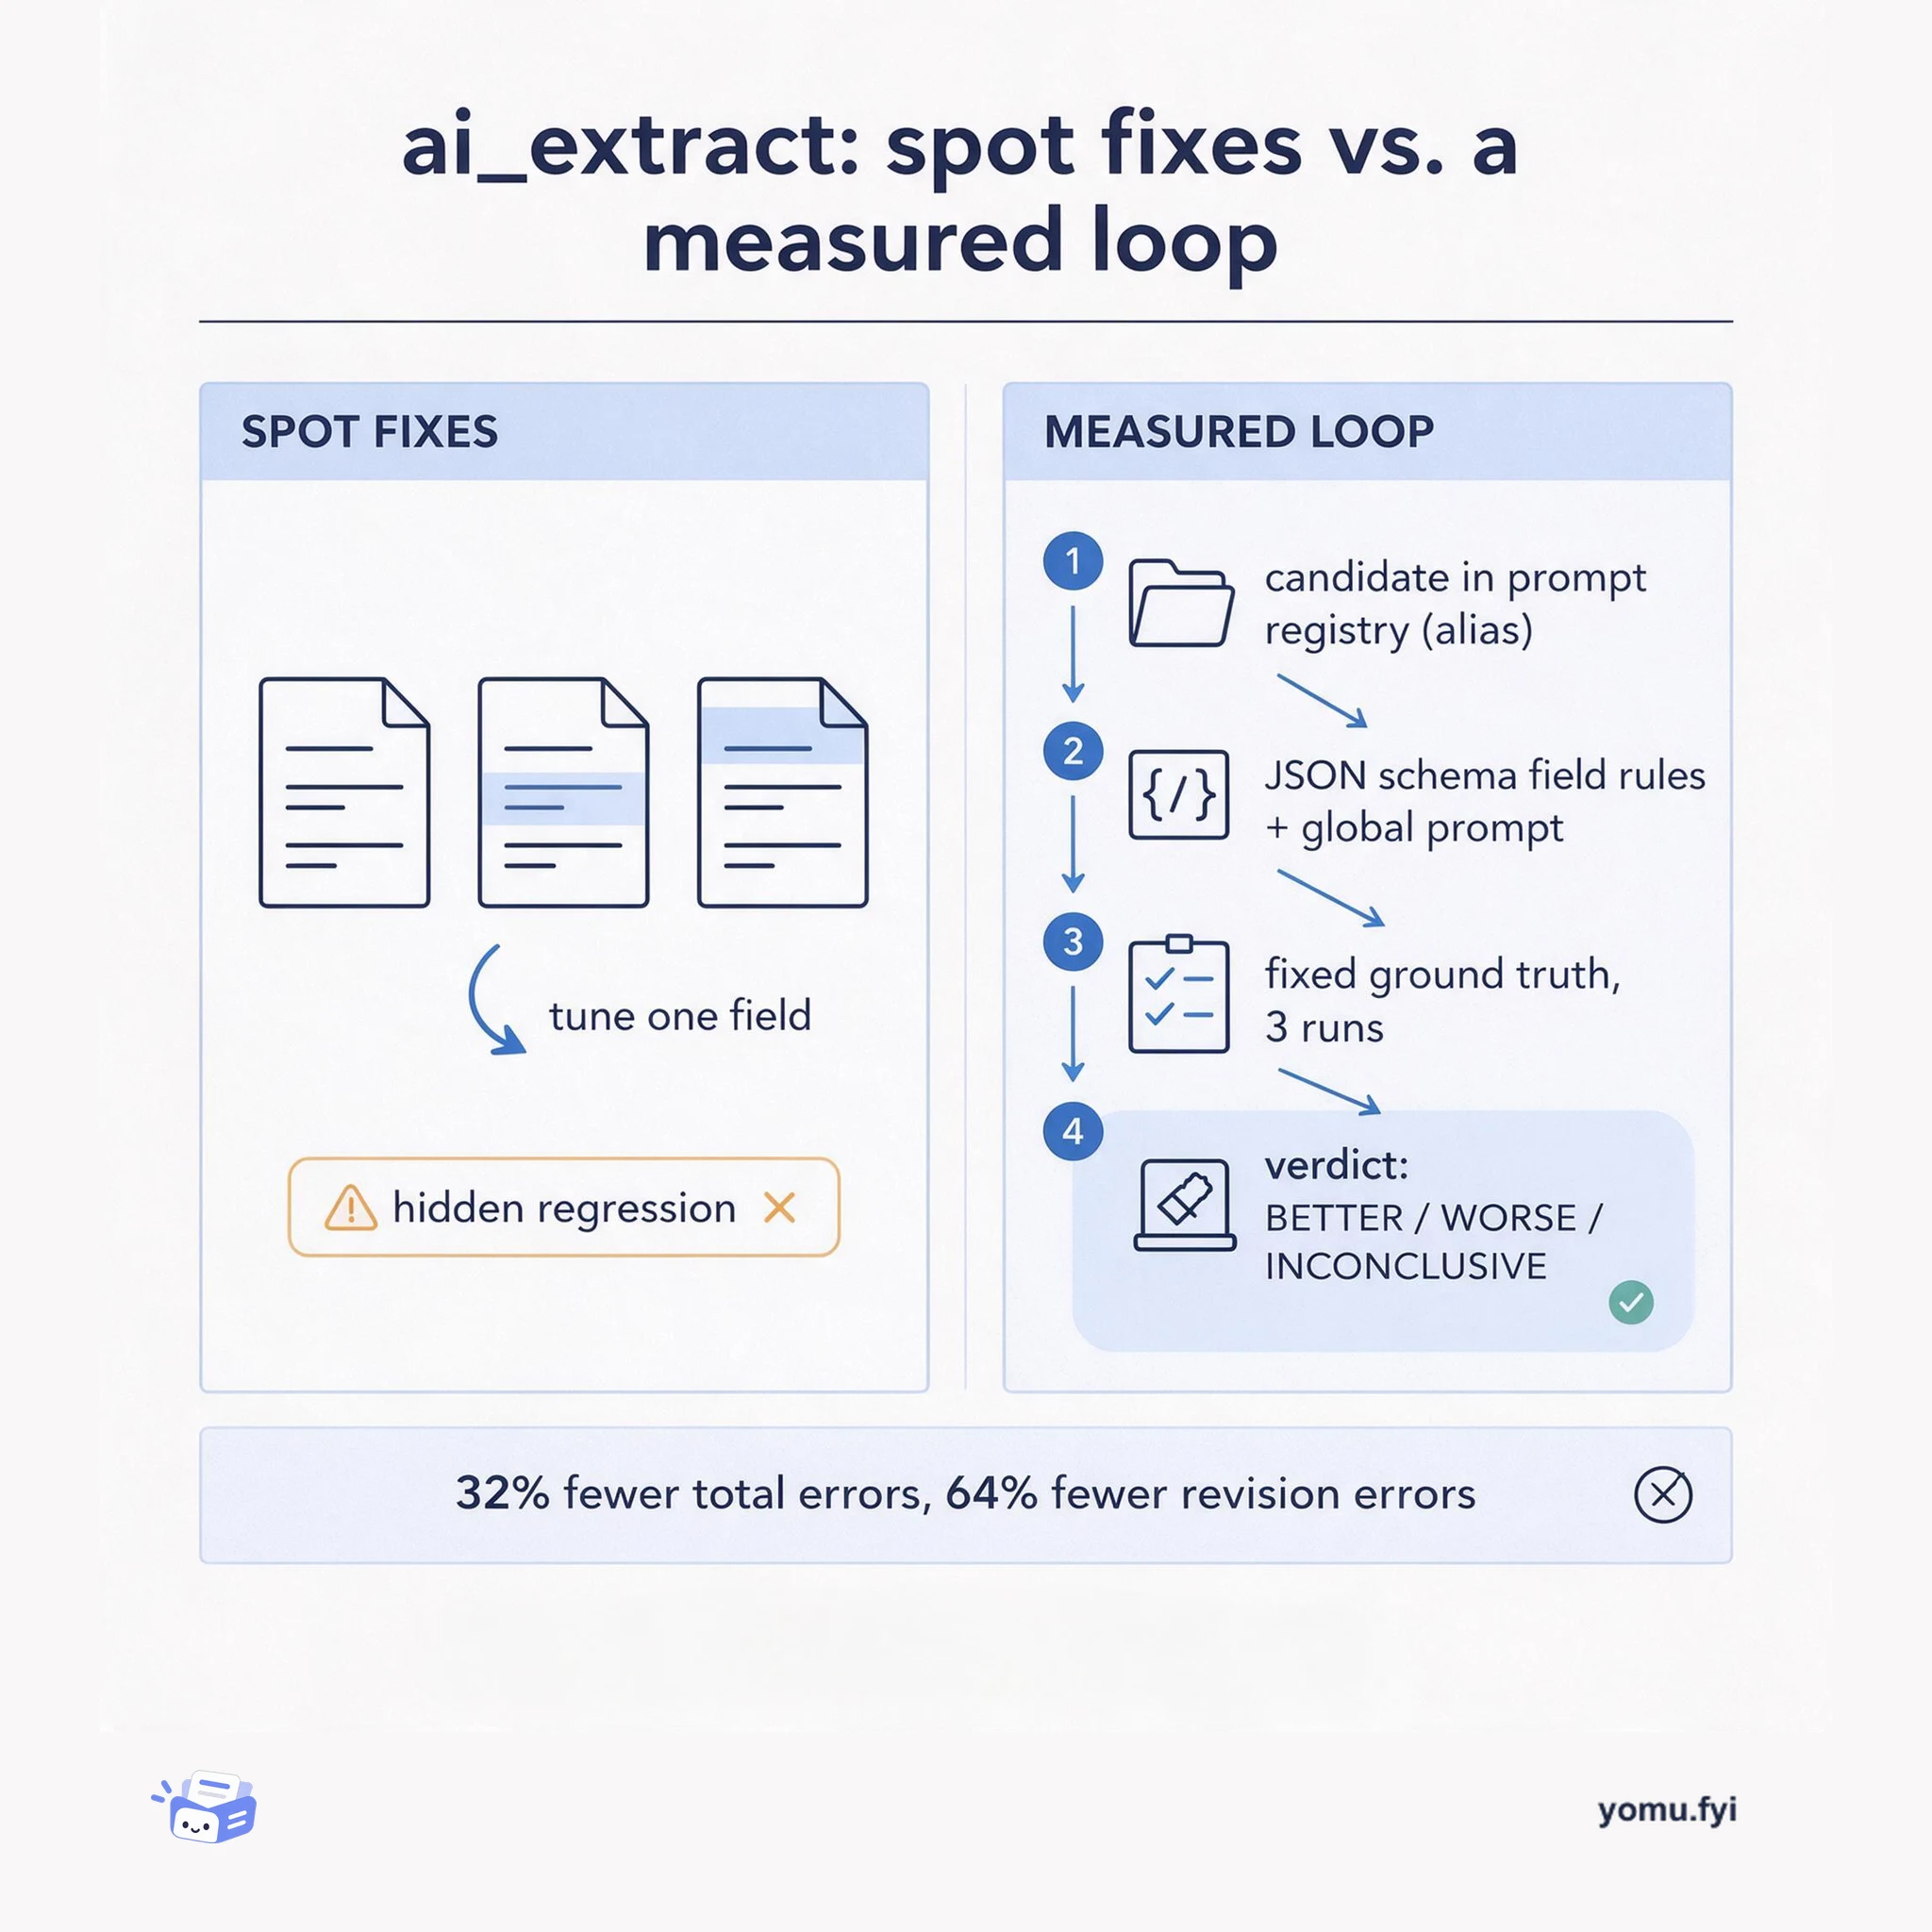
ai_extract: Spot Fixes vs. a Measured Eval Loop
A side-by-side comparison of two ways to improve ai_extract document extraction: patching one field at a time, or versioning prompts and judging them against fixed ground truth.
Loading…
Topic
1 post about Prompt Registry. Every summary links to the original.
See the idea
A side-by-side comparison of two ways to improve ai_extract document extraction: patching one field at a time, or versioning prompts and judging them against fixed ground truth.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
Document extraction across dozens of PDF layouts is unreliable when fields are tuned in isolation; fixing one field can cause hidden regressions and apparent improvements may stem from normal run-to-run variation. The project extracting roughly 40 structured fields from partner-submitted order documents used human reviewers who corrected and approved extracted values, providing ground truth for evaluation. Field-specific rules go in JSON schema descriptions, document-level reasoning in a global prompt, precision mode handles complex structures, and citations diagnose failures. Candidates are versioned in MLflow Prompt Registry with aliases and evaluated against fixed ground truth using three runs to filter noise before promotion, outputting a BETTER, WORSE, or INCONCLUSIVE verdict. This approach reduced total errors by 32% and revision errors by 64%, creating a repeatable and regression-safe extraction workflow now automated by Genie Code.
The best engineering reads, once a week.

