On September 8, 2026, security researcher Gadi Evron reported a tenant isolation issue in the GLM-5.3 Workers AI model via HackerOne. Between August 27 and September 9, 155 responses to prompts longer than 681,280 tokens contained data from other customers’ requests; no other models were affected. The root cause was a configuration mismatch where the KV cache pool held only 681,280 tokens while the model’s context window was 1,048,576 tokens, triggering a bug in SGLang’s disaggregated prefill/decode mode. This bug left stale cache pages from rejected prompts that decode nodes used for generation. Cloudflare remediated by resizing the pool to hold about 2.04 million tokens and patching the engine to reject over-length requests before any KV transfer, with upstream fixes merged, and they plan to apply formal verification to the KV cache transfer protocol.
Context
A tenant isolation vulnerability in the GLM-5.3 Workers AI model caused 155 responses to prompts over 681,280 tokens to contain data from other customers’ requests between August 27 and September 9, 2026. The issue stemmed from a KV cache pool size mismatch and an SGLang bug in disaggregated prefill/decode mode.
Approach / What changed
Resized the KV cache pool to hold about 2.04 million tokens (twice the context length) and patched the SGLang engine to reject over-length requests at the disaggregation admission queue before any KV transfer. Upstream fixes were merged in SGLang.
Takeaways
1
The KV cache pool on prefill GPUs was configured to hold only 681,280 tokens, while the model’s context window was 1,048,576 tokens, causing a mismatch that triggered the bug.
2
The SGLang bug in disaggregated prefill/decode mode caused rejected prompts to leave stale cache pages that decode nodes used, leading to cross-request data exposure.
3
Cloudflare’s remediation included resizing the pool to hold about 2.04 million tokens and patching the engine to reject over-length requests before any KV transfer, with upstream fixes merged.
FAQ
How many responses were affected?
155 responses were affected, all to prompts longer than 681,280 tokens. No other Workers AI models were affected.
What caused the KV cache exposure?
A configuration mismatch where the KV cache pool held only 681,280 tokens while the model's context window was 1,048,576 tokens, combined with an SGLang bug in disaggregated prefill/decode mode that left stale cache pages from rejected prompts.
How was the issue fixed?
Cloudflare resized the pool to hold about 2.04 million tokens and patched the engine to reject over-length requests at the disaggregation admission queue before any KV transfer. Upstream fixes were merged in SGLang.
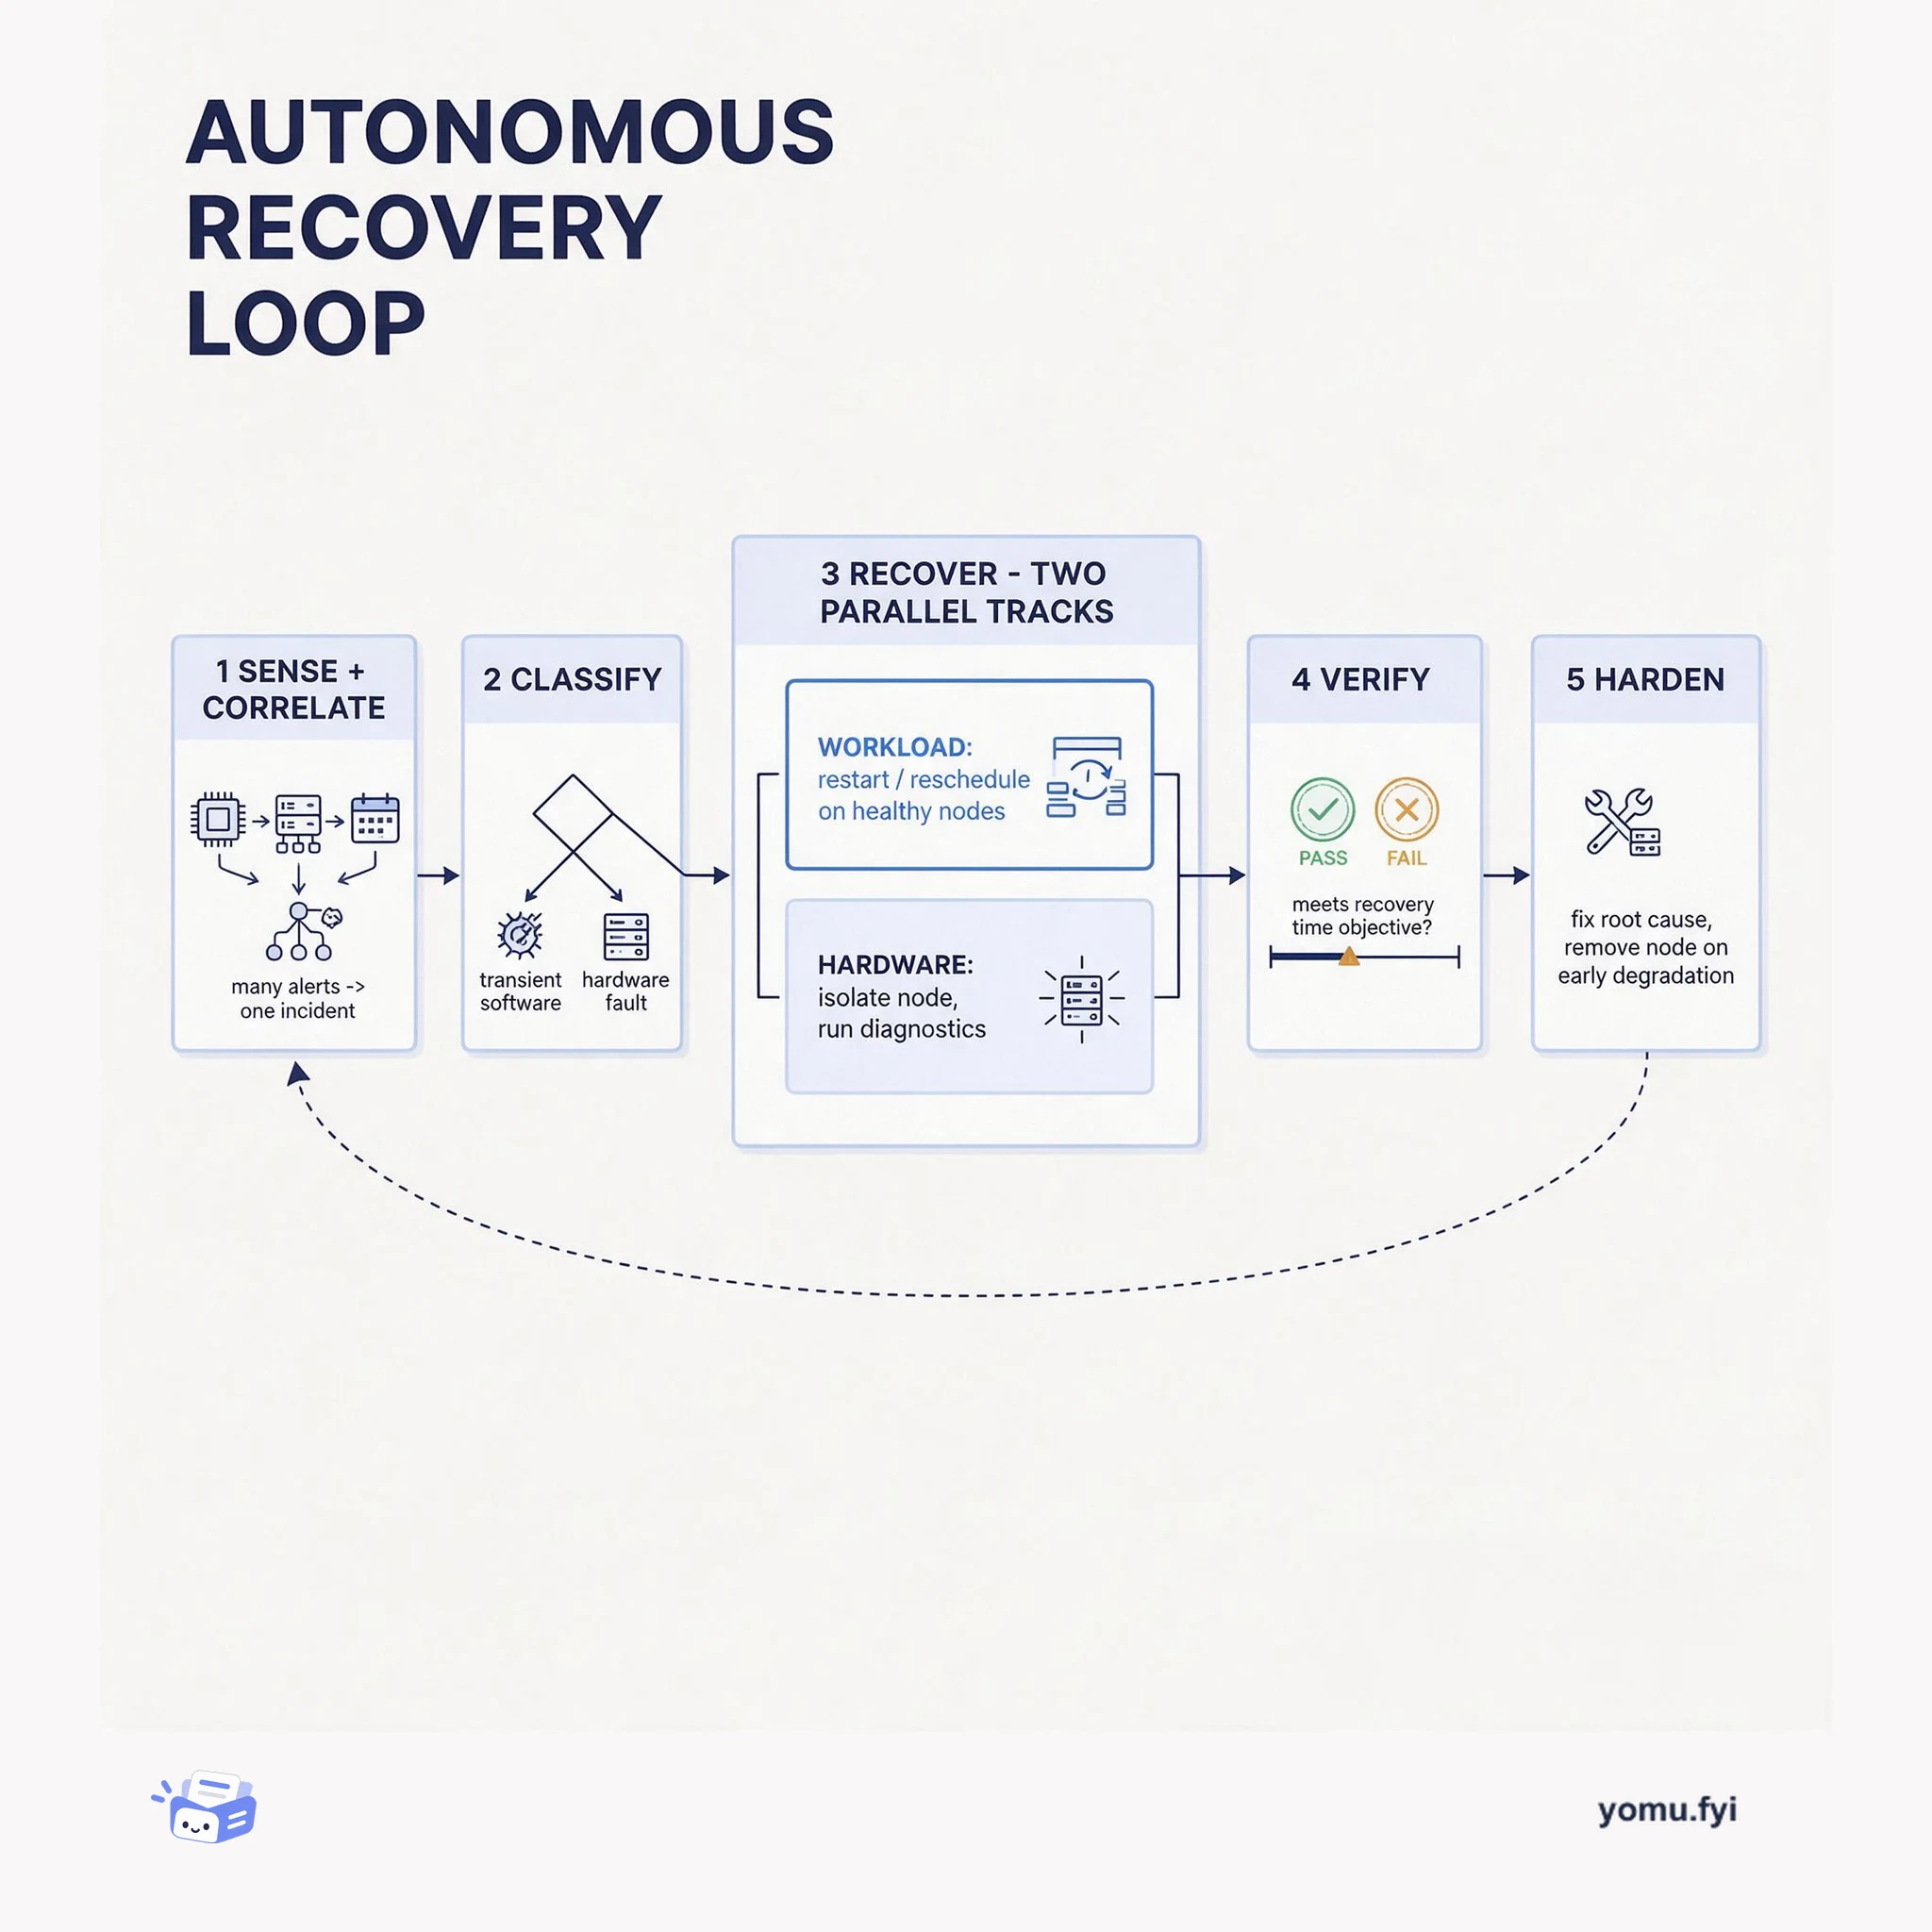
Autonomous Recovery is a closed loop that senses degradation, classifies a fault as transient or hardware, recovers workloads and quarantines hardware in parallel, then verifies against an RTO.
Keep reading
Related reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.