Bot Management as an Adaptive Control Loop
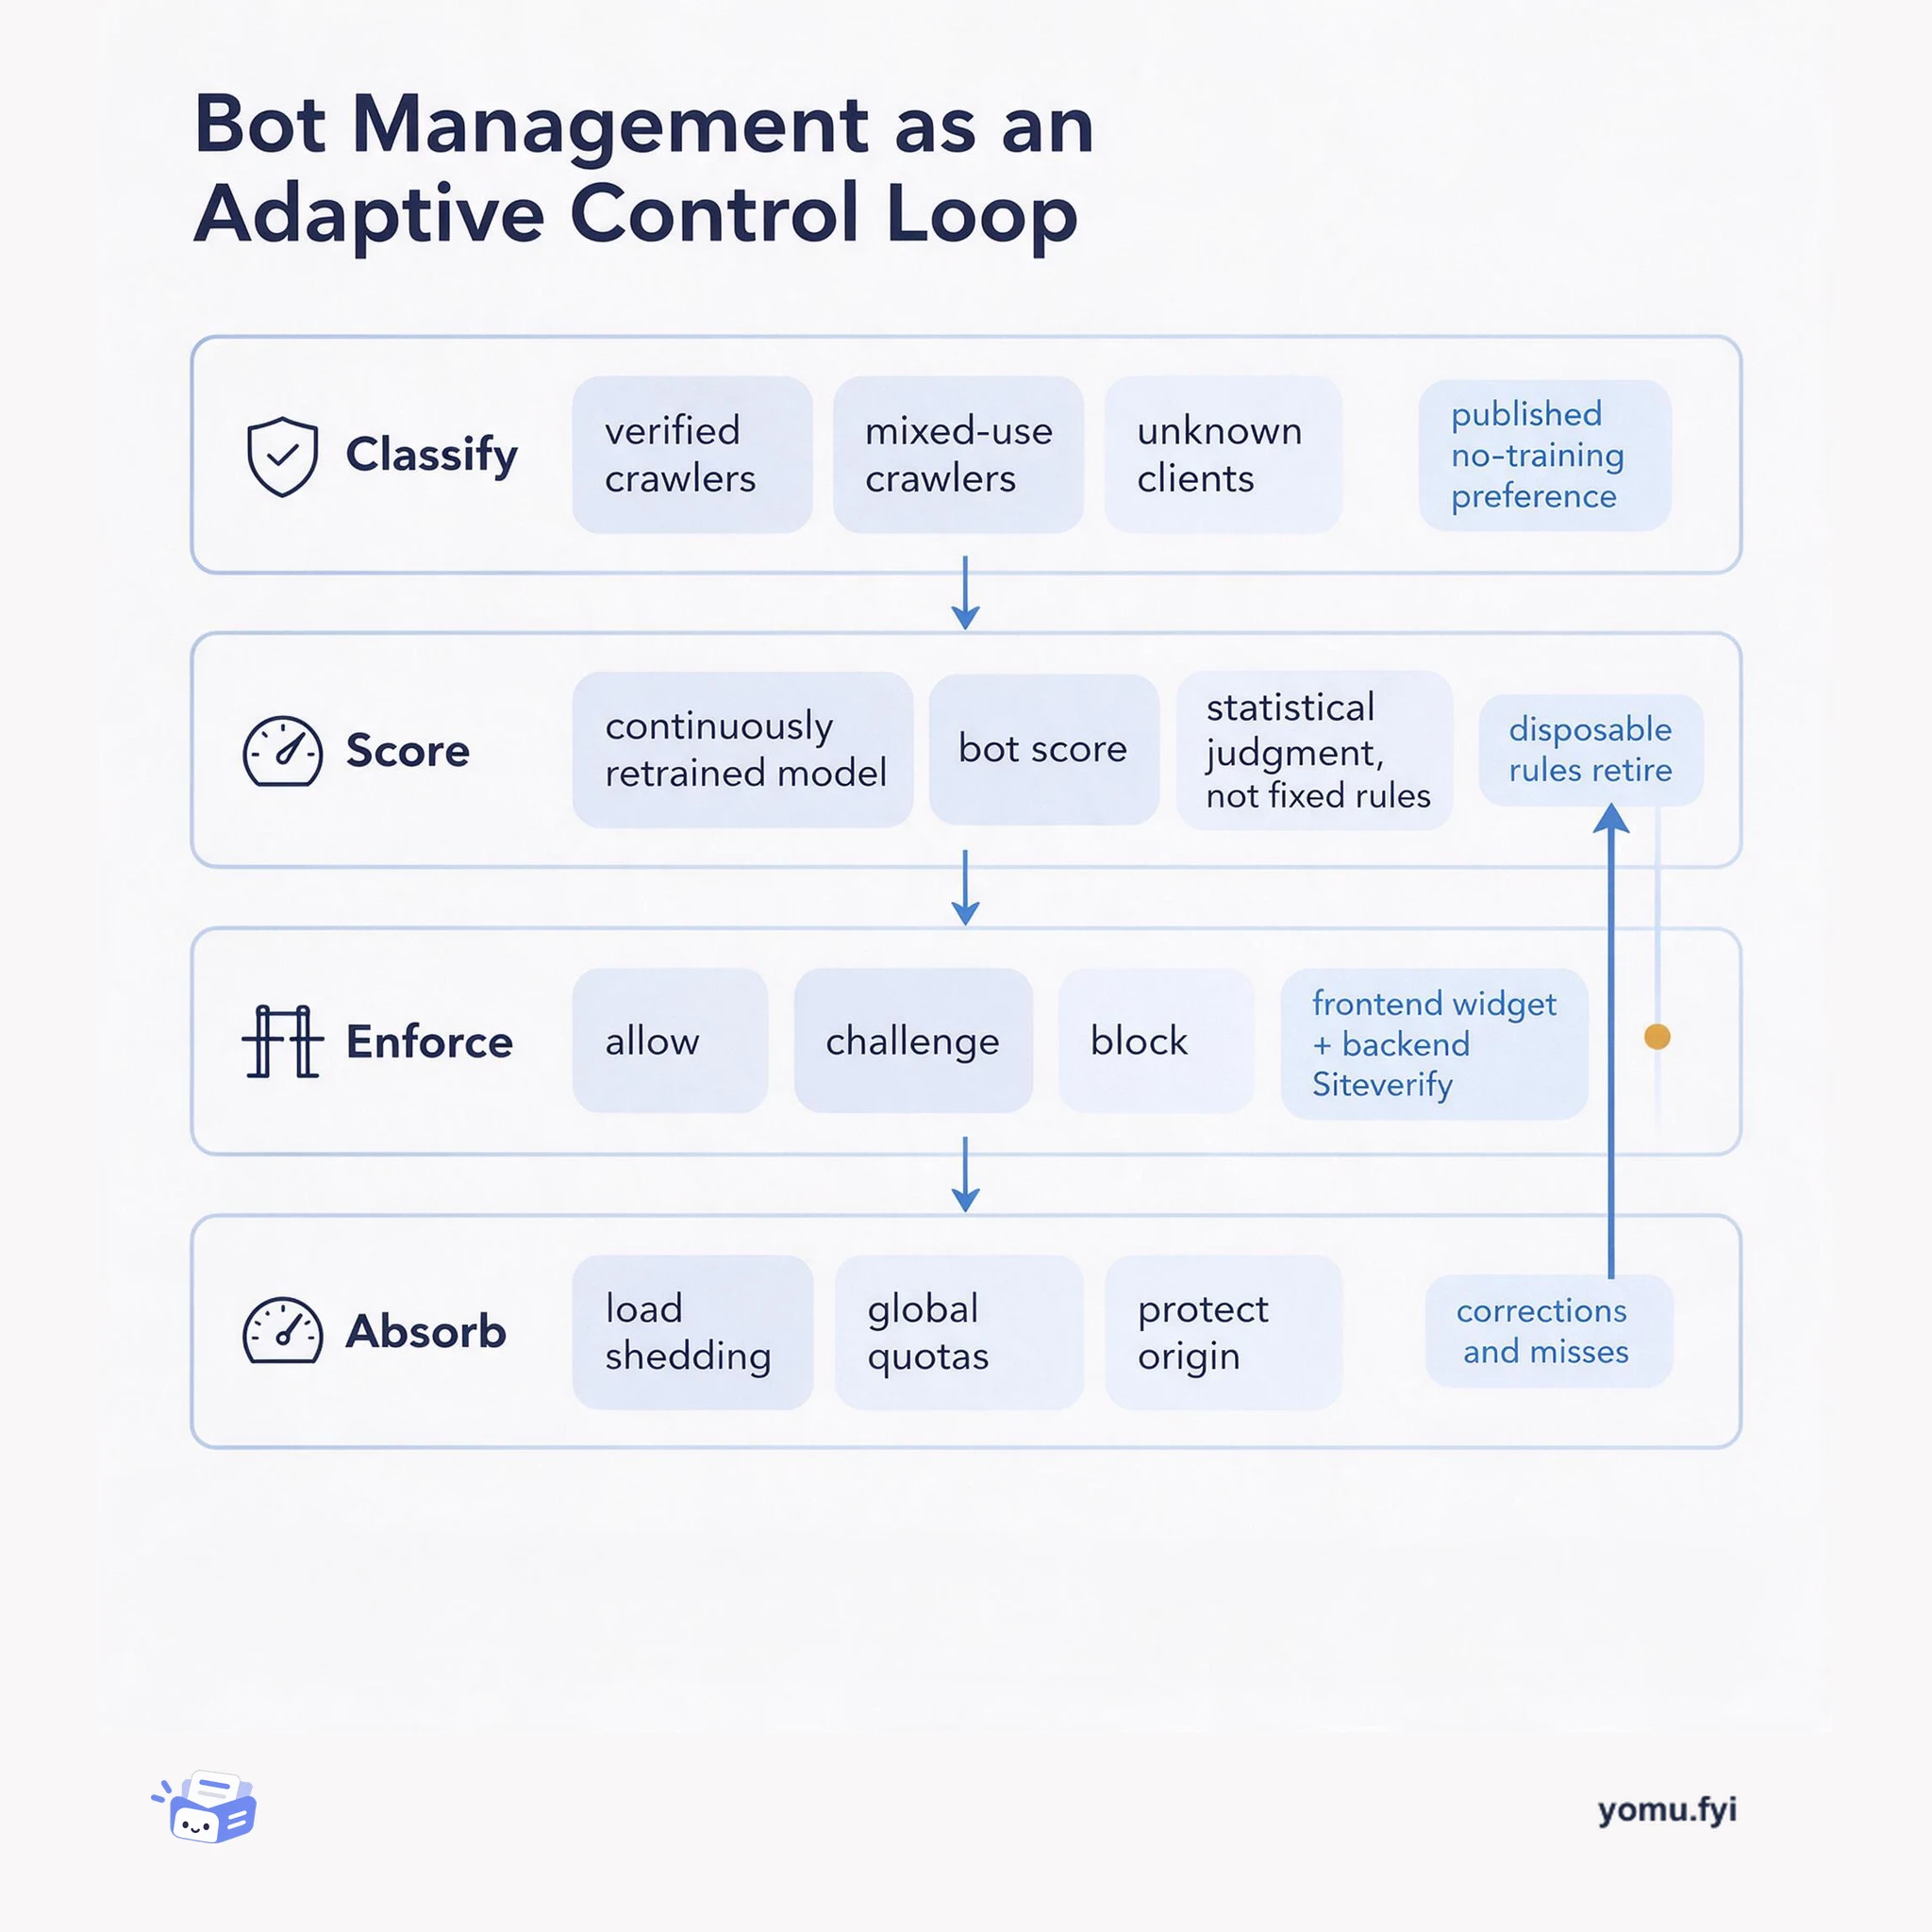
Bot management is an architecture, not a rule list: classify traffic, score it with continuously retrained models, enforce with challenges or blocks, then feed the outcomes back into the model.
 CloudflareBryan BeckerAnnouncement
Cloudflare announces a Disallow AI Training setting intended to let website owners refuse AI training while keeping content available to search crawlers. The problem is mixed-use crawlers such as Applebot, Bingbot, and Googlebot, which can serve both search indexing and model training, making a simple block affect discoverability. Cloudflare says its network can publish preferences, identify and classify crawlers, block those that ignore controls, and report operator behavior on Radar; the setting publishes a no-training preference through robots.txt while allowing Accountable mixed-use crawlers for search. Apple, Google, and Microsoft meet or have committed to meet the Accountable requirements, which include training and summary opt-outs, URL-level visibility, metrics, and assurance that training opt-outs will not affect traditional search.
The announcement addresses the tradeoff between allowing search indexing and allowing AI training when a single crawler performs both functions. It also describes Cloudflare’s Accountable designation for operators that provide control and transparency over training and AI summaries.
Cloudflare adds a domain-level Disallow AI Training control that publishes the applicable no-training preference in robots.txt. Accountable mixed-use crawlers remain allowed for search, while other training crawlers are blocked; Cloudflare also identifies crawler behavior, reports operator actions on Radar, and applies existing Block settings to mixed-use crawlers.
Disallow AI Training allows Accountable mixed-use crawlers to continue search crawling while blocking other training crawlers, including training-only crawlers run by Amazon, Anthropic, Meta, and OpenAI.
Block and Block on pages with ads now apply to mixed-use crawlers, so they can affect search visibility as well as AI training. Owners that want those crawlers removed entirely must select Block.
Cloudflare classifies crawler behavior as Search, Training, or Agent. There is currently no Disallow setting for Agents because the Internet lacks a well-established directive for expressing that preference.
Disallow AI Training keeps Accountable mixed-use crawlers allowed for search while blocking other training crawlers. Block stops all crawlers, including mixed-use crawlers, so it affects search discoverability.
A robots.txt directive cannot identify who is crawling, determine why they are crawling, or stop a crawler that ignores it. Cloudflare says its network can publish preferences, classify crawlers, block noncompliant ones, and report operator behavior.
Not currently. Agents do not create the same search-discoverability tradeoff, and there is not yet a well-established directive for expressing Disallow preferences to them; Cloudflare says it will revisit the approach as standards such as ai-prefs mature.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
Bot management is an architecture, not a rule list: classify traffic, score it with continuously retrained models, enforce with challenges or blocks, then feed the outcomes back into the model.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
