How Apache DataFusion Runs SQL In-Process
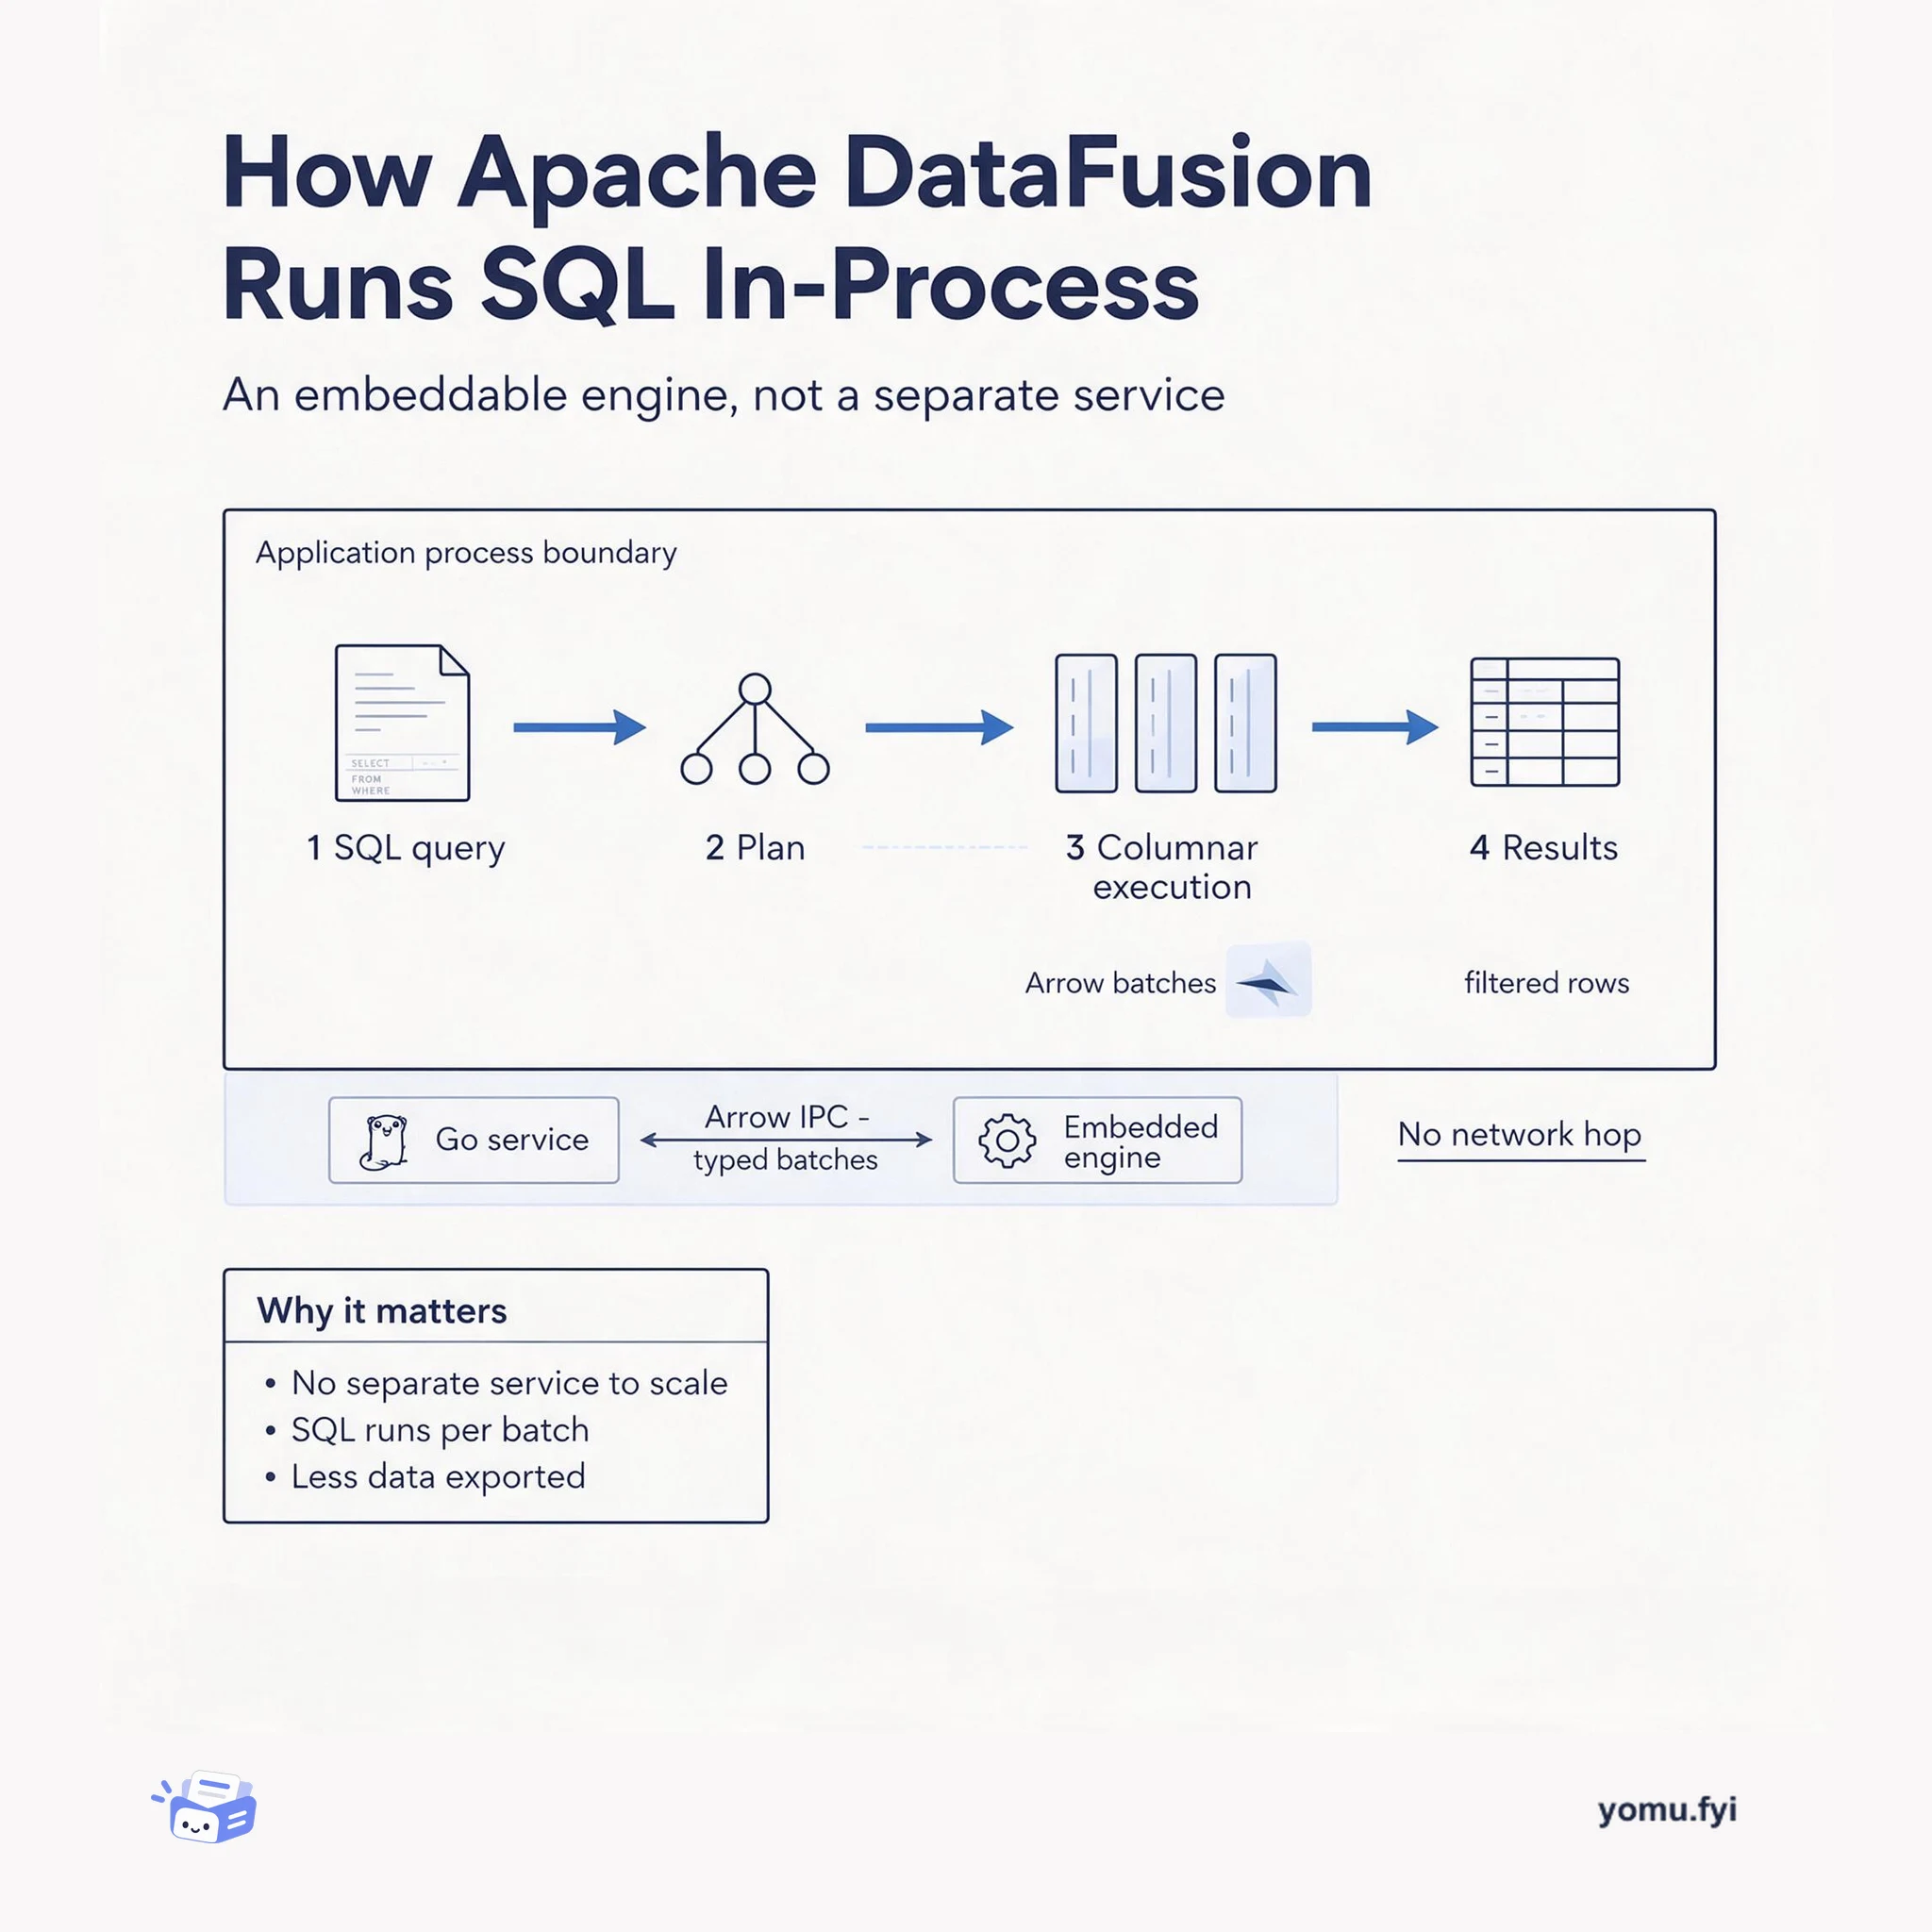
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
 CloudflareChristian EndresProblem & solution
Cloudflare’s Data team manages a pipeline handling over two billion events per second from tens of thousands of servers, powering Logs, SQL API, and observability. To counter exponential traffic growth against linear hardware expansion, they implemented several optimizations over five years, deferring two and a half years of hardware expansion. In 2022, they replaced a monolithic schema with product-specific schemas, reducing backbone bandwidth by 35-40%. In 2024, they switched compression from LZ4 to zstd, achieving a 40% reduction in compressed traffic with negligible CPU impact. In 2026, they decoupled pipeline transit from database redundancy via a shared ingest pool and late replication, applied sampling downstream, and introduced aggregations, eliminating about 70 GB/s of compressed traffic and halving projected 2031 data volume.
Cloudflare’s Data team manages the data pipeline that handles over two billion events per second from tens of thousands of servers across the global network, supporting products like Cloudflare Logs, SQL API, and observability.
The team implemented a series of optimizations: breaking the monolithic schema into product-specific schemas, switching compression from LZ4 to zstd, decoupling pipeline transit from database redundancy using a shared ingest pool and late replication, applying sampling downstream, and introducing aggregations into the pipeline.
Replacing a monolithic schema with product-specific schemas reduced backbone bandwidth by 35-40%, deferring about a year of traffic growth.
Switching from LZ4 to zstd compression achieved a 40% reduction in compressed traffic with negligible CPU impact.
Decoupling pipeline transit from database redundancy and applying sampling downstream eliminated about 70 GB/s of compressed traffic and halved projected 2031 data volume.
They switched from LZ4 to zstd compression, which provided a 40% reduction in compressed traffic with negligible CPU impact after careful rollout and monitoring.
They decoupled pipeline transit from database redundancy by sending each event once to a shared ingest pool and using late replication from centralized regions, eliminating the need for Logfwdr to send two copies.
Sampling was applied downstream after centralization, allowing high-volume traffic to be downsampled while rare events are preserved, reducing compressed traffic by about 25 GB/s across top datasets.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
