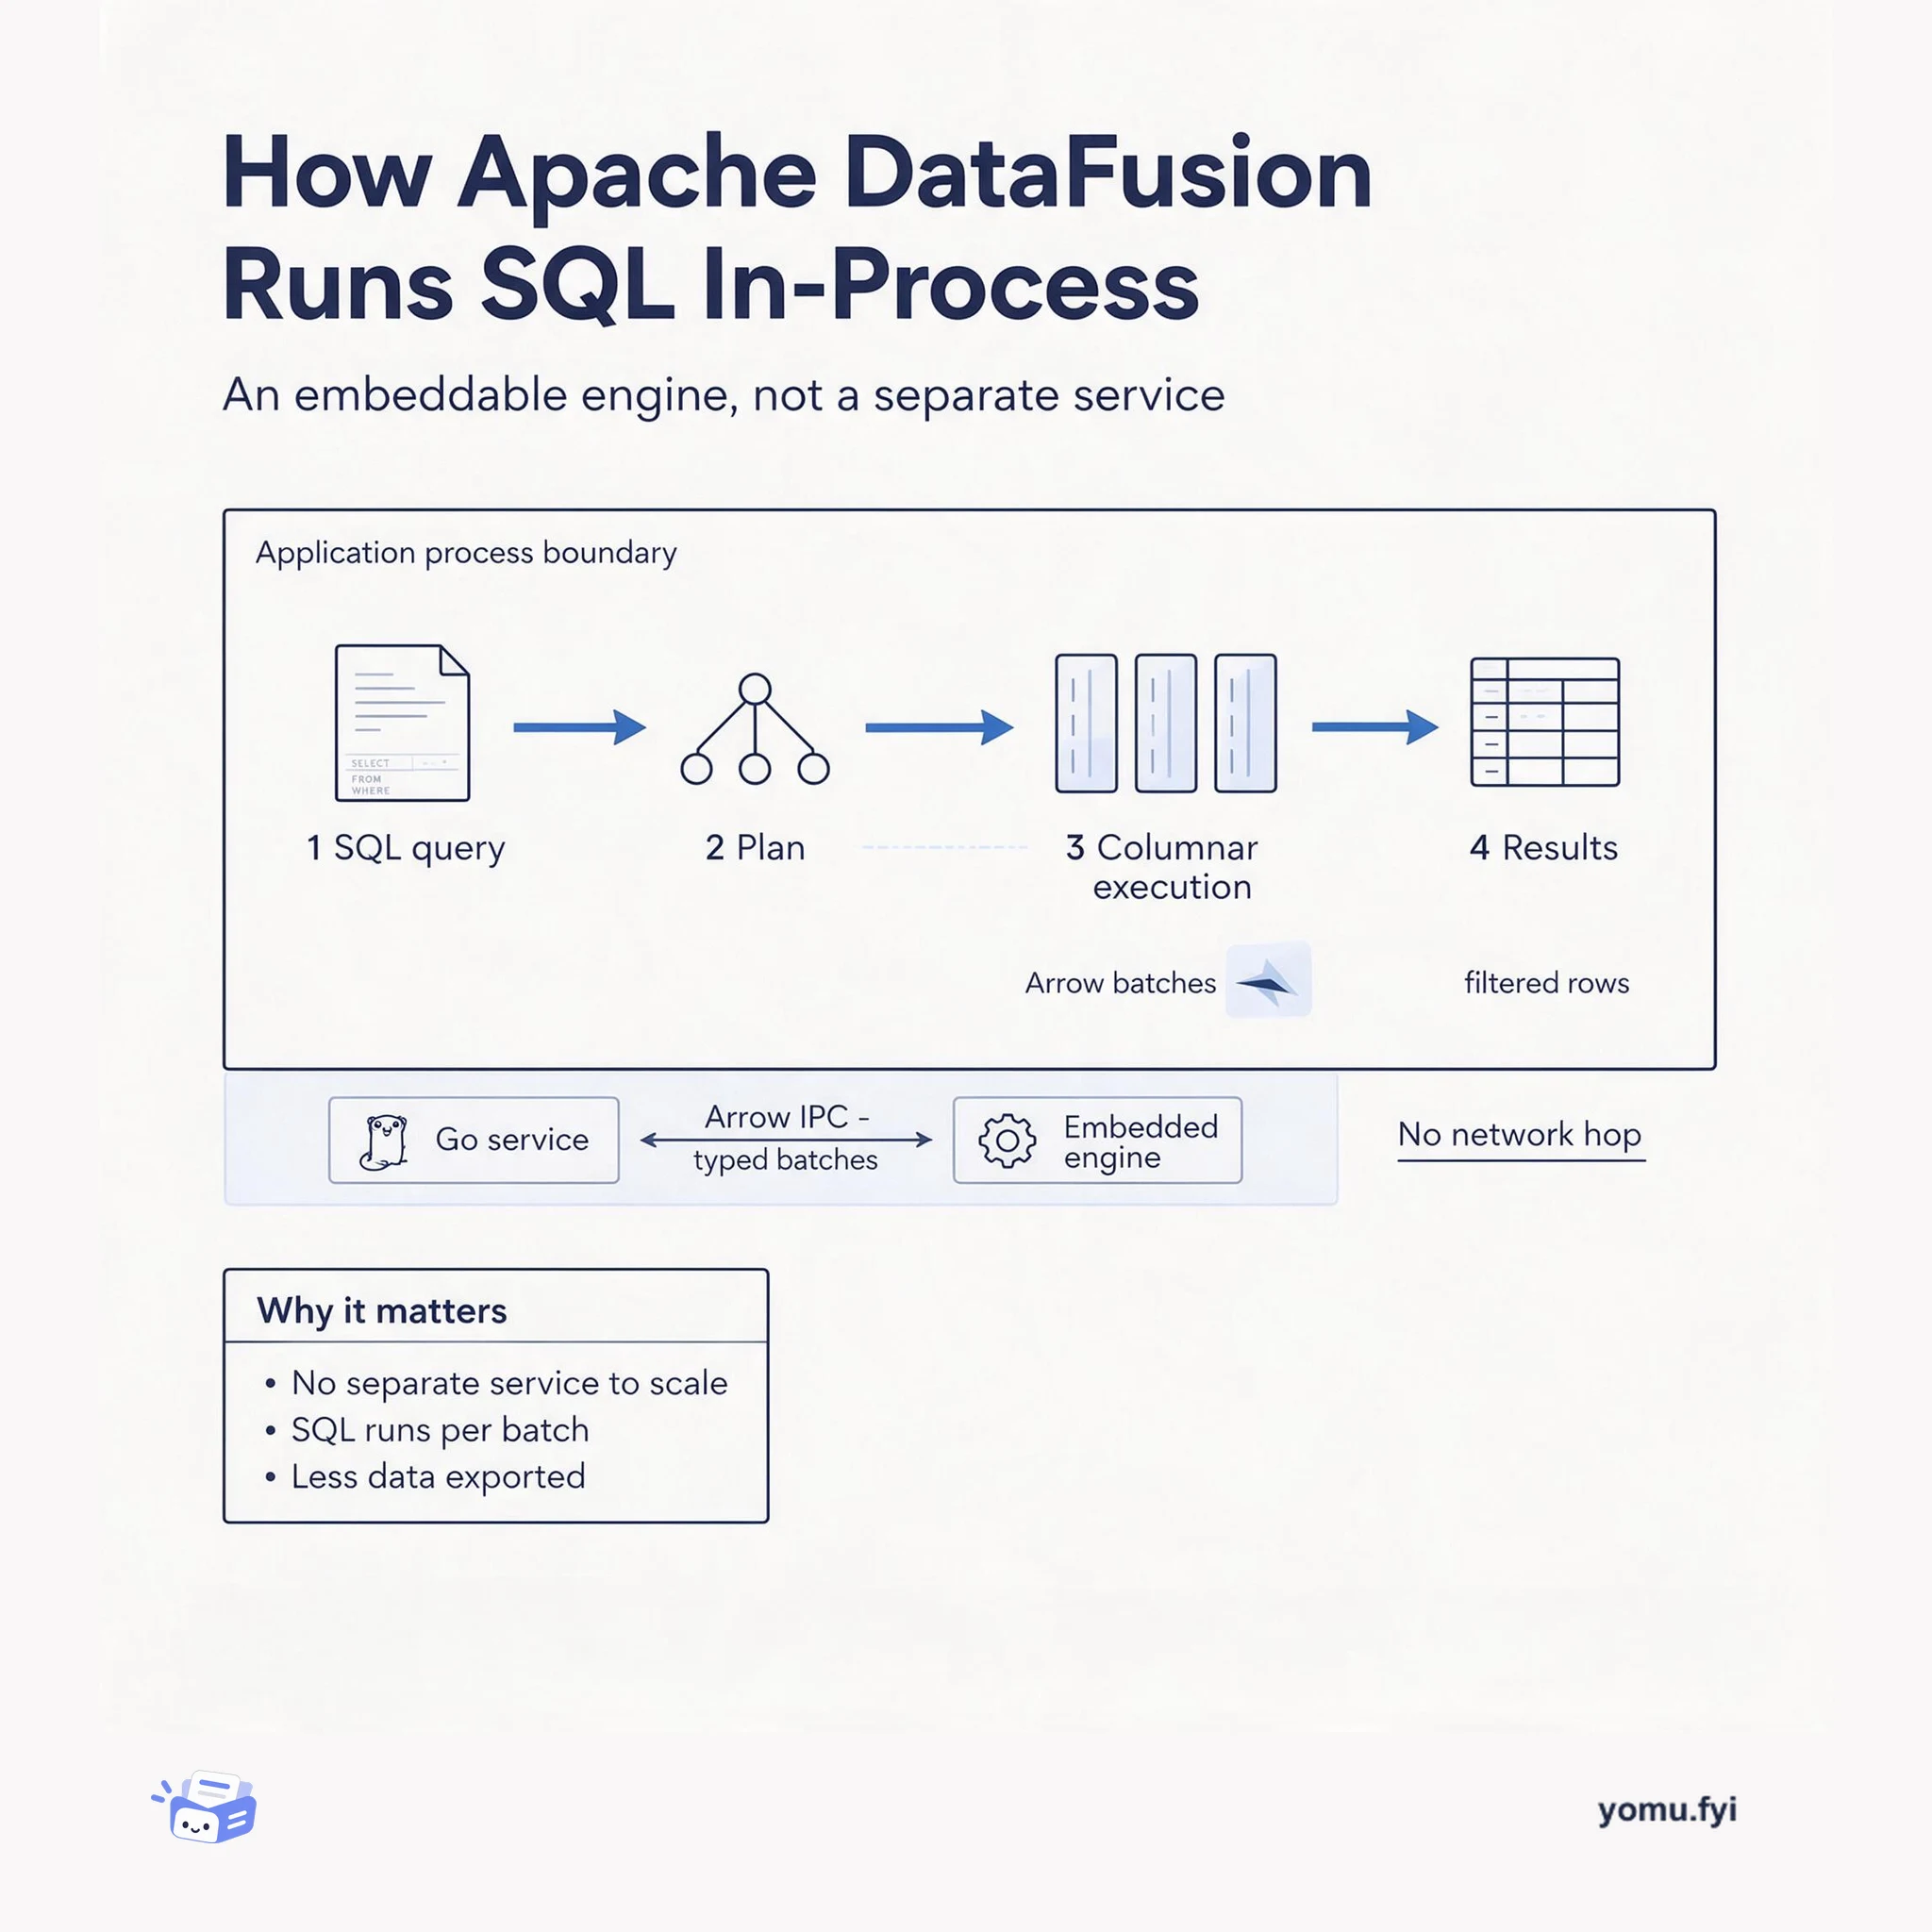
How Apache DataFusion Runs SQL In-Process
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
Loading…
Topic
42 posts about SQL. Every summary links to the original.
See the idea
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
Data teams frequently field questions about future sales, metric movements, and anomalous data, but answering them typically requires data science teams to build and manage models, creating a bottleneck. Predictive AI Functions, now in Beta, remove that bottleneck by providing SQL-native functions for forecasting, driver analysis, and anomaly detection, backed by state-of-the-art ML models maintained centrally by Databricks. The launch includes ai_forecast for time series projection, ai_top_drivers for segment driver analysis, ai_detect_anomalies for outlier detection, and ai_predict_value and ai_predict_class for regression and classification. These functions can be called directly in SQL, invoked through Genie with plain-language questions, or embedded in dashboards, delivering consistent, high-quality answers without infrastructure management. Benchmarking on fev-bench shows ai_forecast outperforms forecasting functions from leading cloud data warehouses, achieving industry-leading accuracy out of the box with no tuning required.
Cloudflare Logpush now supports Transformers, allowing teams to filter, redact, and reshape log streams using SQL before export to SIEMs, analytics platforms, or object storage. This eliminates the need for a separate processing service that teams would otherwise have to deploy, scale, and maintain. Transformers are SQL queries applied per batch within Logpush’s high-throughput pipeline, using Apache DataFusion and Arrow for columnar execution. The implementation embeds DataFusion in Bufstream, the Go-based delivery service, using cgo and Arrow IPC to pass typed batches across the language boundary without introducing network hops. Customers can create, preview, and version Transformers via the dashboard or API, and attach them to NDJSON Logpush jobs to reduce downstream data volume and cost.
Reactive cost management for cloud data warehouses fails because usage is unattributed, budgets are absent, and alerts arrive too late. Databricks’ proactive framework addresses this through five pillars: cost attribution via warehouse and query tags, layered budgets with email alerts, real-time dashboards, and optimizations. SQL Serverless warehouses eliminate idle compute costs, as Lumen Technologies demonstrated with a 30-40% reduction. Query tags (Public Preview) enable per-query attribution, linking spend to specific dashboards or dbt models. The post provides step-by-step instructions for tagging, budget creation in the Account Console, and tuning auto-stop and statement timeouts to reduce waste.
Repointing a dbt project to Databricks involves swapping the adapter and profile, handling SQL dialect differences, and keeping transformation logic unchanged. The dbt-databricks adapter bridges the project to Databricks Lakehouse, which uses a three-level namespace (catalog.schema.table) and supports open formats like Delta Lake and Apache Iceberg. Common dialect gaps include REGEXP_SUBSTR, DIV0, and OBJECT_CONSTRUCT, which can be fixed with Databricks-native functions or dbt_utils macros; the post walks through each error and its fix. After compilation and validation using audit-helper to compare outputs model by model, the project can be deployed as a dbt task in Lakeflow Jobs with built-in governance via Unity Catalog. The process is incremental: one-time setup costs apply, then each additional model requires only dialect fixes, making it a low-risk starting point for warehouse migration.
The data warehouse served structured SQL workloads for two decades, but the lakehouse now supports BI, data engineering, ML, streaming, and AI agents from a single governed platform. Databricks reports a 77% improvement in its production SQL workload mix since 2022, with customer migrations showing 90% faster queries (Lumen) and 80-90% faster analytics (Trek Bicycle). Lakehouse//RT delivers sub-second analytical queries at high concurrency directly on governed lakehouse tables, with Databricks reporting sub-100-ms latency at 12,000 queries per second, collapsing the traditional architecture of separate serving databases. The lakehouse eliminates data copying between systems, handles unstructured data, and runs on open formats like Delta Lake and Apache Iceberg, governed by Unity Catalog. Customer cost reductions range from 25% to 75%, with AXA Japan reducing warehouse costs by 60% and ETL costs by 70%, driven by eliminating redundant systems and data copies.
The 2026 Developer Survey gathered responses from over 30,000 developers over seven weeks, covering work patterns, technology usage, and AI adoption. Only 18% of developers work in an office daily, and the share of solo developers rose from 4% to 10%, possibly reflecting AI-enabled solopreneurship. In technology rankings, SQL surpassed HTML/CSS for the second spot, while Rust climbed to 12th most used language, potentially influenced by memory safety advocacy. AI usage is widespread: 73% of AI tool users employ them daily, with Claude Code (66%) and GitHub Copilot (59%) as leading agents, primarily for code generation (67%) and debugging (61%). Developers prioritize quality over cost (75% vs 38%) when using AI, and organizations implement cost controls like usage limits (38%) and model routing (27%), though 21% report increased spending.
Batch vector search workloads, such as entity resolution and semantic tagging, require high throughput across millions of queries against billions of vectors, unlike real-time serving. Databricks built NEAREST BY, a first-class top-k ranking join syntax, directly into its runtime engine rather than federating to an external endpoint. The feature is implemented as a logical join that the optimizer lowers onto standard relational operators, enabling fault tolerance and elastic parallelism. A fused Photon operator collapses the plan’s middle section with a blocked GEMM kernel designed to approach peak arithmetic intensity for vector scoring. An optional IVF index, stored as an ordinary liquid-clustered Delta table, allows approximate queries to probe only relevant clusters while preserving the same primitives and correctness guarantees.
Cloudflare announced eight major updates unifying logs, traces, analytics, alerts, dashboards, and data export into one observability platform with simplified pricing. The new Logs home combines Workers Observability and Log Explorer, letting users query datasets like HTTP events, firewall events, Workers, and R2 using SQL or filters. Cloudflare Traces, now in open beta, provides request-level visibility across security rules, transformations, caching, routing, Workers, and origin, with OpenTelemetry export and W3C trace context propagation. A unified SQL API lets humans and agents query telemetry across Cloudflare products, and custom alerts can be set on any dataset using threshold, anomaly, or SLO conditions. Pricing shifts to a volume-based model for ingested and stored logs and traces, effective December 1, 2026, with free tier at 0.5 GB ingestion per day and paid plans starting at 50 GB ingestion per billing cycle.
The announcement introduces the general availability of IP Functions, a feature that brings high-performance network analytics to the Lakehouse by enabling SQL-based processing of IP addresses. The post explains that IP data is warehousing data, as firewalls, load balancers, VPNs, CDN edges, DNS resolvers, Kubernetes clusters, and application servers emit streams of records keyed on IP addresses, generating tens of billions of events daily for large enterprises. These streams support valuable analytics such as threat detection, fraud investigation, and network governance. The post notes that network analytics used to be painful because IP addresses were deceptively hard to handle in SQL, with no regex support. The feature aims to simplify this by providing native IP functions for the Lakehouse.
Agent memory built on chDB, an embedded SQL OLAP engine, accumulated state such as project rules, user preferences, and recall traces on a single laptop. Moving that memory to CI, sandboxes, or another laptop broke the local-disk assumption because the MergeTree directory existed on only one disk. Adding a ClickHouse server backend fixed portability but turned every recall into a network round trip. The chDB Durable Layer fills the gap by keeping the local analytical hot path while publishing authoritative state to object storage (S3, GCS, or Azure Blob). Applications write to a local working copy and use flush() to publish writes and checkpoint() to compact the log, avoiding a sidecar or database server. The contract supports Python, Node, Go, and Rust bindings with cross-binding recoverability.
System One decision models such as Jev produce well-calibrated decisions from discrete options and are fast and cheap for large-scale applications, with potential use cases ranging from analyzing customer support transcripts to applying complex decisions at scale. Open-weight versions like SemIf-OpenJev are available, and Databricks enables serving them on governed data using serverless GPUs via AI Runtime, which provides on-demand GPU compute without managing infrastructure. The workflow is packaged in an importable notebook that downloads the model files, logs and registers the model using Express Deployments, and creates a GPU Model Serving endpoint automatically. The endpoint can be called from SQL via ai_query, which supports arbitrary custom model APIs, allowing structured request formats directly from SQL to return selected classifications and option probabilities as structured columns. The example classifies hotel reviews as good or bad, and users can import the notebook, select Serverless GPU, and run all to get started.
Modal and CMU built Quail, a query-aware inference layer for AI-SQL that combines a query planner with an inference engine to process structured LLM transformations of database entries. On a multi-join query, Quail achieves over a billion tokens per minute per H100 GPU, over 10x faster than vLLM, costing under 6 cents per billion tokens on Modal. The gain comes from using the query plan to order requests for better KV cache management, including a revised Hydragen-style cascade attention and batching small requests to reduce host overhead. On a new AI-SQL benchmark, Quail runs 1.84x faster than vLLM, but falls behind on agent trace processing. The authors see this as part of a trend toward custom inference engines for specific workloads, with a reusable core like databases post-DataFusion, and note that much work was done by prompting coding agents.
The relational data model organizes structured data in tables of rows and columns, with SQL used to access and manage it. Introduced by Edgar F. Codd in 1970, it uses schemas, domains, keys, constraints, and relationships to define and connect data. A relation schema specifies a table's structure, while a relation instance is the data held at a particular moment; primary, candidate, super, foreign, and composite keys support identification and referential integrity, and one-to-one, one-to-many, and many-to-many relationships model associations between tables. Functional dependencies inform normalization, whose 1NF, 2NF, and 3NF stages reduce redundancy and insertion, update, and deletion anomalies, though heavier normalization can require more joins. The model is used in banking, e-commerce, healthcare, education, and enterprise systems, where constraints and ACID transactions help preserve accuracy and reliability.
Databricks SQL’s generally available Default Warehouse lets administrators choose the SQL warehouse automatically used for ad hoc experiences, addressing manual selection and fallback behavior such as “Last Selected” or alphabetical ordering. A workspace-level setting applies across SQL Editor, Catalog Explorer, AI/BI Dashboards, Alerts, and Genie Spaces, while users can override it or retain “Last Selected”; admin APIs and a Terraform resource support per-user assignment, auditing, and control. The feature supports serverless, pro, and classic SQL warehouses and respects existing governance and access controls, with the setting opt-in and new assets automatically using it. In customer results, Catalog Explorer queries sent to smaller warehouses rose from 77% to 96%, and users running ad hoc SQL across multiple warehouses fell by 15%, while future coverage is planned for MLflow, Lakeflow CLI, and DBSQL MCP.
The post examines how enterprises can replace SFTP-based financial reconciliation with Stripe’s reporting APIs. Stripe’s Reports API v2 and Query Run API provide SQL-based report customization, consistent schemas, API-key permissioning, audit trails, and event-driven completion notifications instead of fixed files and polling schedules. Using fictional retailer Galtee, the examples run payout queries across multiple Stripe accounts with an Organization secret key, joining transfers with balance_transactions and using a succeeded webhook to trigger retrieval. Further queries join charges to add presentment amounts and exchange rates, then use aggregation and a common table expression to itemize IC+ fees; the conclusion is that this supports an on-demand pipeline that evolves with business requirements.
Auth0 FGA Permissions Index is announced in Early Access as a way for B2B SaaS applications to enforce permissions while handling expanding AI-agent activity and complex relationship graphs. Customers select relations used for search and filtering, typically high-cardinality relations such as can_view, and the index precomputes the access those relations imply. It streams the resulting data into the customer’s database alongside application data, allowing indexed permission checks through SQL JOINs instead of repeated authorization API calls or runtime graph traversal. Computation moves to relationship-write time, while relations outside the index continue to be evaluated by FGA in real time. The announcement positions this design as a path to consistently low-latency filtering at enterprise scale, with permission decisions described as precomputed, traceable, and compliant.
SQL's unordered-set model makes it difficult to detect ordered event sequences such as consecutive login failures followed by a success, especially when timing matters. MATCH_RECOGNIZE, now available in Databricks compute including Lakehouse Real-Time, expresses row sequences through regex-like states while supporting time anchoring and row-relative checks. The post shows its use for credential-stuffing anomalies, V-shaped stock reversals, checkout abandonment, and equipment-failure signals: FIRST can anchor a failure window, the end-of-partition marker $ can represent inactivity, and PREV/NEXT can compare sensor readings. By replacing chains of common table expressions, gaps-and-islands scaffolding, self-joins, and window-function logic, the clause is presented as easier to validate, maintain, and update for event-sequence analytics.
ClickHouse’s beta AI Functions let SQL queries call an LLM or embedding provider directly, keeping classification, extraction, generation, translation, redaction, filtering, embedding, and similarity work alongside stored data. The feature addresses workflows that export rows to separate LLM, orchestration, or vector-database systems and then reload results, with the stated goal of running the full RAG cycle in ClickHouse. Functions make remote HTTP calls per input, or batch embedding inputs, and return native ClickHouse values; in open-source deployments, named collections store provider credentials and endpoint settings. Examples use Hacker News data for topic classification and natural-language filtering, while the guidance emphasizes cheap predicates, quotas, LIMIT tests, prompt-injection defenses, non-determinism, cost, latency, and provider access to data in cleartext after TLS termination.
ClickHouse 26.8 is a long-term support release with 98 new features, 128 performance optimizations, and 556 bug fixes. It adds background queries, PostgreSQL-style regular-expression operators, array subscripting with multiple indices, expanded Parquet and data-lake integrations, and improvements for GROUP BY and joins. Background queries return immediately while continuing after client disconnection, with progress exposed through system.processes and completion details recorded in system.query_log; the example exports 243,619,704 rows to Parquet. Performance work includes dictionary-filter pushdown for Parquet, adaptive parallel GROUP BY processing, smaller hash-table cells for single-string keys, parallel merge joins, IEJoin for two-inequality conditions, and a cost-based optimizer for distributed plans. The PostgreSQL wire protocol supports psql commands such as \d, \dt, and \dv while the release adds text tokenizers.
SQL data types define what values columns accept, how those values are stored, and how databases process them, making type selection central to schema design. The reference covers numeric, character, date/time, and specialized types, noting that MySQL, PostgreSQL, SQL Server, and Oracle differ in naming, precision, limits, and storage requirements. It recommends choosing the smallest type that safely accommodates expected values, checking range, precision, NULL requirements, string length, and time-zone needs before deployment. Examples contrast CHAR with VARCHAR, DECIMAL with FLOAT, DATE with TIMESTAMP, and integer sizes such as TINYINT, INT, and BIGINT; indexes and distributed engines also benefit from right-sized data. Sample data, execution-plan analysis, storage measurements, schema audits, and documentation help validate choices, identify waste or overflow risks, and preserve reasoning behind edge cases.
The best engineering reads, once a week.







