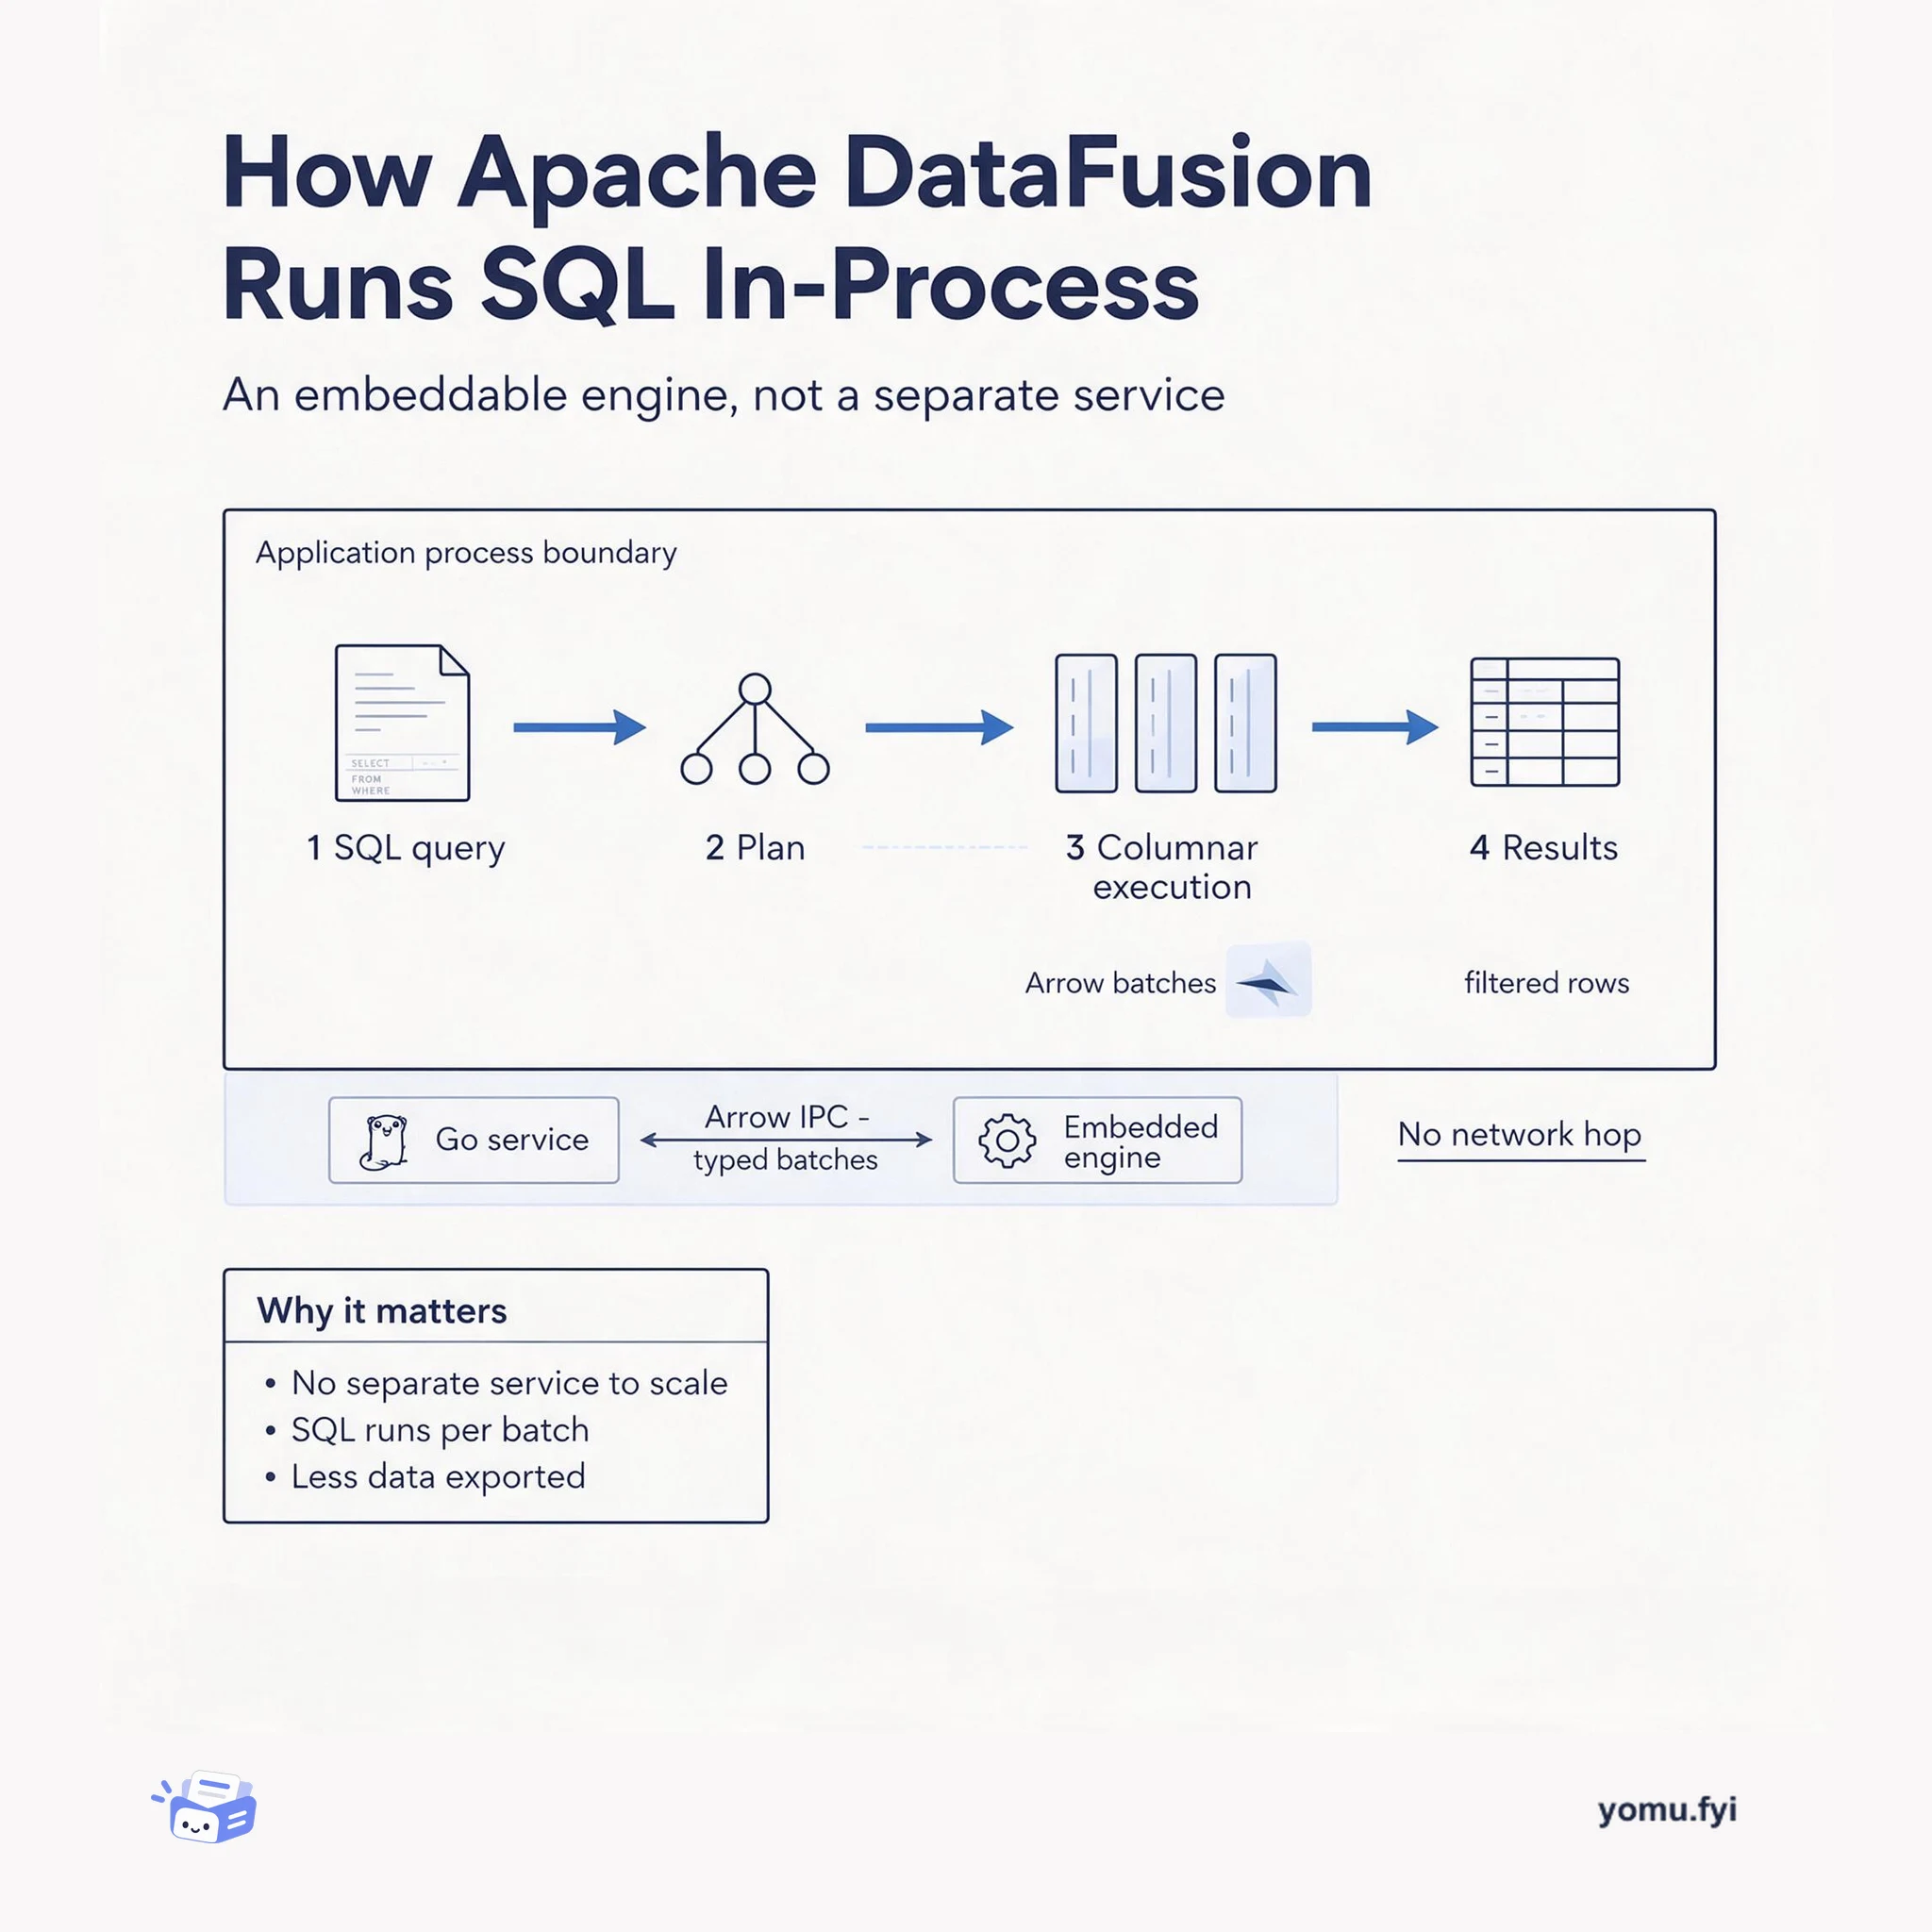
How Apache DataFusion Runs SQL In-Process
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
Loading…
Topic
1 post about UDF. Every summary links to the original.
See the idea
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
User-defined functions (UDFs) in Apache Spark break the declarative abstraction, forcing GPU-accelerated pipelines to fall back to CPU execution and incur data transfer overhead. NVIDIA cuDF addresses this with GPU parallelism, but UDFs remain a bottleneck due to their opaque code. The post describes three approaches to rewrite UDFs into GPU-accelerable forms: SQL expressions, the RapidsUDF interface using cuDF columnar operations, or custom CUDA kernels via JNI. The cuDF skills for Apache Spark automate this process with four agent-guided feedback loops for testing, conversion, benchmarking, and optimization, providing a project template and best practices. A production deployment converted over 30 UDFs, achieving a 22x speedup on a 600-billion-row workload, reducing operator time from 274.55 to 12.78 hours.
The best engineering reads, once a week.

