AWS Systems Manager: Closed-Loop Automation vs Manual Runbooks
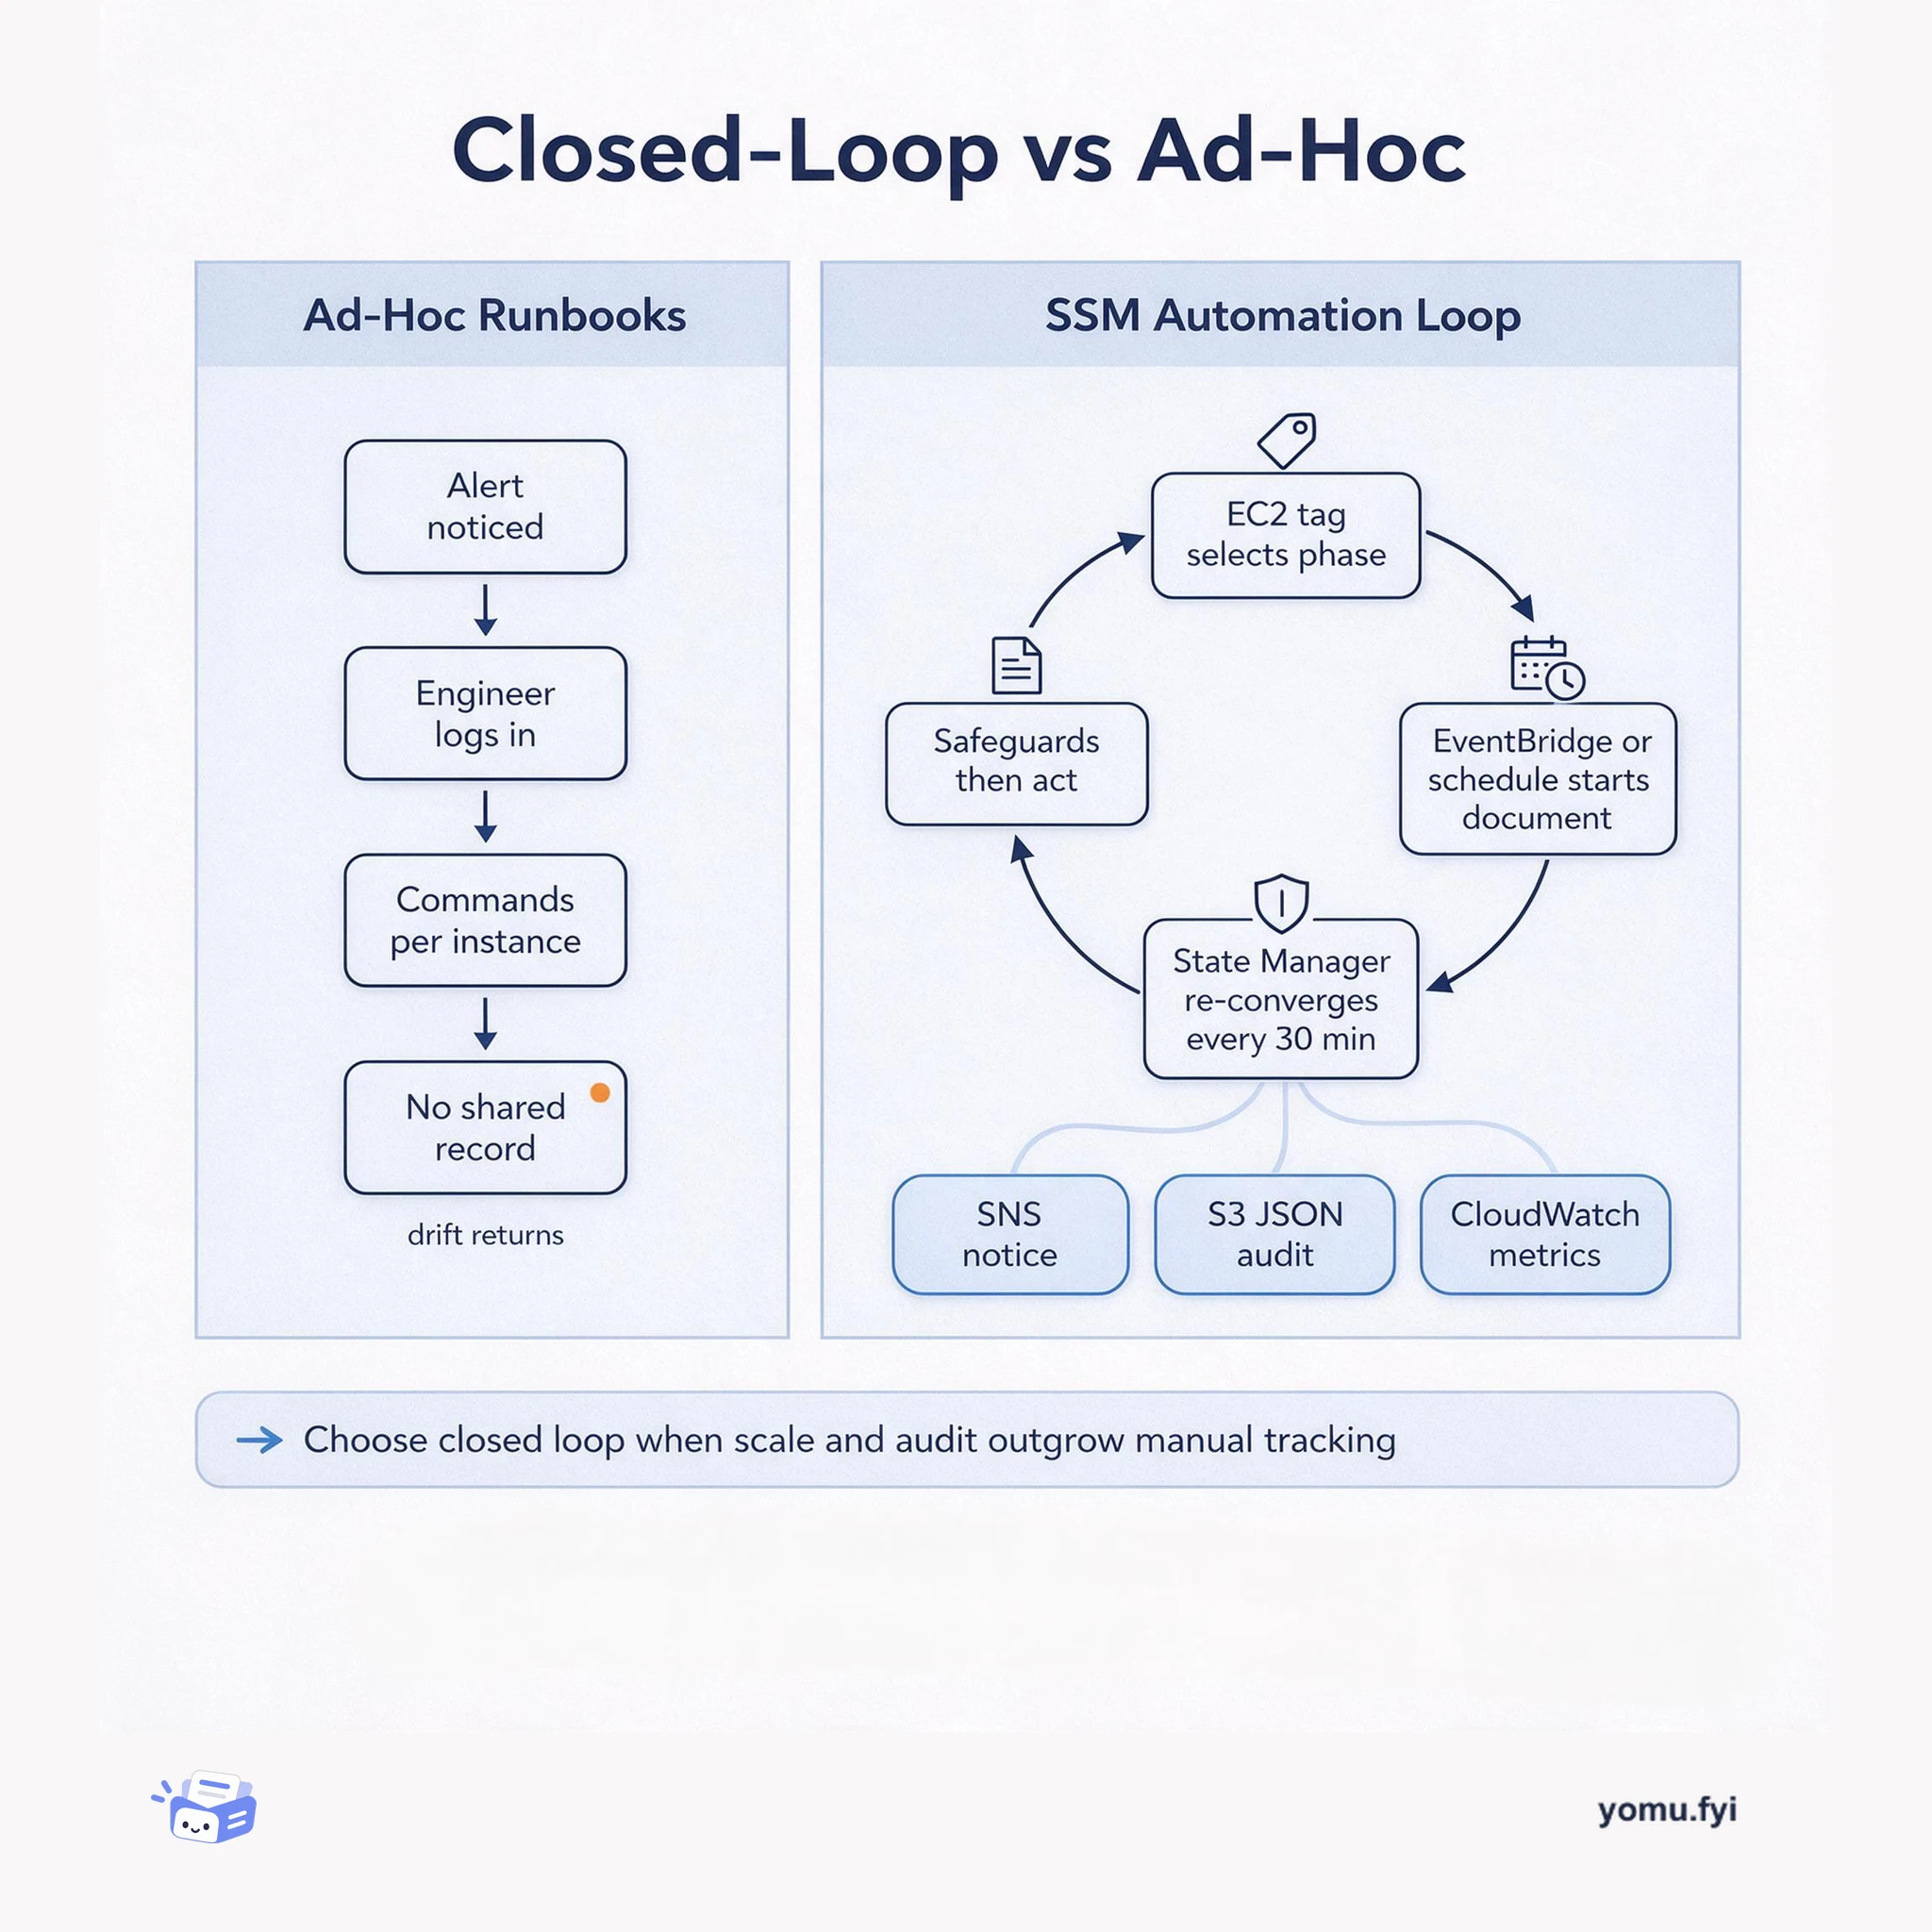
A side-by-side comparison of ad-hoc, human-run remediation and tag-driven AWS Systems Manager Automation, showing what each costs in audit trail, drift, and time to recover.
Loading…
Topic
1 post about AWS Systems Manager. Every summary links to the original.
See the idea
A side-by-side comparison of ad-hoc, human-run remediation and tag-driven AWS Systems Manager Automation, showing what each costs in audit trail, drift, and time to recover.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
An enterprise customer with more than 300 Linux and Windows instances in AWS Elastic Disaster Recovery scope had agents stall after network changes and descoped servers keep replicating and adding cost. The solution automates onboarding, healing, and offboarding through AWS Systems Manager Automation documents started by EventBridge or a schedule. A single EC2 DR tag with values yes, pause, or no selects the phase; unrecognized values are normalized, skipped, and logged as SKIPPED_MISCONFIGURED. Onboarding runs every 30 minutes through State Manager, healing restarts or reinstalls the agent for agent-side stalls and escalates infrastructure stalls through Amazon SNS, and offboarding checks safeguards before stopping replication, deleting the source server, uninstalling the agent, and removing tags. Offboarding records whether replication billing stopped, while the documents emit SNS notifications, per-event JSON audit reports to Amazon S3, and CloudWatch Outcome metrics.
The best engineering reads, once a week.