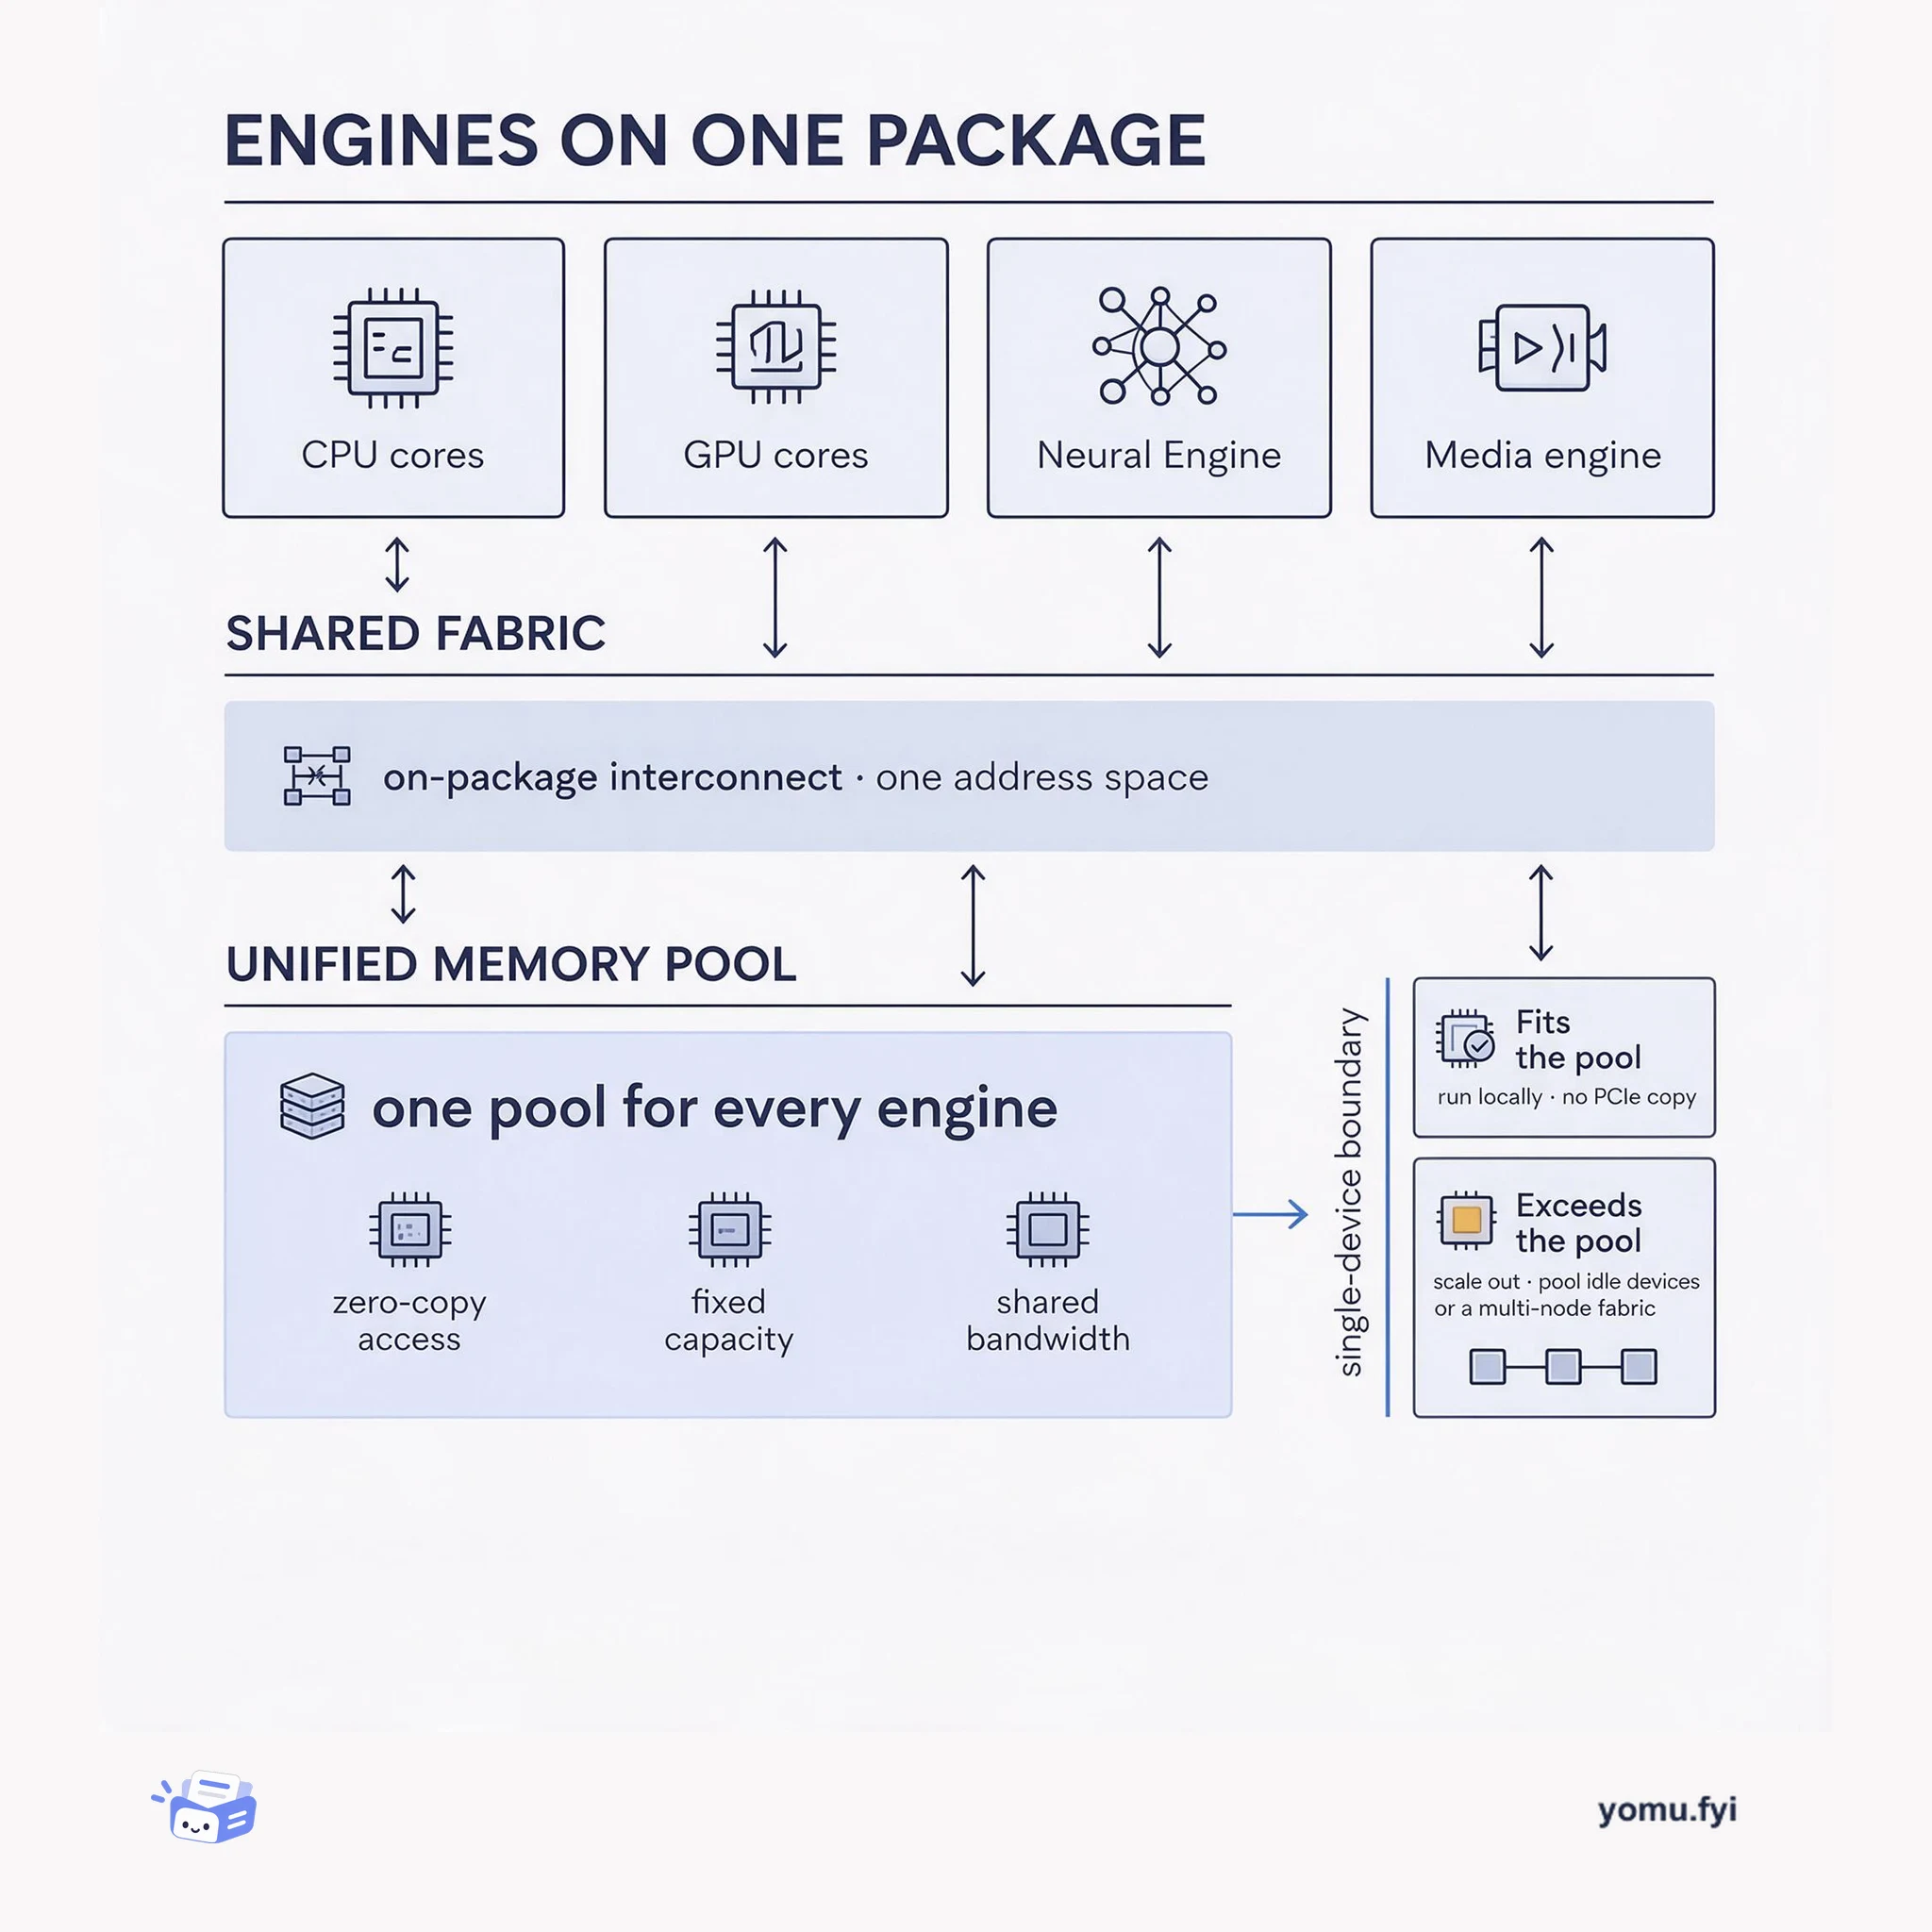
One Pool, Many Engines: The Architecture of Apple Silicon
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
 AppleProblem & solution
Minions is a dynamic, distributed virtual GPU cloud that aggregates idle Apple Silicon GPUs across macOS devices to run large-scale machine learning inference. The work responds to limits in centralized GPU infrastructure, including high cost, limited elasticity, and long wait times when resources are constrained. Demand for GPU-accelerated machine learning inference keeps rising, while modern Apple Silicon macOS devices carry powerful GPUs that stay largely idle during normal usage. Minions offers flexible GPU inference task execution and provides fault tolerance and efficient resource utilization, letting teams use existing hardware in place of additional GPU procurement. The authors report that idle macOS devices can become a practical distributed GPU inference platform in environments where centralized GPU resources are constrained.
The supplied excerpt points to related readings on running models locally. MLX lets users run and explore LLMs efficiently on Macs and experiment with inference or fine-tuning techniques in a private environment on their own Apple silicon hardware. Separate efforts target accelerating LLM inference both on Apple silicon and on the NVIDIA GPUs widely used for production applications across the industry.
Minions aggregates otherwise idle Apple Silicon GPUs spread across macOS devices into a dynamic, distributed virtual GPU cloud that executes large-scale machine learning inference workloads. It is positioned as a way for teams to draw on hardware they already own rather than buying additional GPUs, which the source frames as avoiding extra GPU procurement. The system provides flexible GPU inference task execution together with fault tolerance and efficient resource utilization. The supplied text describes these capabilities at the system level.
Centralized GPU infrastructure is described as costly, only partially elastic, and prone to long wait times when resources are constrained, which motivates looking for inference capacity outside dedicated GPU pools.
Minions pools idle Apple Silicon GPUs across macOS devices into a distributed virtual GPU cloud for large-scale machine learning inference, so teams can use existing hardware rather than procure more GPUs.
The system is presented as offering flexible GPU inference task execution, fault tolerance, and efficient resource utilization, with the reported experience that idle macOS devices can serve as a practical distributed inference platform where centralized GPU resources are constrained.
The source cites high cost, limited elasticity, and long wait times under resource constraints as the limitations of centralized GPU infrastructure. Growing demand for GPU-accelerated machine learning inference is what exposes those limits and motivates aggregating idle Apple Silicon GPUs instead.
It aggregates their largely idle GPUs into a dynamic, distributed virtual GPU cloud that executes large-scale machine learning inference workloads. The stated benefit is that teams can leverage existing hardware without additional GPU procurement.
The paper states that Minions provides flexible GPU inference task execution, fault tolerance, and efficient resource utilization. It also reports that idle macOS devices can be transformed into a practical distributed GPU inference platform where centralized GPU resources are constrained.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
