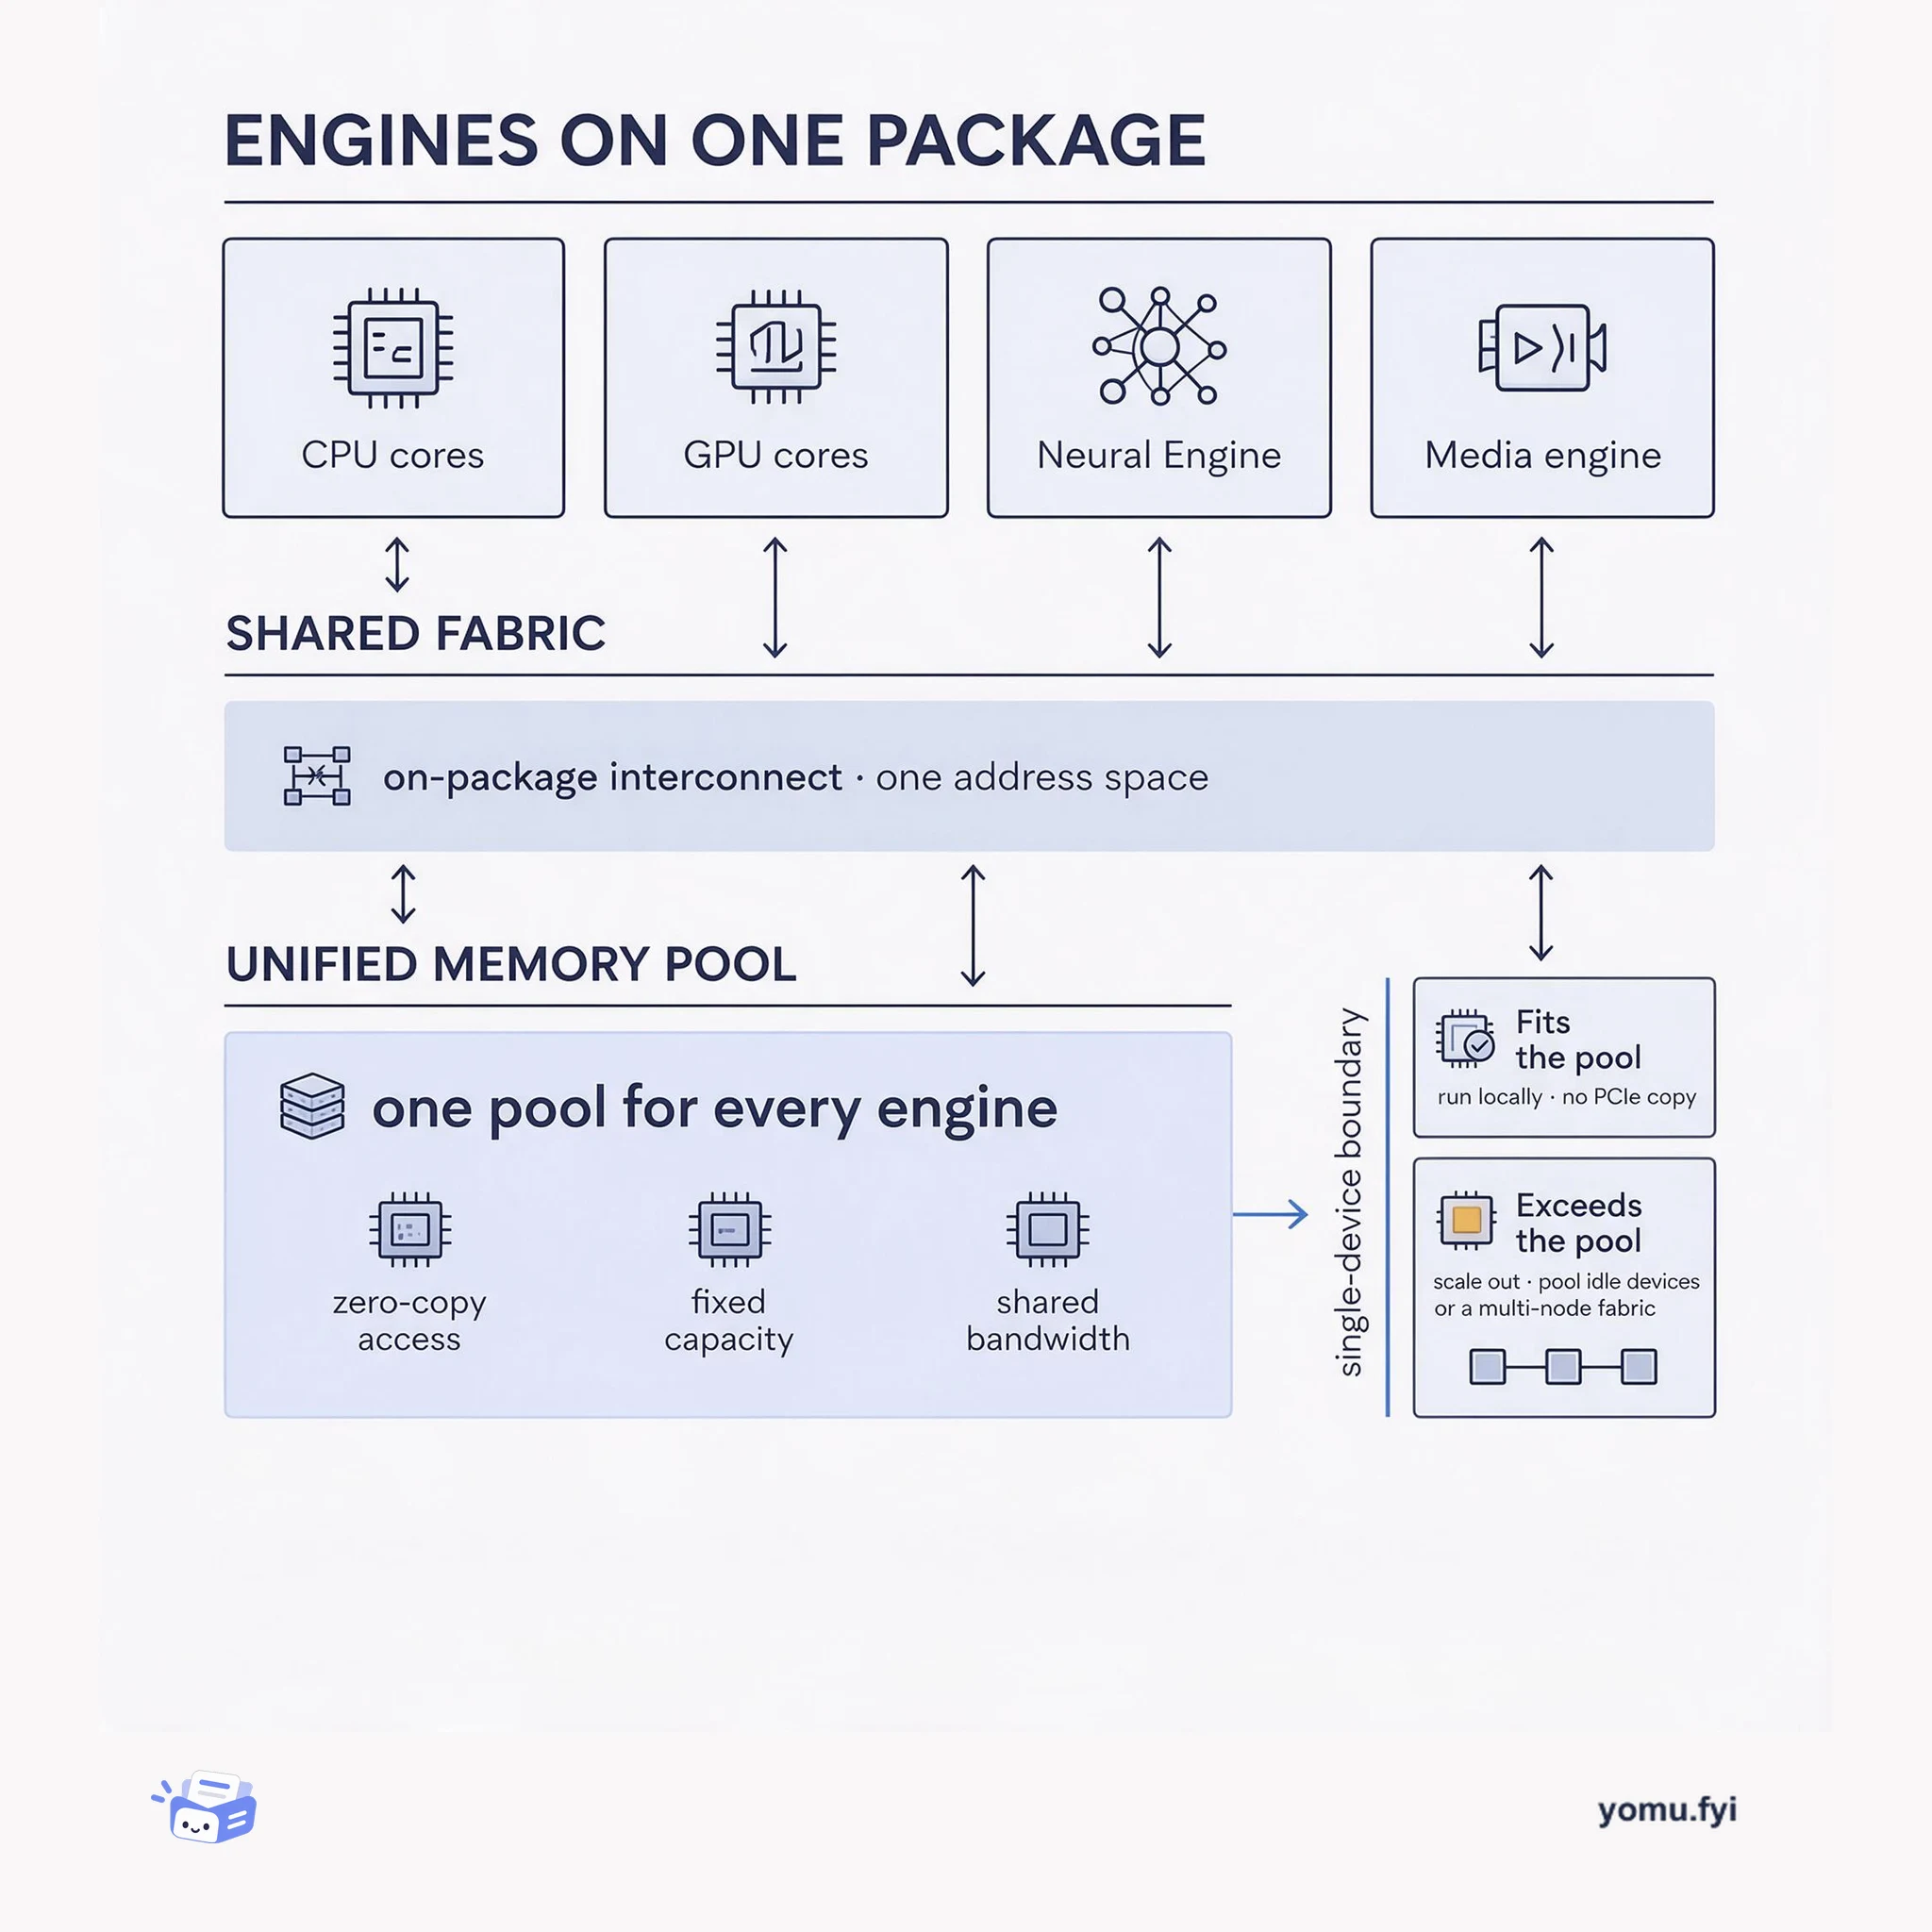
One Pool, Many Engines: The Architecture of Apple Silicon
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
Loading…
Topic
2 posts about MLX. Every summary links to the original.
See the idea
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
MLX enables running large language models locally on Apple silicon by exploiting the unified memory architecture of Mac Studio. The latest MLX release supports distributed inference across multiple Macs using RDMA over Thunderbolt, with pipeline or tensor parallelization schemes, and uses the jaccl communication collective. Benchmarks compare M3 Ultra and M5 Ultra across three models: Qwen 3.8 (27B) and Mistral Medium 3.5 (128B) fit on a single 512GB Mac, while the newly released Muse Spark Open (816B) requires parallelization across up to four machines at its 4-bit NVFP4 quantization. The M5 Ultra’s GPU Neural Accelerator delivers up to 4.6 times faster time-to-first-token than the M3 Ultra, while its 1.2 TB/s memory bandwidth improves generation throughput by 1.6 times for dense models. On four M5 Ultra Mac Studios with tensor parallelism, Muse Spark Open achieves over 36 tokens per second.
Jun Kim, creator and maintainer of oMLX, has joined Hugging Face to support the MLX community. MLX is Apple’s framework for local AI, optimized for Apple Silicon, and Hugging Face is the Hub for MLX models. oMLX, staying Apache 2.0, will gain stability and faster development as a funded, maintained project, allowing Jun to guide contributors and build for the long term. The goal is to unblock the community to run local AI in any form, with oMLX serving as a testbed leveraging dependencies like mlx-lm and mlx-vlm, and collaborating with projects such as LMStudio. A key focus is streamlining the transition from transformers model definitions to reference MLX implementations for different engines, so each can focus on unique features.
The best engineering reads, once a week.


