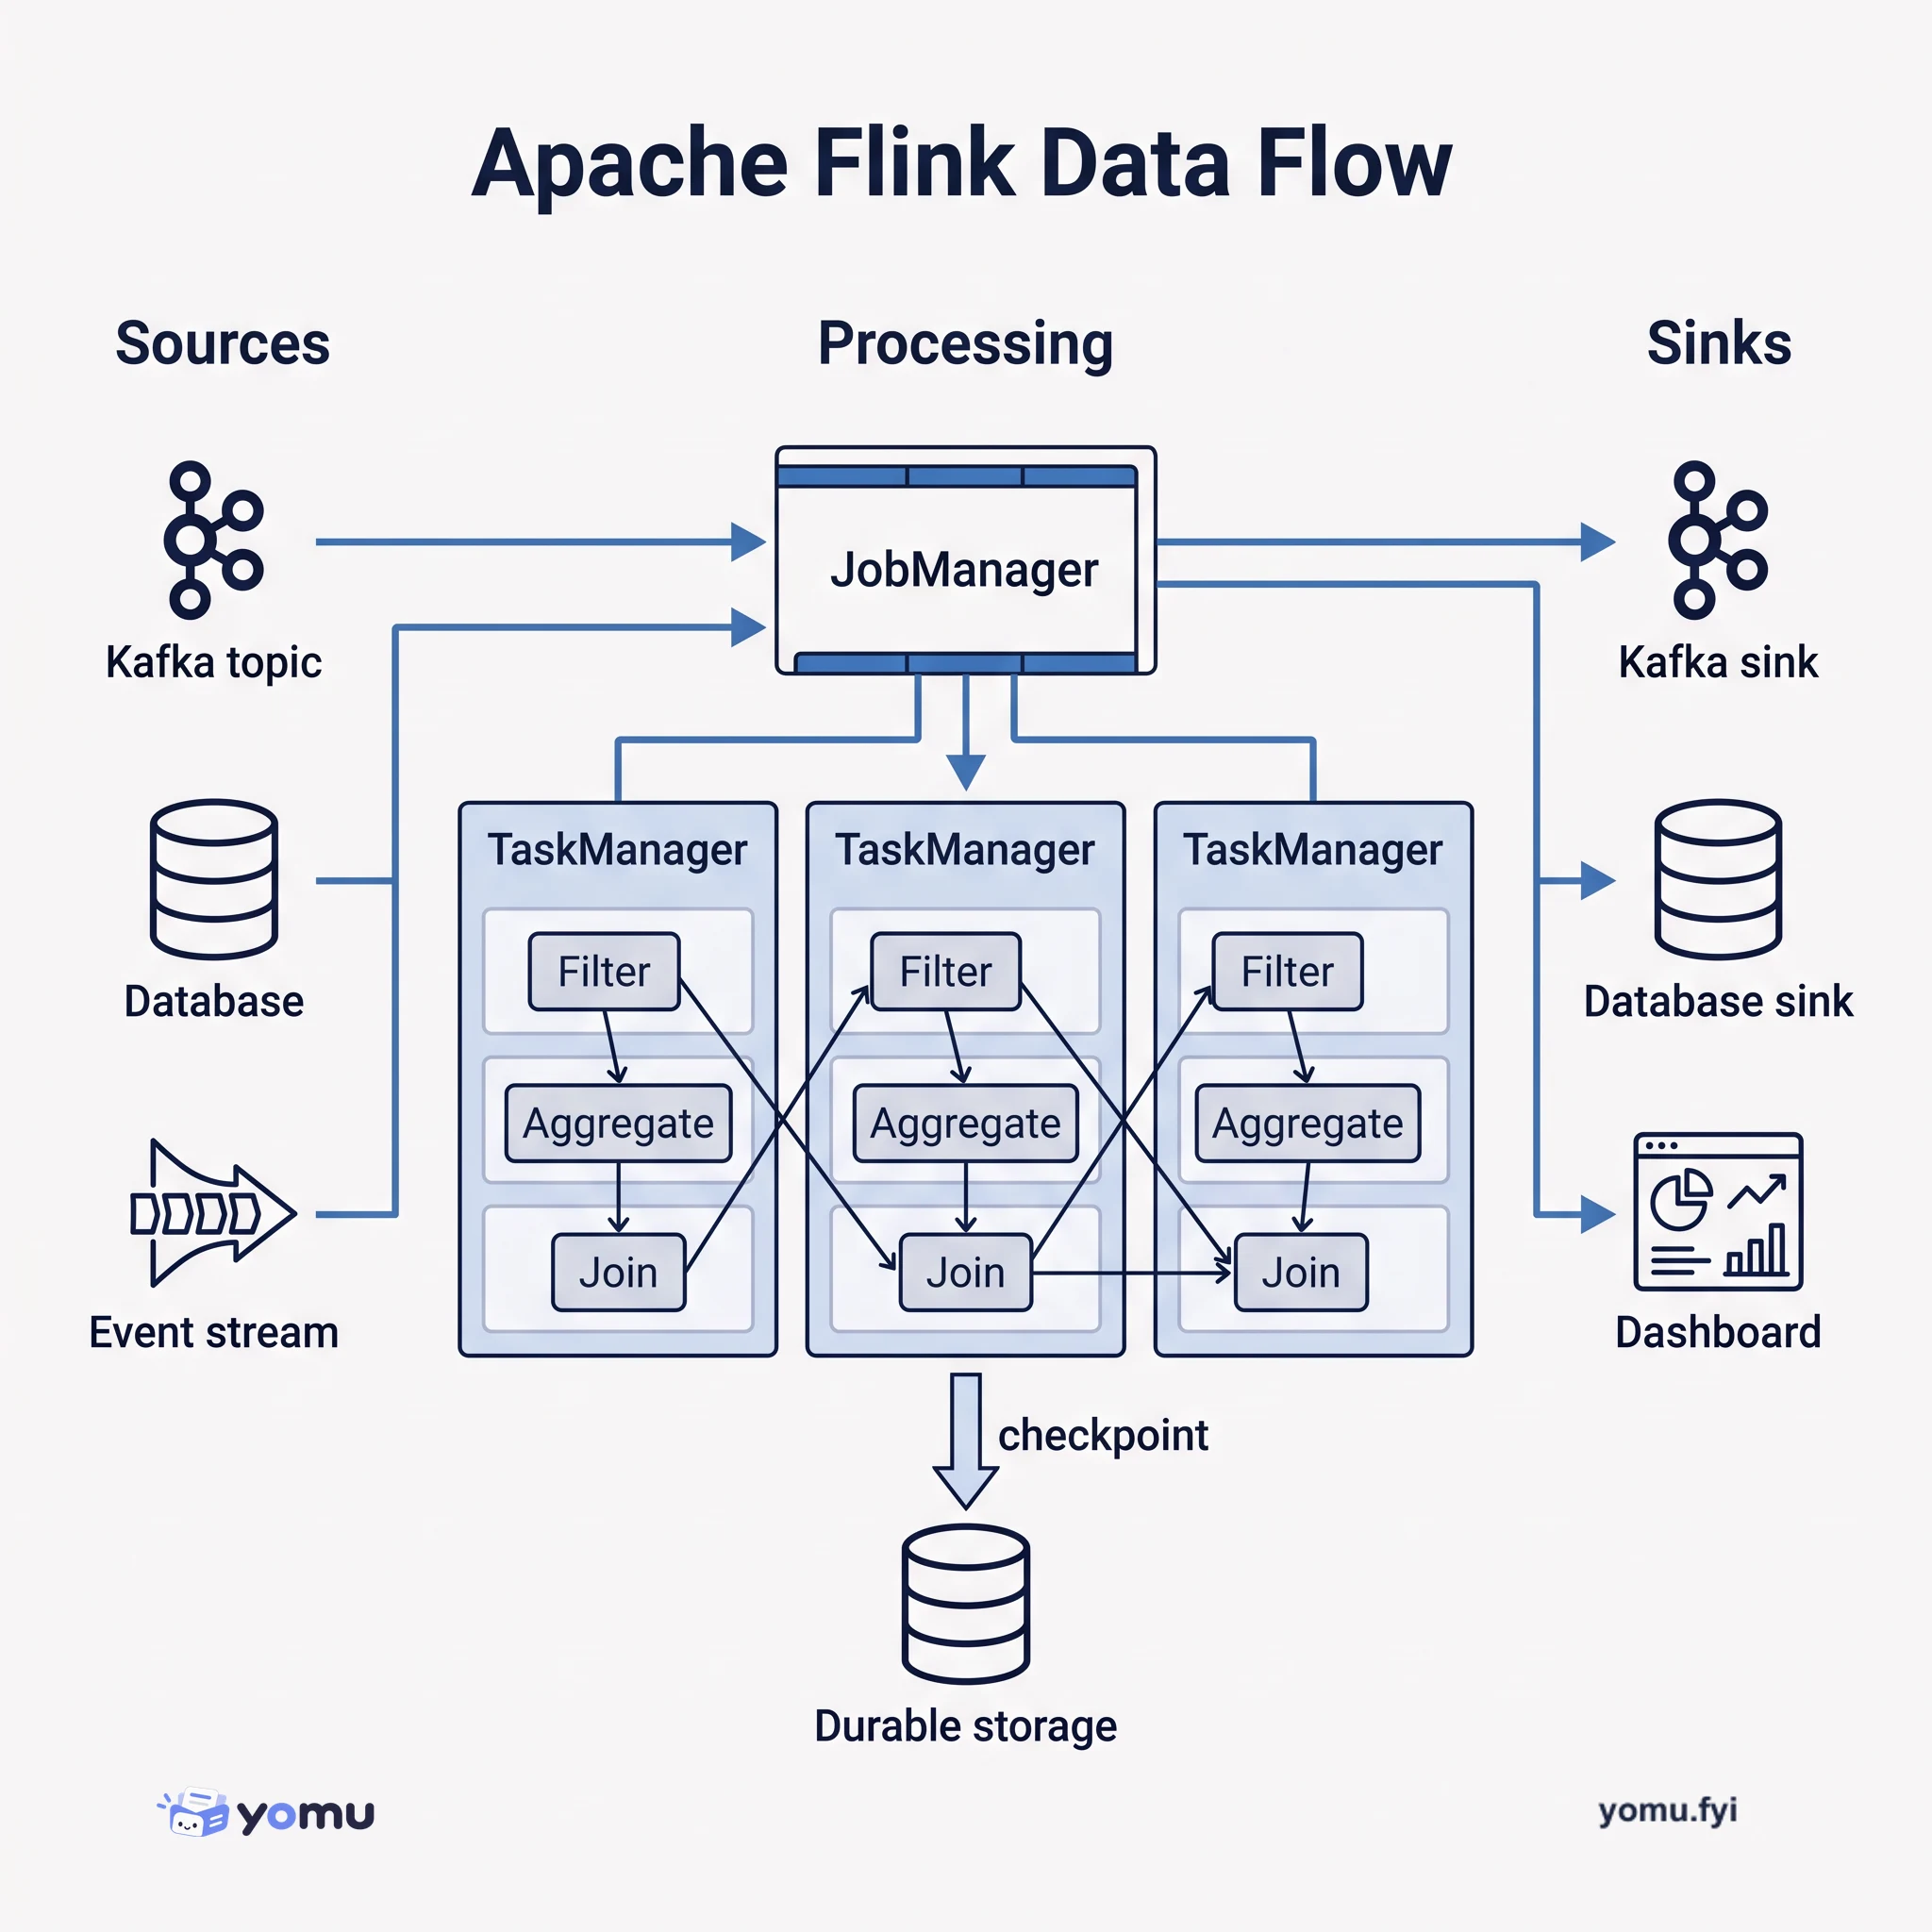
How Apache Flink Processes Streaming Data
Apache Flink is a distributed stream-processing framework that ingests continuous data, applies transformations in parallel, and outputs results with fault tolerance and low latency.
 Hugging FaceNicholas Fuller, Sean Falconer, Ayhan Sebin, Bilge Zeren Aksu, Mountu Jinwala, Pankaj Dayama, Roman Vaculin, Siddharth Bedekar, Julian PayneAnnouncement
IBM and Confluent are making IBM Granite Time Series foundation models available in Early Access on Confluent Cloud, bringing forecasting and other time-series capabilities into streaming workflows. The announcement addresses the cost and delay of bespoke models by offering models that generalize across previously unseen series and can be used for forecasting, anomaly detection, similarity search, classification, gap-filling and optimization. Native inference runs directly in Apache Flink through Confluent’s AI_FORECAST and AI_DETECT_ANOMALIES functions, with Flink maintaining keyed, fault-tolerant state for each series and results written to Kafka topics. Confluent manages serving, scaling and runtime operations while retaining schemas, lineage, access controls and replayable data within the platform. Early Access starts on Confluent Cloud on AWS at no charge, with Confluent Platform planned next for on-premises and hybrid environments.
Bespoke time-series modeling requires one model at a time and months of expert work, leading teams to cover many series with safety margins such as extra inventory, headroom or tolerance. Those decisions may be acted on after the useful forecasting window has closed.
IBM Granite Time Series models are exposed through Confluent Cloud’s native Apache Flink inference, using AI_FORECAST and AI_DETECT_ANOMALIES functions. Flink maintains state per series, while Confluent handles serving, infrastructure, scaling and runtime operations and applies platform governance, security and delivery mechanisms.
Early Access requires no model training, feature engineering or AI/ML expertise; teams can call the capabilities using familiar Flink SQL syntax.
Inference results are written to durable, replayable Kafka topics, supporting auditing, troubleshooting, model evaluation and rerunning inference against historical data.
The portfolio contains four complementary time-series foundation models, and users can switch models with one SQL parameter without redesigning the pipeline.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
Apache Flink is a distributed stream-processing framework that ingests continuous data, applies transformations in parallel, and outputs results with fault tolerance and low latency.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
