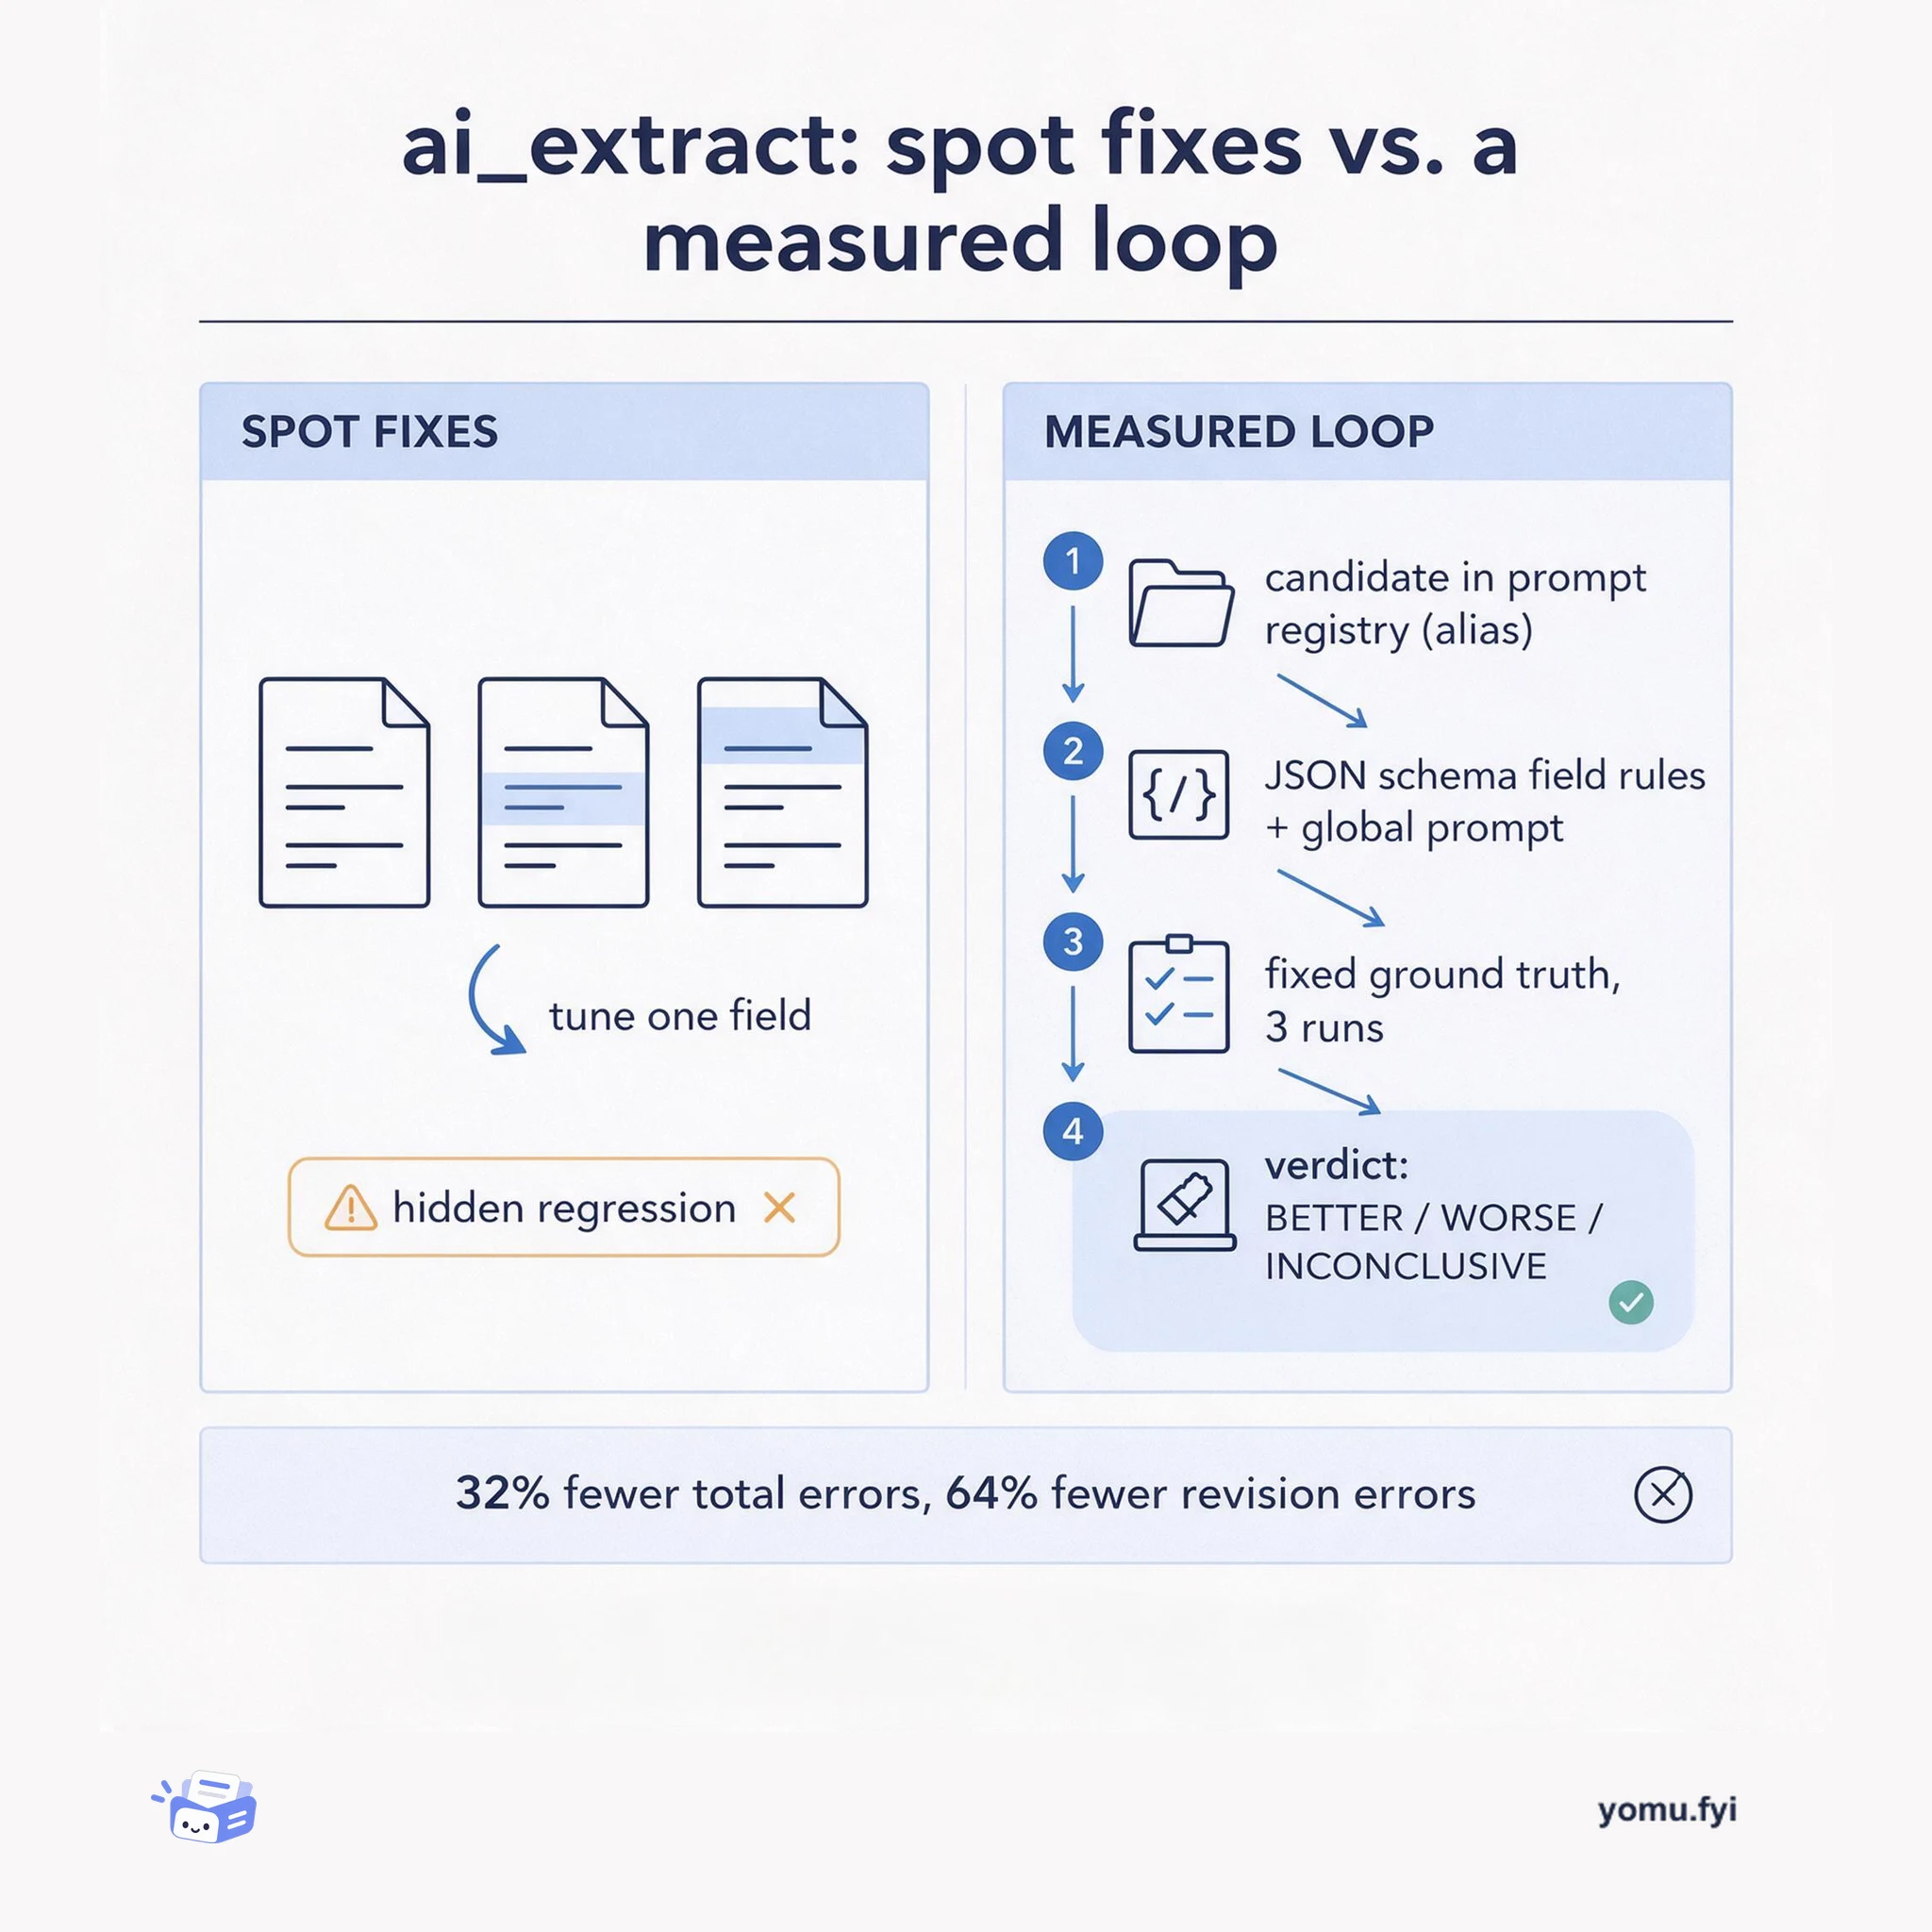
ai_extract: Spot Fixes vs. a Measured Eval Loop
A side-by-side comparison of two ways to improve ai_extract document extraction: patching one field at a time, or versioning prompts and judging them against fixed ground truth.
 ClickhouseBenchmark
Jev is a System One model that returns typed answers with calibrated probabilities in 70–500 ms without generating text, used for table ranking and failure labeling. On the Agentic Analytics Benchmark, Jev labeled 277 failures across 4 models in under a second, revealing wrong data selection as the largest bucket, mostly entity resolution errors like wrong identifiers or unresolved named entities. Jev also ranked 18 warehouse tables per question at nDCG@10 0.951 in 0.4 seconds with no fine-tuning or gold data. The labeler flagged 18 likely grader errors under a 0.65 threshold, traced to a comparator that returns not equal on row-count differences before linking columns, now tracked as a bug. However, feeding these rankings as schema hints left accuracy flat across 20 models, and development-set savings did not transfer to the held-out board.
This post is the second half of round two of the Agentic Analytics Benchmark series, testing whether a cheap retrieval component built on Jev can improve agent accuracy by providing table rankings and failure labels.
Jev is used as a classifier to rank warehouse tables per question and label agent failure modes, all in under a second without fine-tuning or gold data.
Jev ranks warehouse tables per question at nDCG@10 0.951 in 0.4 seconds without fine-tuning or gold data, but feeding this ranking as hints to agents does not improve accuracy across 20 models.
Jev labels agent failures in under a second with a finer taxonomy that reveals wrong data selection, mostly entity resolution errors (wrong identifiers or never resolving named entities), as the largest failure bucket.
The labeler’s correct-despite-fail flag identified 18 answers likely mis-scored due to a deterministic comparator that compares row counts before linking columns, a bug now tracked.
Jev ranks warehouse tables per question at nDCG@10 0.951 in 0.4 seconds, requiring no fine-tuning or gold data.
The authors found that the ranking itself is the result, not a useful hint; feeding it as a schema hint left accuracy flat across 20 models and development savings did not survive the board.
Wrong data selection, specifically entity resolution errors like wrong identifiers or never resolving named entities, rather than wrong table selection.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A side-by-side comparison of two ways to improve ai_extract document extraction: patching one field at a time, or versioning prompts and judging them against fixed ground truth.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
