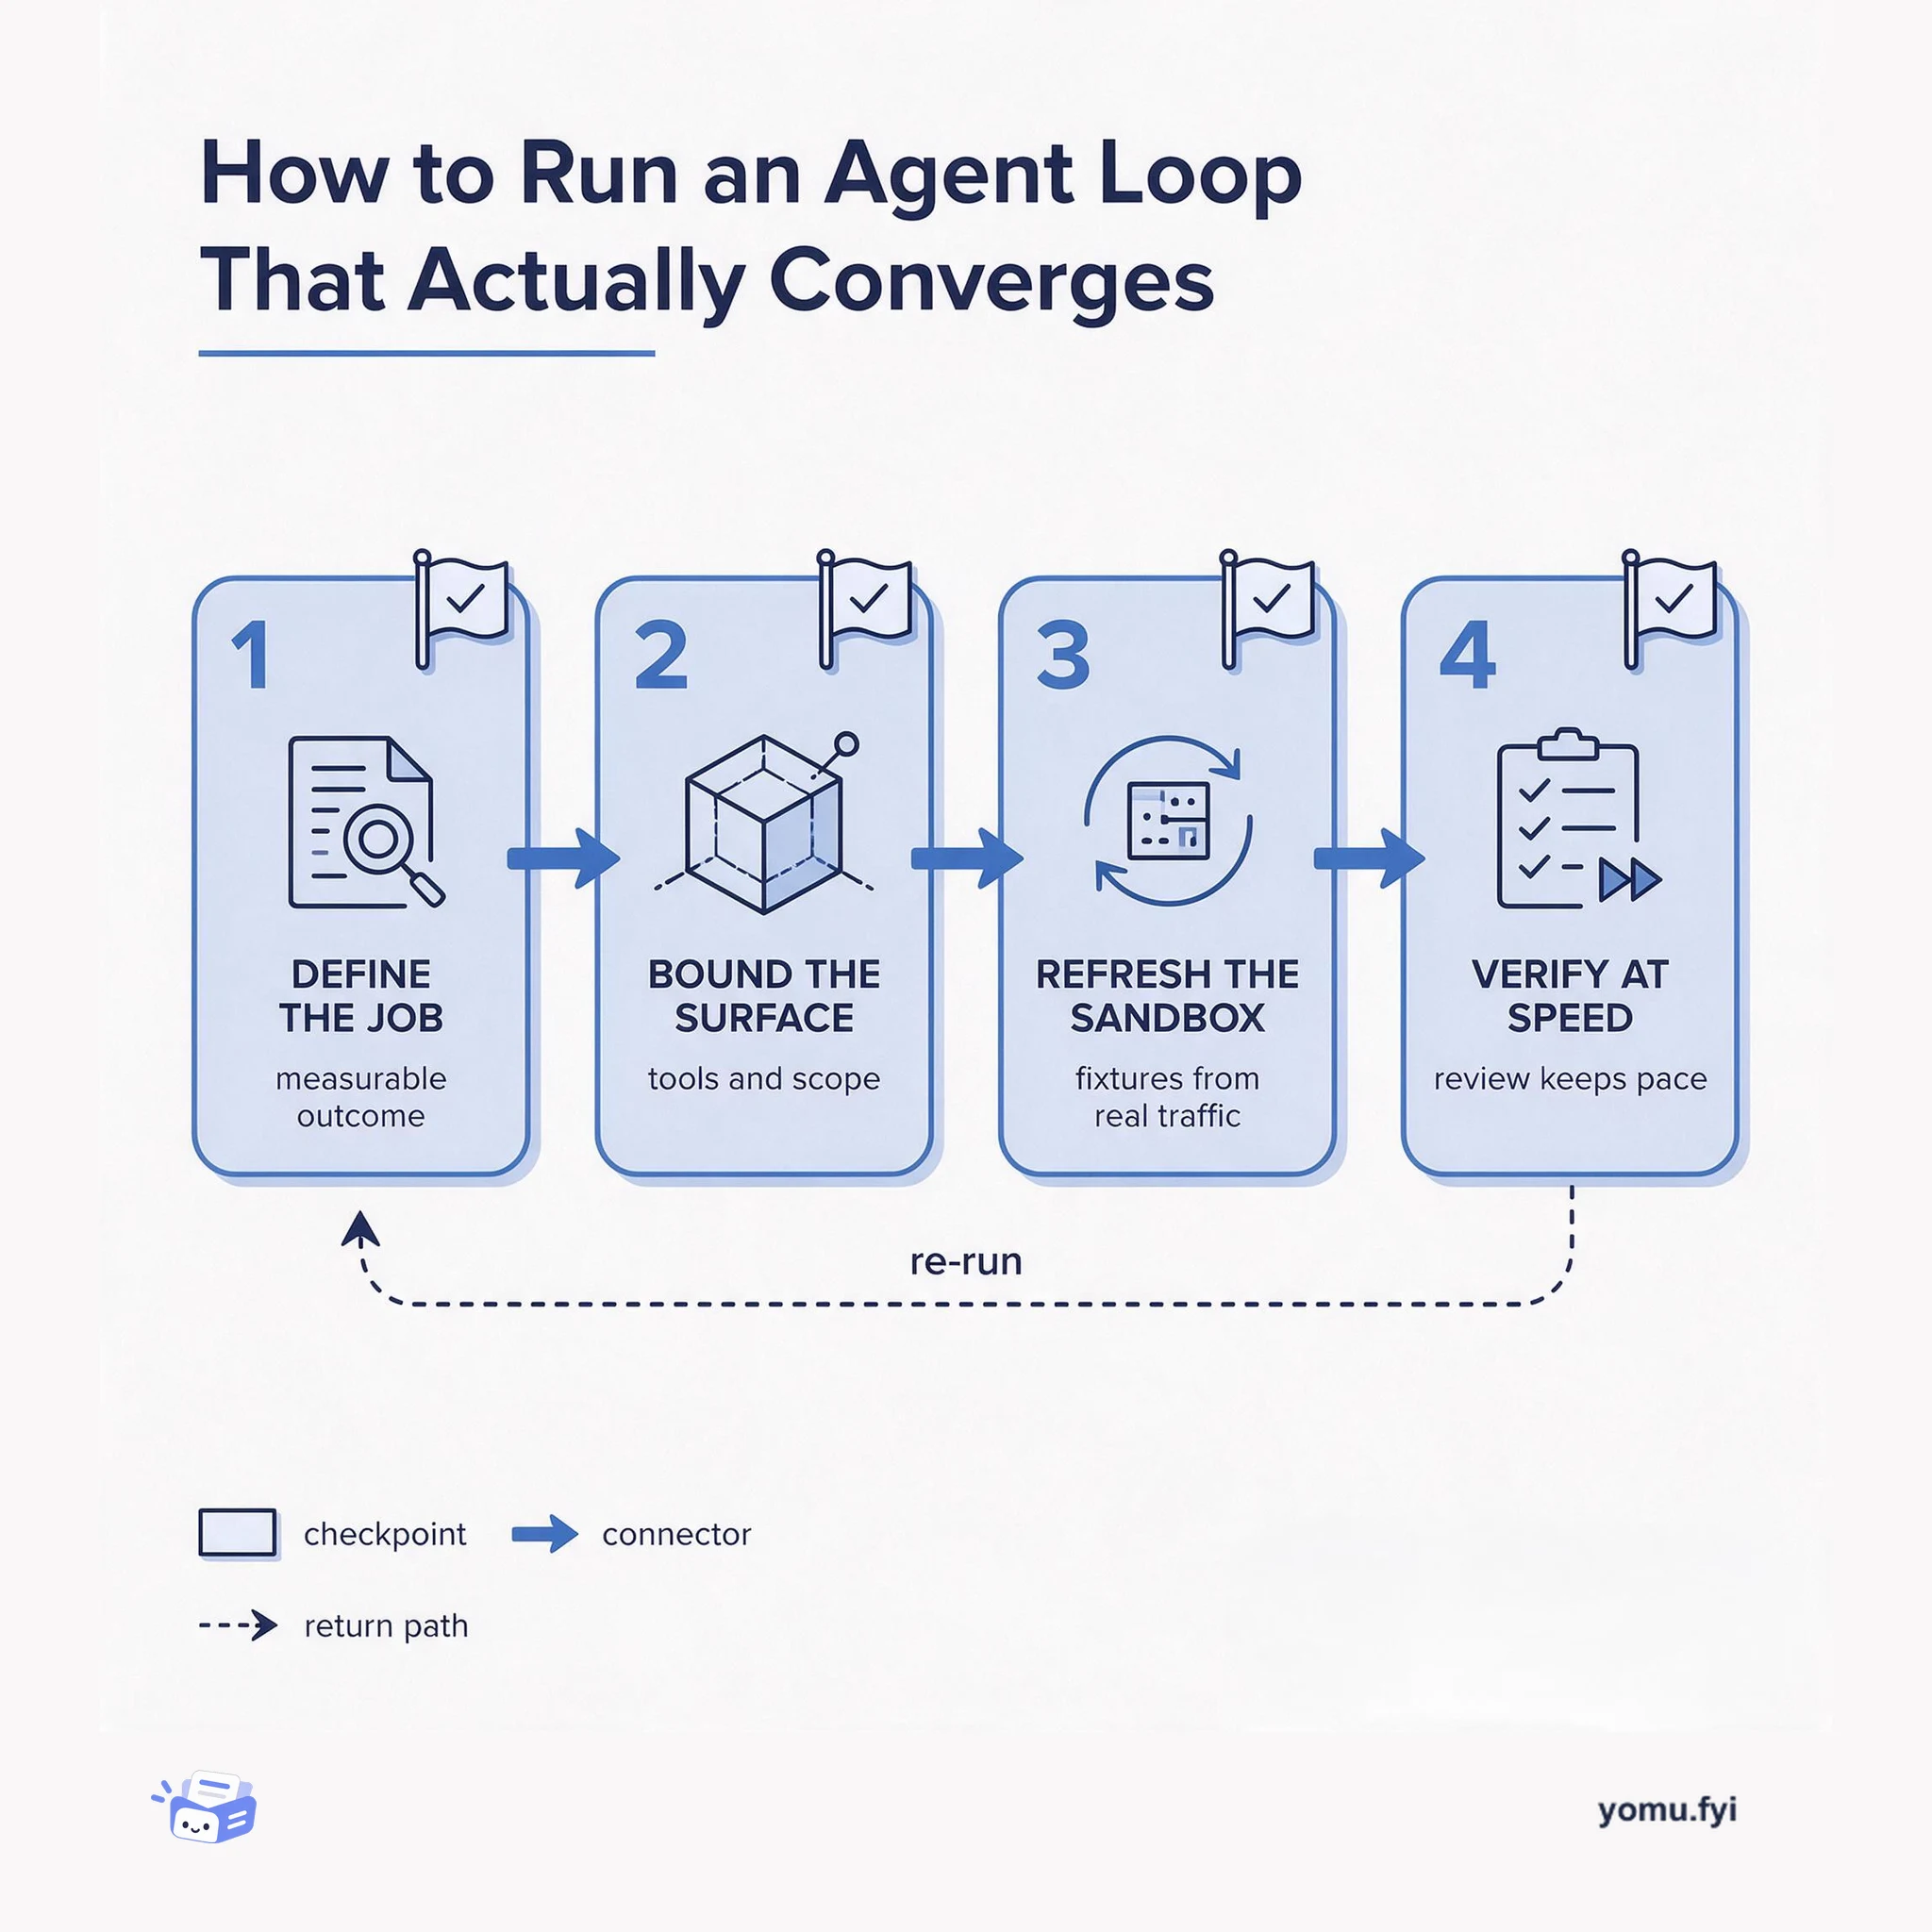
How to Run an Agent Loop That Actually Converges
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
Loading…
Topic
5 posts about Agents. Every summary links to the original.
See the idea
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
Tool-augmented LLM agents must discover relevant APIs from large registries before planning, but finite context windows prevent injecting all tool definitions into a single prompt. Two competing architectures are Retrieve-then-Plan (RtP), which embeds the query and retrieves similar tools via nearest-neighbor search, and Plan-then-Retrieve (PtR), which first generates abstract tool stubs as retrieval queries. Evaluating on ToolBench with 46,984 API endpoints across 50 categories reveals a clear complexity-dependent crossover: RtP outperforms PtR on single-tool queries while PtR outperforms RtP on multi-tool queries. PtR’s stub-hallucination failure mode acts as a double-edged sword—on simple queries it abstracts away proper-noun signals, yet on complex queries it decomposes multi-faceted intent into functional sub-needs. PtR roughly doubles inference cost, which pays off on multi-tool queries but hurts on single-tool ones, motivating complexity-adaptive routing driven by RtP’s top-1 retrieval score.
Databricks announces General Availability of Document Intelligence REST APIs for real-time document parsing, extraction, and classification, with the ai_decide API for routing in beta. These synchronous APIs eliminate the manual bottleneck of reading documents by transforming unstructured contracts, invoices, and insurance claims into structured insights in real time. The ai_parse_document API converts tables and figures into structured text with citation bounding boxes, while ai_extract pulls specified fields with optional citations and confidence scores for verification. The ai_classify API assigns labels using a business taxonomy with optional rationales, and ai_decide uses content to route or flag documents for review. Developers can integrate these APIs into Databricks Apps for human-in-the-loop workflows, such as a contract intake flow where a lawyer uploads an agreement and sees key terms prefilled, or into custom agents on Agent Bricks.
Apple Mail and Gmail now generate AI summaries of emails, while agents read messages to automate tasks like logging receipts or tracking deadlines. Summarizers focus on the first 100 to 150 characters, so the main point and call to action must lead the email. Semantic HTML with h1 headings, a descriptive title, lang attributes, and role=‘presentation’ on tables creates a machine-readable outline, yet the Email Markup Consortium found 74% of emails lack an h1 and 96% lack lang. Hidden text styled to be invisible can hijack summaries, as Forcepoint demonstrated, and similar attacks have targeted Gemini in Google Workspace; such practices also trigger security flags. Testing in Gmail, Apple Mail, and Outlook, along with verifying the plain text version, confirms that both humans and agents interpret the email correctly.
LFM2.5-24B-A2B is a 24-billion-parameter reasoning model with only 2 billion active parameters per token, designed for fast, private on-device agents. It uses a Mixture-of-Experts architecture with 40 layers, 64 experts per block, and top-4 routing, combined with gated short convolutions and GQA. The model produces an explicit chain of thought before answering and supports tool calling and multi-step tasks. Pre-training scaled to 33 trillion tokens, followed by mid-training and a five-stage post-training pipeline including supervised fine-tuning, multi-domain distillation, and agentic reinforcement learning. On benchmarks, it leads or matches larger models on tool use and instruction following, achieving 48.09 on LiveClaw and 96.75 on IFEval, while decoding 184 tokens per second on an Apple M5 Max.
At Anthropic, Claude’s ability to iterate on code at high speed has caused git-based source control to become the bottleneck in their development workflow. To handle the growth from 2,500 to over 30,000 daily code merges, the team built Scion, an in-house version control system, fully migrating their monorepo from git in five months. Scion diverges from git by assuming clients are always online, shifting computation to the server, and using horizontally scalable data structures without any fully materialized copy of the repository. The system stores changes as entries in a write-ahead log, supports sparse and virtualized checkouts, and enables cheap, lock-free commits that scale with change size rather than repository size. Anthropic shares Scion’s design principles to help the broader ecosystem prepare for AI-driven scaling challenges, noting that similar pressure points will emerge for other organizations as AI coding tools become more common.
The best engineering reads, once a week.





