One Pool, Many Engines: The Architecture of Apple Silicon
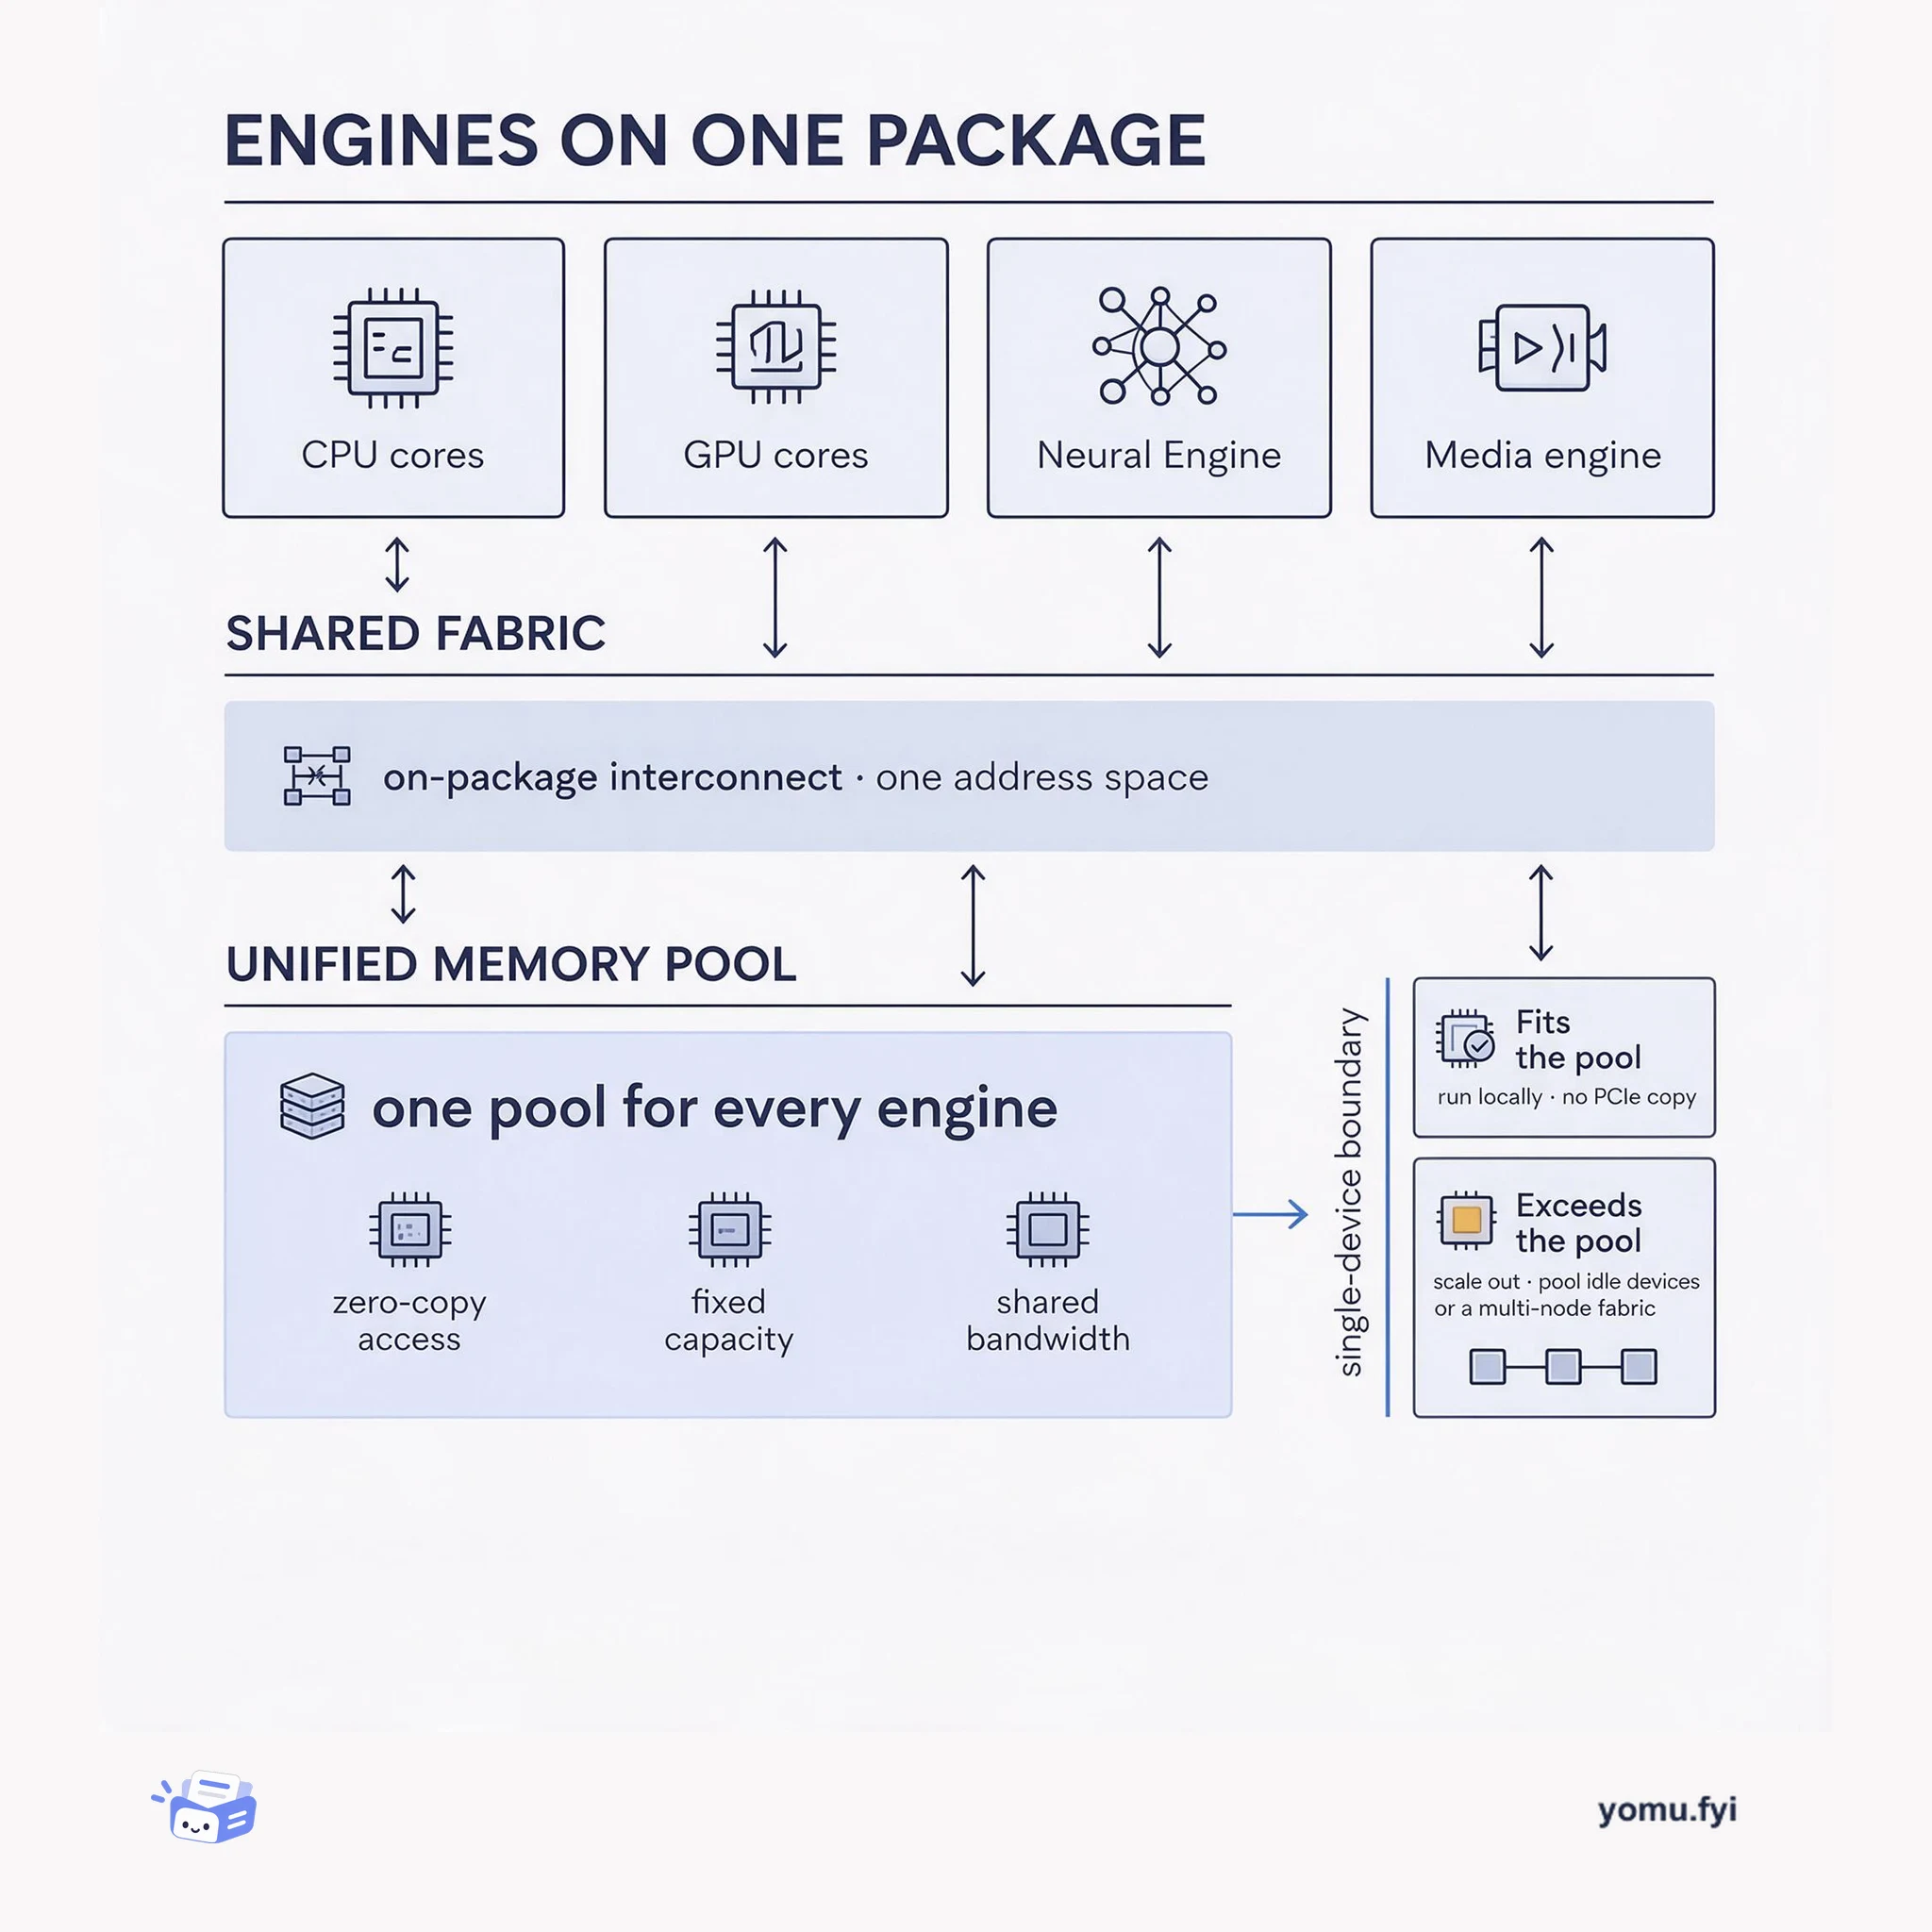
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
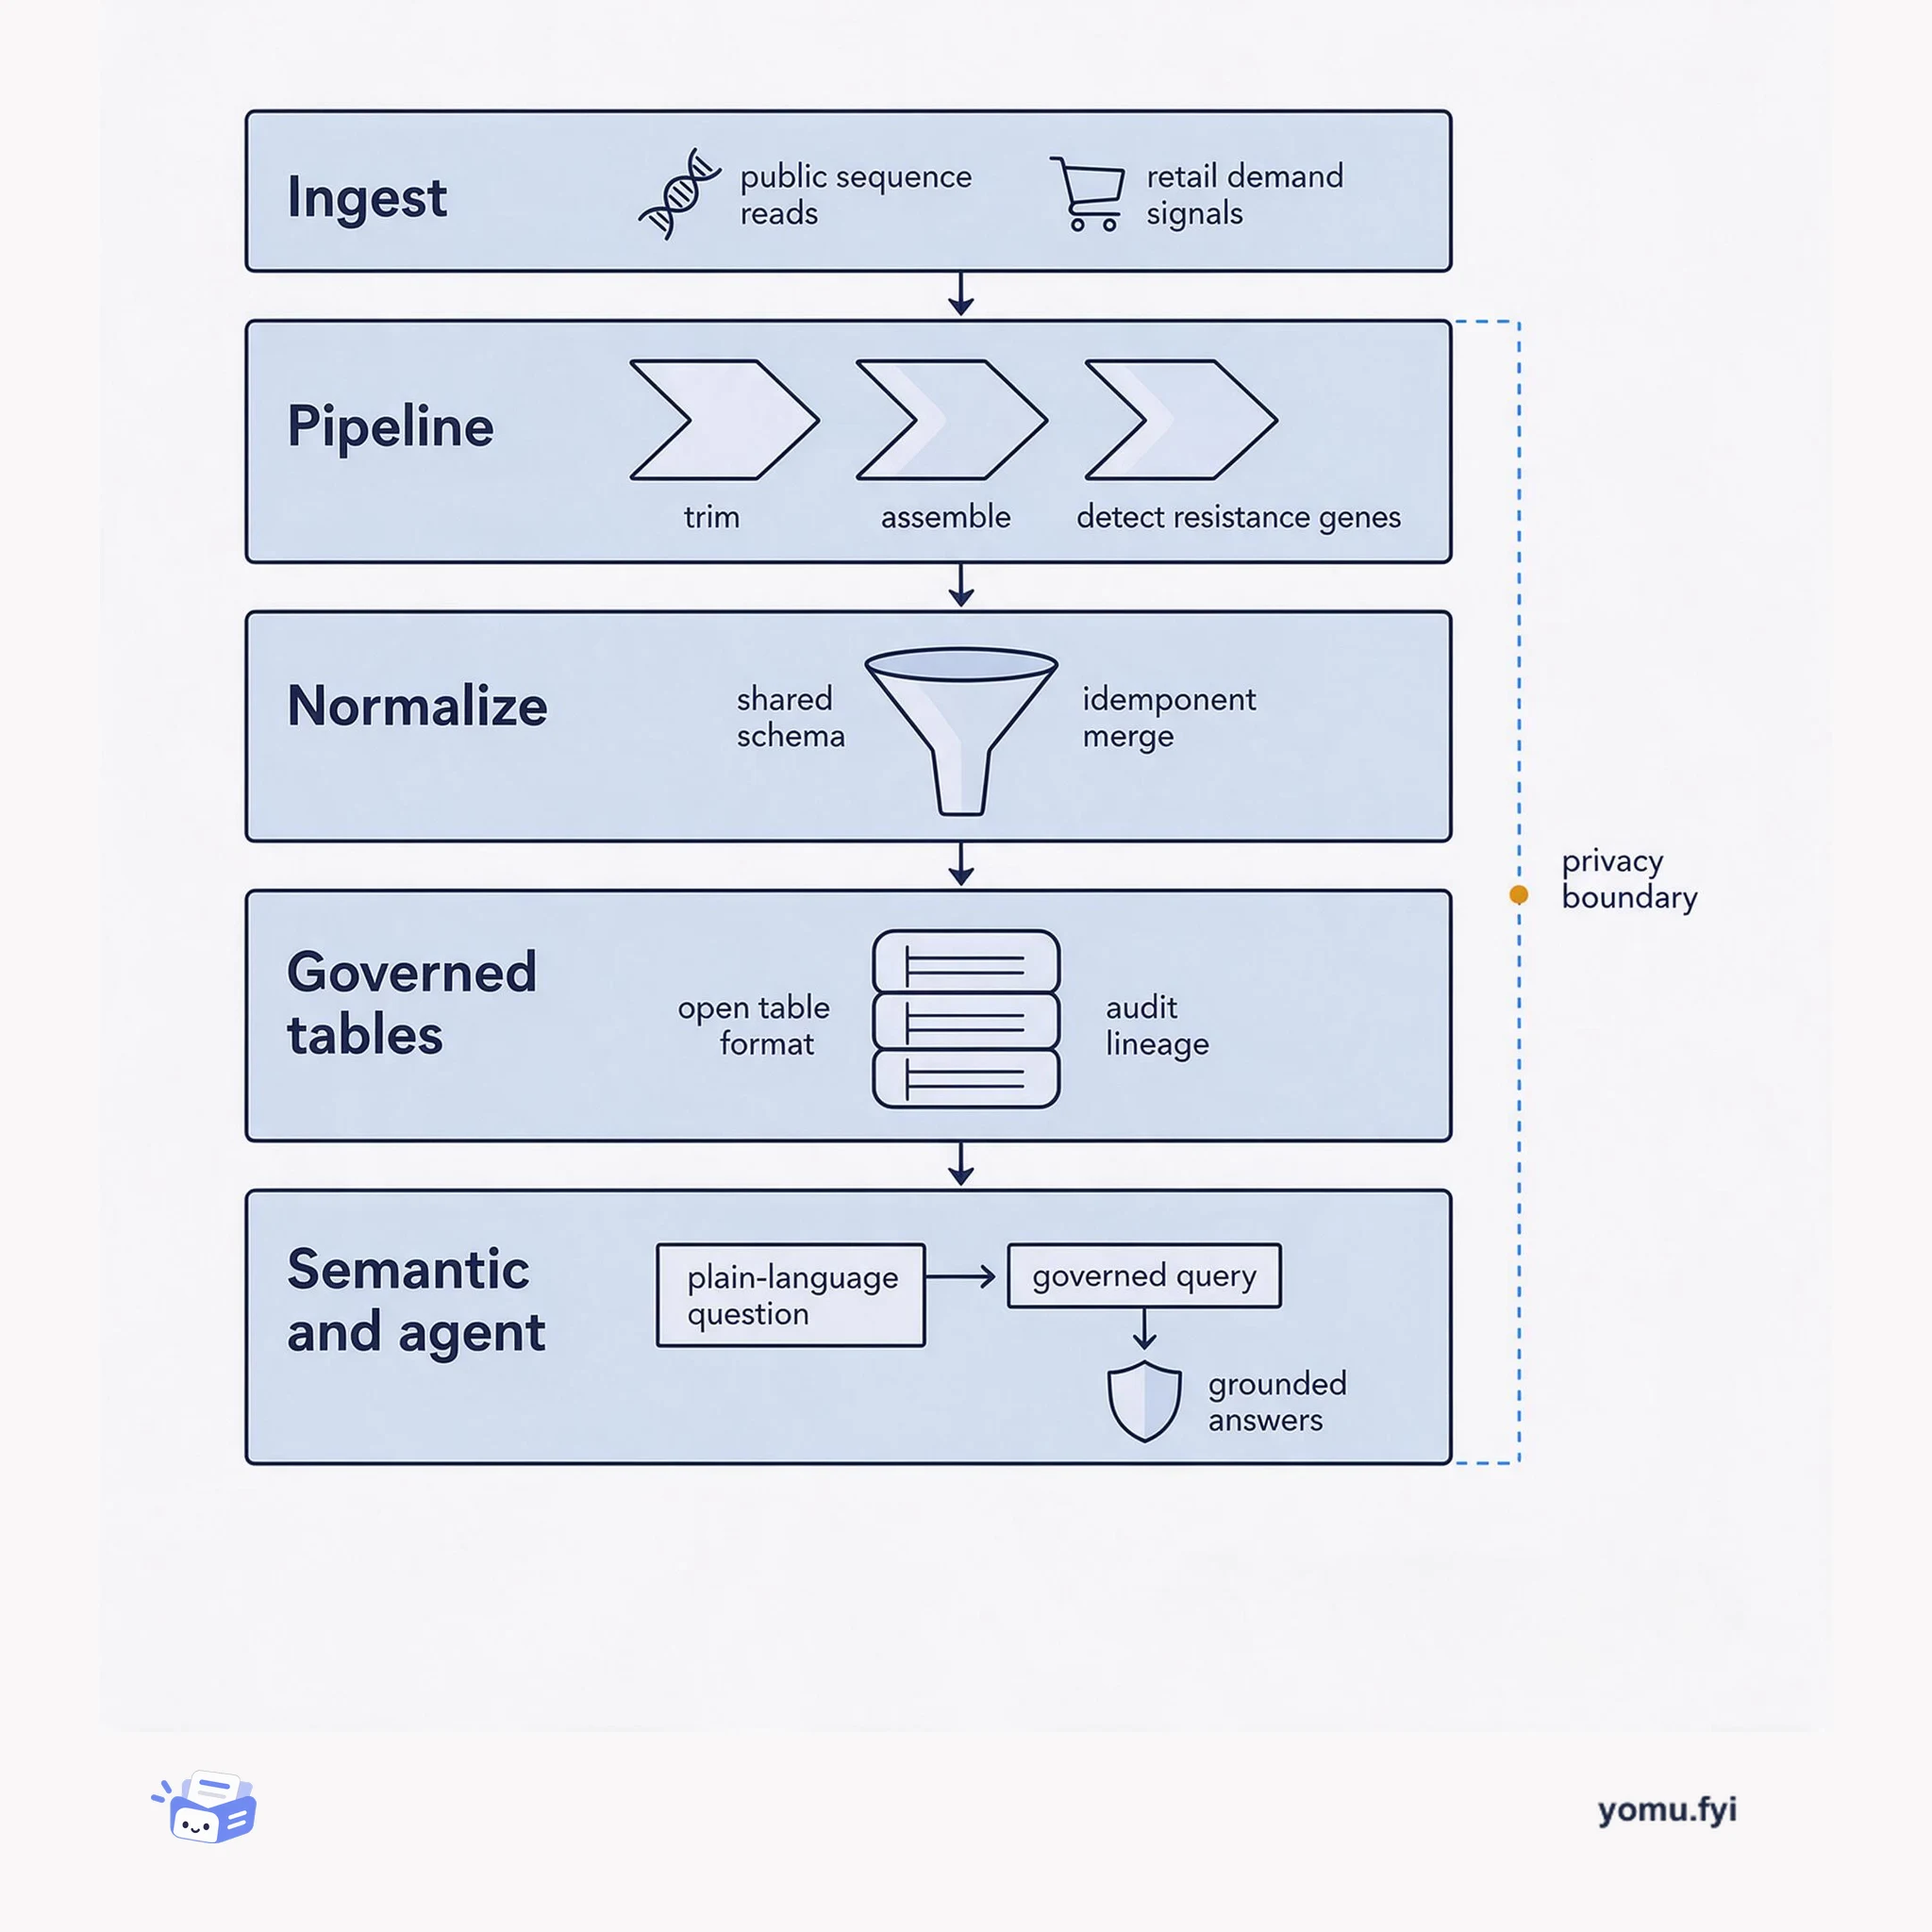
Amazon Bedrock is the managed reasoning tier in an agent architecture, not the whole system. This layered view shows the pipelines, governed tables, query layer, and guardrails around it.
Amazon Bedrock is best understood as a layer rather than a model: the managed tier where an agent reasons, plans, and calls tools, sitting between your governed data and your application's interface. Below it, domain pipelines normalize and idempotently merge results into open table formats so answers trace back to a single source of truth. At the agent tier, the model generates queries instead of scanning raw records, and guardrails keep responses grounded in retrieved evidence. Above it, model choice becomes configuration you can evaluate and swap, while the architecture stays stable.
In the AMR surveillance example, reads are processed by a HealthOmics pipeline, normalized into the hAMRonization schema, and merged idempotently into Iceberg tables on S3 Tables. The Strands agent on Bedrock AgentCore then answers plain-language questions by generating Athena queries, with Guardrails keeping responses grounded.
Mirror a percentage of production traffic to a candidate endpoint, then run your existing quality and performance evaluations against it without touching production; when it wins, promote it. TinyFish shows the complementary rule: score the whole agent on task completion, not individual model responses.
Guardrails constrain what the agent says, but grounding comes from the layer beneath. The AMR example merges results idempotently so reprocessing an isolate updates rows rather than duplicating them, and where definitions change quickly a governed context layer keeps every agent working from the same understanding.
The posts behind it
 Databricks · · Problem & solution
The post argues that model intelligence is no longer the bottleneck for enterprise AI; the real gap is business context — the unique knowledge about an organization’s processes, customers, and products. Without proper grounding, agents resort to brute force, iterating through guesses and burning tokens while producing unreliable answers. While building a well-grounded agent for a single domain is now easier, scaling context across hundreds of agents in an enterprise remains unsolved due to fragmentation, fast-changing definitions, and differing team-specific interpretations of the same concepts. Genie Ontology addresses this by providing a unified, governed context layer that combines intentionally curated knowledge with automatically learned observations from system usage. This enables every agent connected to Databricks to work from the same consistent business understanding, supporting accurate answers without each agent rediscovering the business from scratch.
Databricks · · Problem & solutionData warehouses have been the standard for structured SQL analytics for two decades but cannot serve modern AI, ML, streaming, and unstructured data workloads. The data lakehouse now matches warehouse SQL performance while serving all these workloads from a single governed foundation. Databricks Lakehouse improved production SQL workload performance by 77% from a 2022 baseline, with BI queries improving 14% over a recent five-month period. Customer migrations show 90% faster queries and 30–40% cost reduction at Lumen Technologies, and 80–90% faster analytics at Trek Bicycle. The lakehouse eliminates redundant data copies, supports open formats like Delta Lake and Iceberg, and extends governance to AI agents through Unity Catalog and Unity Gateway.
Databricks · · Problem & solutionTinyFish builds infrastructure for enterprises that need agents to work across the live web and is developing its own specialized web-native model. The company uses Databricks AI Runtime to manage GPU compute for post-training with supervised fine-tuning and moving toward Direct Preference Optimization, MLflow for evaluation, and Model Serving for production deployment. TinyFish evaluates its model by measuring full agent task completion rather than individual responses, achieving a 77.6% success rate on its internal go/no-go benchmark where 1,691 of 2,178 tasks were completed successfully. Over a 15-day period, the web-native model handled 294,781 agent runs across 6.4 million tool steps at an estimated serving cost of $0.088 per run or $0.0040 per tool step. By consolidating training, evaluation, serving, and operational data on Databricks, TinyFish reduces infrastructure overhead and maintains a continuous development cycle from agent behavior to deployment.
 AWS · · Problem & solution
Antimicrobial resistance, estimated to cause 1.27 million direct deaths in 2019, requires surveillance that normally demands bioinformatics skills to turn raw reads into answers. It ingests public SRA data via a Step Functions workflow and Fargate task, then runs a HealthOmics Nextflow pipeline that trims reads, assembles them, and detects resistance genes with AMRFinderPlus using a baked-in database. Results are normalized into the hAMRonization schema and merged idempotently into Iceberg tables on S3 Tables, so reprocessing an isolate updates rows rather than duplicating them. A Strands agent on Amazon Bedrock AgentCore answers plain-language questions by generating Athena queries, with Guardrails keeping responses grounded. The solution is defined entirely in AWS CDK, deploys with a single command, and avoids manual bioinformatics steps, remaining inexpensive when idle.
 Apple · · Problem & solution
Long agent traces of chains of thought and tool calls accumulate stale content that anchors later generations and outgrow context window. SELFCOMPACT lets the model itself decide when and how to compact rather than using fixed-interval compaction triggered at a token threshold. It pairs a compaction tool that summarizes accumulated context with a lightweight rubric for when to fire, such as resolved sub-task or converging trajectory, and when to suppress, such as mid-derivation or stuck. Both are needed: the tool alone is unevenly used across open-weight models, while a rubric closes a meta-cognitive gap without training. On six math and agentic-search benchmarks across seven models, SELFCOMPACT matches or exceeds fixed-interval summarization at a fraction of the token cost, improving over no summarization by up to 18.1 points on math and 5–9 points on agentic search at 30–70% lower per-question cost.
 Modal · · Announcement
Modal introduced Endpoint Candidates to stage alternative inference deployments for Dedicated Endpoints, allowing evaluation of quality, latency, throughput, and cost without affecting production traffic. Users create a Candidate by selecting a model from Modal’s catalog or importing custom weights, then set a percentage of production traffic to mirror. The Pingora-based proxy forks each request stream into separate bounded buffers per Candidate and shares body chunks across mirrors with a per-process memory budget; if a buffer fills or the budget is exceeded, the proxy cancels that mirrored request while production continues. Each Candidate receives its own URL for running existing evaluations on output quality and performance benchmarks under load, and all mirrored compute uses standard Modal compute pricing. When ready, users promote from the dashboard to roll out to the production endpoint, leaving other Candidates available for continued independent testing and enabling Auto Endpoints to validate automated inference optimizations.
More like this
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
Antimicrobial resistance surveillance is a layered data architecture: raw reads and demand signals flow in, get normalized into governed tables, and answer plain-language queries. The diagram maps each boundary.
API versioning as an architecture: requests enter through a version header, pass through a chain of reversible version changes, and reach controllers that only ever see the latest model.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.