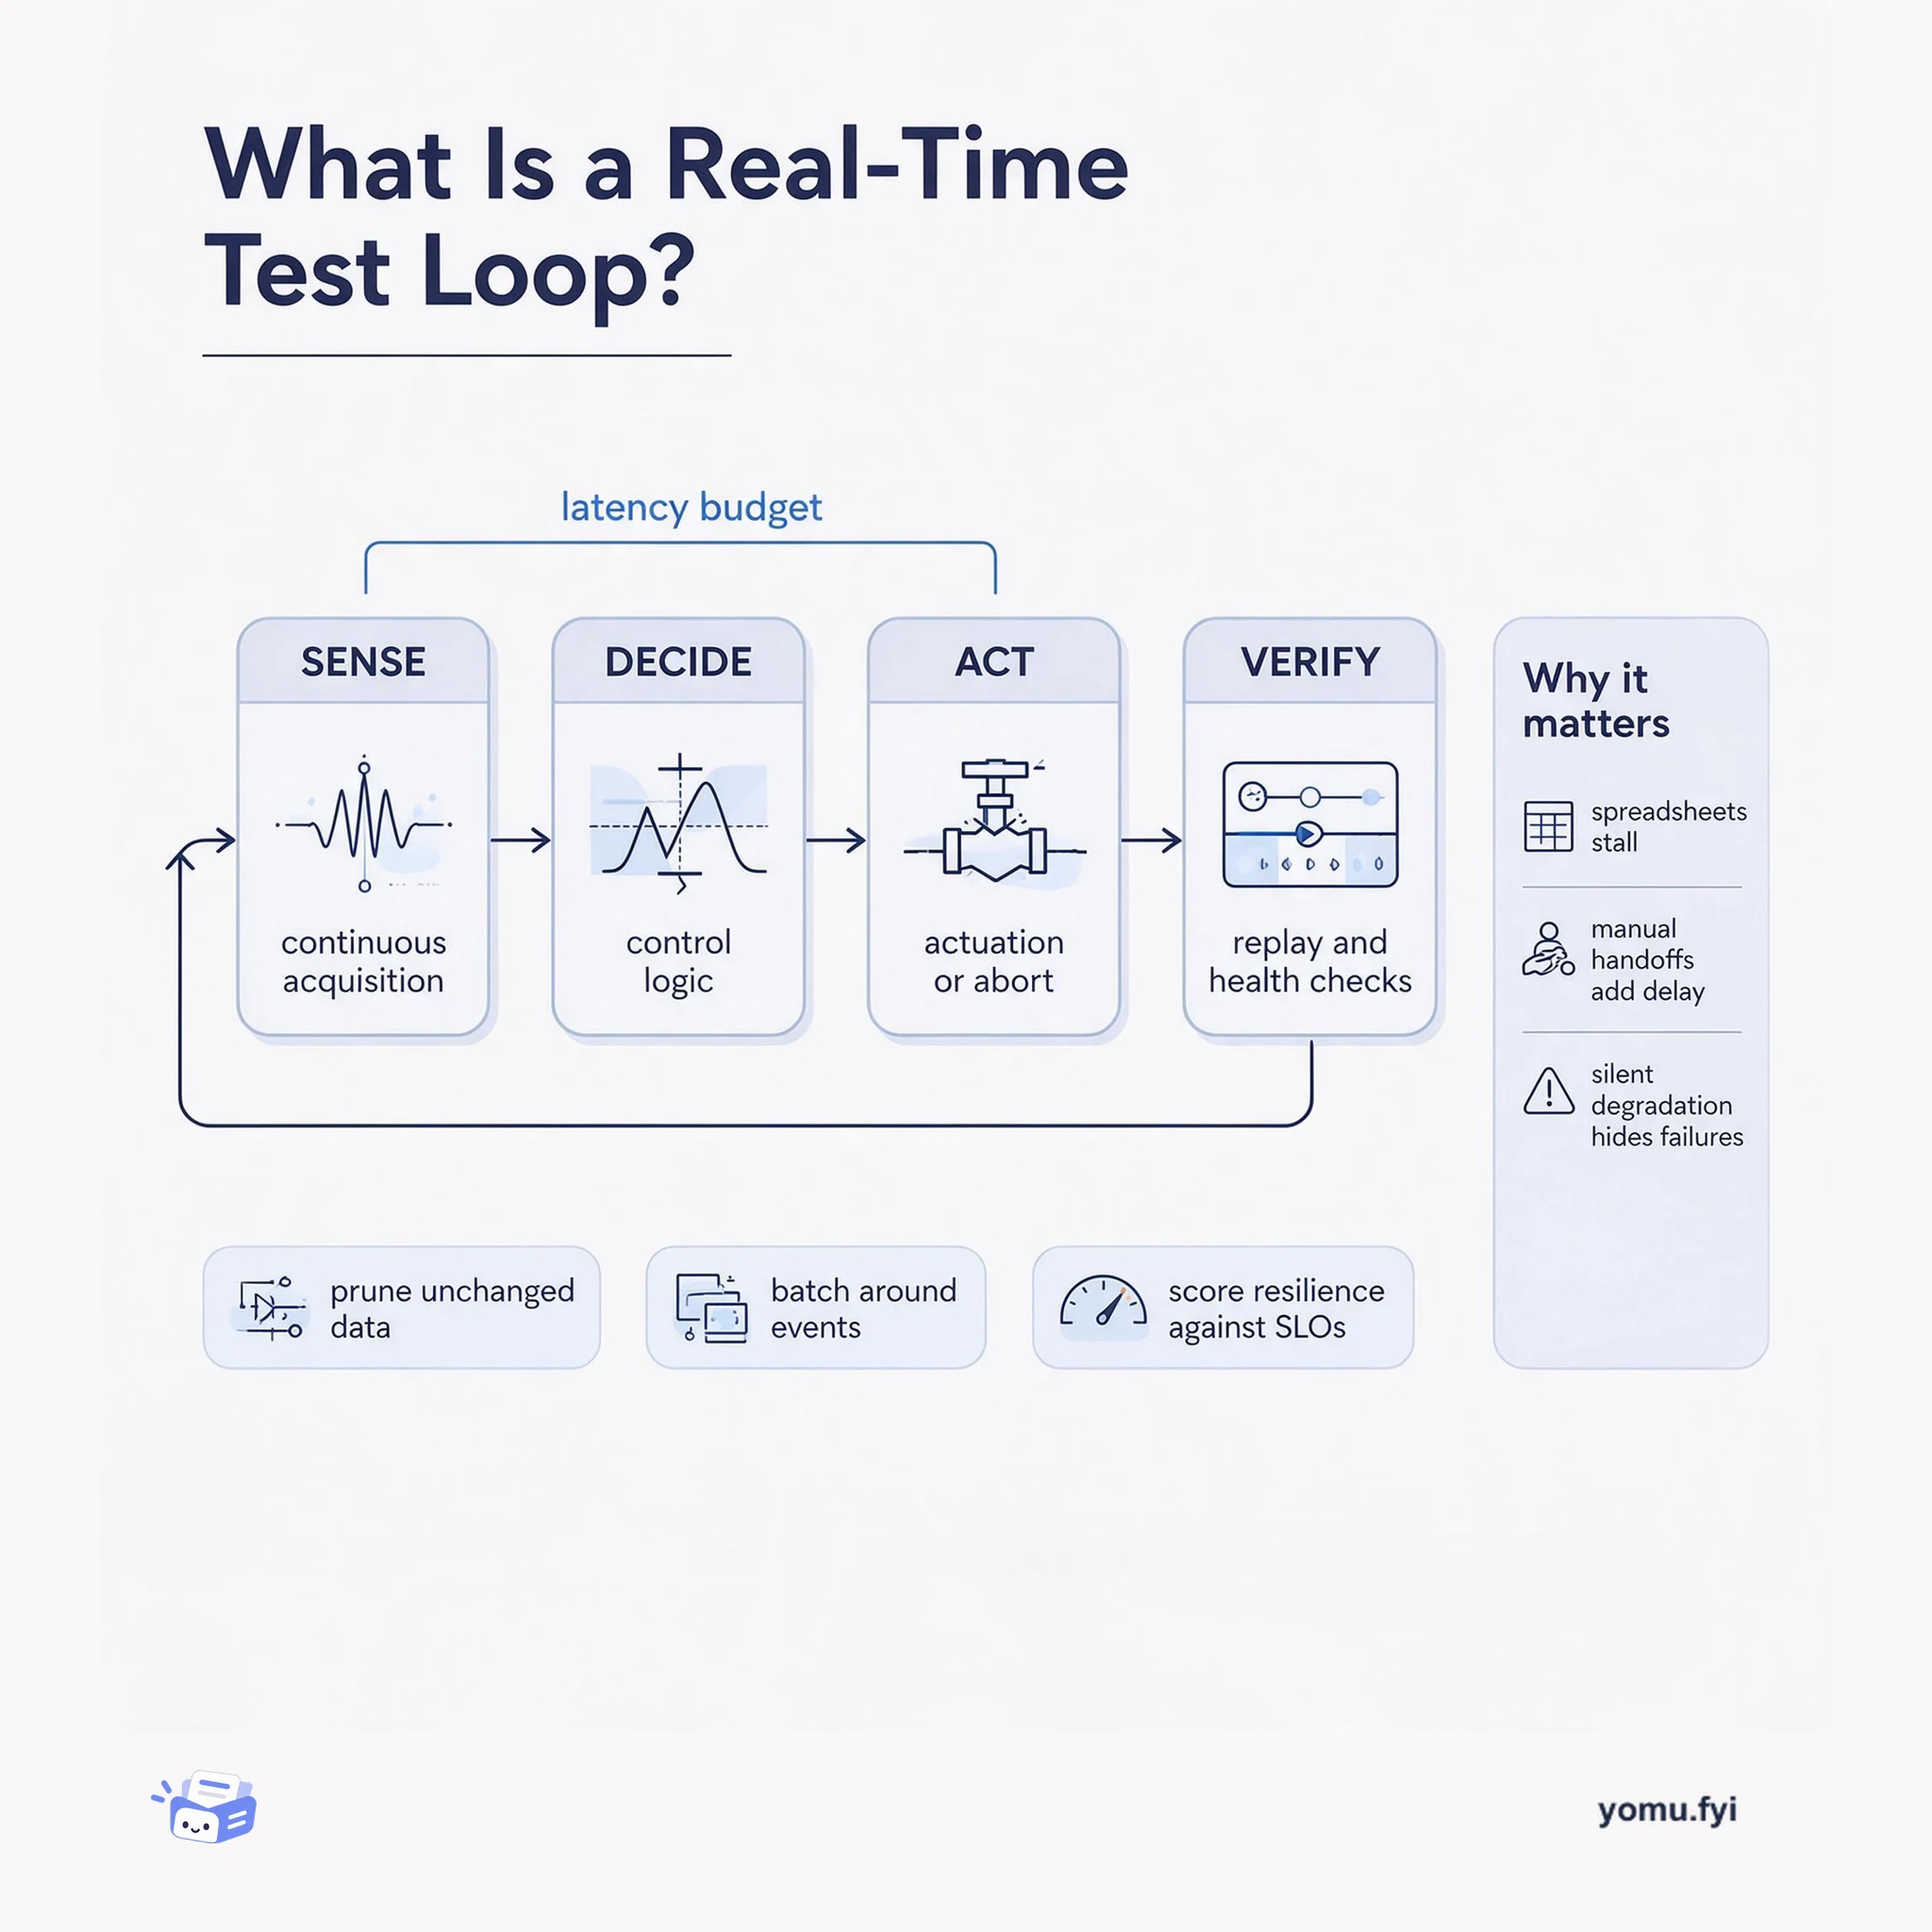
What Is a Real-Time Test Loop?
A real-time test loop is the closed path from sensor acquisition to control action and back to verification. This explainer maps its four parts and the latency budget that binds them.
 Red HatPaige PattonProblem & solution
Binary pass/fail uptime testing no longer suffices for cloud-native deployments because a cluster can remain operational while dropping packets, breaching SLOs, or suffering performance degradation. Krkn addresses this with a trifecta of telemetry: a weighted Resiliency Score, continuous HTTP Health Checks, and KubeVirt Checks. The Resiliency Score is a 0–100% macro-health metric that evaluates live Prometheus data against pre-defined SLOs using custom weights, allowing engineers to prioritize business-critical components like authentication or payment gateways. HTTP Health Checks probe application endpoints at configurable intervals, capturing exact downtime start and end times alongside HTTP status codes, enabling teams to track self-healing duration. KubeVirt Checks monitor virtual machine instances via real-time SSH connectivity and record node, IP address changes, and exact down-time, with a final post-chaos check that flags VMs remaining unreachable after the experiment concludes.
Chaos engineering in cloud-native environments has evolved beyond binary pass/fail uptime metrics because clusters can remain operational while silently degrading performance or breaching SLOs, requiring multidimensional telemetry to assess true resilience.
Krkn implements three telemetry layers: a weighted Resiliency Score that evaluates live Prometheus data against SLOs with custom weights, continuous HTTP Health Checks that probe endpoints at configurable intervals capturing exact downtime start/end times and HTTP status codes, and KubeVirt Checks that monitor virtual machine instances via SSH connectivity recording node, IP changes, and downtime duration with a final post-chaos check.
The Resiliency Score uses a weighted scoring model where standard warning alerts are worth 1 point and critical outages are worth 3 points by default, but engineers can assign custom weights to individual SLOs to prioritize business-critical components.
HTTP Health Checks capture exact downtime start time, end time, and duration during chaos experiments, and support bearer tokens and credential tuples for monitoring protected API endpoints.
Running identical Krkn chaos scenarios against successive application versions in CI/CD provides quantifiable evidence of architectural regressions by comparing Resiliency Scores, HTTP endpoint failure durations, and VM outage durations.
The score ranges from 0–100% and calculates by tracking Prometheus alert queries against pre-defined SLOs during the chaos time window, using a weighted scoring model where engineers assign custom weights to different alert severities—by default, standard warnings are worth 1 point and critical outages are worth 3 points.
They continuously probe application endpoints at user-defined intervals and capture the exact start time, end time, duration of downtime, and HTTP status codes, with support for bearer tokens and credential tuples for authentication on protected endpoints.
They attempt real-time SSH connectivity using virtctl or direct worker nodes, logging whether a VM lost connectivity, the node it ran on, IP address changes if rescheduled, and exact downtime duration, with a final post-chaos check that flags any VMs remaining unreachable after the experiment ends.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A real-time test loop is the closed path from sensor acquisition to control action and back to verification. This explainer maps its four parts and the latency budget that binds them.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
