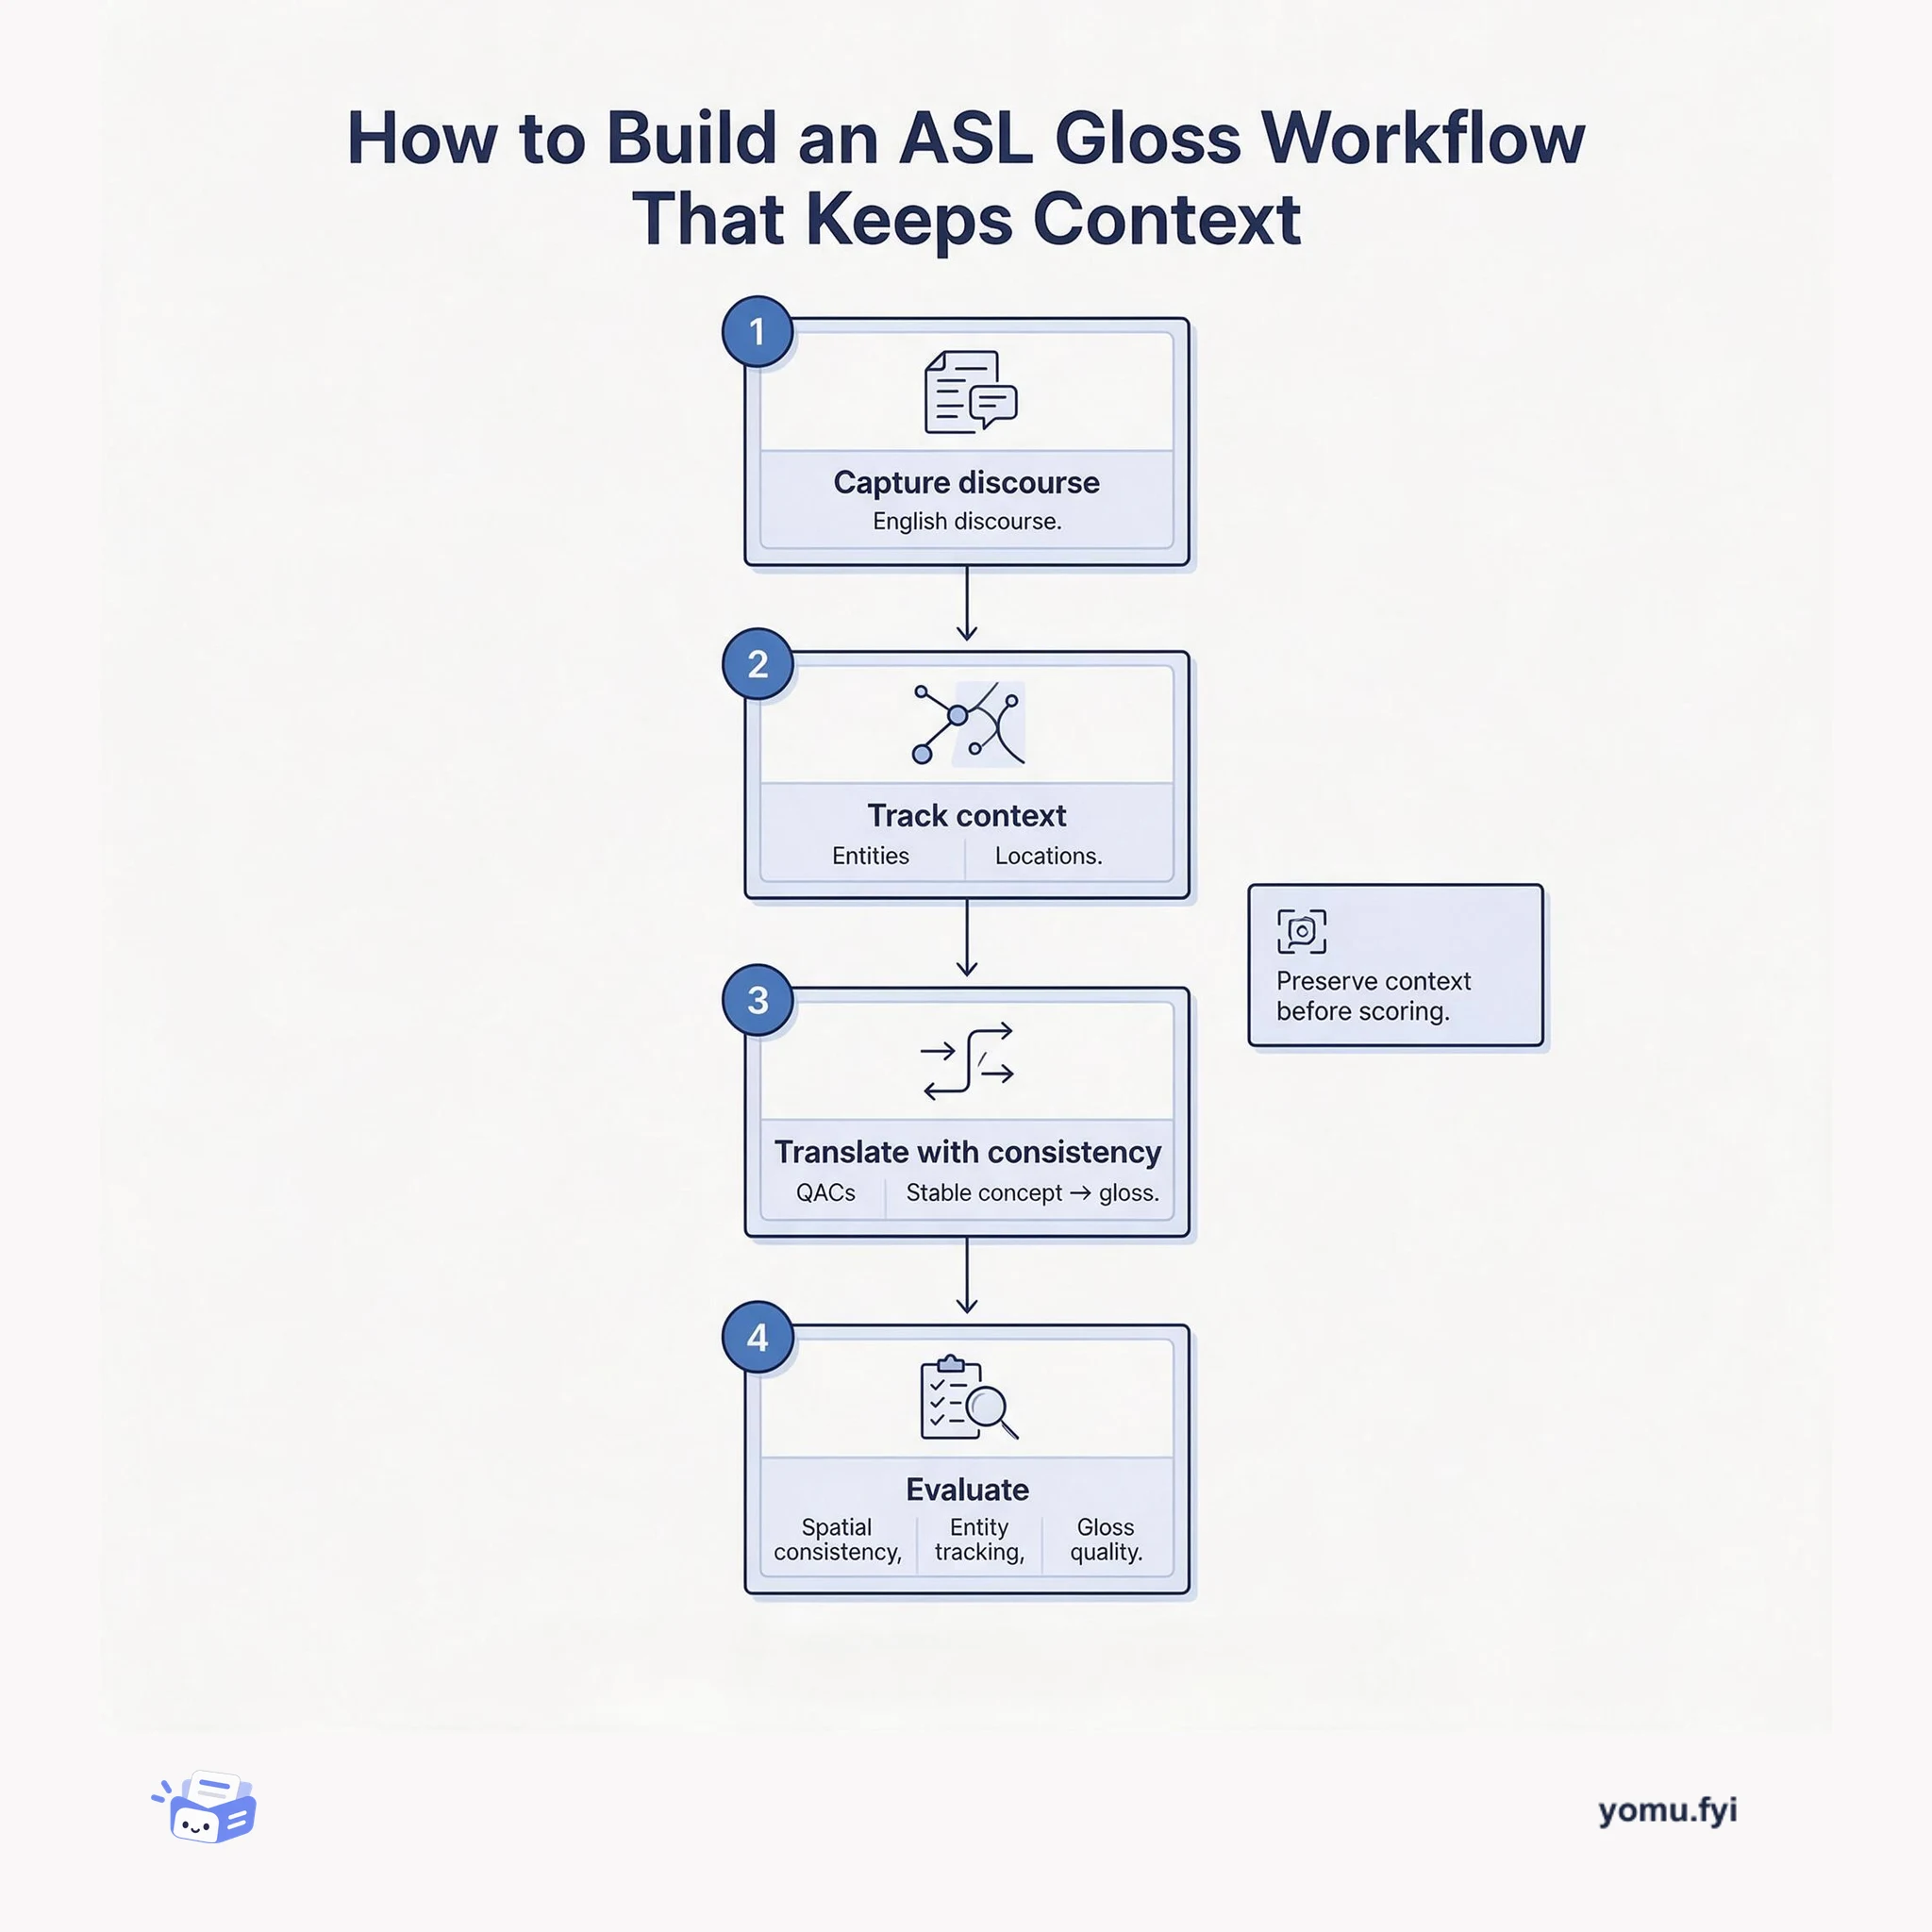
How to Build an ASL Gloss Workflow That Keeps Context
Learn a practical workflow for translating English discourse into ASL gloss while preserving spatial references, question-answer structure, and consistent concept-to-gloss mappings.
 PinterestPinterest EngineeringExplainer
Pinterest describes building a VLM serving stack on NVIDIA Blackwell B200 GPUs and NVIDIA Dynamo for multimodal products including Pinterest Assistant, hybrid search, multimodal reranking, content understanding, signal generation, and content safety. Unlike text-only workloads, requests may contain thousands of images, costly and variable prefill, long multi-turn histories, and large KV caches, making preprocessing, routing, memory, and latency central serving concerns. The implementation combines Dynamo's distributed orchestration, multimodal frontend and vLLM support, KV-aware routing, disaggregated encoder/prefill/decode serving, and LMCache-based KV offloading with vLLM, an OpenAI Chat Completions interface, model-aware routing, EKS, and custom deployment components. Production-oriented AIPerf DAG benchmarks model QPS patterns, multi-turn conversations, many-image requests, and agentic DAGs; the team concludes that payload design, cache-aware routing, offload tiers, and a shared platform are essential to meeting product targets and accelerating new launches.
Pinterest's visual search and discovery products require AI systems that reason over language and visual content. VLM serving introduces image loading and preprocessing, expensive and irregular prefill, larger KV caches, multi-turn visual context, and model-specific payload requirements compared with text-only serving.
The stack uses NVIDIA Dynamo as its orchestration layer on Blackwell B200 GPUs, with vLLM, multimodal frontend support, disaggregated encoder/prefill/decode serving, KV-aware routing, LMCache-based KV offloading, OpenAI Chat Completions, model-aware routing, and AWS EKS deployments with custom sidecars and containers.
VLM traffic can include thousands of images per request, making image preprocessing and multimodal prompt construction significant serving concerns.
Dynamo's multimodal KV-aware routing, encoder/prefill/decode disaggregation, and LMCache-based KV offloading address prefill-heavy workloads and KV cache pressure.
AIPerf-based DAG benchmarks reproduce production QPS patterns, multi-turn conversations, many-image requests, and agentic DAGs rather than relying on single-shot synthetic prompts.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
Learn a practical workflow for translating English discourse into ASL gloss while preserving spatial references, question-answer structure, and consistent concept-to-gloss mappings.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
