How to Run an Agent Loop That Actually Converges
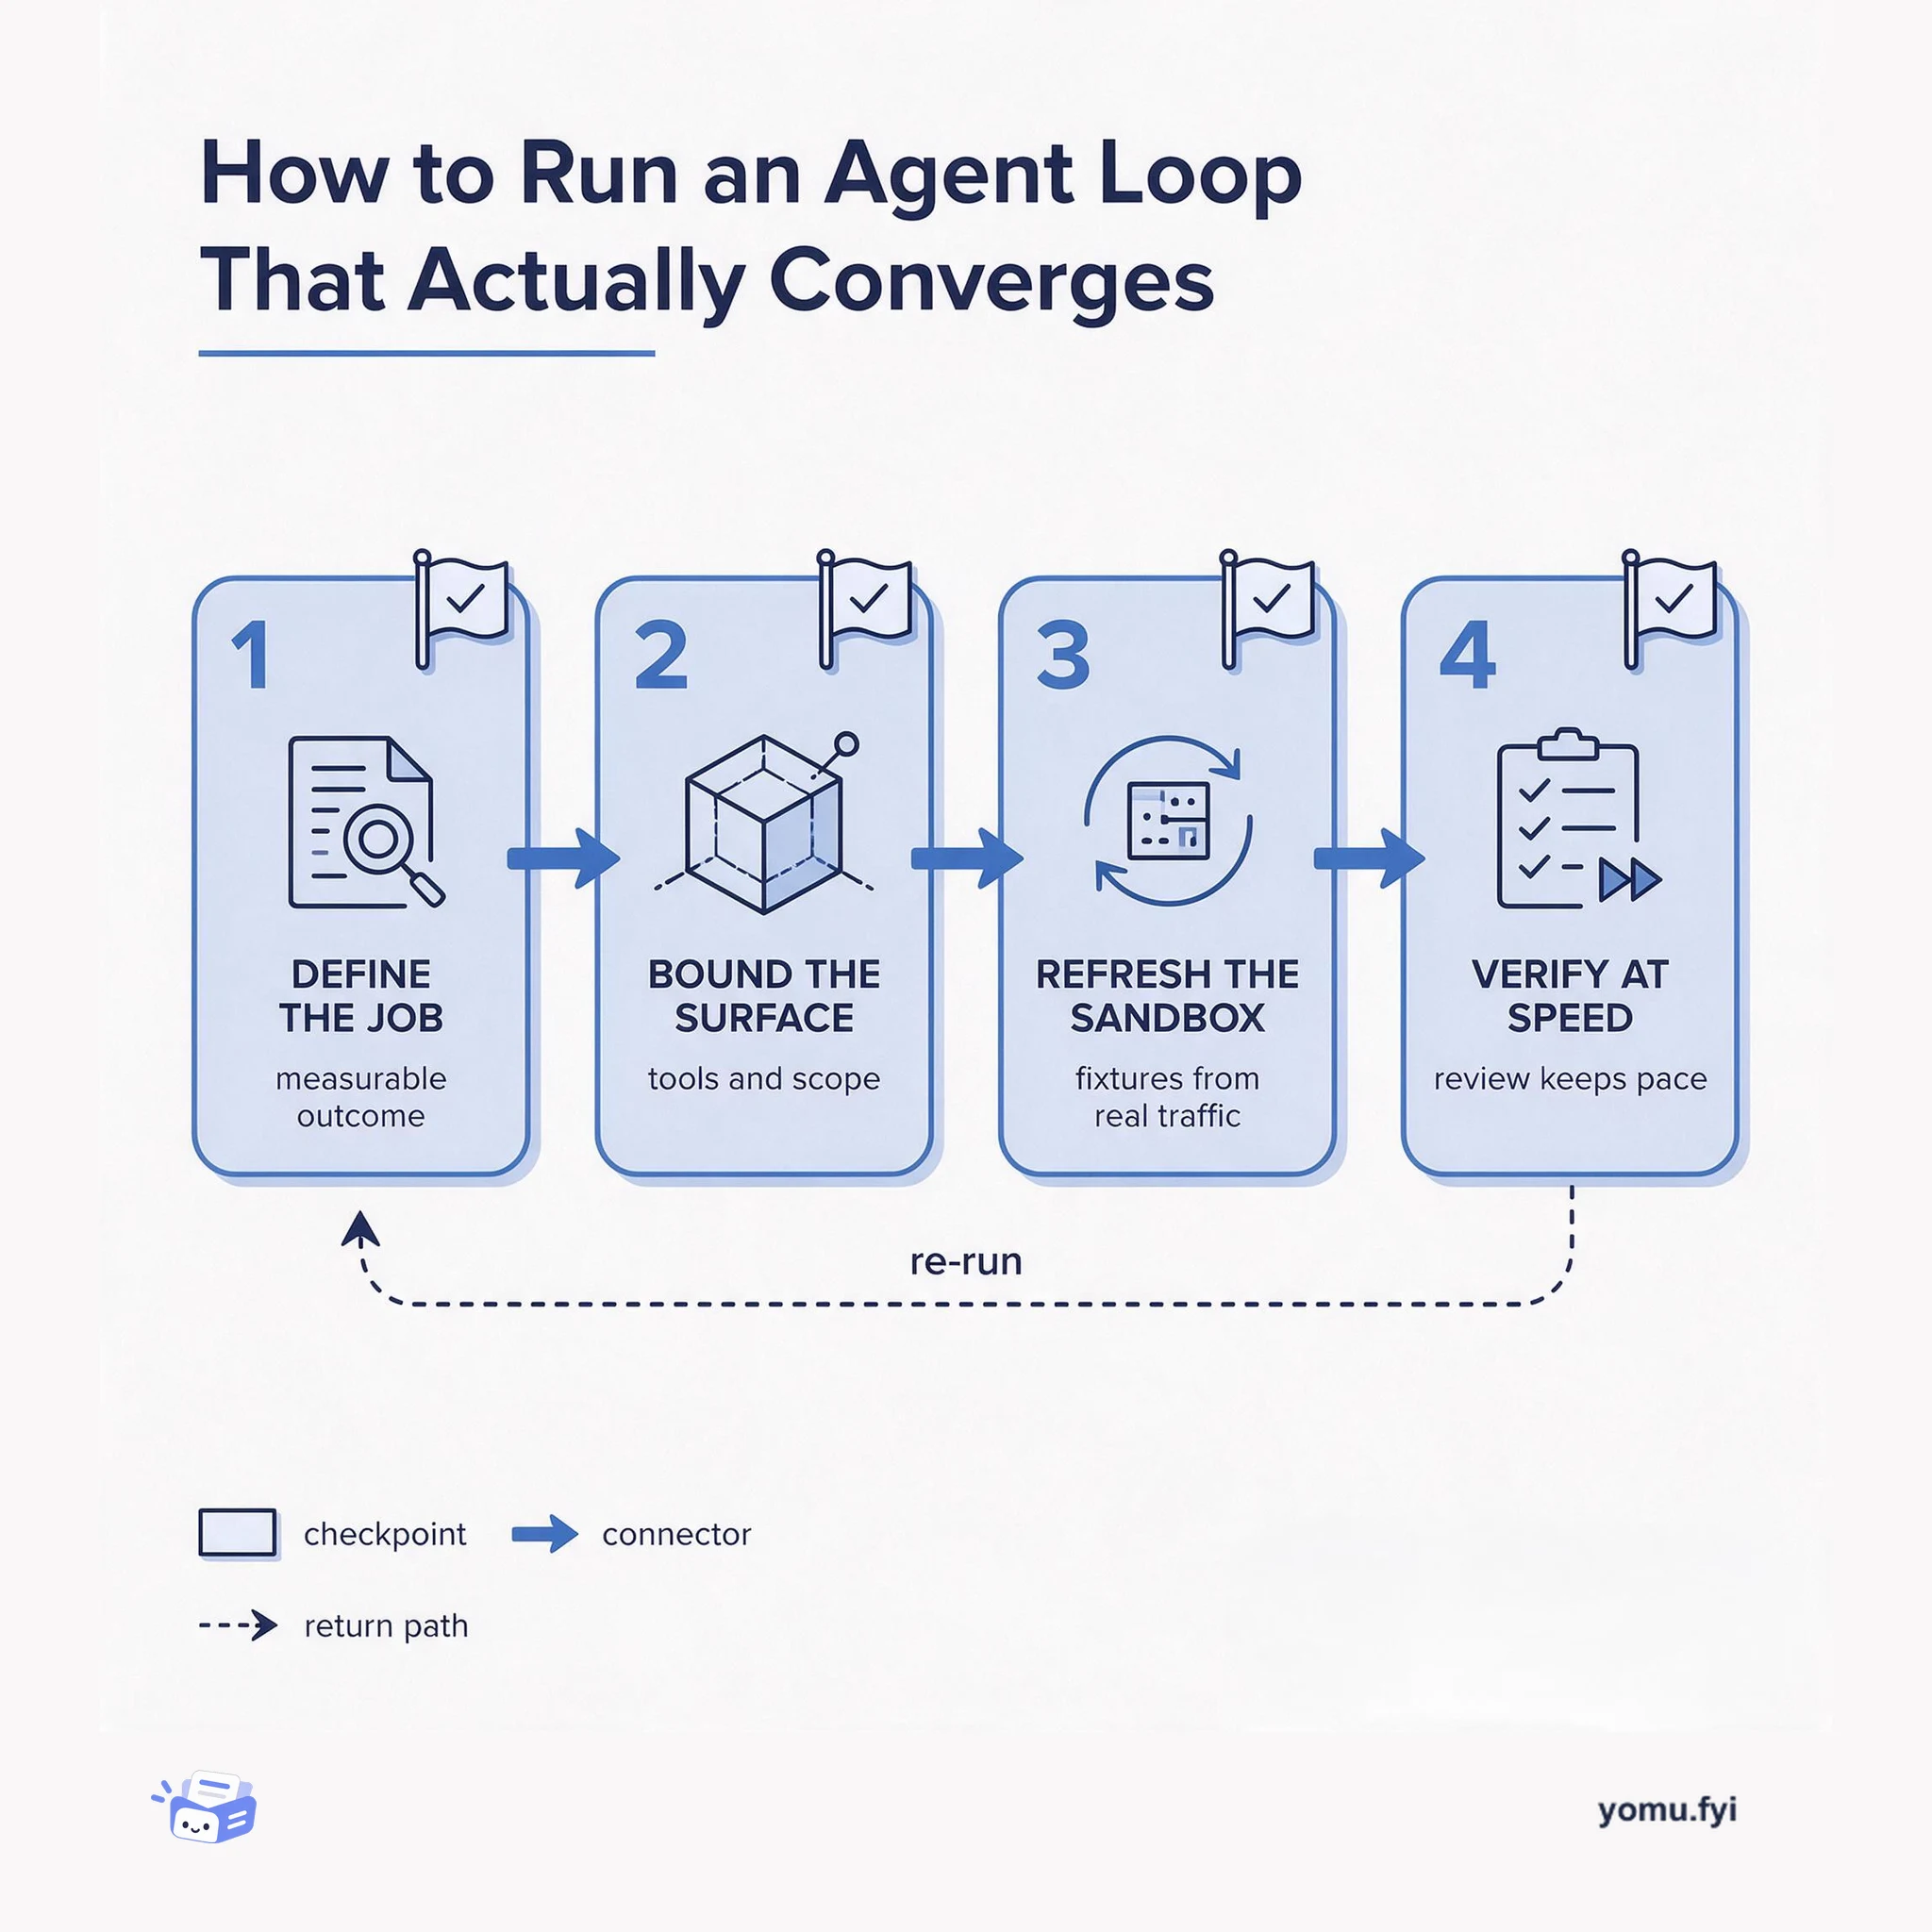
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
Learn a practical workflow for translating English discourse into ASL gloss while preserving spatial references, question-answer structure, and consistent concept-to-gloss mappings.
ASL gloss translation needs more than sentence-by-sentence conversion. This workflow starts with discourse context, tracks entities and their spatial locations, resolves question-answer clauses, and maintains stable English-to-ASL concept-gloss mappings. The final checkpoint evaluates spatial consistency, entity tracking, and gloss quality separately, giving engineers a clearer way to diagnose failures than relying on one sentence-level score.
The posts behind it
 Clickhouse · · Explainer
ClickHouse’s beta AI Functions let SQL queries call an LLM or embedding provider directly, keeping classification, extraction, generation, translation, redaction, filtering, embedding, and similarity work alongside stored data. The feature addresses workflows that export rows to separate LLM, orchestration, or vector-database systems and then reload results, with the stated goal of running the full RAG cycle in ClickHouse. Functions make remote HTTP calls per input, or batch embedding inputs, and return native ClickHouse values; in open-source deployments, named collections store provider credentials and endpoint settings. Examples use Hacker News data for topic classification and natural-language filtering, while the guidance emphasizes cheap predicates, quotas, LIMIT tests, prompt-injection defenses, non-determinism, cost, latency, and provider access to data in cleartext after TLS termination.
 Apple · · Problem & solution
DiscoSign addresses a limitation in sign language processing: systems have traditionally translated at the sentence level, overlooking discourse phenomena important to sign language comprehension. It presents a modular Large Language Model (LLM)-based framework for text-to-sign language gloss translation that handles spatial coreference resolution, Question-Answer Clauses (QACs), and concept-gloss consistency, preserving entity locations and stable English-to-ASL sign mappings across discourse. Because traditional translation metrics do not measure discourse-level quality, the authors introduce metrics for each coherence dimension targeted by the framework. Experiments on sentence-level and discourse-level datasets report improved spatial consistency and entity tracking over sentence-only translation, while maintaining competitive single-sentence gloss quality; the work describes this as the first systematic framework with a corresponding evaluation methodology.
Apple · · BenchmarkEvaluating video captions is difficult because reference-matching metrics can penalize valid descriptions that use different wording or focus on different visual content, while offering little fine-grained diagnosis. The paper reframes quality around information fidelity: captions should cover salient visual information and remain factually accurate. It introduces CapQuiz, a reference-free benchmark that tests caption utility through human-verified, fine-grained multiple-choice questions derived from videos, organized into 10 Descriptive and Inferential question types across 24 domains. It also proposes CapF1, which combines CapP for factuality with CapR for coverage; extensive experiments report significantly stronger correlation with human judgments than existing metrics and interpretable insight into model performance.
 Pinterest · · Explainer
Pinterest describes building a VLM serving stack on NVIDIA Blackwell B200 GPUs and NVIDIA Dynamo for multimodal products including Pinterest Assistant, hybrid search, multimodal reranking, content understanding, signal generation, and content safety. Unlike text-only workloads, requests may contain thousands of images, costly and variable prefill, long multi-turn histories, and large KV caches, making preprocessing, routing, memory, and latency central serving concerns. The implementation combines Dynamo's distributed orchestration, multimodal frontend and vLLM support, KV-aware routing, disaggregated encoder/prefill/decode serving, and LMCache-based KV offloading with vLLM, an OpenAI Chat Completions interface, model-aware routing, EKS, and custom deployment components. Production-oriented AIPerf DAG benchmarks model QPS patterns, multi-turn conversations, many-image requests, and agentic DAGs; the team concludes that payload design, cache-aware routing, offload tiers, and a shared platform are essential to meeting product targets and accelerating new launches.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
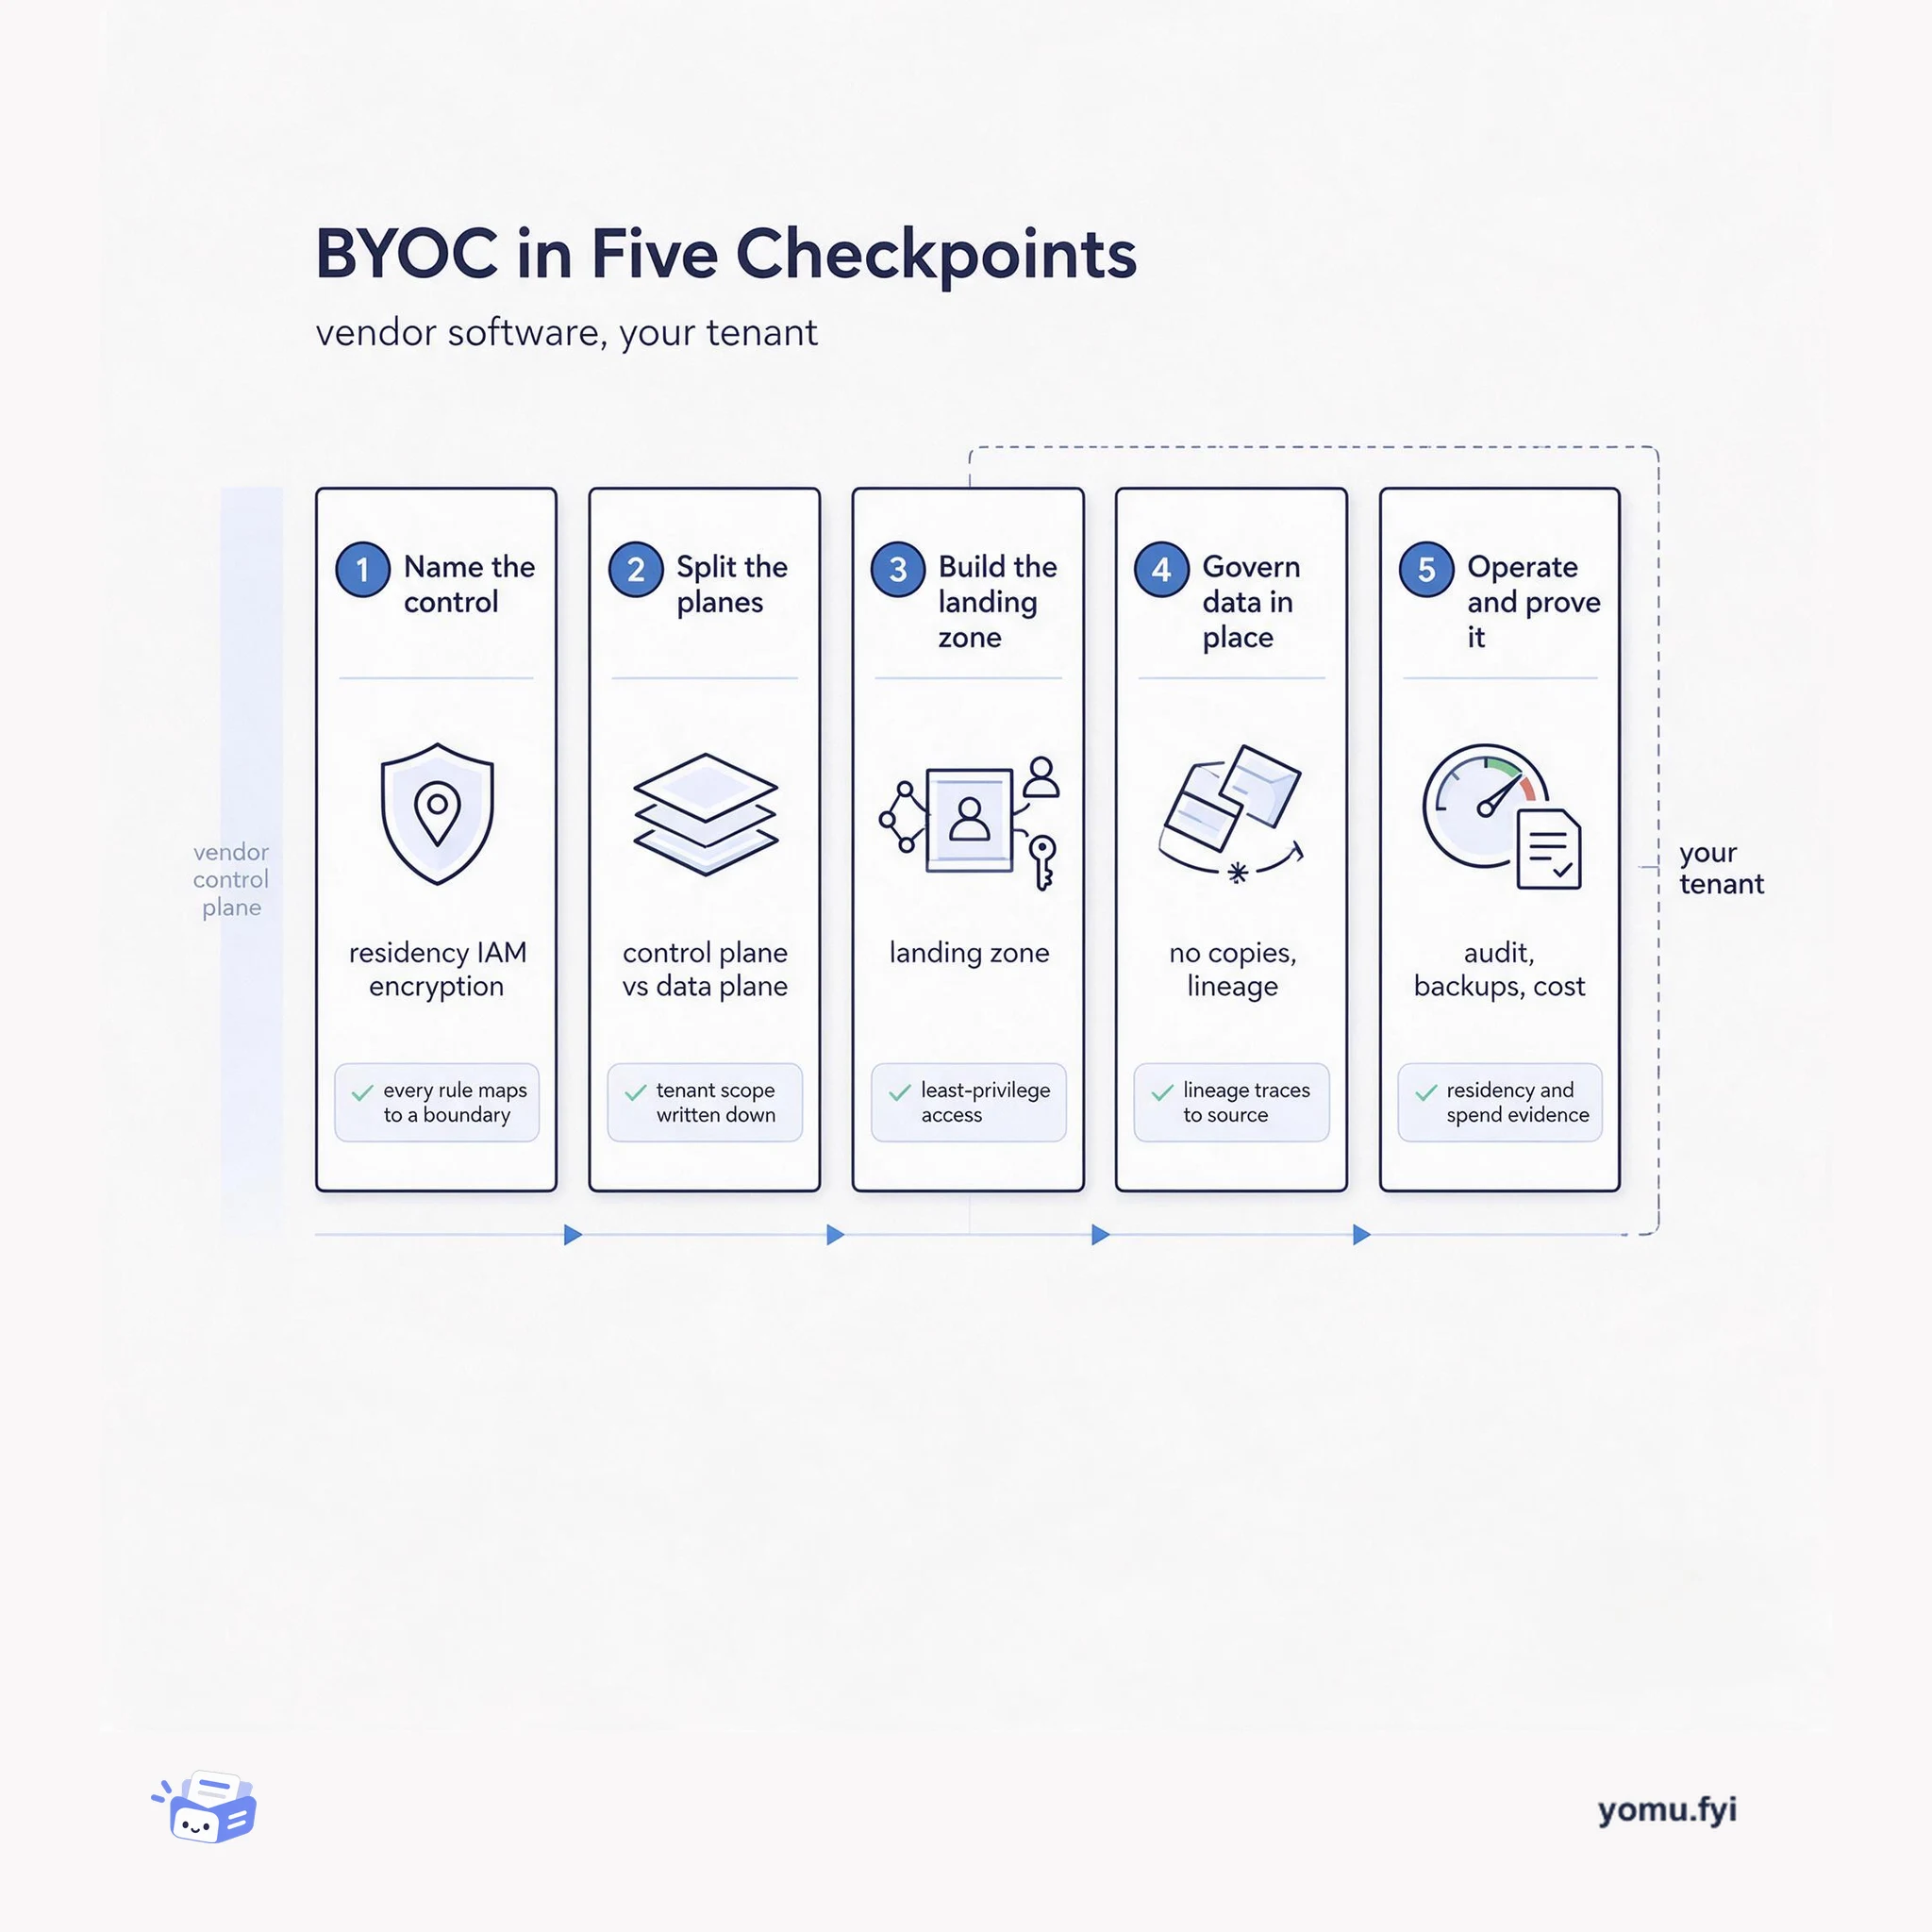
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.