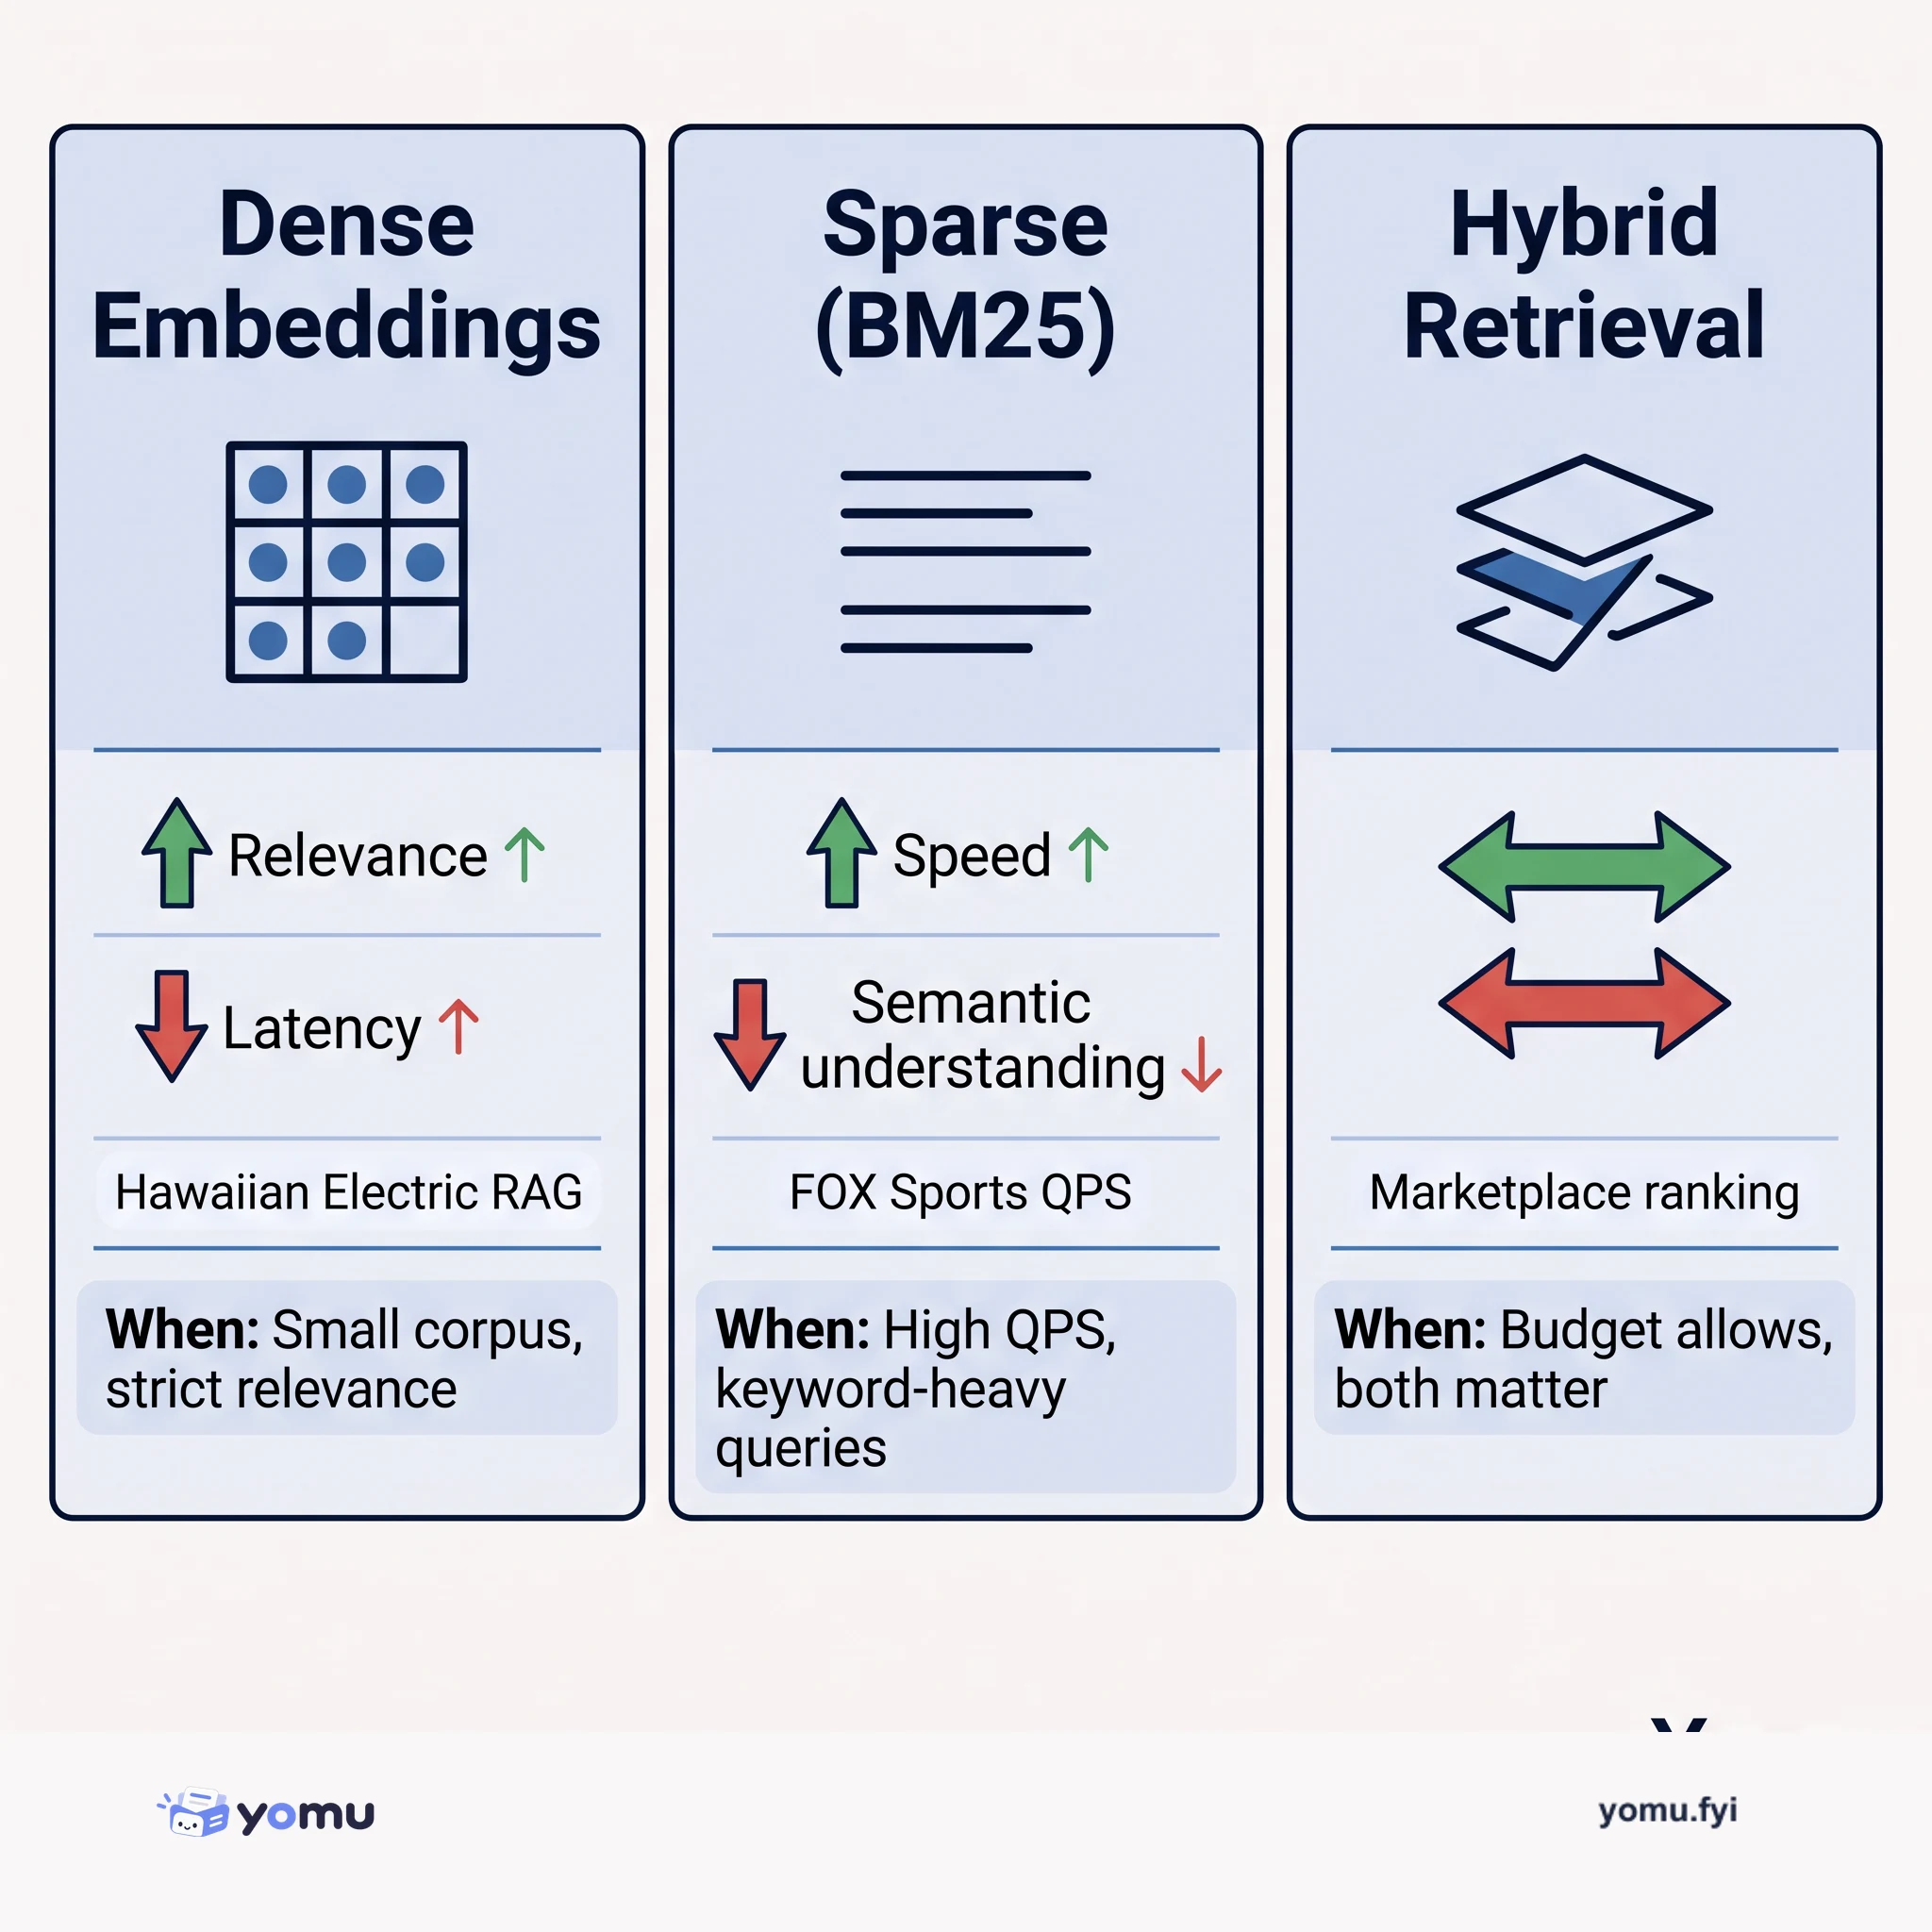
AI Search: Speed vs. Relevance Trade-off
AI Search balances retrieval speed and result quality by choosing between dense embeddings, sparse lexical search, and hybrid approaches. Understand which trade-off fits your workload.
 DatabricksJiayi Wu, Luke Lefebure, Adam GuraryExplainer
Real-time product search for an online marketplace must retrieve, filter, rank, and respond in milliseconds while balancing latency, relevance, revenue, and click-through rate. The Databricks architecture divides the pipeline into ingestion, retrieval, and refinement, using Lakeflow pipelines and AI Functions for source processing, AI Search for embeddings and hybrid retrieval, and Lakebase for sub-10ms operational signals. It recommends validating p95/p99 latency, throughput, retrieval quality, and engagement metrics, with MLflow supporting systematic evaluation and caching helping meet strict latency requirements. As an example, FOX Sports used AI Search for thousands of QPS and achieved a 2x improvement in query success rate, combining streaming ingestion, two-phase retrieval, model serving, caching, and trending searches.
Online marketplace search must deliver relevant, personalized, and trustworthy ranked choices within milliseconds while accounting for structured constraints such as budget, preferences, location, and availability. The system also needs to balance technical metrics, including latency and throughput, with business outcomes such as revenue, click-through rate, and conversions.
The architecture uses Databricks Auto Loader, Lakeflow Spark Declarative Pipelines, and AI Functions to process source data; AI Search to create embeddings, apply metadata filters, and perform full-text, semantic, or hybrid retrieval; and Lakebase to provide real-time application state for refinement. Ranking, personalization, business rules, observability, load testing, and agent integrations extend the pipeline.
The search pipeline has three functional segments: ingestion prepares and indexes product data, retrieval generates candidates through full-text, semantic, or hybrid search, and refinement applies intent, ranking, personalization, and business rules.
Lakebase provides session state, inventory, pricing, and user preferences with sub-10ms latency, while managed change-data-capture syncs operational data to Delta without custom pipelines.
FOX Sports reported handling thousands of QPS with a 2x improvement in query success rate by combining streaming ingestion, two-phase retrieval, model serving, caching, and trending searches.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
AI Search balances retrieval speed and result quality by choosing between dense embeddings, sparse lexical search, and hybrid approaches. Understand which trade-off fits your workload.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
