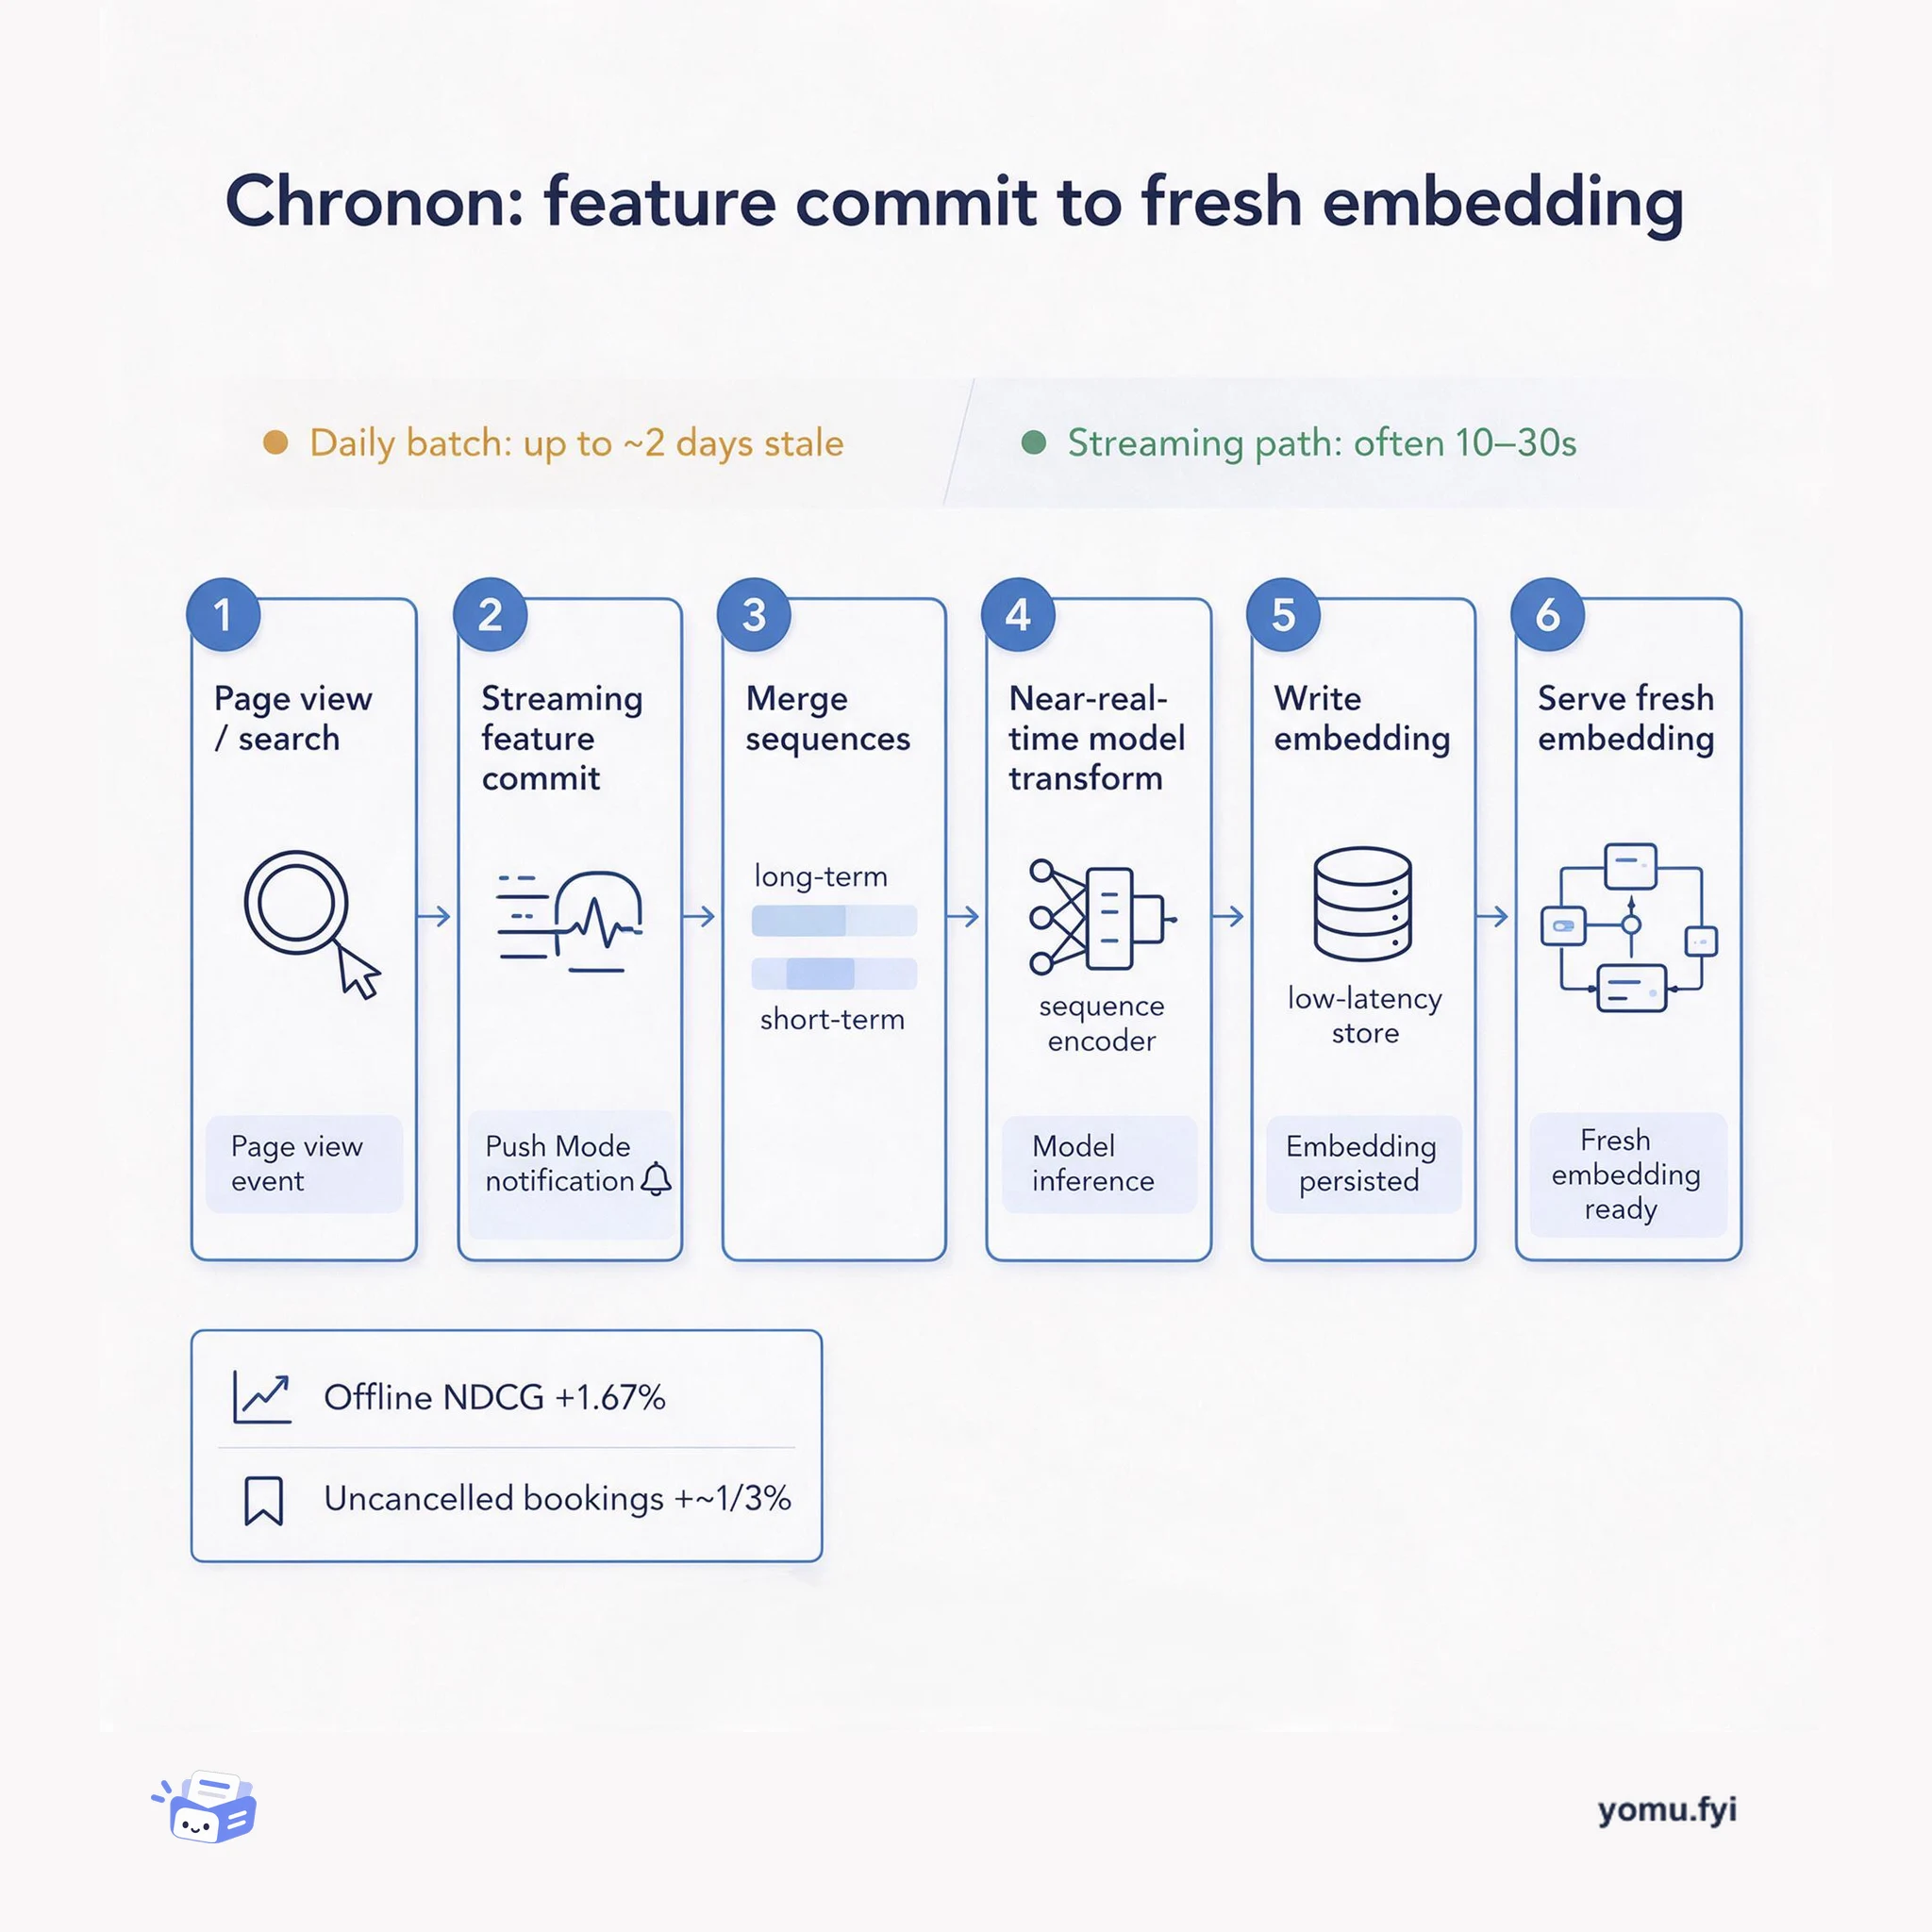
Chronon: Turning Feature Commits into Fresh Embeddings
A step-by-step look at how Chronon turns streaming feature commits into fresh model inputs, cutting recommender staleness from nearly two days to seconds.
 DatabricksJungtaek Lim, Wenchen Fan, Andreas Neumann, Serge Rielau, Hyukjin Kwon, Jerry Peng, DB Tsai, Daniel Tenedorio, Xiao Li, Reynold XinAnnouncement
Apache Spark 4.3 introduces stateful processing in Real-Time Mode, achieving sub-150 ms P99 end-to-end latency for streaming aggregation, deduplication, and custom stateful processing using transformWithState. This eliminates the need for a separate streaming engine for millisecond-scale latency in fraud detection, user activity monitoring, and device monitoring, enabled by native concurrent stage scheduling and pipelined shuffles. The release also includes Project Feather for faster iteration on small data by reducing execution overhead, and SCD Type 2 Auto CDC for tracking record changes over time. SQL enhancements include JSON_TABLE, VARIANT transformations, ASOF JOIN for temporal matching, and a nanosecond timestamp preview. Spark 4.3 marks a shift to quarterly feature releases, with over 200 contributors addressing more than 1,100 Jira tickets, and is now available in Databricks Runtime 19.
Apache Spark 4.3 extends Real-Time Mode to stateful processing, enabling millisecond-scale latency for streaming aggregations, deduplication, and custom stateful operations without a separate streaming engine.
Native concurrent stage scheduling and pipelined shuffles (PipelinedShuffleDependency) allow producer and consumer stages to run simultaneously, with StreamingShuffleManager transferring records incrementally. Project Feather introduces opt-in shuffle-free single-task execution for small, single-partition query fragments.
Spark 4.3’s Real-Time Mode now supports stateful operations like streaming aggregation, dropDuplicates, and transformWithState, achieving sub-150 ms P99 latency in benchmarks.
The release introduces PipelinedShuffleDependency and StreamingShuffleManager, enabling concurrent stage execution and incremental data transfer for continuous streaming.
Project Feather reduces execution overhead for small data by enabling opt-in shuffle-free single-task execution, making Spark more responsive for iterative development.
Spark 4.3 achieves sub-150 ms P99 end-to-end latency for stateful workloads including dropDuplicates (136 ms), window aggregation (139 ms), and transformWithState (141 ms) in benchmarks.
It introduces native concurrent stage scheduling and pipelined shuffles via PipelinedShuffleDependency, allowing producer and consumer stages to run concurrently and transfer records incrementally.
Project Feather targets unnecessary execution overhead for small data by introducing opt-in shuffle-free single-task execution for eligible small, single-partition query fragments, making Spark more responsive for iterative development.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A step-by-step look at how Chronon turns streaming feature commits into fresh model inputs, cutting recommender staleness from nearly two days to seconds.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
