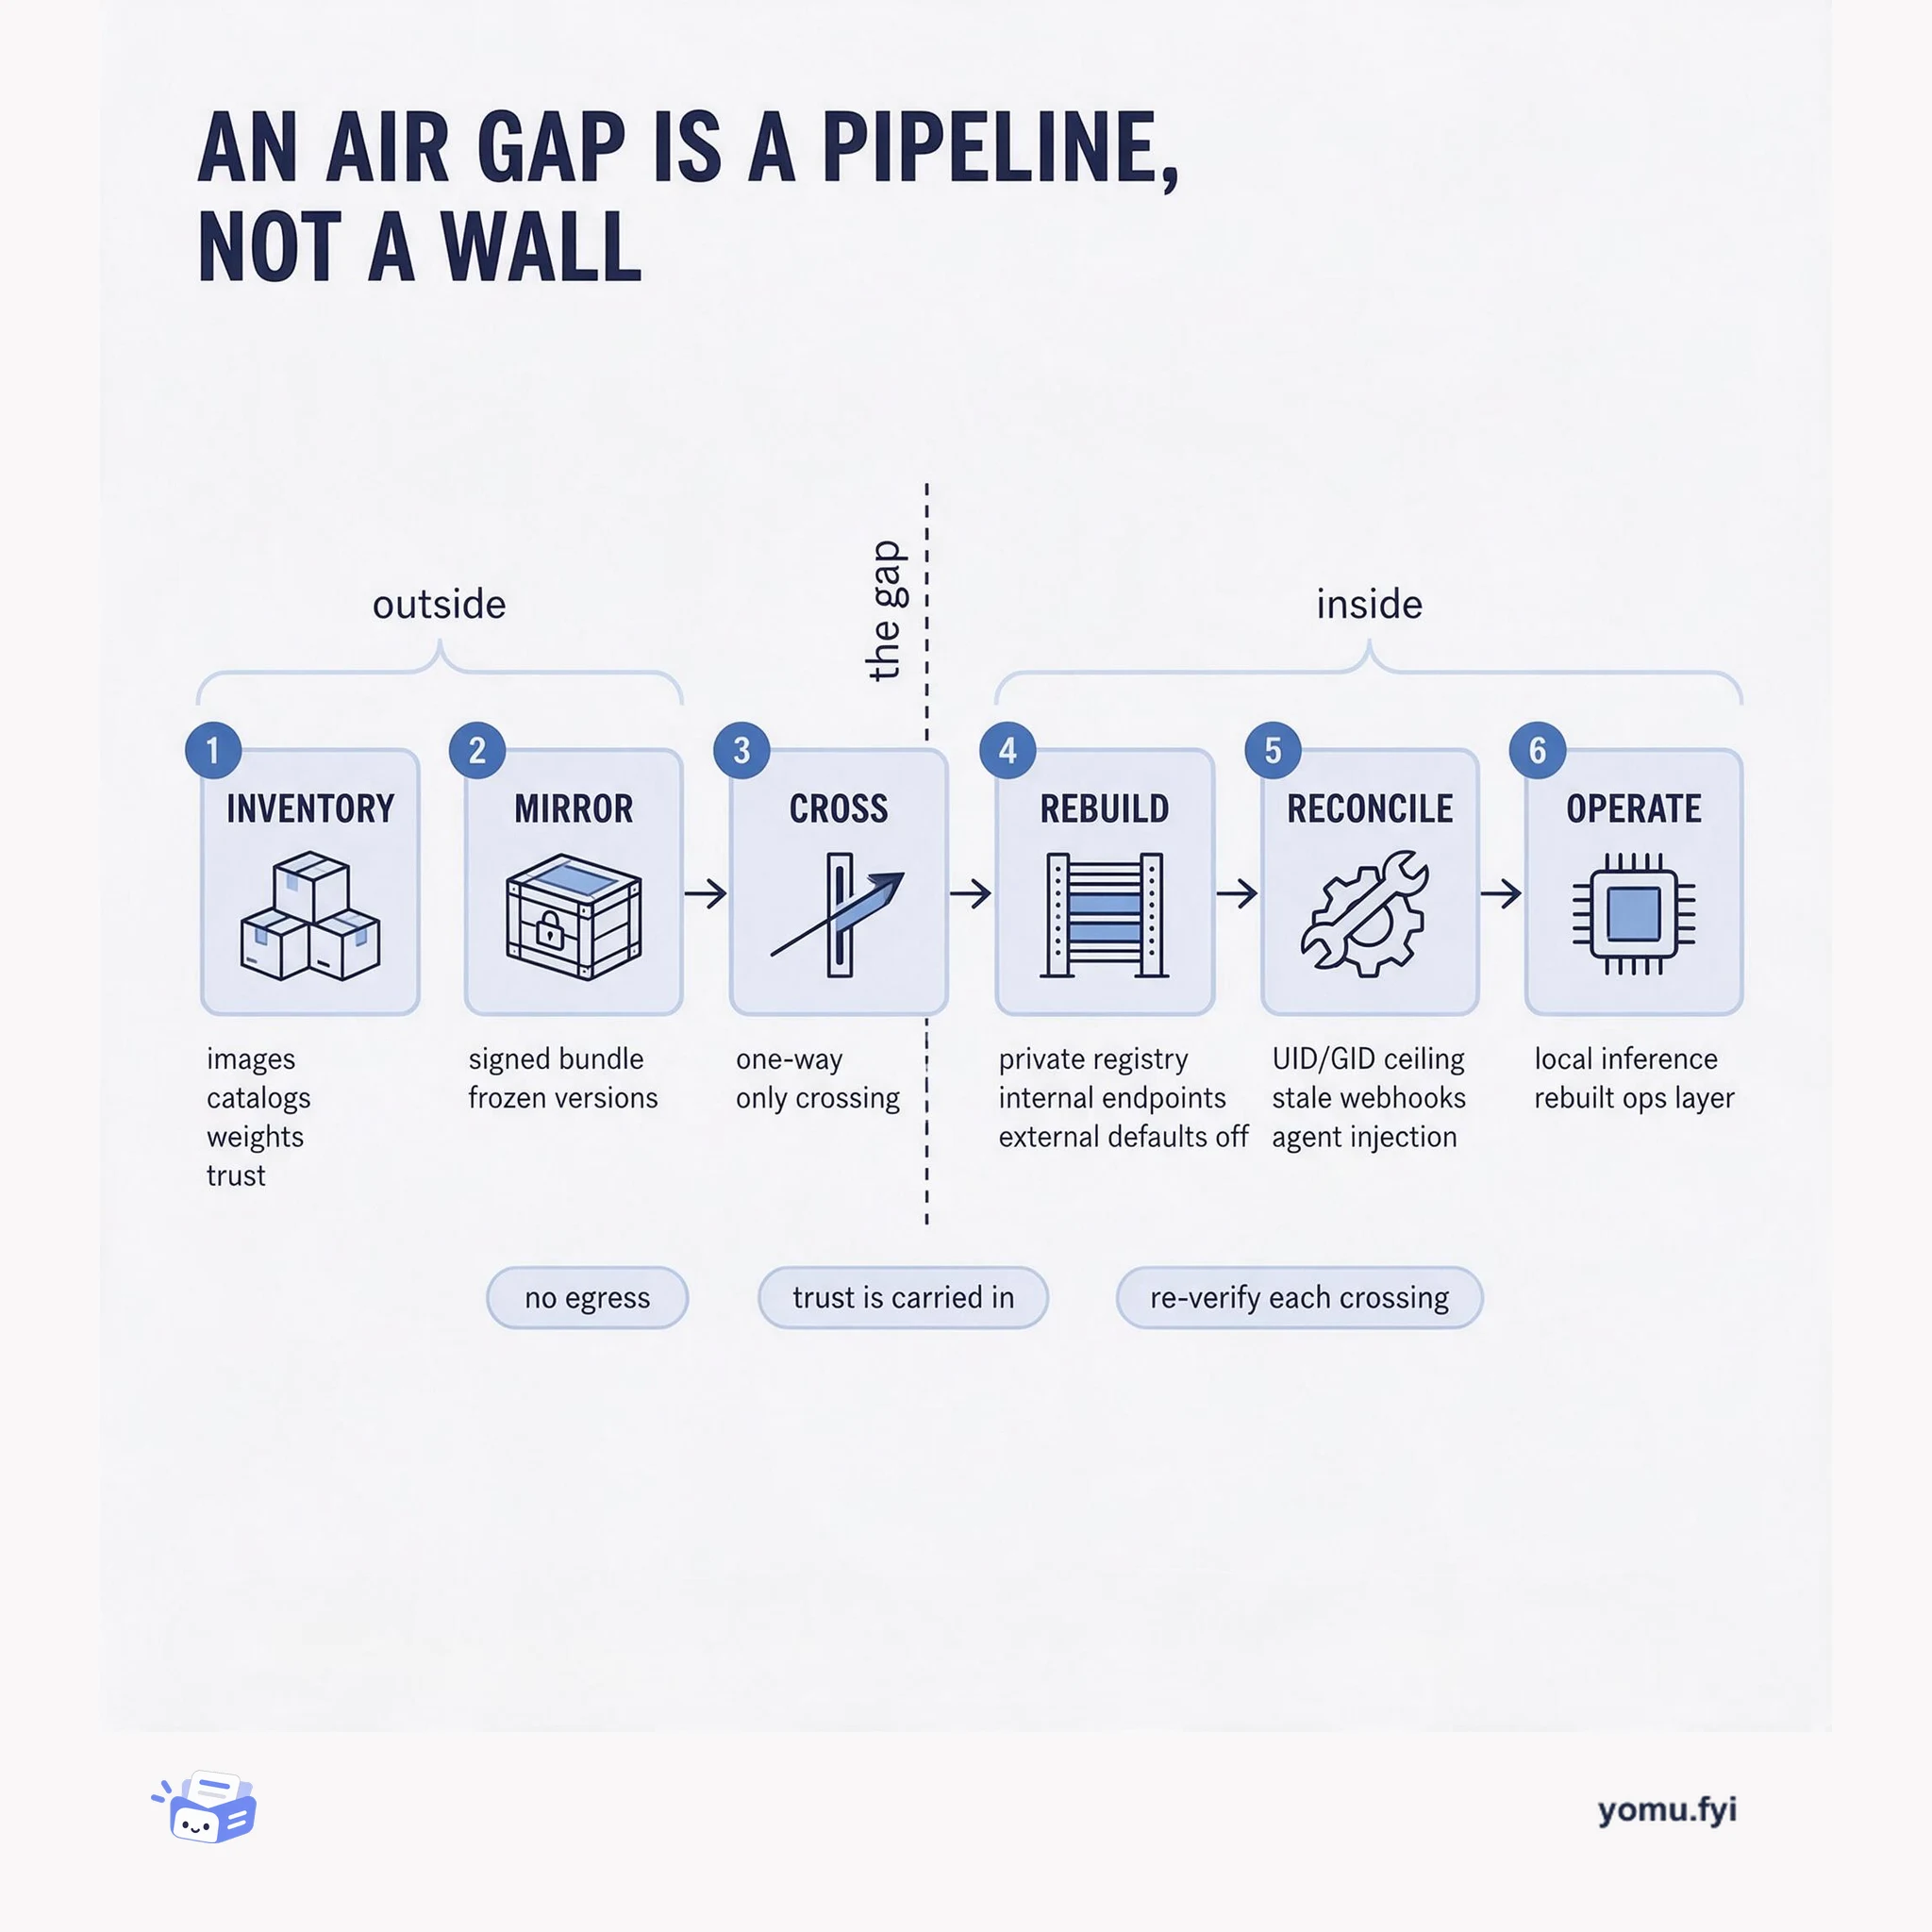
An Air Gap Is a Pipeline, Not a Wall
An air gap is a one-way artifact pipeline, not just a blocked network. This explainer follows six stages, from mirroring dependencies outside to operating inside with no egress.
 JetbrainsVladimir SotnikovAnnouncement
JetBrains announced Junie Local is now supported on the NVIDIA RTX Spark platform from day one, and Windows support has moved from experimental to stable. The RTX Spark pairs a Blackwell RTX GPU with a Grace CPU, enabling local AI coding on slim laptops and compact desktops. In testing, Junie Local reached generation speeds of up to 55 tokens per second on the RTX Spark, using Blackwell’s Tensor Cores for FP8 computation and speculative decoding. Junie Local automatically sizes the context window to fit available GPU memory, and users can choose between Qwen3.6-27B or a merged Qwen3.8-3.6-27B-blend model. The local engine now features a simple installer, reliable startup and updates, and no token charges or quotas, with code never leaving the machine.
Junie Local was initially launched in August requiring an M5 Mac with 64 GB memory. In September, experimental Windows support shipped for NVIDIA RTX cards with 24 GB VRAM. Now, Junie Local is supported on the NVIDIA RTX Spark from day one, and Windows support is stable. The RTX Spark pairs a Blackwell RTX GPU with a Grace CPU, enabling local AI coding on slim laptops and compact desktops. In testing on the RTX Spark, Junie Local reached generation speeds of up to 55 tokens per second.
Junie Local is adapted to the NVIDIA RTX Spark by using Blackwell’s Tensor Cores for efficient FP8 computation and speculative decoding to accelerate generation. The context window is automatically sized to fit the available GPU memory. The installer was rebuilt to recognize the PC, check the GPU and driver, and install an optimized inference engine, the model, and the Junie integration. Users can choose between Qwen3.6-27B or a merged Qwen3.8-3.6-27B-blend model.
Junie Local on RTX Spark achieves up to 55 tokens per second generation speed using Blackwell Tensor Cores for FP8 computation and speculative decoding.
Junie Local automatically sizes the context window to fit the GPU memory available, allowing it to retain more code and conversation history.
Windows support is now stable for NVIDIA RTX GPUs with at least 24 GB VRAM (Ampere or newer), including RTX 3090, 4090, and 5090, with a simple installer that checks GPU and driver.
You need a Windows PC with an NVIDIA RTX GPU with at least 24 GB of VRAM (Ampere or newer, such as RTX 3090, 4090, or 5090) or an NVIDIA RTX Spark running Windows 11 on Arm. You also need NVIDIA driver 581 or newer and about 20 GB of free disk space.
You can choose between Qwen3.6-27B or Qwen3.8-3.6-27B-blend, a merged model that retains much of Qwen3.8's coding ability and Qwen3.6's shorter reasoning. Support for additional models is coming.
Junie Local automatically sizes the context window to fit the memory available to the GPU in your configuration. With more memory, it can retain more code, tool outputs, and conversation history in its running context.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
An air gap is a one-way artifact pipeline, not just a blocked network. This explainer follows six stages, from mirroring dependencies outside to operating inside with no egress.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
