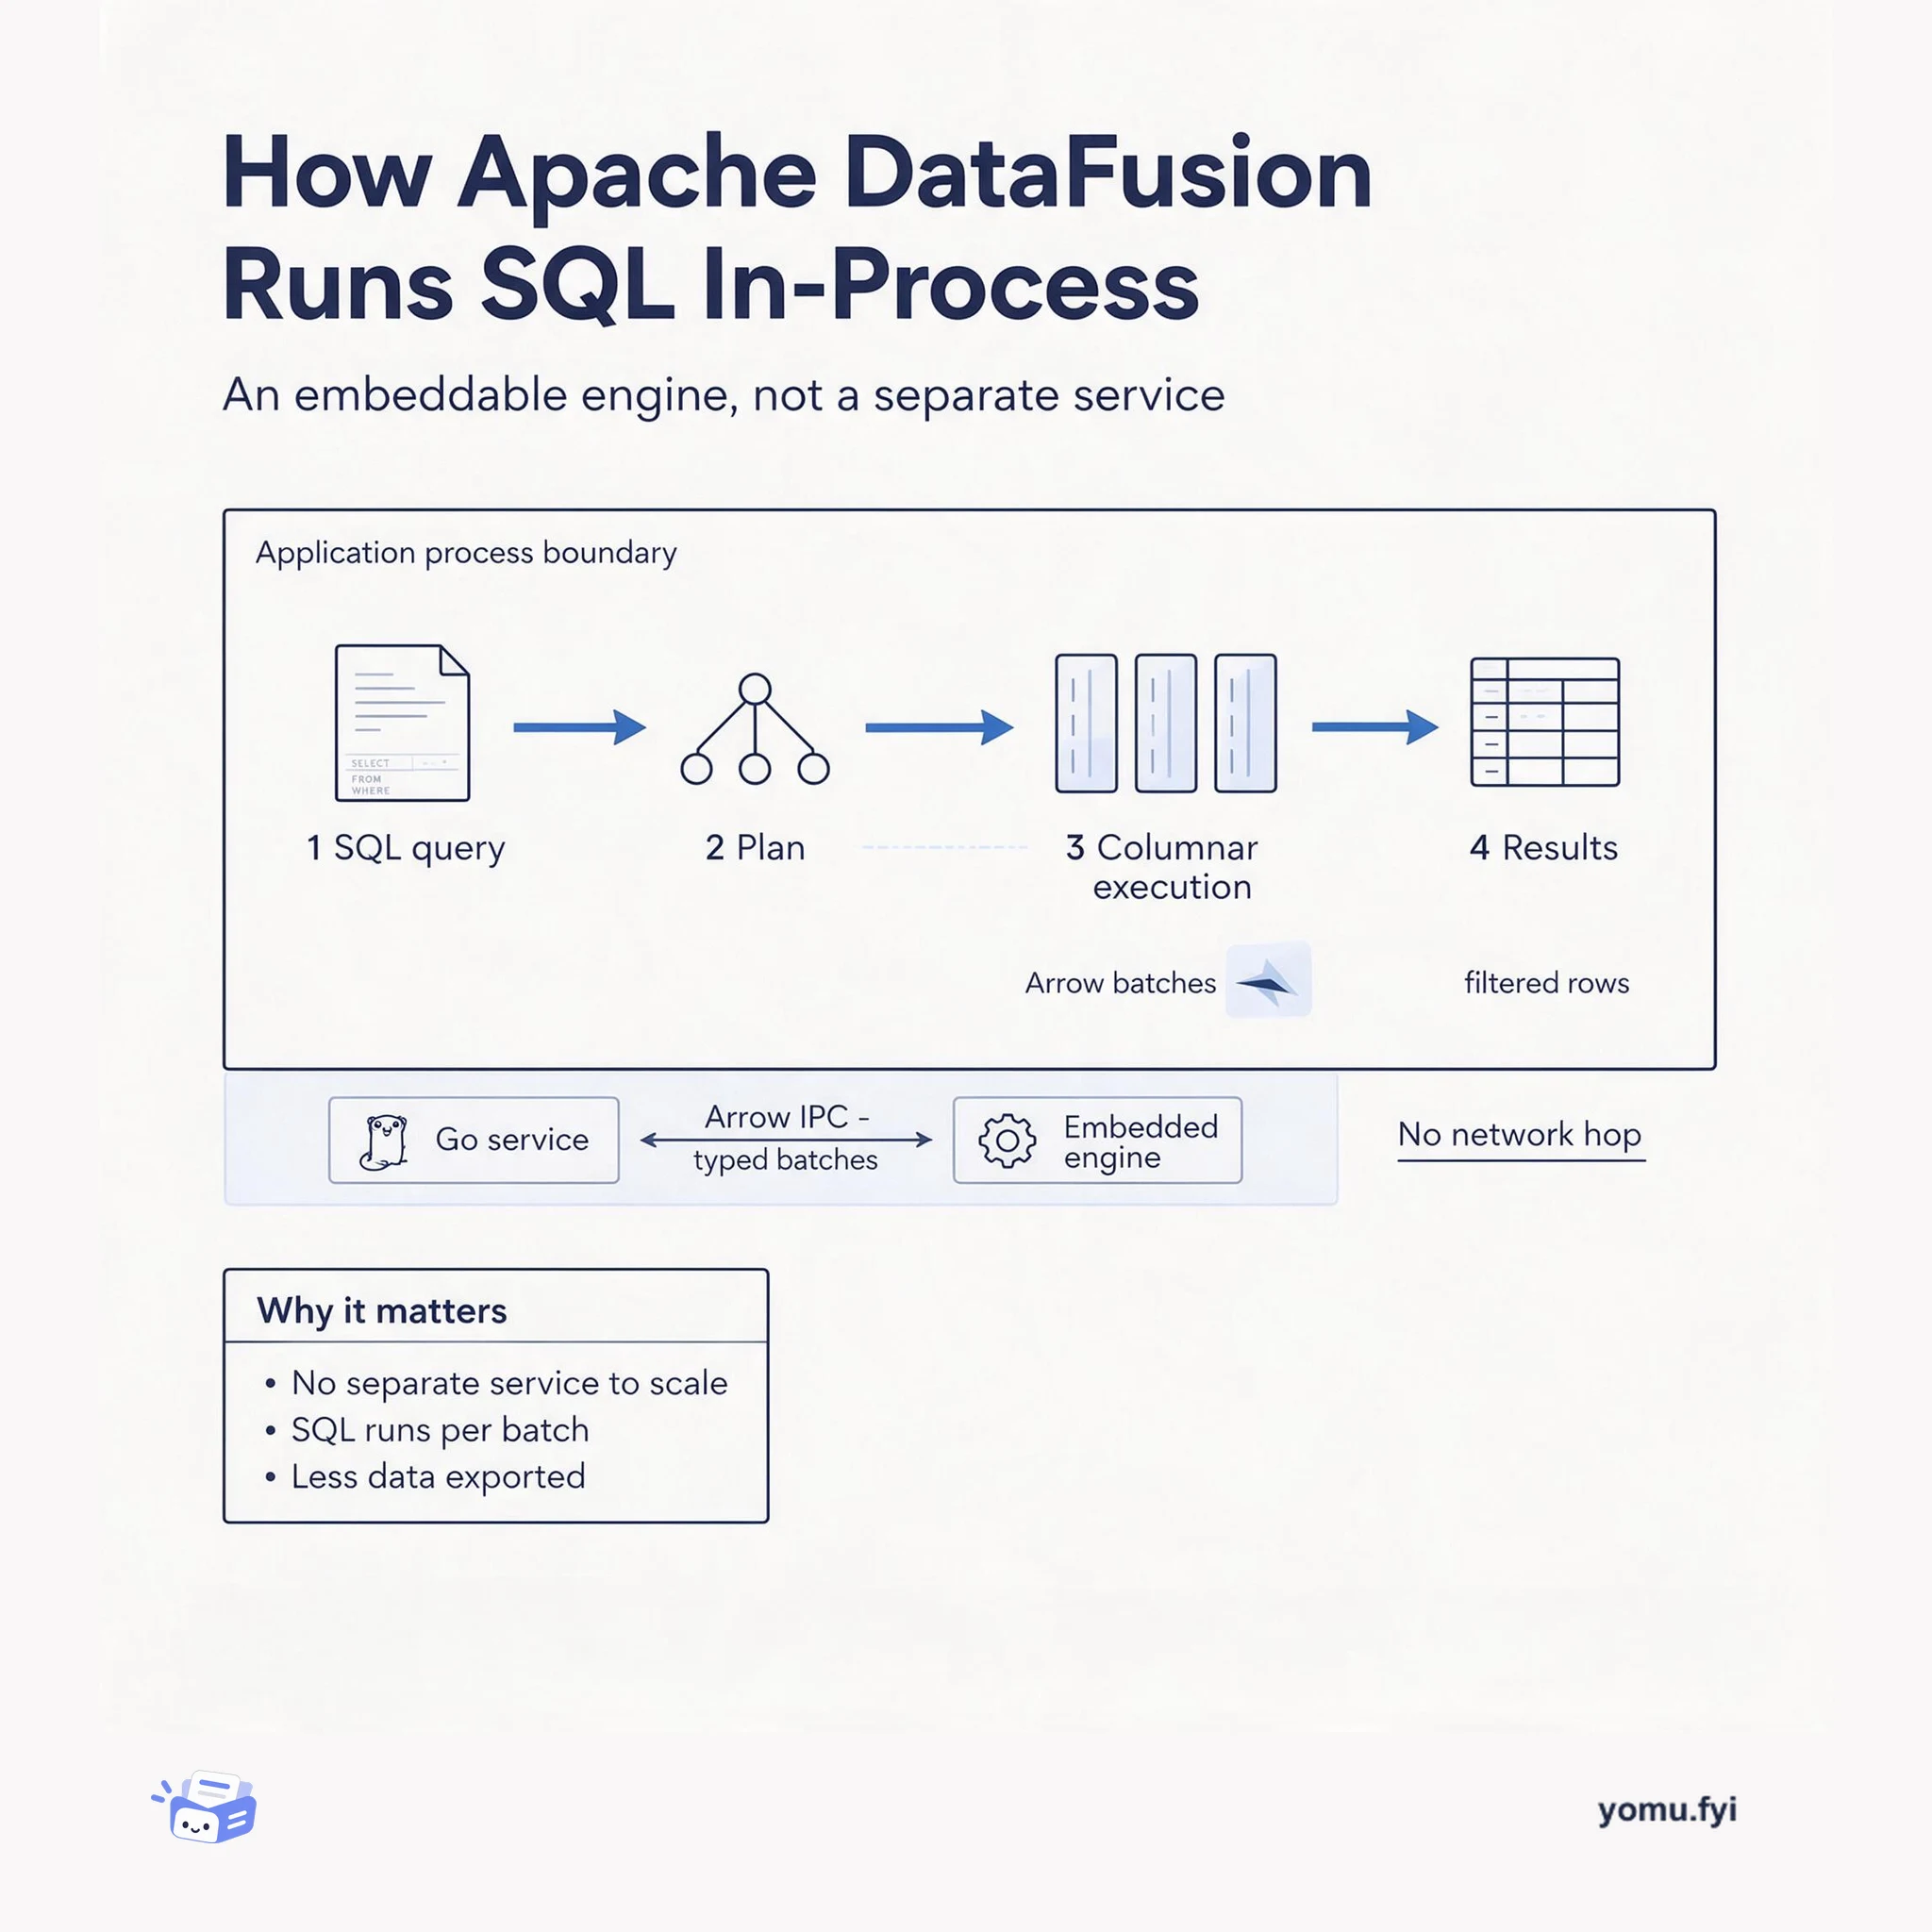
How Apache DataFusion Runs SQL In-Process
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
An air gap is a one-way artifact pipeline, not just a blocked network. This explainer follows six stages, from mirroring dependencies outside to operating inside with no egress.
An air-gapped environment is defined less by what it blocks than by what it must carry in. Container images, operator catalogs, model weights, package mirrors, and PKI trust all have to be inventoried, frozen into a signed bundle outside, and moved across a single one-way crossing. Inside, that bundle must be rebuilt into internal services such as a private registry, internal extension endpoints, and a trust ConfigMap, with default external registries turned off. The runtime then needs reconciliation, because rootless UID/GID ceilings, stale admission webhooks, and monitoring agent injection only fail once you are offline.
Usually the components that quietly reach outward: default registries, extension marketplaces, and monitoring agents that inject sidecars into your namespaces. In OpenShift Dev Spaces, the checklist is to mirror operator catalogs, run an internal Open VSX server, set PKI trust via a ConfigMap, and disable the default devfile registry. Labeling namespaces to block agent injection helps.
Rootless containers need user namespace UID and GID ranges under a 65,536 UID ceiling, and the wrong range fails only when a build runs. In Dev Spaces, UDI 3.22 needed a manual script with a corrected range while UDI 3.26 mapped it automatically. Stale admission webhooks from an old operator namespace cause a similar failure after reinstall.
No. Local inference is one alternative: Junie Local on an RTX Spark machine keeps code on the device with no token charges or quotas. Another is a programmable egress path, where a gateway routes matched traffic to inline code that inspects or rewrites it rather than blocking it.
The posts behind it
 NVIDIA · · Announcement
NVIDIA RTX Spark consolidates AI development onto a single machine by integrating the GB10 system-on-a-chip, up to 128GB unified memory, a Blackwell GPU with 1 petaflop of FP4 compute, and a Grace CPU. This eliminates the split across laptop, cloud API, and cloud VM, enabling local coding agents and reducing token consumption through hybrid prompt routers. Compared with Intel Panther Lake, RTX Spark delivers 4.6x faster coding-agent performance, 2.7x faster fine-tuning, and 1.8x faster compilation. A partnership with Microsoft provides Windows Developer Config, WSL optimizations, native PyTorch-CUDA, Python 3.15, and over 2,000 Conda packages for Arm. Local agents like GitHub Copilot, Pi, and Junie are optimized, and decision models in llama.cpp and Unsloth offer near-instant actions while the Nemotron 3.5 Bolt model fits in 24GB using 2-bit quantization.
 Jetbrains · · Announcement
JetBrains announced Junie Local is now supported on the NVIDIA RTX Spark platform from day one, and Windows support has moved from experimental to stable. The RTX Spark pairs a Blackwell RTX GPU with a Grace CPU, enabling local AI coding on slim laptops and compact desktops. In testing, Junie Local reached generation speeds of up to 55 tokens per second on the RTX Spark, using Blackwell’s Tensor Cores for FP8 computation and speculative decoding. Junie Local automatically sizes the context window to fit available GPU memory, and users can choose between Qwen3.6-27B or a merged Qwen3.8-3.6-27B-blend model. The local engine now features a simple installer, reliable startup and updates, and no token charges or quotas, with code never leaving the machine.
 Red Hat · · Problem & solution
Scaling OpenShift Dev Spaces in air-gapped environments requires addressing four friction points: third-party monitoring agents, rootless container runtimes, custom install namespaces, and admission webhooks. Dynatrace OneAgent sidecar conflicts are resolved by labeling all Dev Spaces namespaces with dynatrace.com/inject: “false” to prevent init container injection. Rootless Podman inside workspace pods needs user namespace UID/GID ranges respecting a 65,536 UID ceiling; UDI 3.22 requires a manual script with a corrected range, while UDI 3.26 handles mapping automatically. Stale admission webhooks from a previous operator install namespace must be manually deleted before reinstalling into a different namespace to avoid conflicting definitions. A readiness checklist includes mirroring operator catalogs, deploying an internal Open VSX server with PostgreSQL, configuring PKI trust via ConfigMap, and disabling the default devfile registry.
 Hugging Face · · Announcement
Reflection released Beam, a 501B-parameter mixture-of-experts model with 23B active parameters per token, under the Apache 2.0 license, targeting coding and agentic use cases. The model supports a 1M-token context window using hybrid attention with 43 sliding-window and 9 global layers, and a residual stream that scales sublayer outputs by 1/sqrt(k) to maintain constant magnitude. Its MoE router uses a group-limited scheme with 256 experts, 8 routed per token, and the BF16 checkpoint occupies about 1 TB. Benchmarks show strong performance: 81.6% on SWE-bench Verified, 97.7% on AIME 2026, and 90.6% on GPQA Diamond, with minimal degradation in FP8 and NVFP4 quantizations. The model ships with a Rust-based harness, day-0 support in transformers, vLLM, and SGLang, and includes SFT and RL recipes, with a $10,000 Hub credits competition for community projects.
 Stack Overflow · · Explainer
MCP standardized how AI models connect to tools, with clients like Claude Code and Cursor adopting it and SDK downloads approaching half a billion monthly. However, production use reveals that the protocol solves only the interface problem, not the operational concerns around authentication, rate limiting, idempotency, and observability. Teams repeatedly build duplicate infrastructure for deployment, secret handling, health checks, and access control because the protocol does not address these. Context efficiency also remains a challenge: a benchmark showed reducing context from 220,393 to 27,352 tokens (87.6%) while maintaining test pass rates, highlighting the need for deliberate context selection. The author argues that MCP’s success forces the question of building a production-grade infrastructure layer, similar to how HTTP led to CDNs and API gateways.
 Cloudflare · · Announcement
Traditional secure web gateways enforce security through a binary allow, block, or log model, which limits customization for complex environments. Cloudflare is integrating its Cloudflare Gateway and Data Loss Prevention with Cloudflare Workers, allowing customers to run arbitrary code inline at the moment a security decision is made. The new Forward action, available in public beta, routes matched HTTP traffic to a Worker that acts as inline middleware, enabling request and response modification or asynchronous tasks like sending Slack messages. Custom Functions, arriving before the end of the year, call a Worker during policy evaluation and return values used as selectors, enabling data-conditional rules and DLP validation against external APIs. Because Gateway and Workers run on the same machines in Cloudflare’s global network, dispatching traffic to a Worker is a local function call with no hairpinning or added latency.
More like this
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
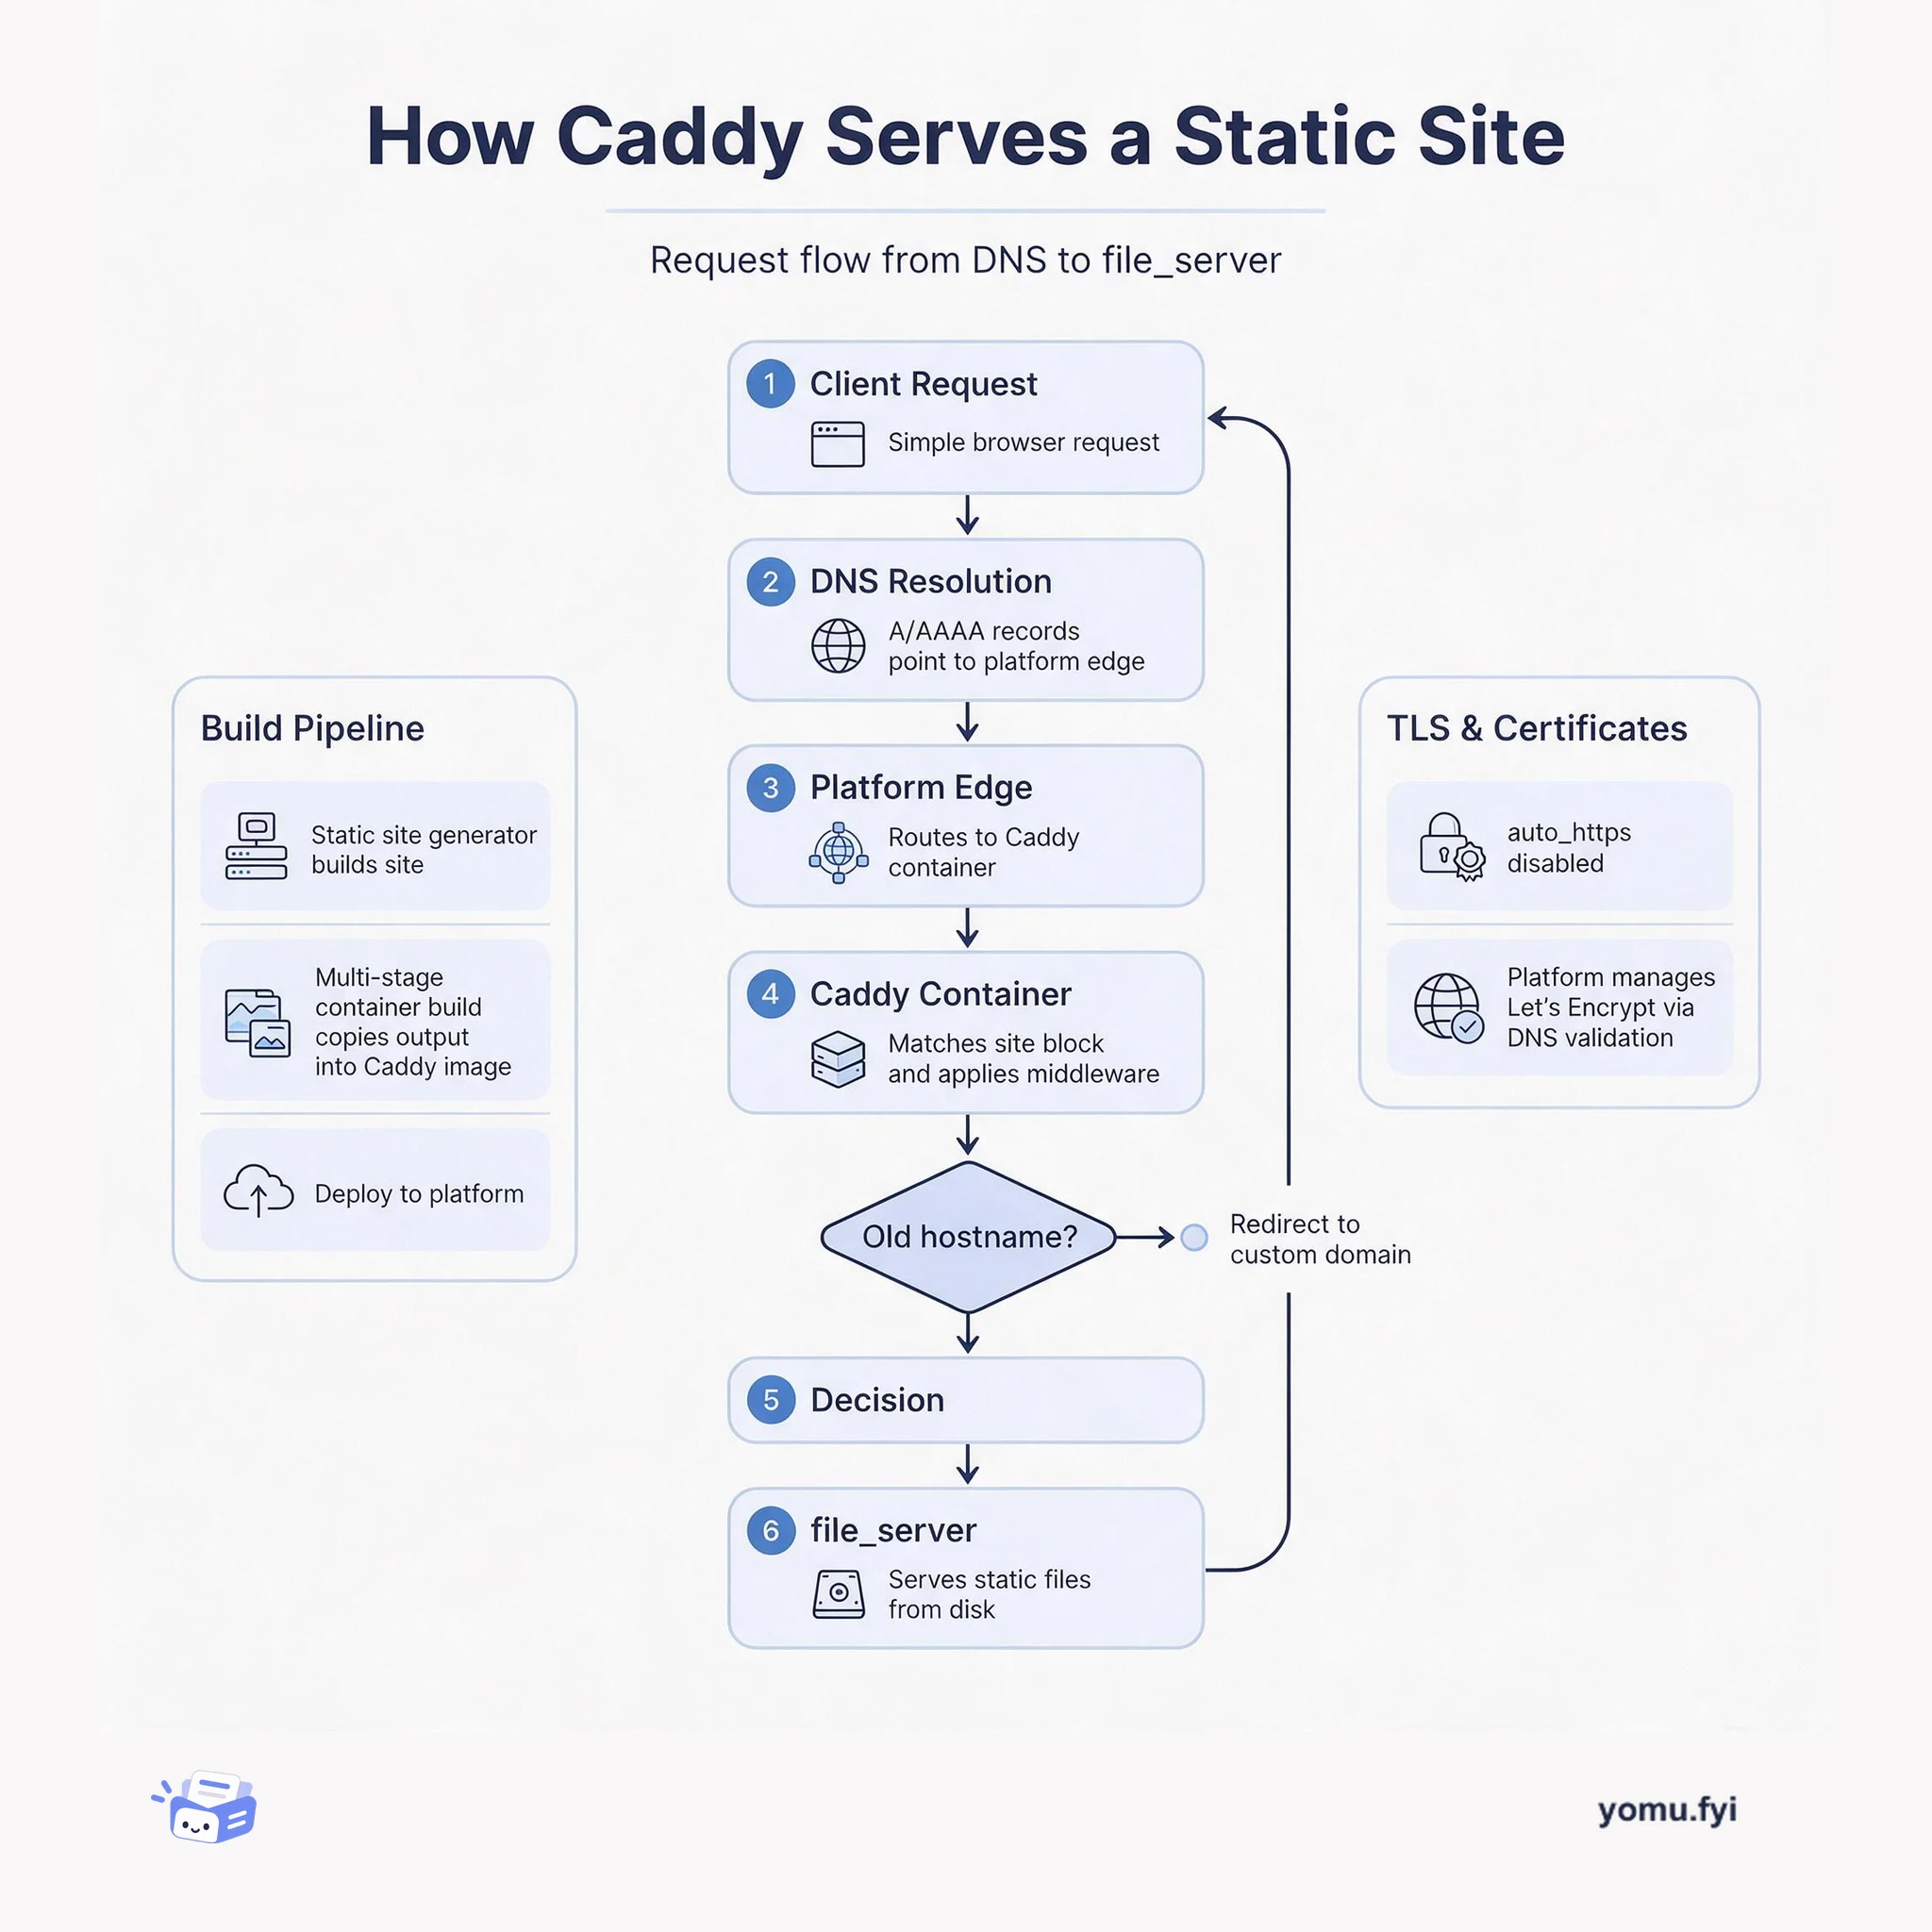
See how Caddy handles a request for a static site, from DNS resolution through container routing to file_server, and how TLS and redirects fit into the flow.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.