Bloom Filters: The Cheap Gate Before the Expensive Question
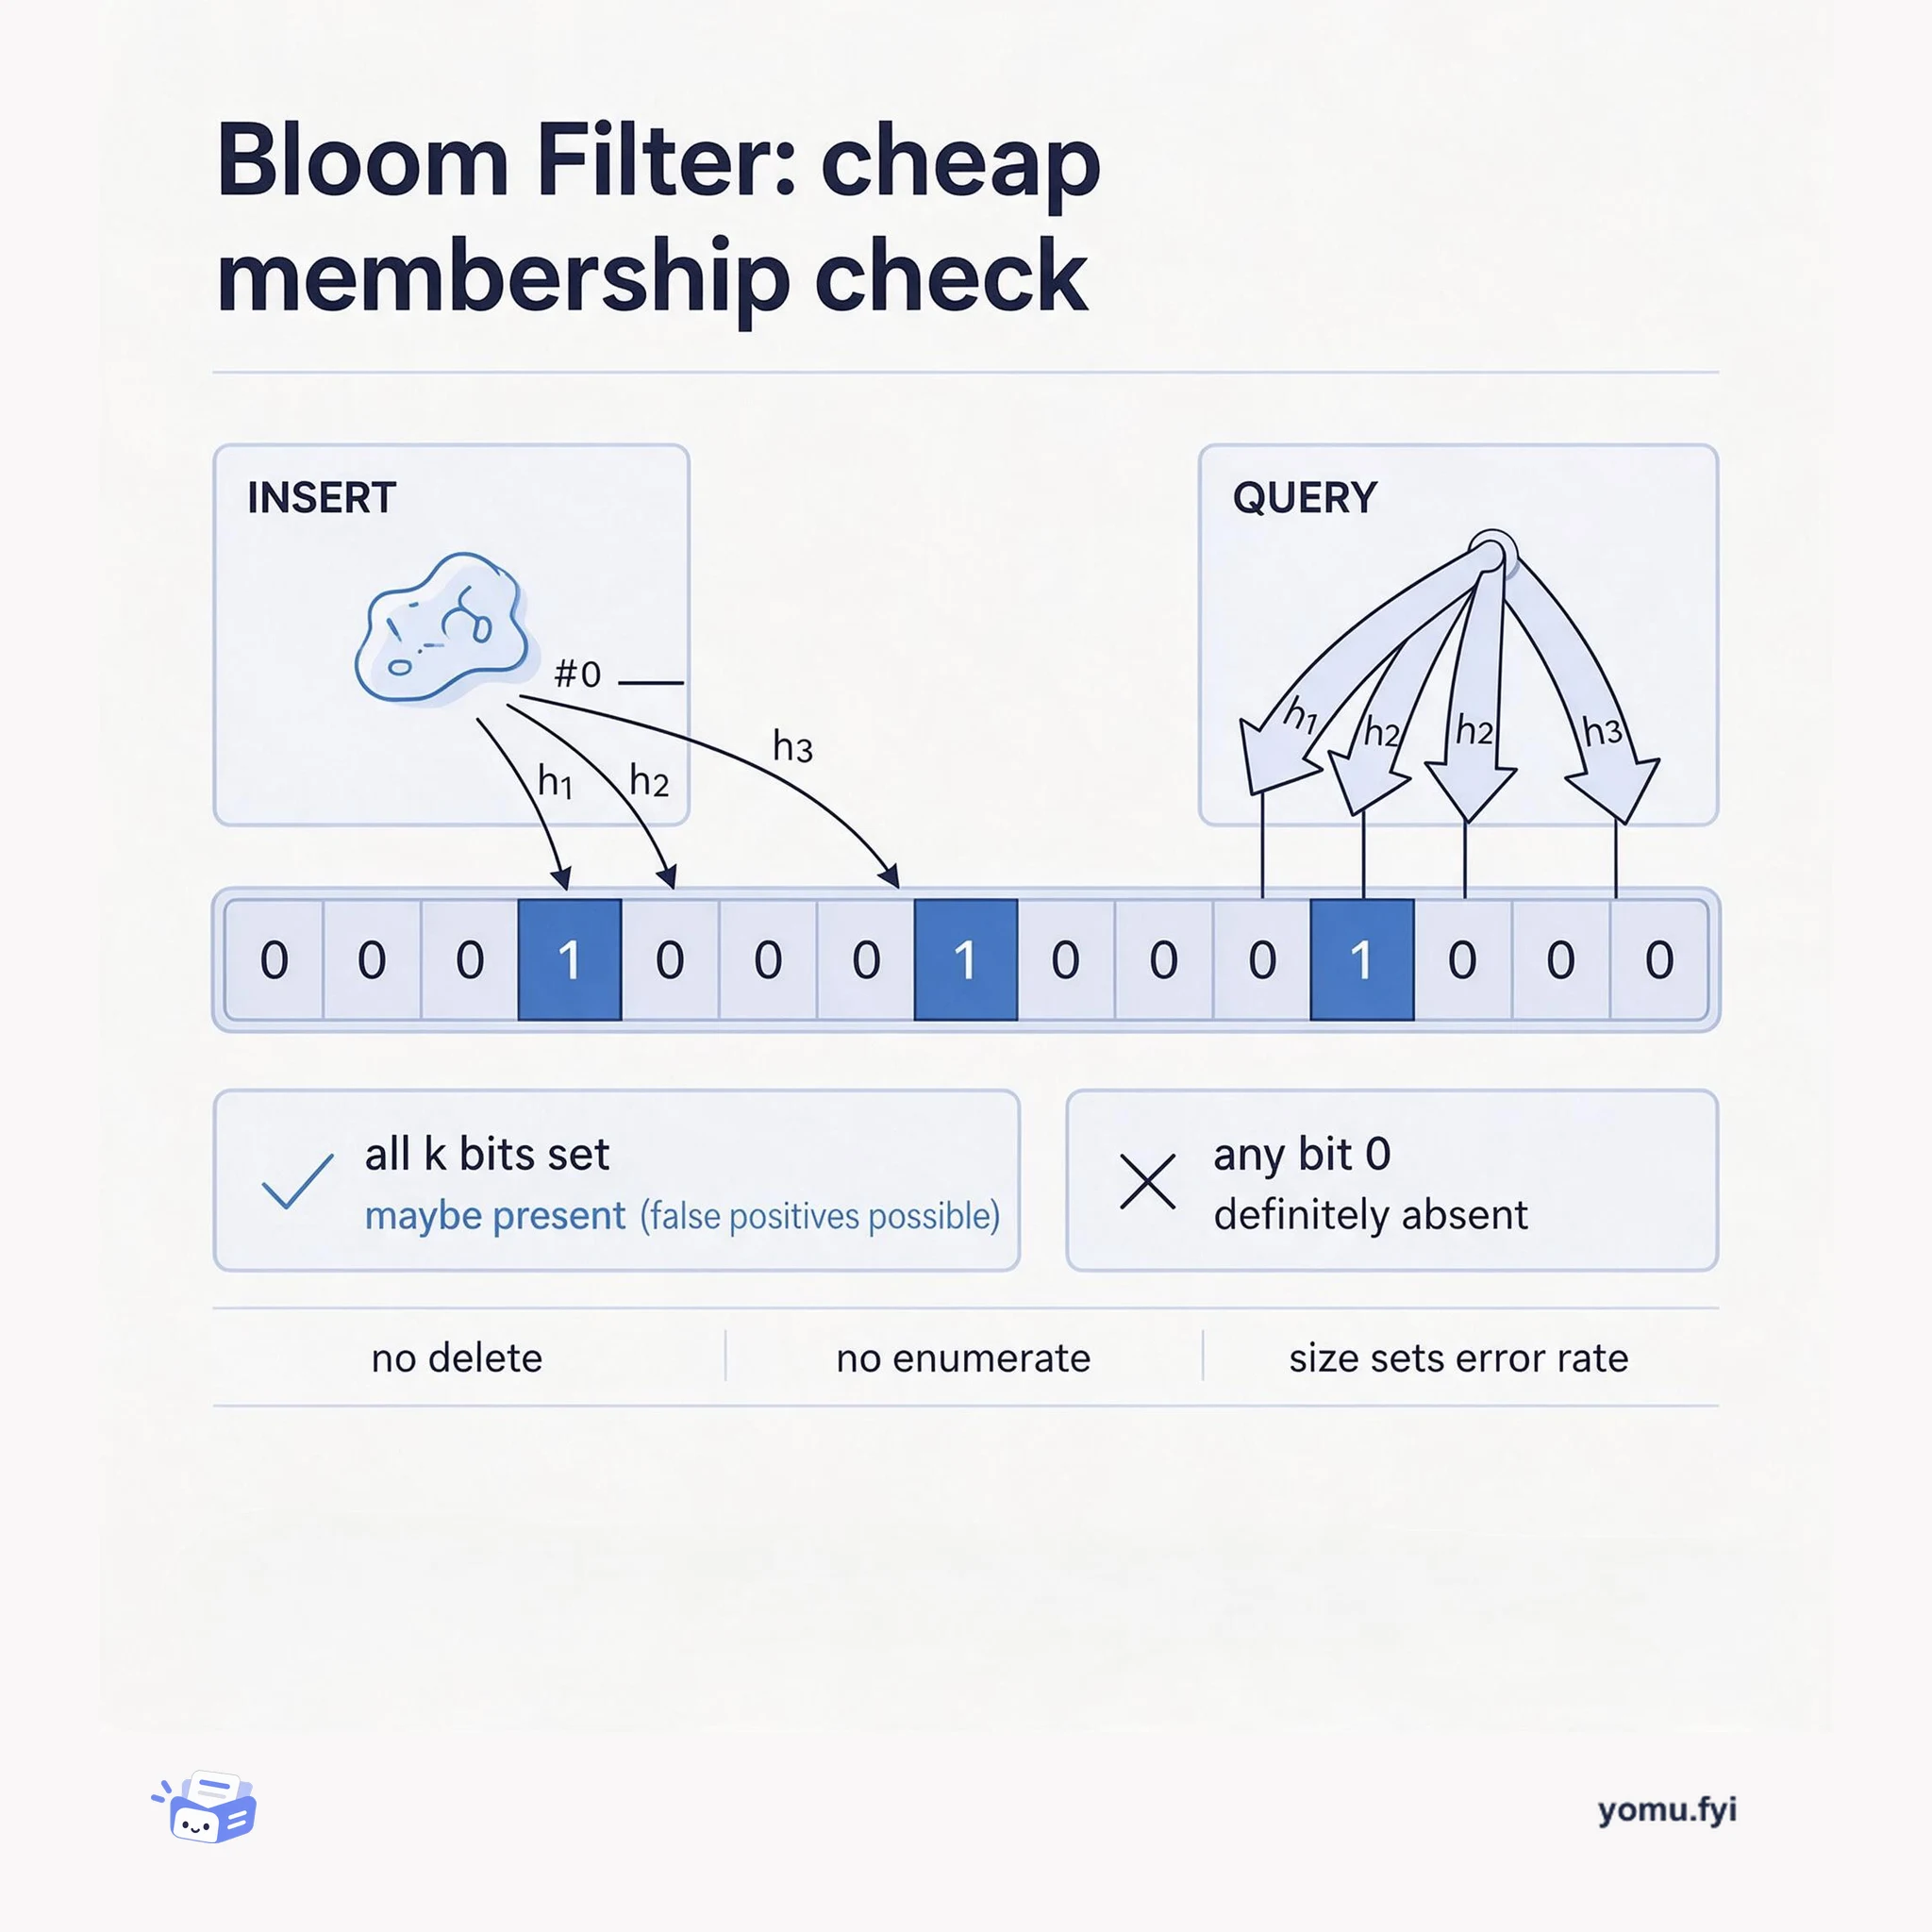
A Bloom filter is a small bit array plus a few hash functions that answers "has this been seen?" with no false negatives and a false-positive rate you choose up front.
 MongoDBExplainer
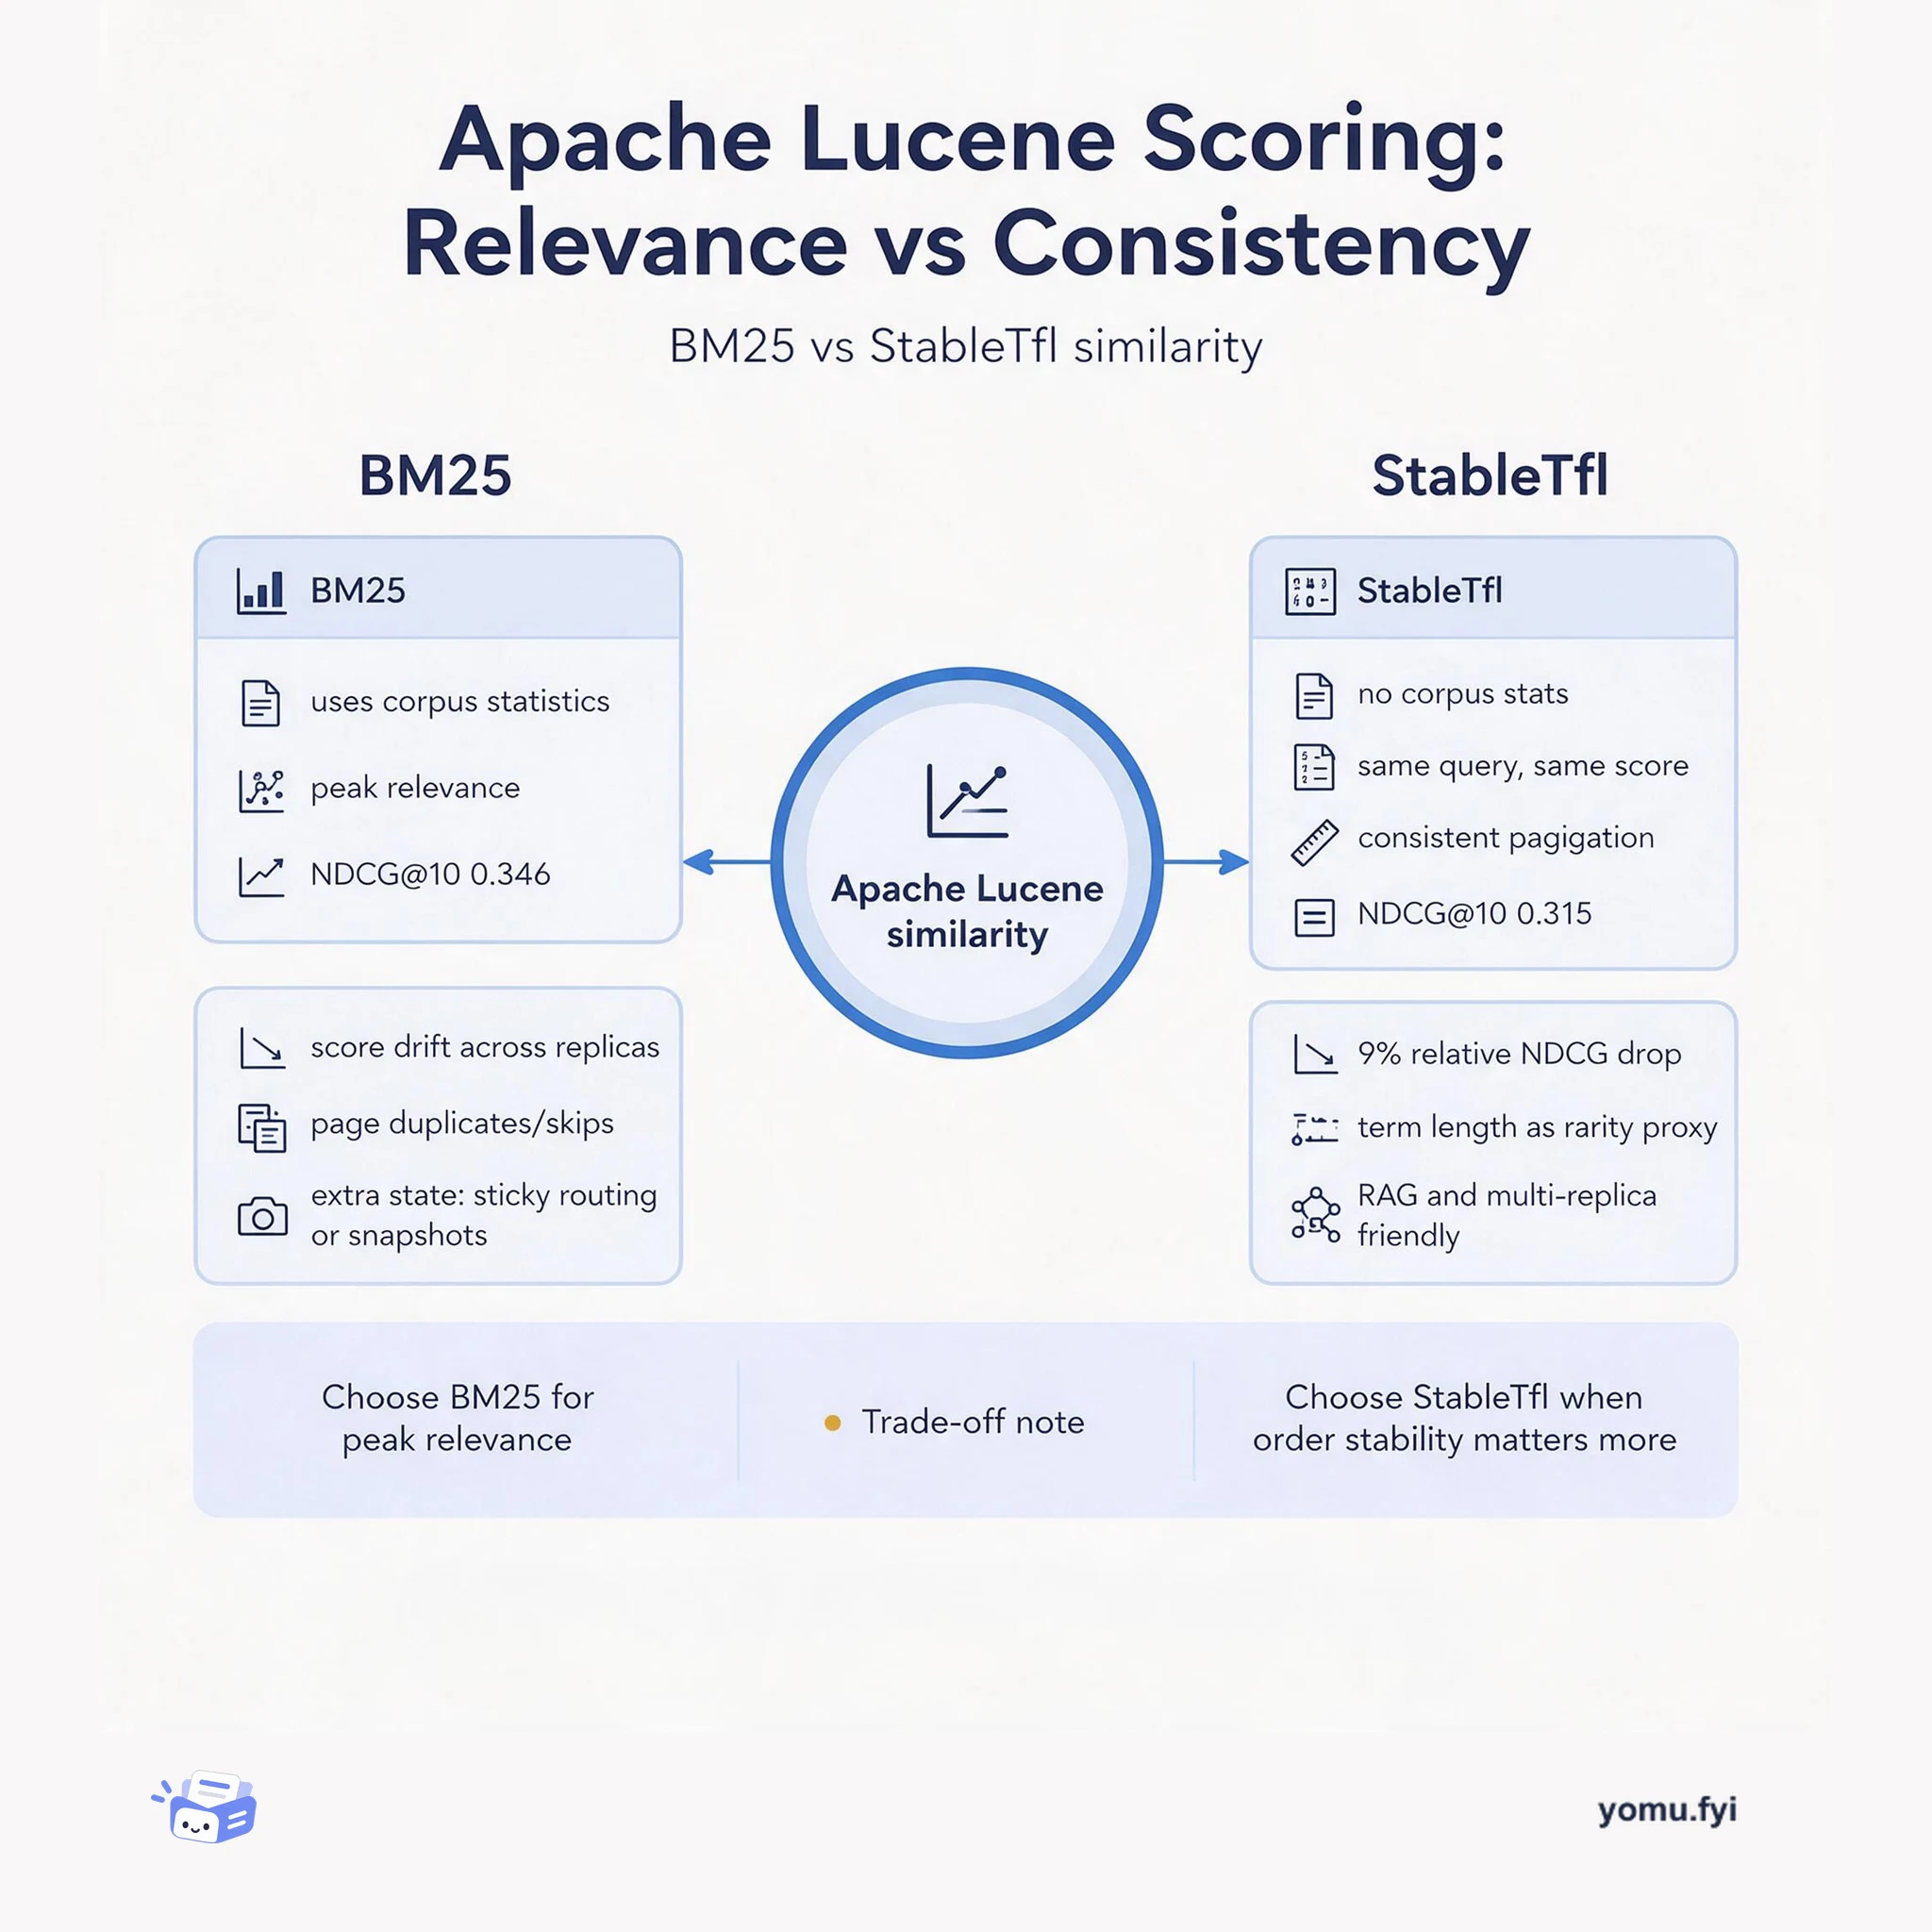
Paginated search in Atlas Search can show duplicate or skipped results across pages because BM25 scores drift between replicas due to changing corpus statistics. The usual workarounds like sticky routing or index snapshots require extra state and are cumbersome. The solution is StableTfl, a scoring function that uses only term frequency and document length, with term length as a proxy for rarity based on Zipf’s brevity law, eliminating corpus statistics and requiring no extra state. StableTfl is contributed to Apache Lucene and is available as a per-field similarity option in Atlas Search. Benchmarks on BEIR show StableTfl achieves 0.315 NDCG@10 compared to BM25’s 0.346, a 9% relative drop, making it suitable for paginated search, RAG pipelines, and multi-replica deployments where consistency matters more than peak relevance.
Paginated search in Atlas Search can produce duplicate or skipped results across pages because BM25 scores depend on corpus statistics that vary between replicas and over time. Standard mitigations like sticky routing or index snapshots require extra state and are cumbersome.
StableTfl scores documents using only term frequency and document length, with term length as a proxy for rarity via a probabilistic model. It precomputes term rarity for all 256 possible document length encodings, making scoring efficient. It is available as a per-field similarity option in Atlas Search and has been contributed to Apache Lucene.
StableTfl eliminates corpus statistics from scoring, using only term frequency and document length, with term length as a proxy for rarity, ensuring consistent scores across replicas.
Benchmarks on BEIR show StableTfl achieves 0.315 NDCG@10 compared to BM25’s 0.346, a 9% relative drop in relevance, but provides deterministic ranking.
StableTfl is suitable for paginated search, RAG pipelines, and multi-replica deployments where consistency is critical, while BM25 remains the default for raw relevance.
It uses term length as a proxy, based on Zipf's brevity law, where longer terms are rarer. It models the probability that a document contains a term of a given length using a probabilistic formula.
On BEIR, StableTfl achieves 0.315 NDCG@10 vs BM25's 0.346, a 9% relative drop, but provides consistent ranking across replicas.
Term rarity is precomputed for all 256 possible document length encodings, so scoring reduces to an array lookup, one multiplication, and one division, avoiding transcendental functions.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A Bloom filter is a small bit array plus a few hash functions that answers "has this been seen?" with no false negatives and a false-positive rate you choose up front.
A comparison of Apache Lucene's BM25 scoring and StableTfl for paginated search: BM25 maximizes relevance, while StableTfl trades a small relevance drop for consistent ranking across replicas and pages.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.