Apache Beam: Unified Batch and Stream Processing
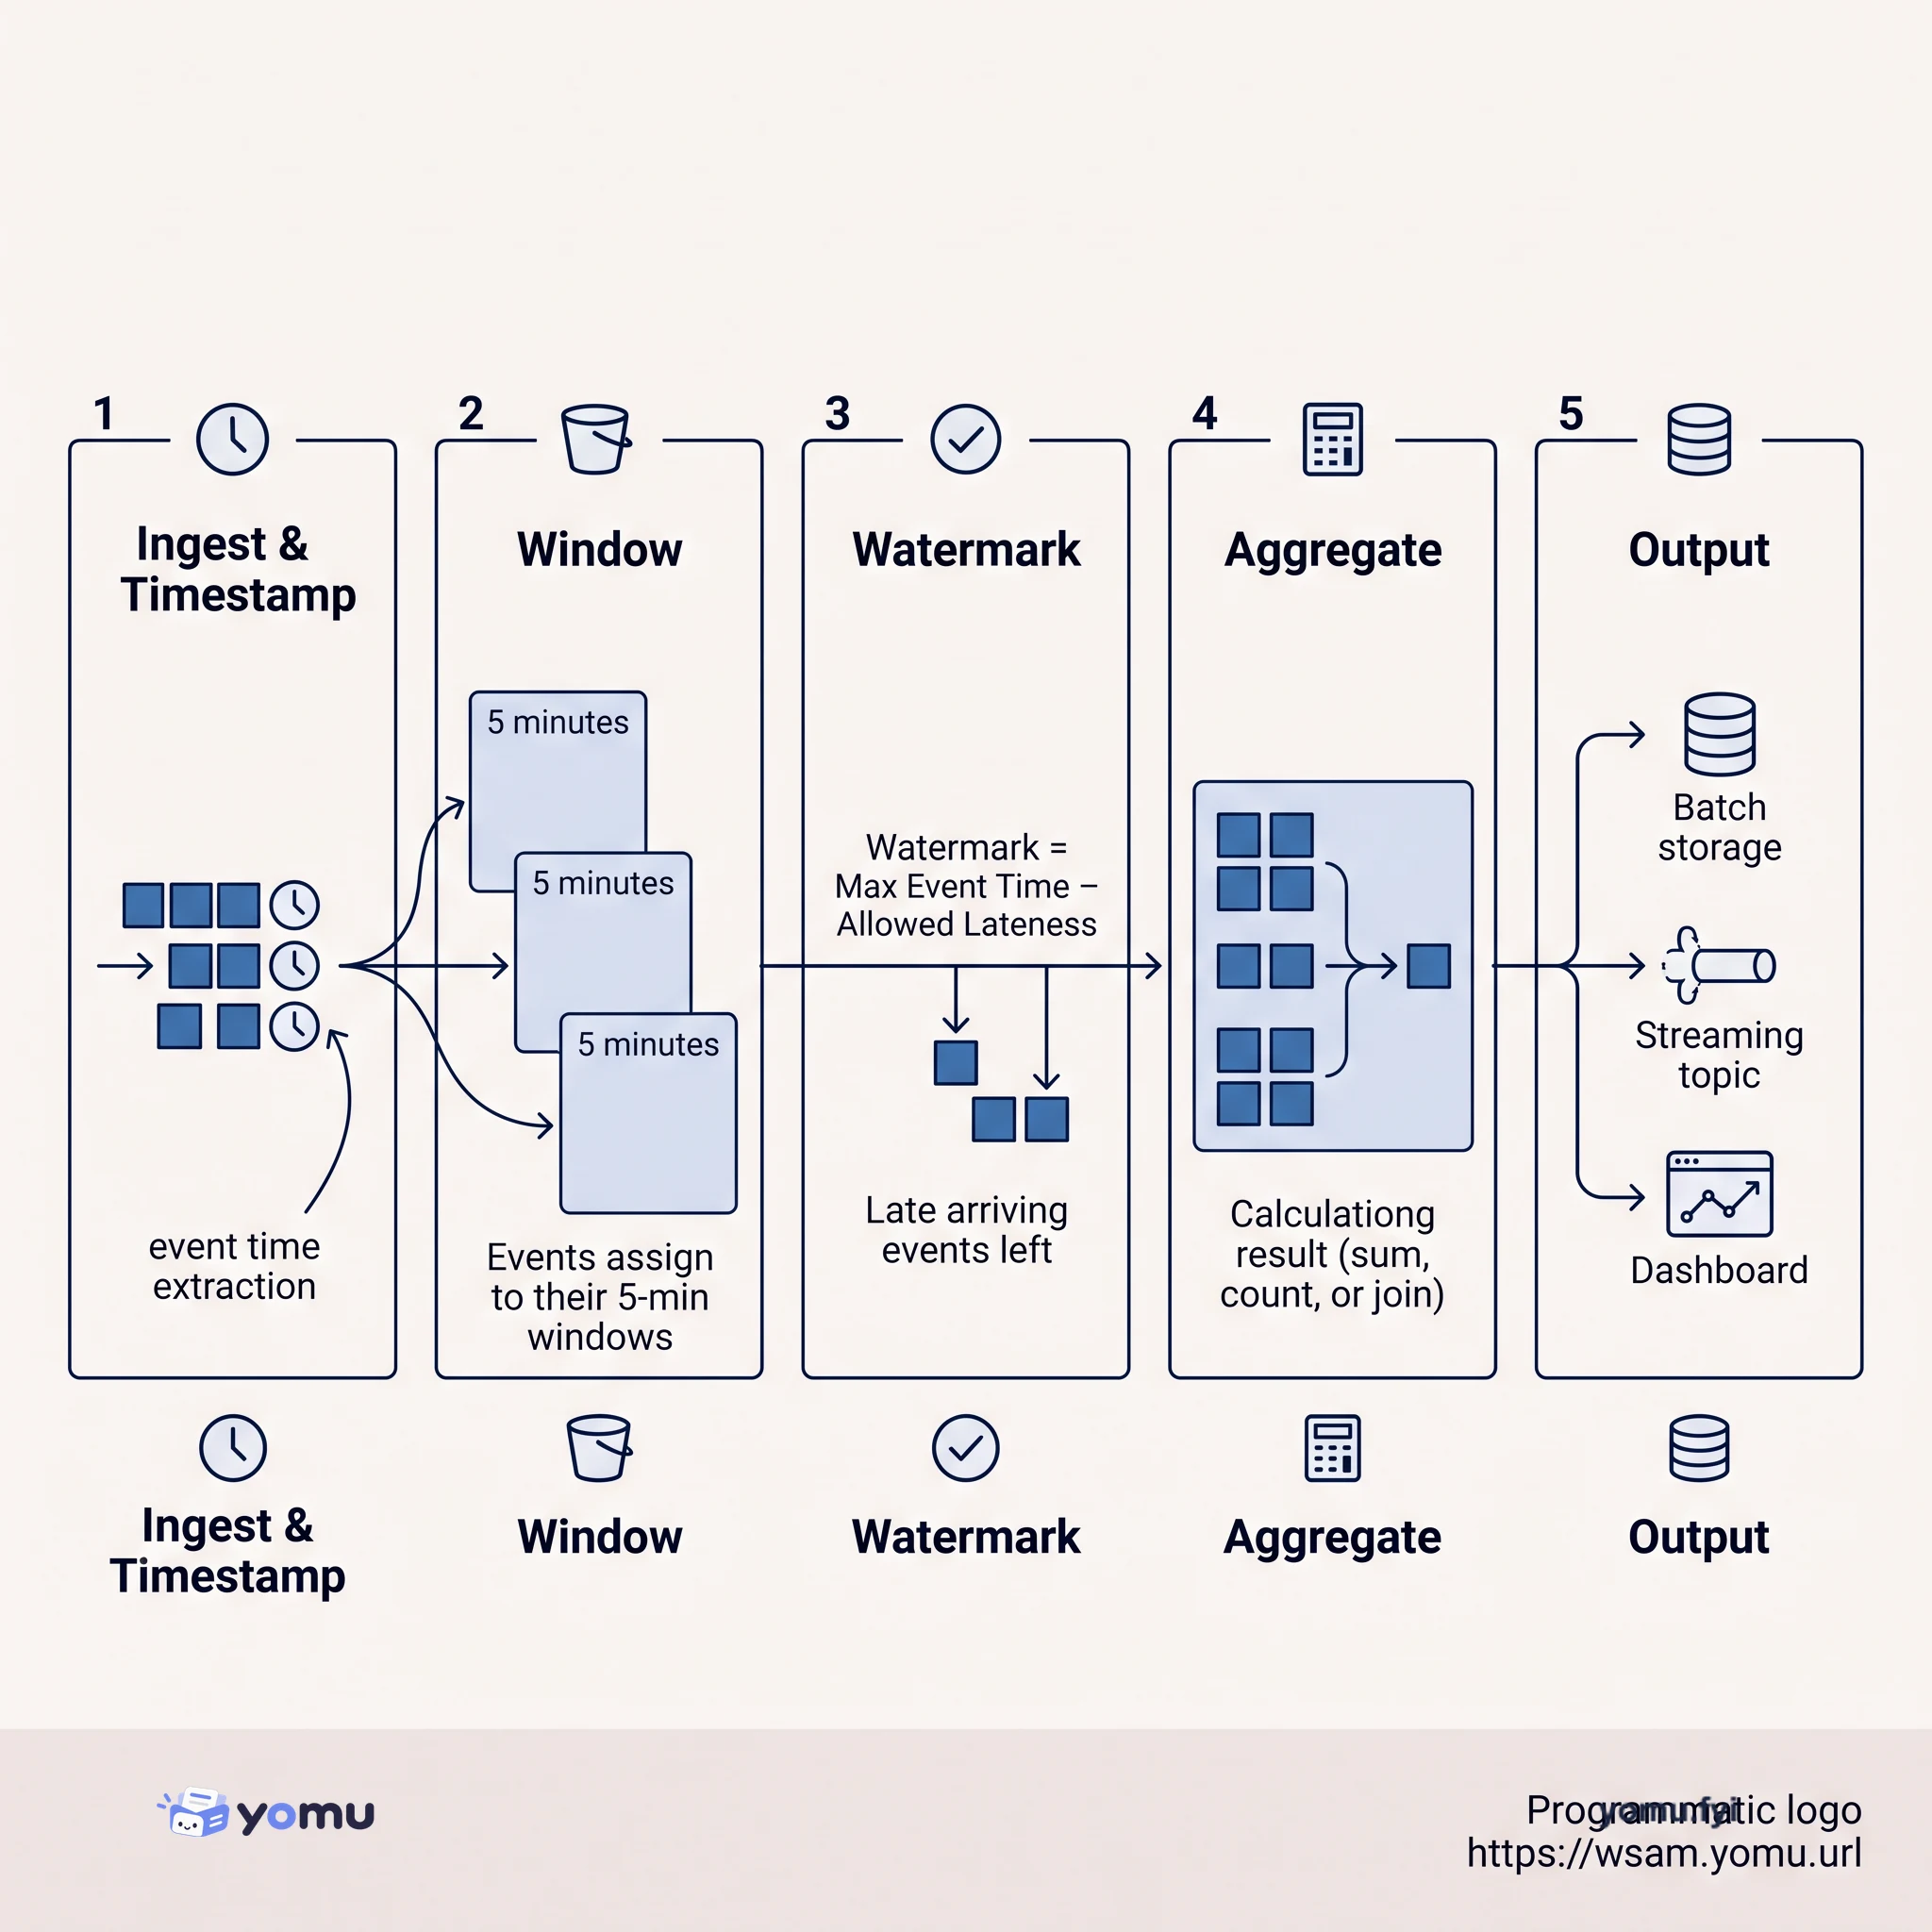
Apache Beam is a unified programming model for batch and stream data processing. Learn how it handles event time, watermarks, and windowing to process data reliably at scale.
 DatabricksDatabricks StaffExplainer
Data transformation turns raw data extracted from source systems into usable, trusted datasets for operational needs, analytics and decision-making. The process addresses inconsistencies, missing values and duplicates through techniques such as cleansing, de-duplication, integration, aggregation, validation and format revision, often mapping data to a target schema during ETL. Performance considerations include compaction, partitioning, file-size tuning, data skipping and pruning, and caching to reduce storage, scanning, processing time and latency. The article also compares on-premises, cloud, open-source, proprietary, no-code, low-code and codable ETL tools, then describes Spark Declarative Pipelines and Lakeflow Jobs on Databricks for quality checks, pipeline development, monitoring and orchestration. A Navy Federal Credit Union proof of concept illustrates a rapid deployment, with a proof of concept completed in a week and a dashboard released days after production deployment.
Organizations collect large volumes of data that can contain inconsistencies, missing values, duplicates, disparate formats or structures, making it difficult to use for trustworthy analysis, integration, reporting and decision-making.
Data is cleansed, mapped, standardized and transformed, often to a specific schema, before being loaded through ETL. The text describes transformation techniques, performance optimizations, ETL tool categories and Databricks capabilities for quality checks, pipeline development, monitoring and orchestration.
In ETL, transformation is the stage where data is cleansed, mapped and converted into a usable resource, often according to a specific schema, before loading.
Partitioning can improve query performance by enabling parallel processing and reducing the amount of data scanned; data skipping and pruning further limit unnecessary reads.
Spark Declarative Pipelines includes Expectations for applying data quality checks to every record passing through a query, while Lakeflow Jobs manages and monitors multitask workflows.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
Apache Beam is a unified programming model for batch and stream data processing. Learn how it handles event time, watermarks, and windowing to process data reliably at scale.
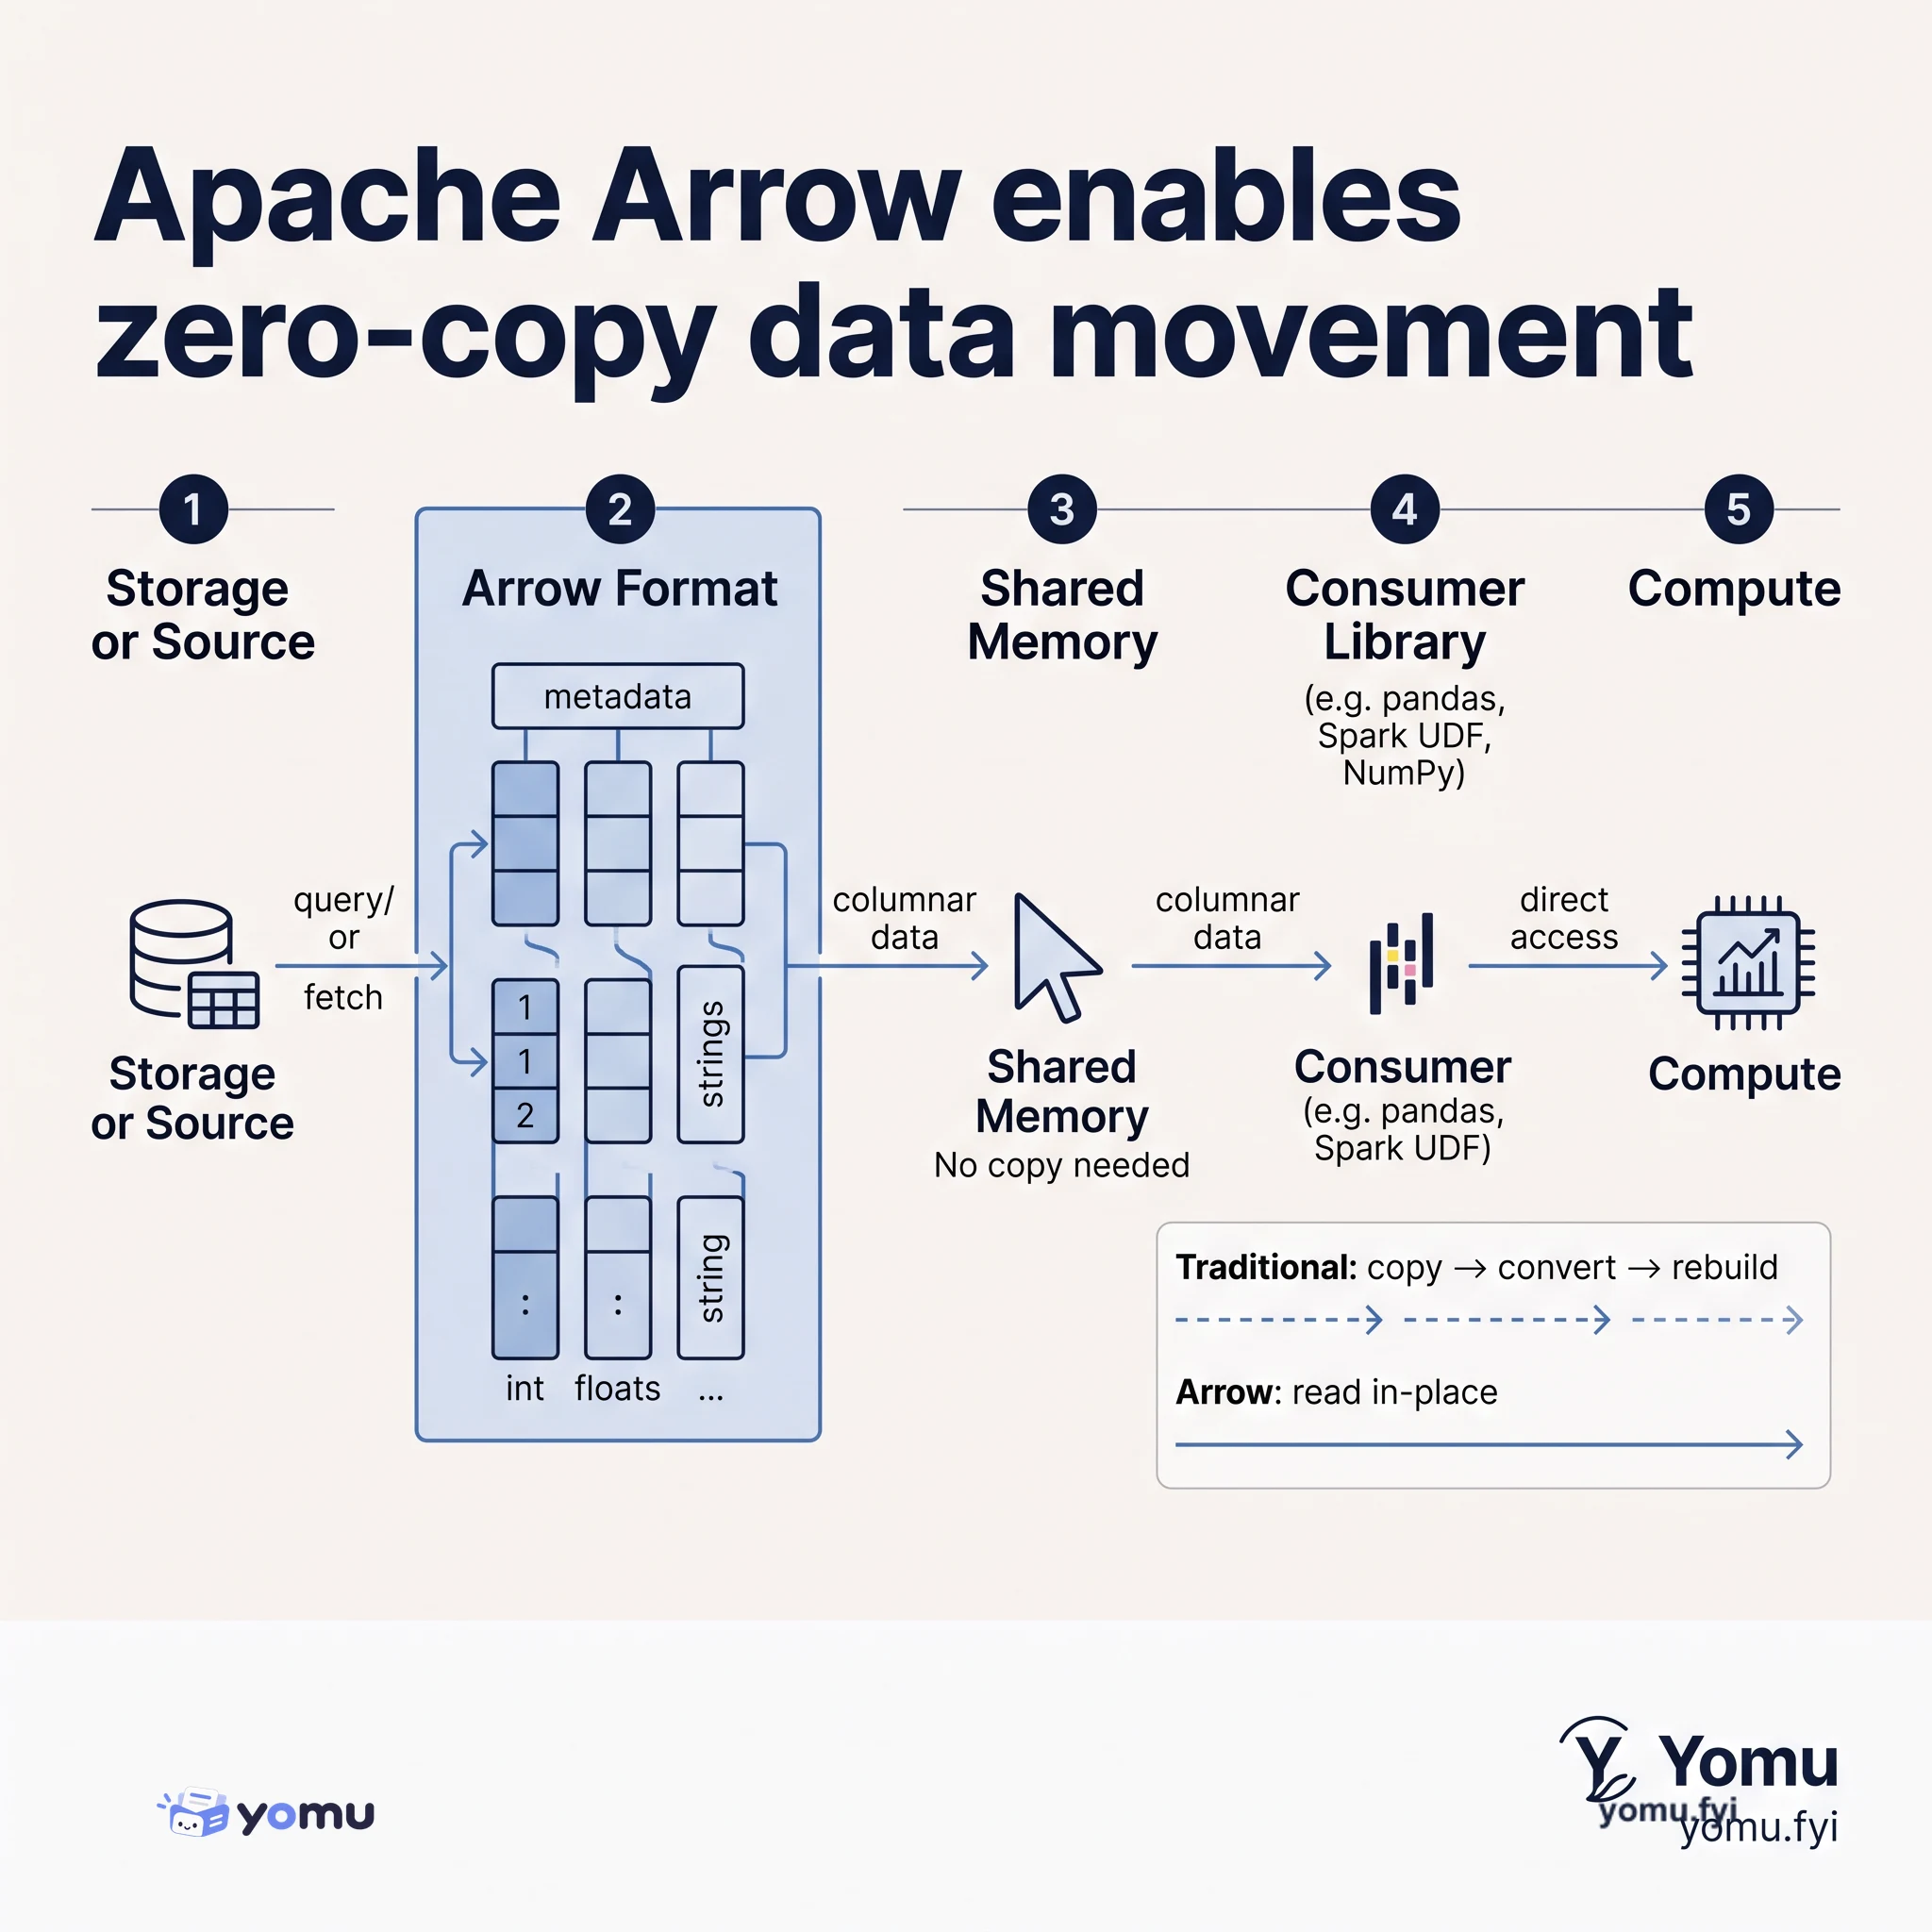
Apache Arrow is a columnar in-memory format that lets databases, analytics engines, and Python libraries share data without serialization overhead or format conversion, cutting memory peaks and speeding up common workflows.
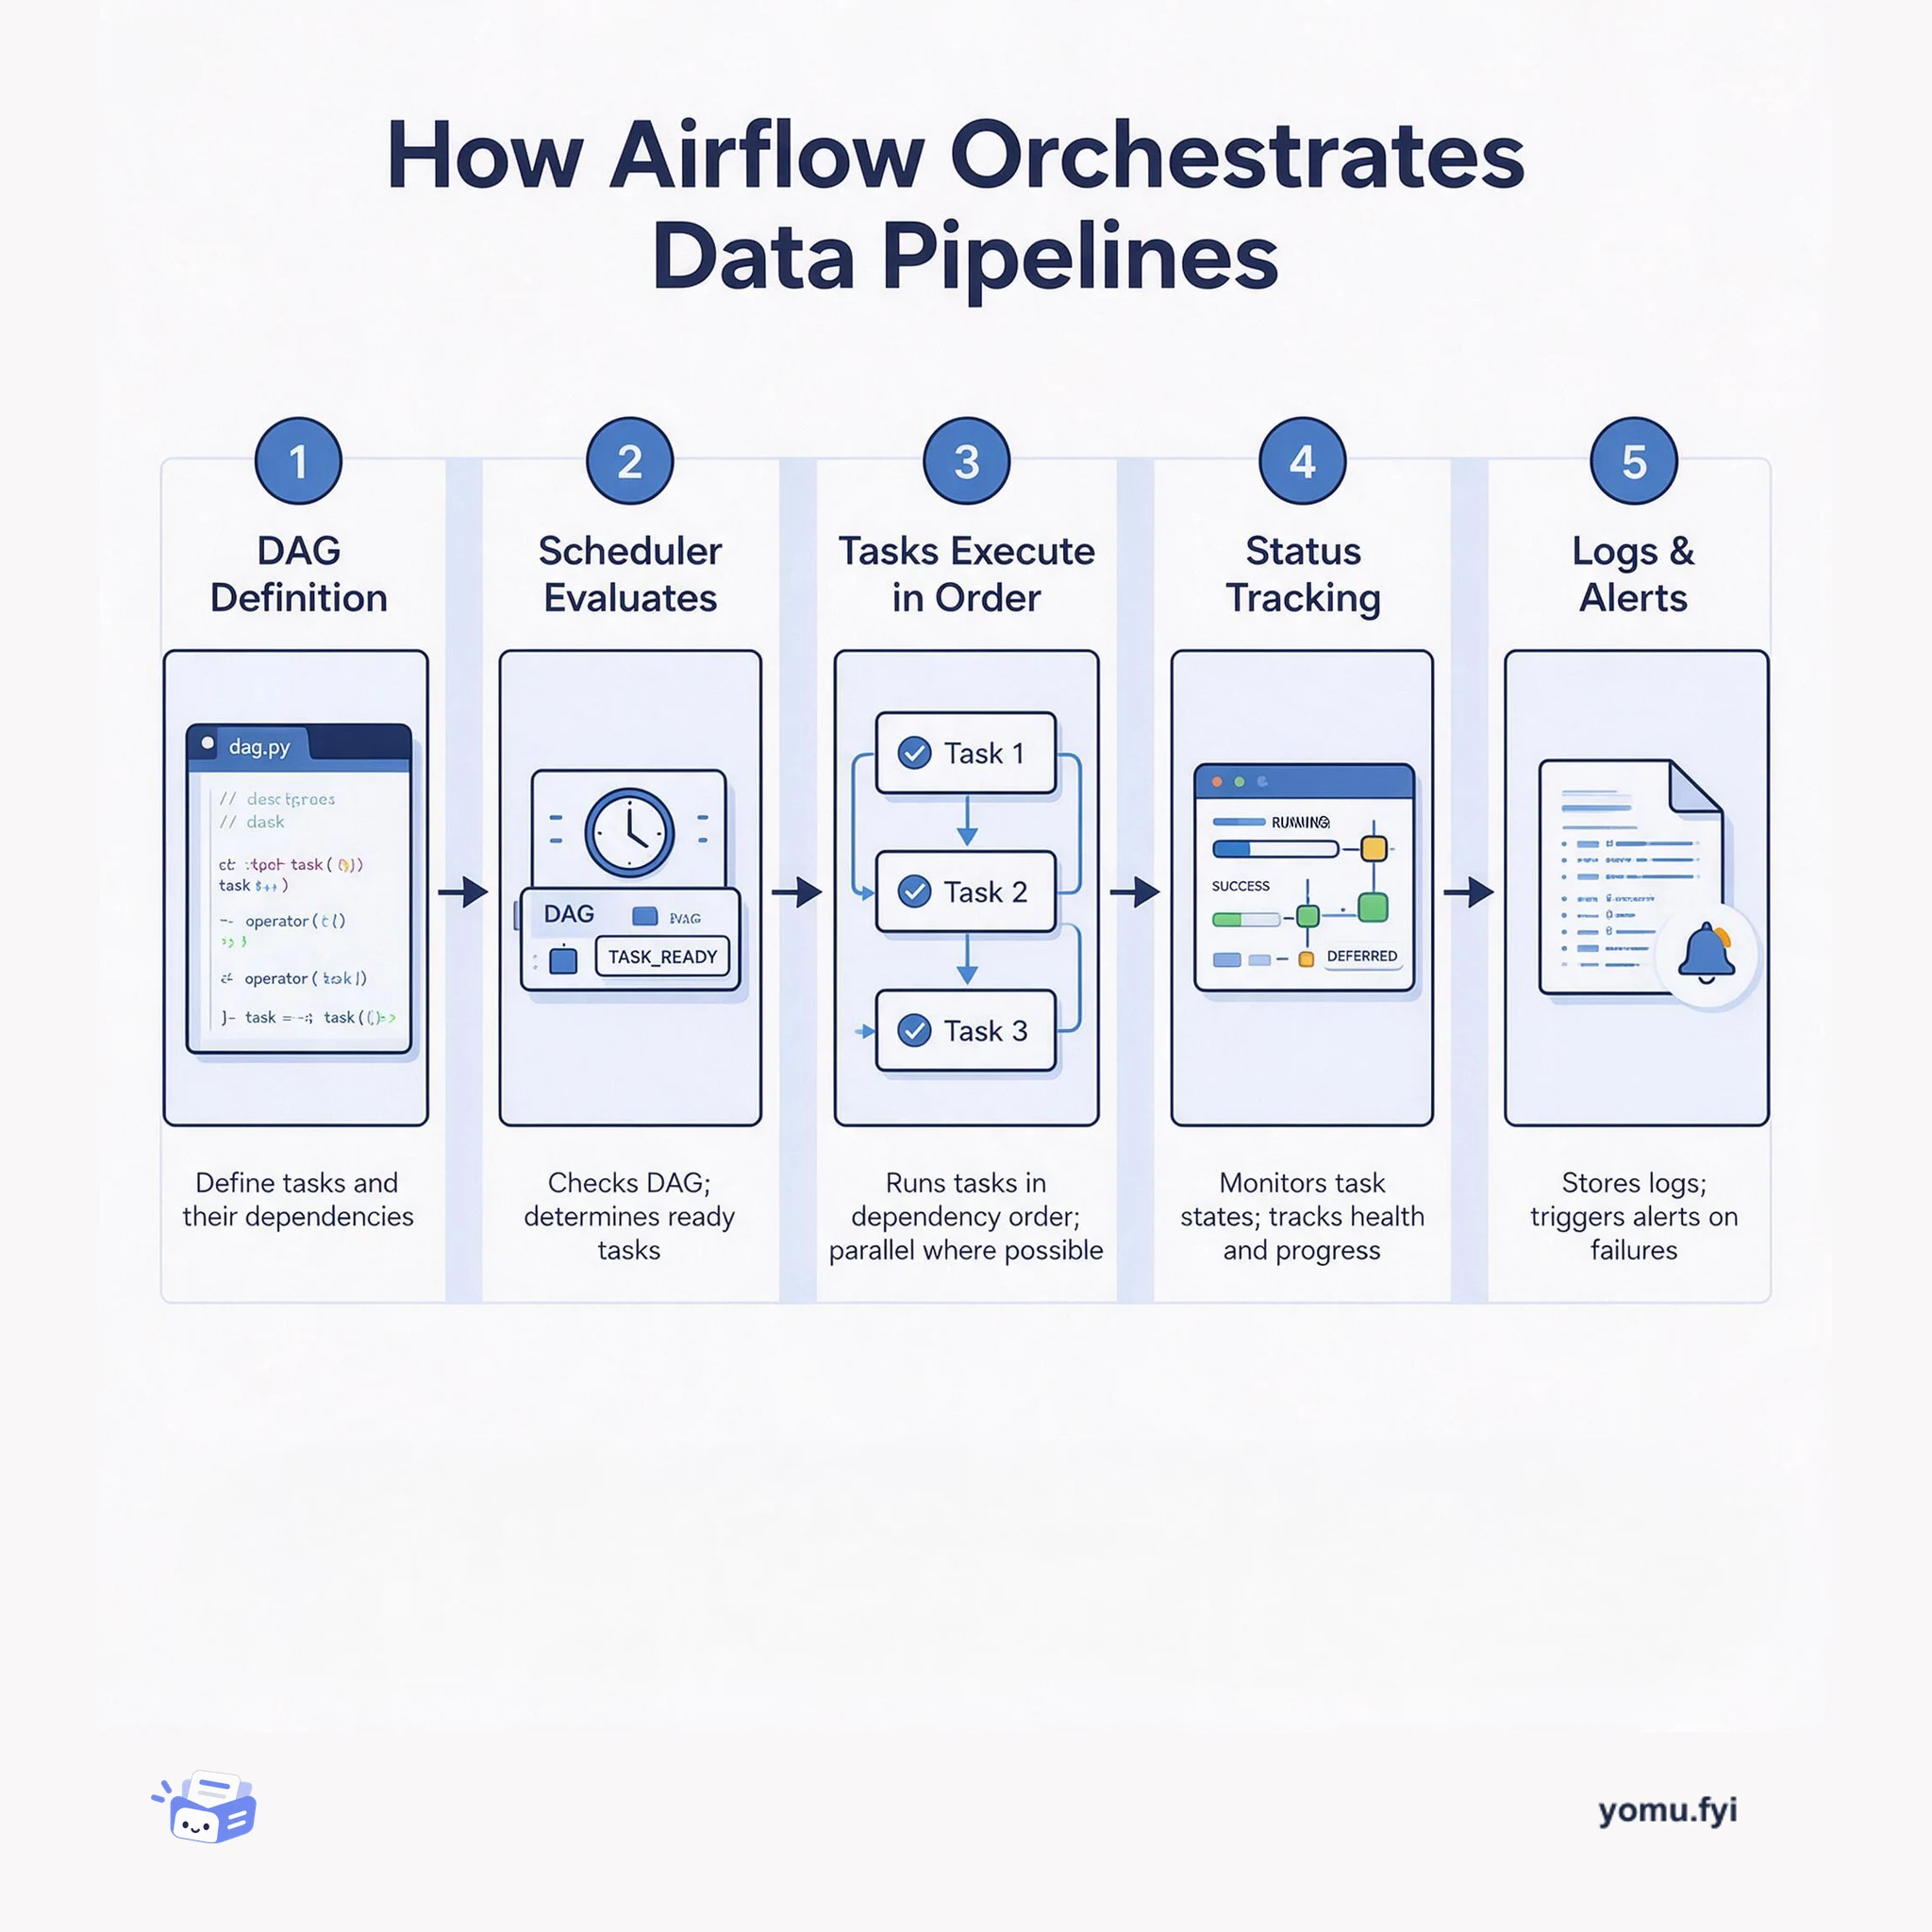
Airflow is a workflow orchestration platform that schedules, monitors, and manages data pipelines by defining tasks as code, executing them in dependency order, and tracking their success or failure.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.