How Apache DataFusion Runs SQL In-Process
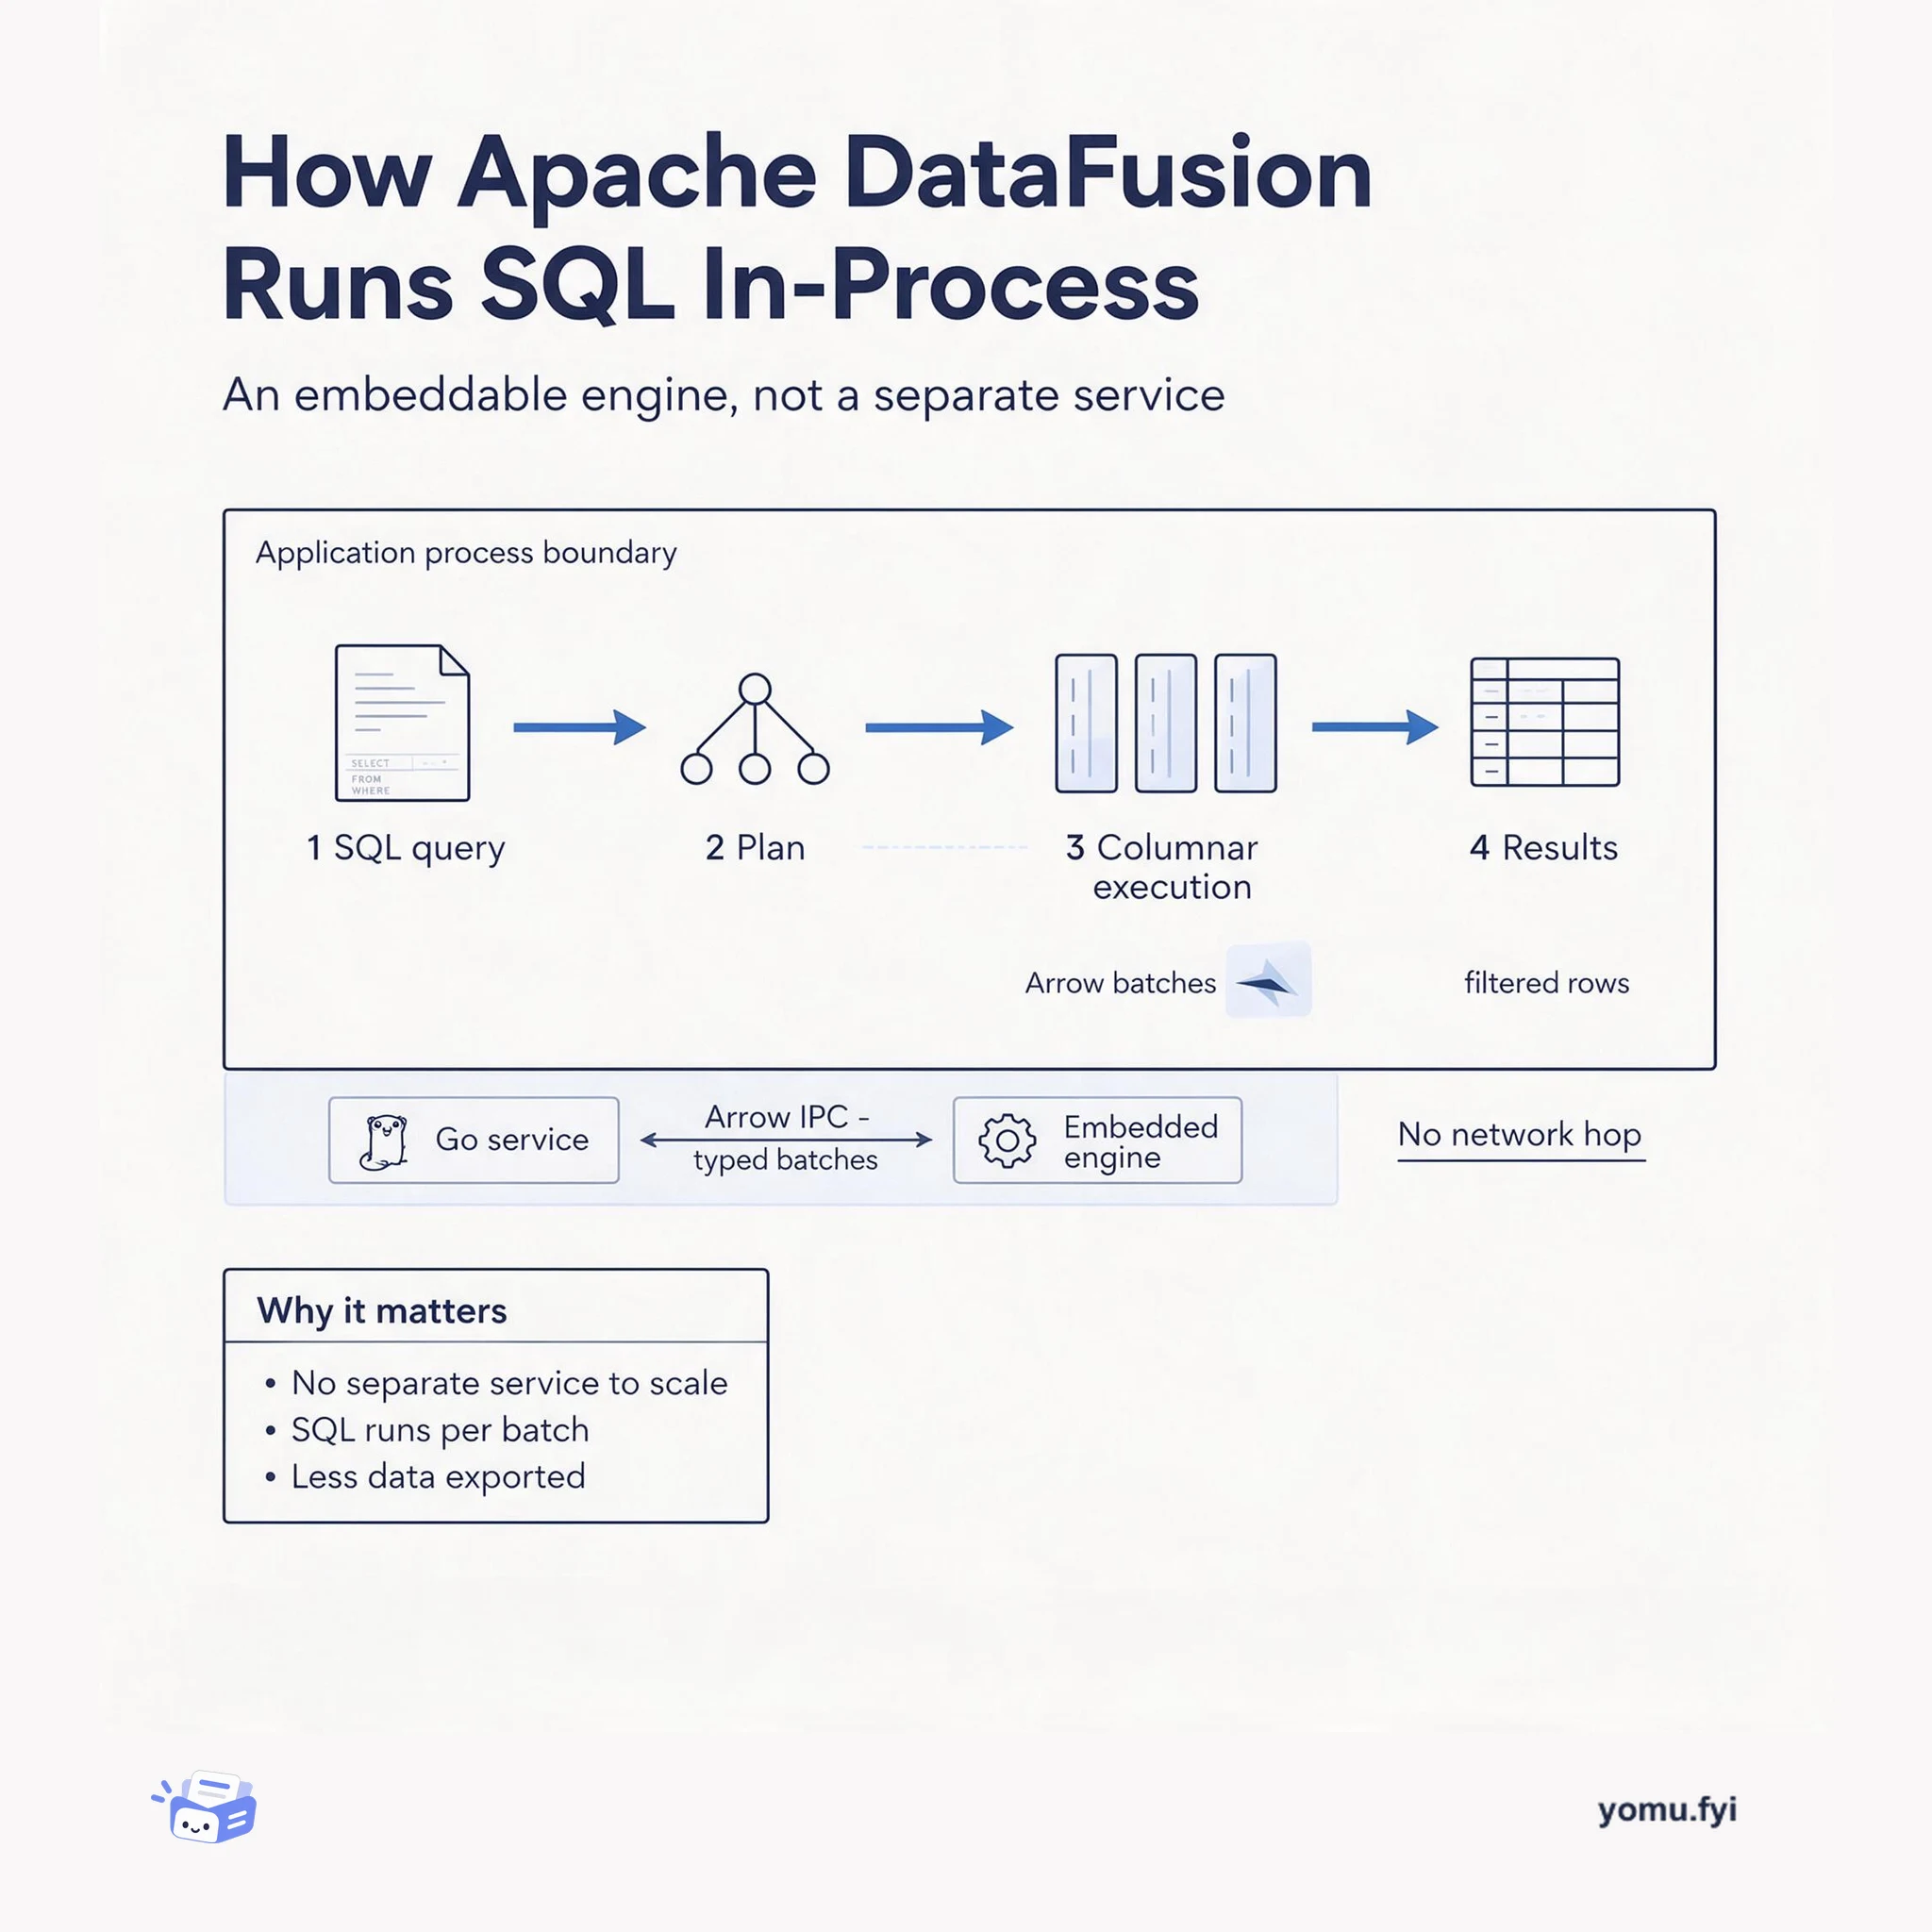
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
Apache Arrow is a columnar in-memory format that lets databases, analytics engines, and Python libraries share data without serialization overhead or format conversion, cutting memory peaks and speeding up common workflows.
Apache Arrow defines a standardized columnar memory layout that multiple systems can read and write directly, eliminating the need to convert between formats like pandas DataFrames, SQL result sets, or NumPy arrays. When a database or compute engine produces Arrow-formatted data, a consumer can access it in-place without copying or rebuilding objects. This shared-memory contract reduces peak memory usage during data movement, speeds up batch processing, and enables zero-copy handoffs between libraries. Engineers choose Arrow when memory constraints, latency, or throughput make serialization and format conversion a bottleneck—particularly in data pipelines, machine learning training, and analytics where large datasets move between storage, compute, and Python.
The posts behind it
 Databricks · · Explainer
Enterprise data products are presented as managed assets that deliver the right data at the right time, with appropriate quality, format, and usability for users and applications. Their value depends on clear ownership, business-aware data product owners, and five trustworthiness characteristics: quality and observability, semantic consistency, privacy, security, and discoverability. The proposed lifecycle runs from inception and design through creation, publication, operation and governance, consumption, and retirement, with data contracts, quality metrics, testing, versioning, access management, and lineage supporting those stages. For Databricks implementations, the guidance recommends Delta Live Tables expectations and constraints, staged development, testing and production environments, automated monitoring, and Unity Catalog for discovery, governance, lineage, auditing, and access controls.
Databricks · · ExplainerData transformation turns raw data extracted from source systems into usable, trusted datasets for operational needs, analytics and decision-making. The process addresses inconsistencies, missing values and duplicates through techniques such as cleansing, de-duplication, integration, aggregation, validation and format revision, often mapping data to a target schema during ETL. Performance considerations include compaction, partitioning, file-size tuning, data skipping and pruning, and caching to reduce storage, scanning, processing time and latency. The article also compares on-premises, cloud, open-source, proprietary, no-code, low-code and codable ETL tools, then describes Spark Declarative Pipelines and Lakeflow Jobs on Databricks for quality checks, pipeline development, monitoring and orchestration. A Navy Federal Credit Union proof of concept illustrates a rapid deployment, with a proof of concept completed in a week and a dashboard released days after production deployment.
 Ramp · · Problem & solution
An ML training run was exhausting worker memory before training could start because a cold Snowflake fetch peaked at 88.8 GiB RSS, versus 17.6 GiB when loading local Parquet. The shared Snowflake-to-pandas path created Python objects and SQLAlchemy Row proxies before pandas built the DataFrame, with temporary representations requiring roughly three times the final DataFrame size at peak. An Apache Arrow path for supported reads reduced median peak process RSS growth by 60–79% across three query shapes, while peak Python allocations fell by 69–87%. The narrow and wide tests also ran faster, but aggregate timing was mixed, so elapsed time was not the headline claim. Existing jobs adopted the default without query rewrites, with normalization preserving the pandas contract and SQLAlchemy retained for unsupported reads; in one workflow, lower fetch peaks doubled the training-data window on the same cluster size.
Databricks · · ExplainerApache Spark’s Pandas UDFs improve Python UDF throughput through Arrow-based serialization and batching, but Pandas/Arrow conversion can add copies, limit zero-copy behavior, and weaken support for complex datatypes. Native Arrow UDFs, introduced in Databricks Runtime 18.0, operate directly on Arrow data without converting inputs to Pandas or NumPy objects, preserving columnar layout and enabling vectorized processing through Arrow’s compute and memory model. The new @arrow_udf decorator supports scalar, aggregate, and table functions, while type-hinted @udf definitions, mapInArrow, and applyInArrow extend the interface to DataFrame and grouped operations; iterator-based modes can amortize initialization costs. In a comparison, an Arrow UDF ran about 10% faster than a Pandas UDF and used about 40% less memory, with better complex-datatype support.
More like this
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
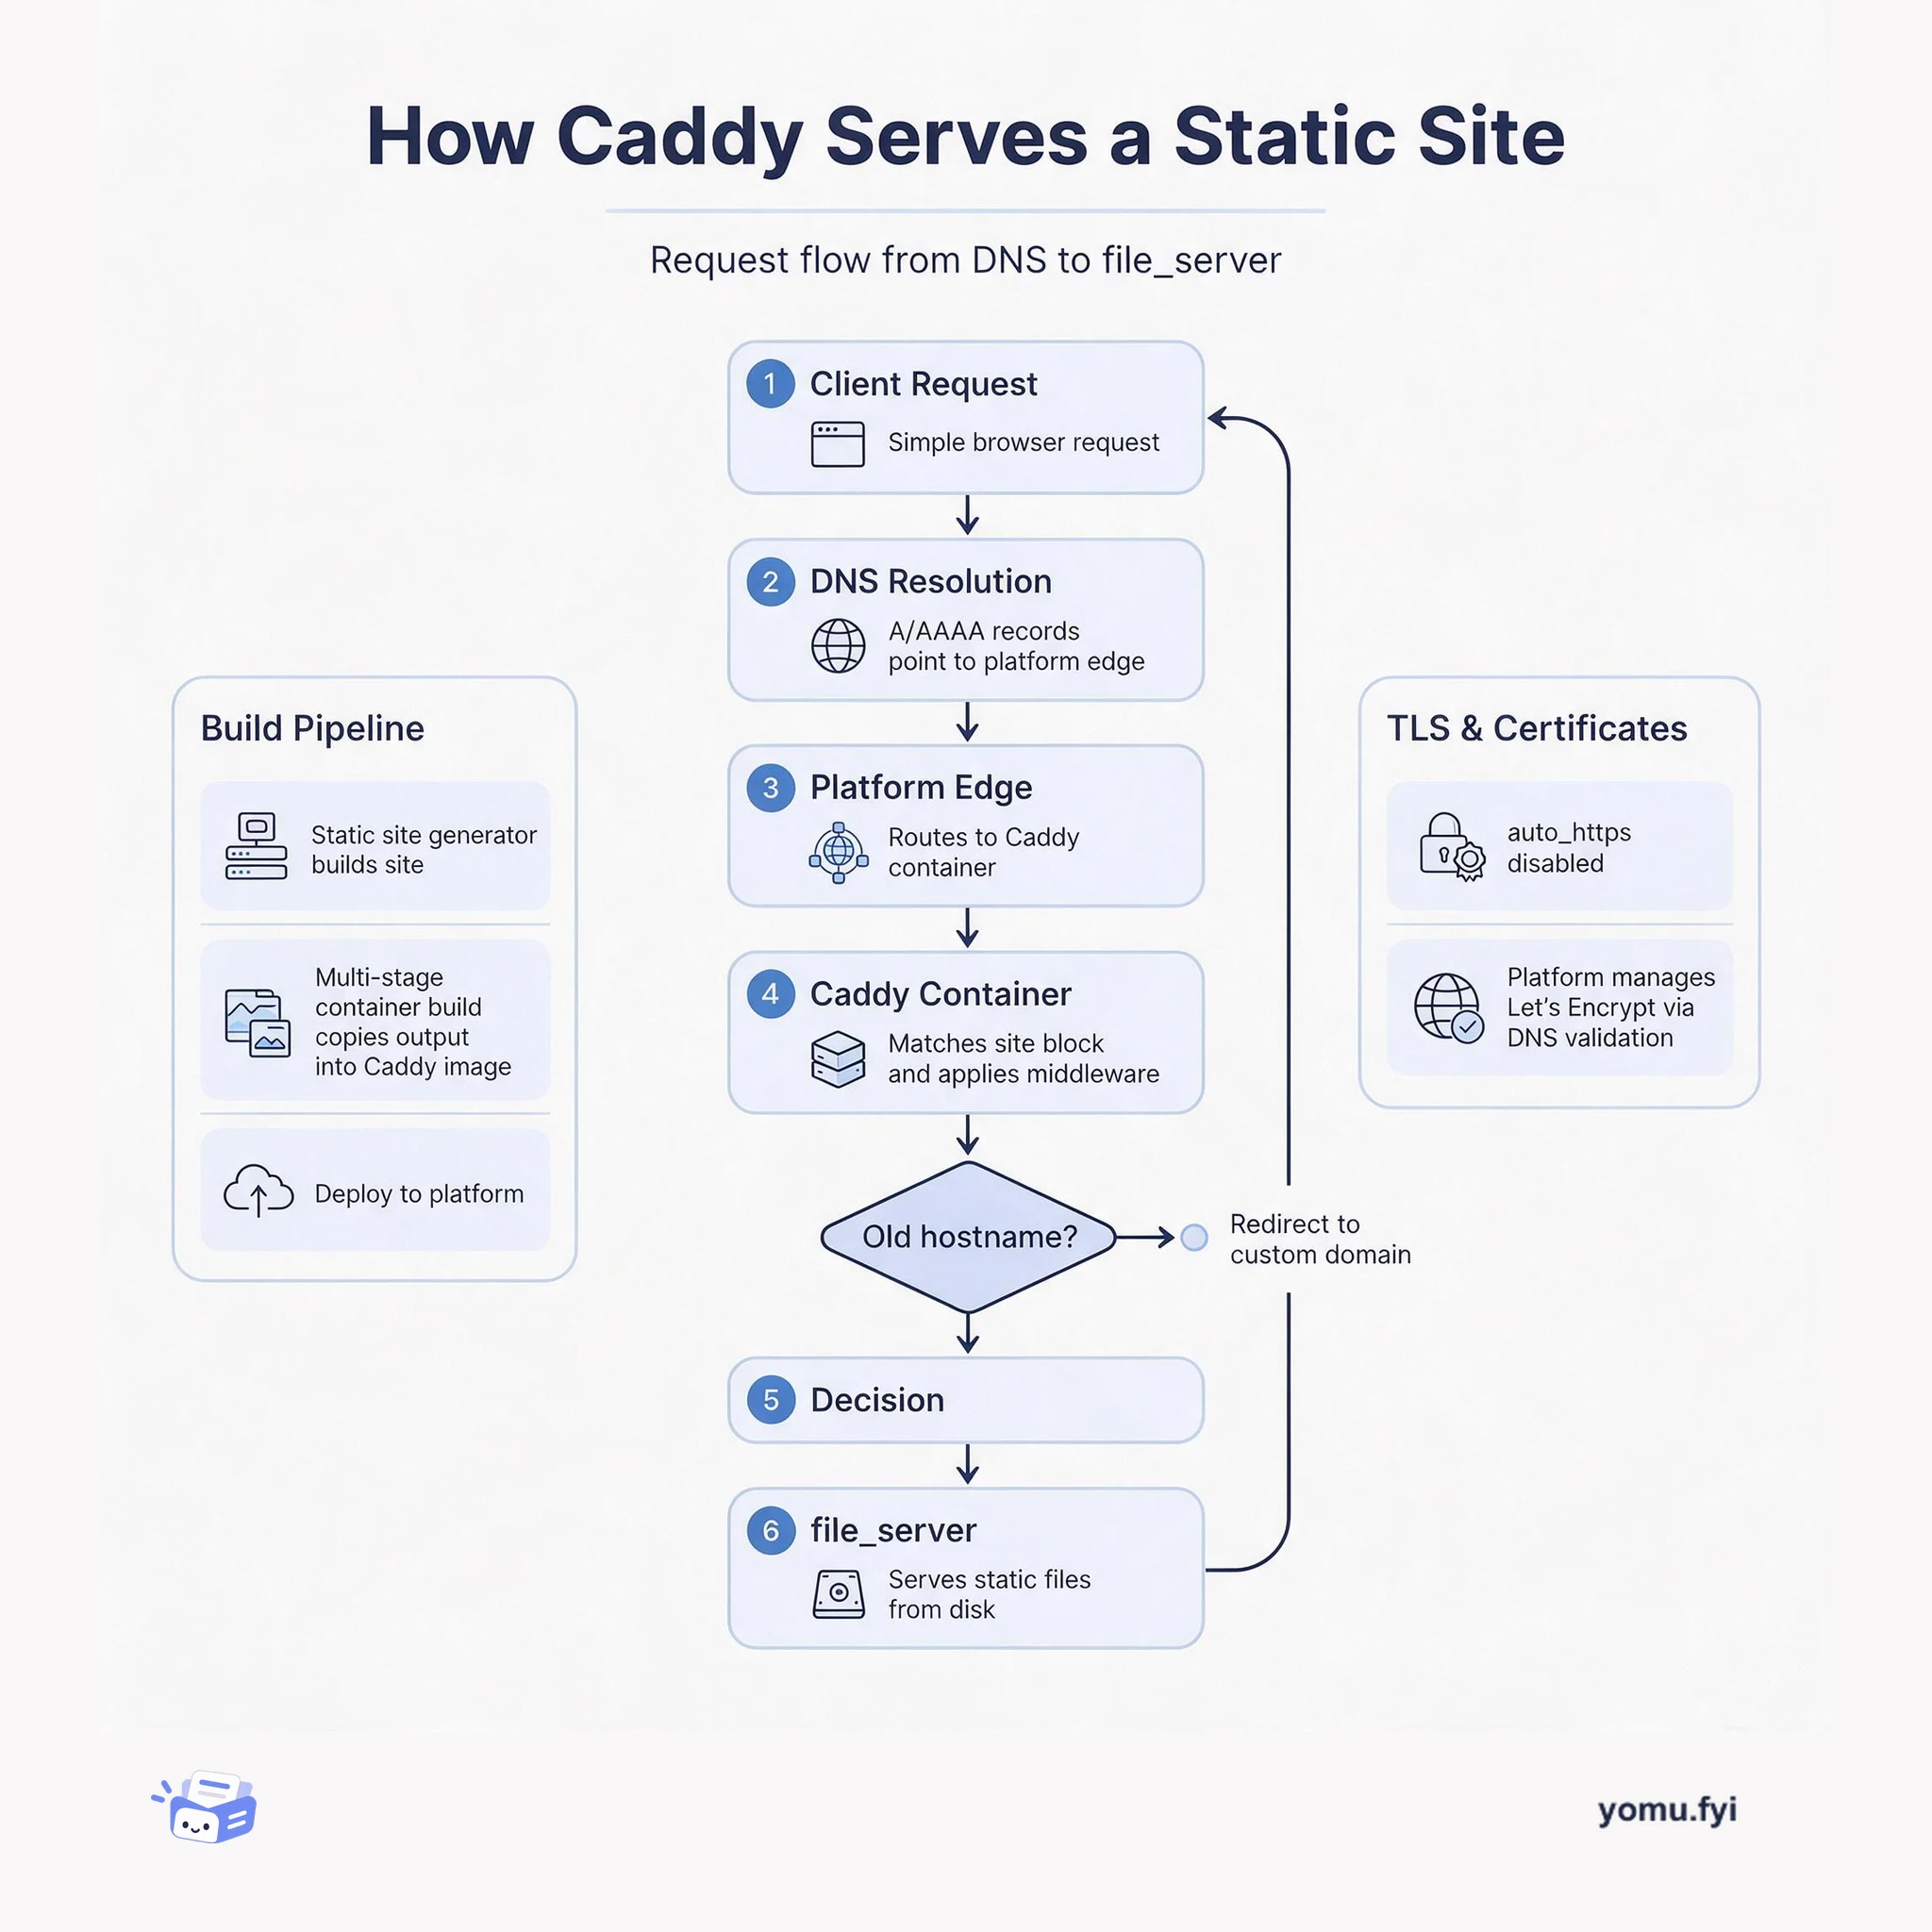
See how Caddy handles a request for a static site, from DNS resolution through container routing to file_server, and how TLS and redirects fit into the flow.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.