How MaaS Governance Wraps a Model Endpoint on AKS
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
 Stack OverflowSancharini PandaExplainer
The gap between sandbox and production environments is structural and inevitable because they change on different schedules with different triggers. Infrastructure divergence rarely affects what integration tests catch, but behavioral contract drift—when simulated upstream responses no longer match real ones—causes tests to pass while production fails. The most effective teams connect simulation updates to upstream deployment events rather than to test failures, using observation-based tools like Keploy that capture real HTTP traffic to keep simulations current. Full production parity is not the goal; targeted accuracy for the specific behavioral contracts that integration tests validate is sufficient to catch the failures that matter most in distributed systems. The sandbox covers what it can, production reveals what it cannot, and the maintenance work is keeping the sandbox’s coverage accurate within its boundary, not expanding it to match production exactly.
The post addresses the persistent gap between sandbox and production environments in software testing, arguing that full parity is unnecessary and that teams should focus on keeping behavioral contract simulations accurate by tying updates to upstream deployment events.
Connect simulation updates to upstream deployment events rather than test failures. Use observation-based tools that capture real HTTP traffic (e.g., Keploy) to generate simulations from observed reality. Focus on maintaining accurate behavioral contracts for the specific integrations being tested, not on full infrastructure parity.
Behavioral contract drift—when simulated upstream responses no longer match real ones—causes tests to pass while production fails, and it goes unnoticed until a production incident because the suite looks trustworthy.
The most effective teams connect simulation updates to upstream deployment events rather than to test failures, reducing the drift window from weeks to hours.
Full production parity (infrastructure, data volume, traffic patterns) is unnecessary; targeted accuracy for the specific behavioral contracts that integration tests validate is sufficient to catch the failures that matter most.
Drift accumulates because production and sandbox change on different schedules with different triggers, and the sandbox does not track production automatically. Without deliberate coordination, drift is the default outcome.
Behavioral contract drift—when simulated upstream responses no longer match what the real service returns—is the category that breaks things. Infrastructure divergence (different instance types, memory limits) rarely changes what integration tests catch.
Connect simulation updates to upstream deployment events rather than to test failures. Use observation-based tools like Keploy that capture real HTTP traffic to generate simulations from observed reality, so the simulation reflects what the service actually returns.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
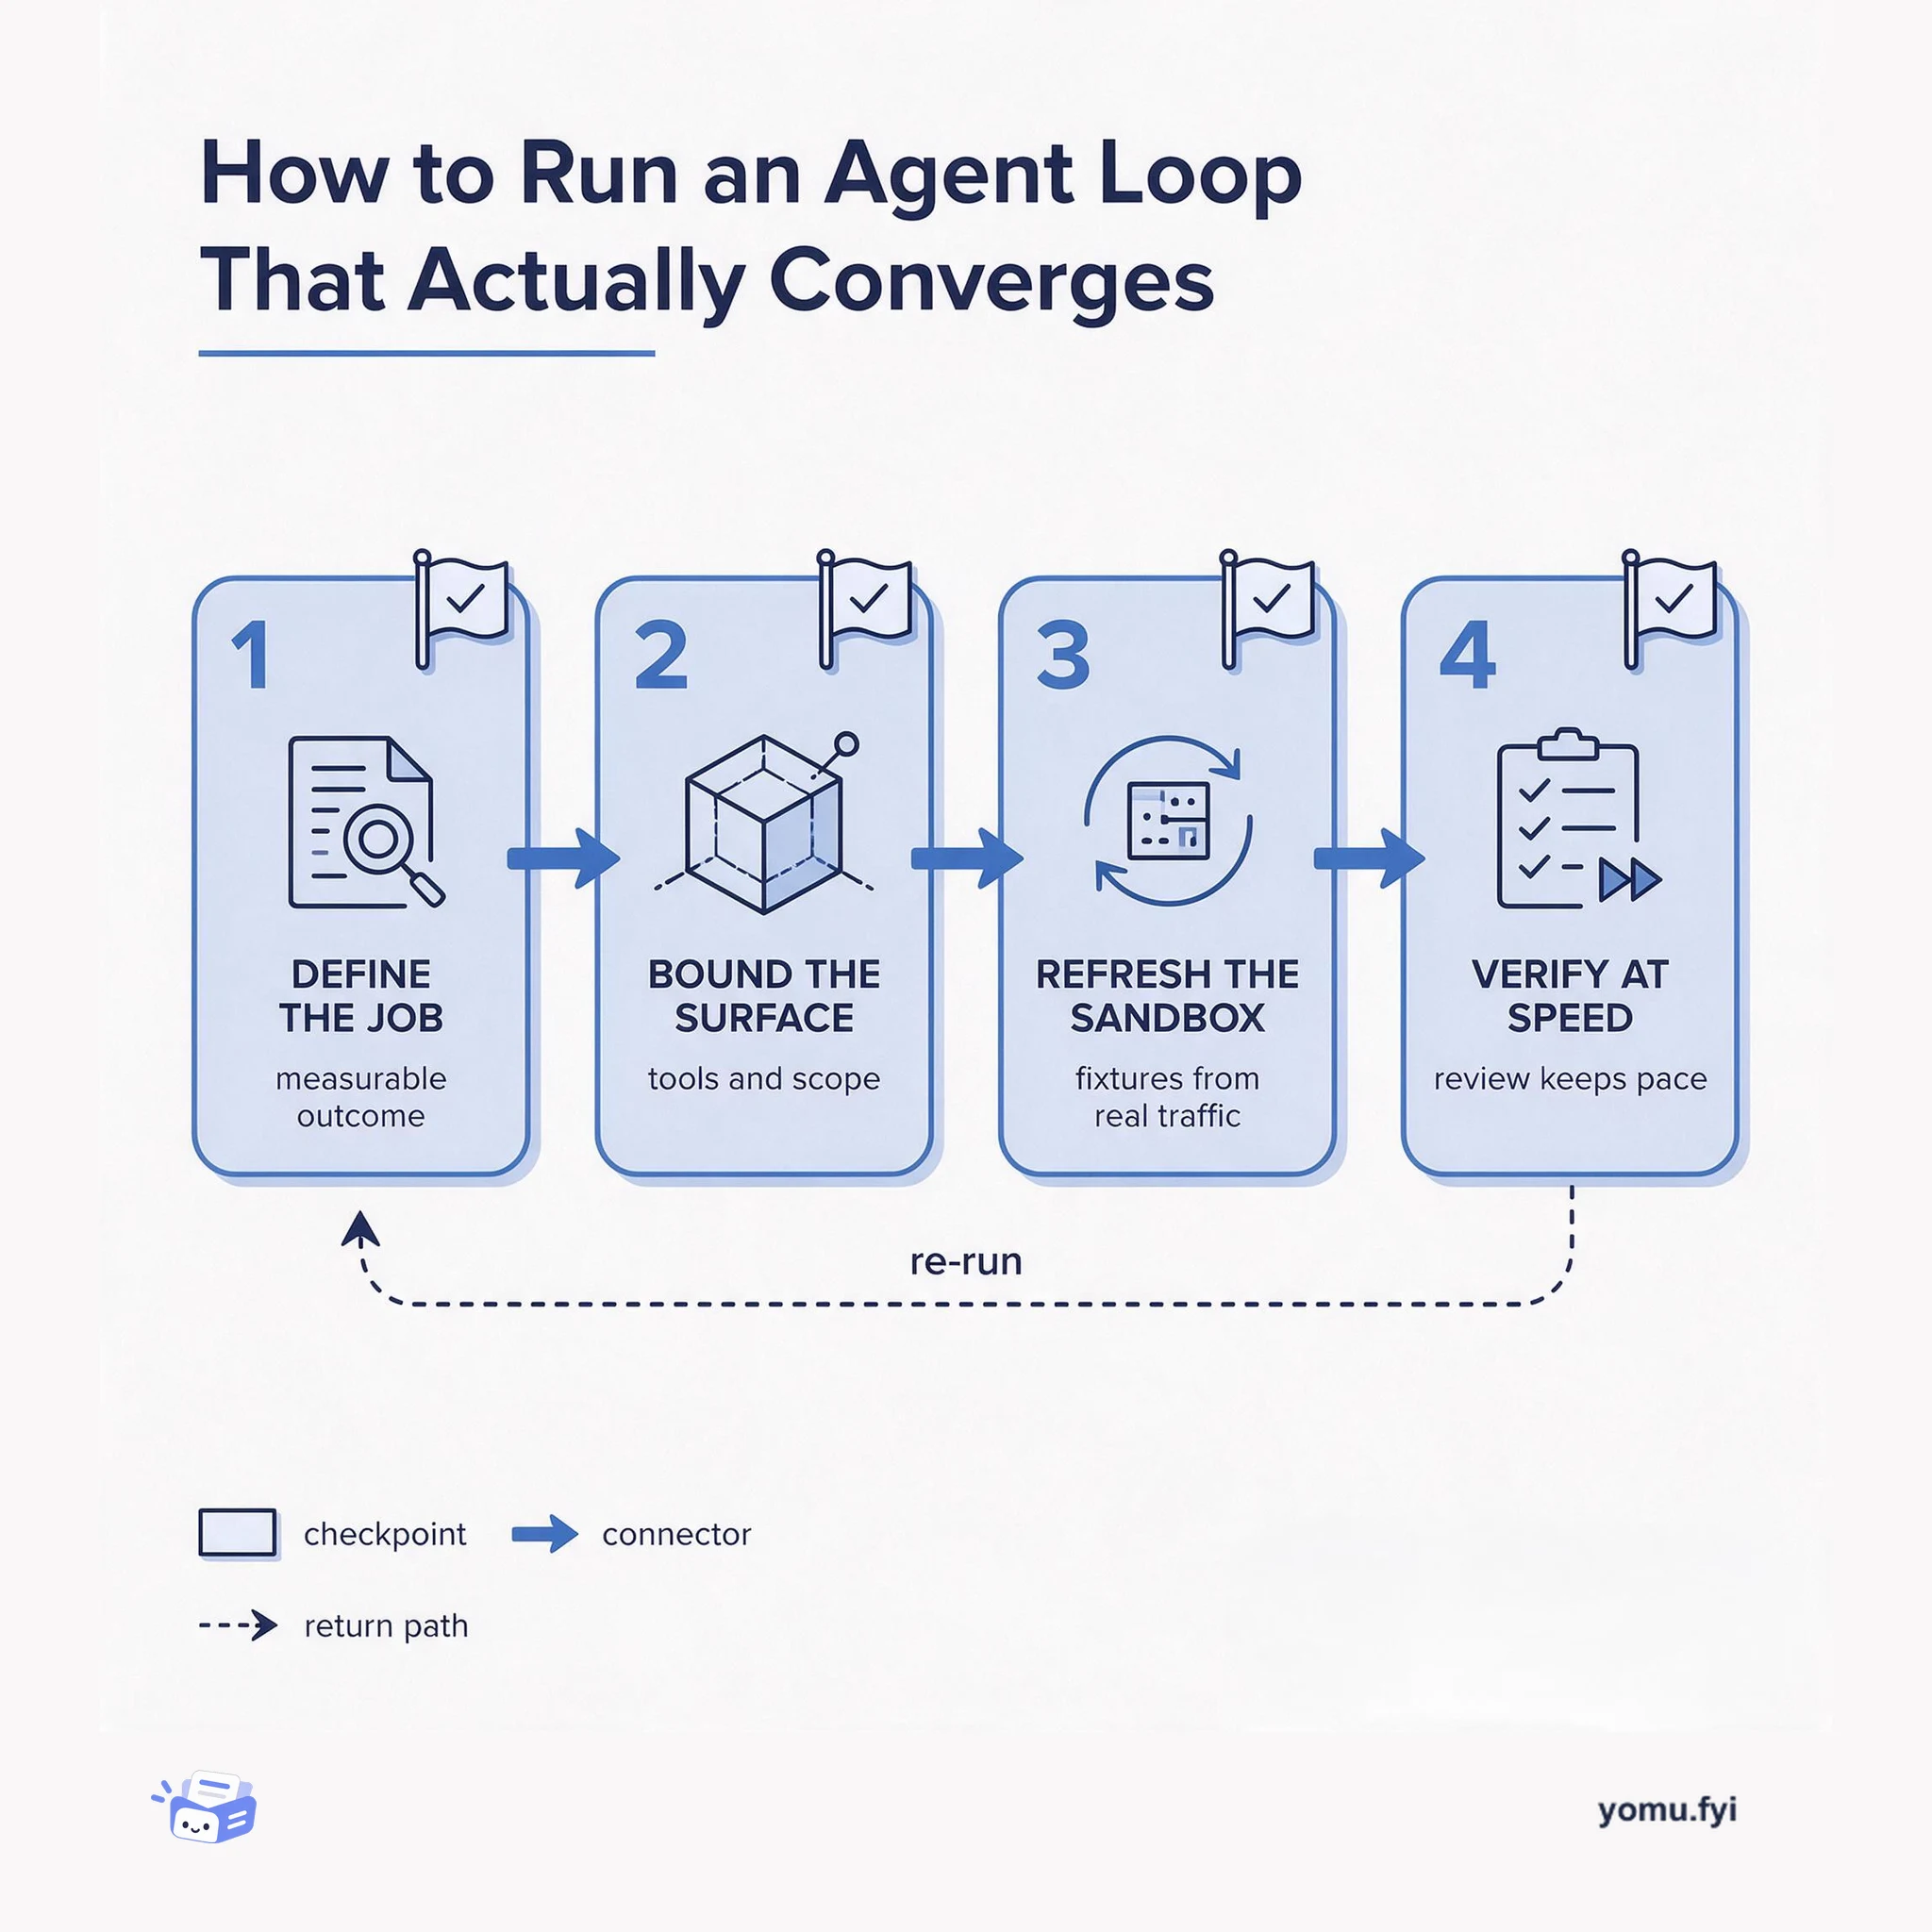
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.