ARM Is a Stack Decision, Not a CPU Checkbox
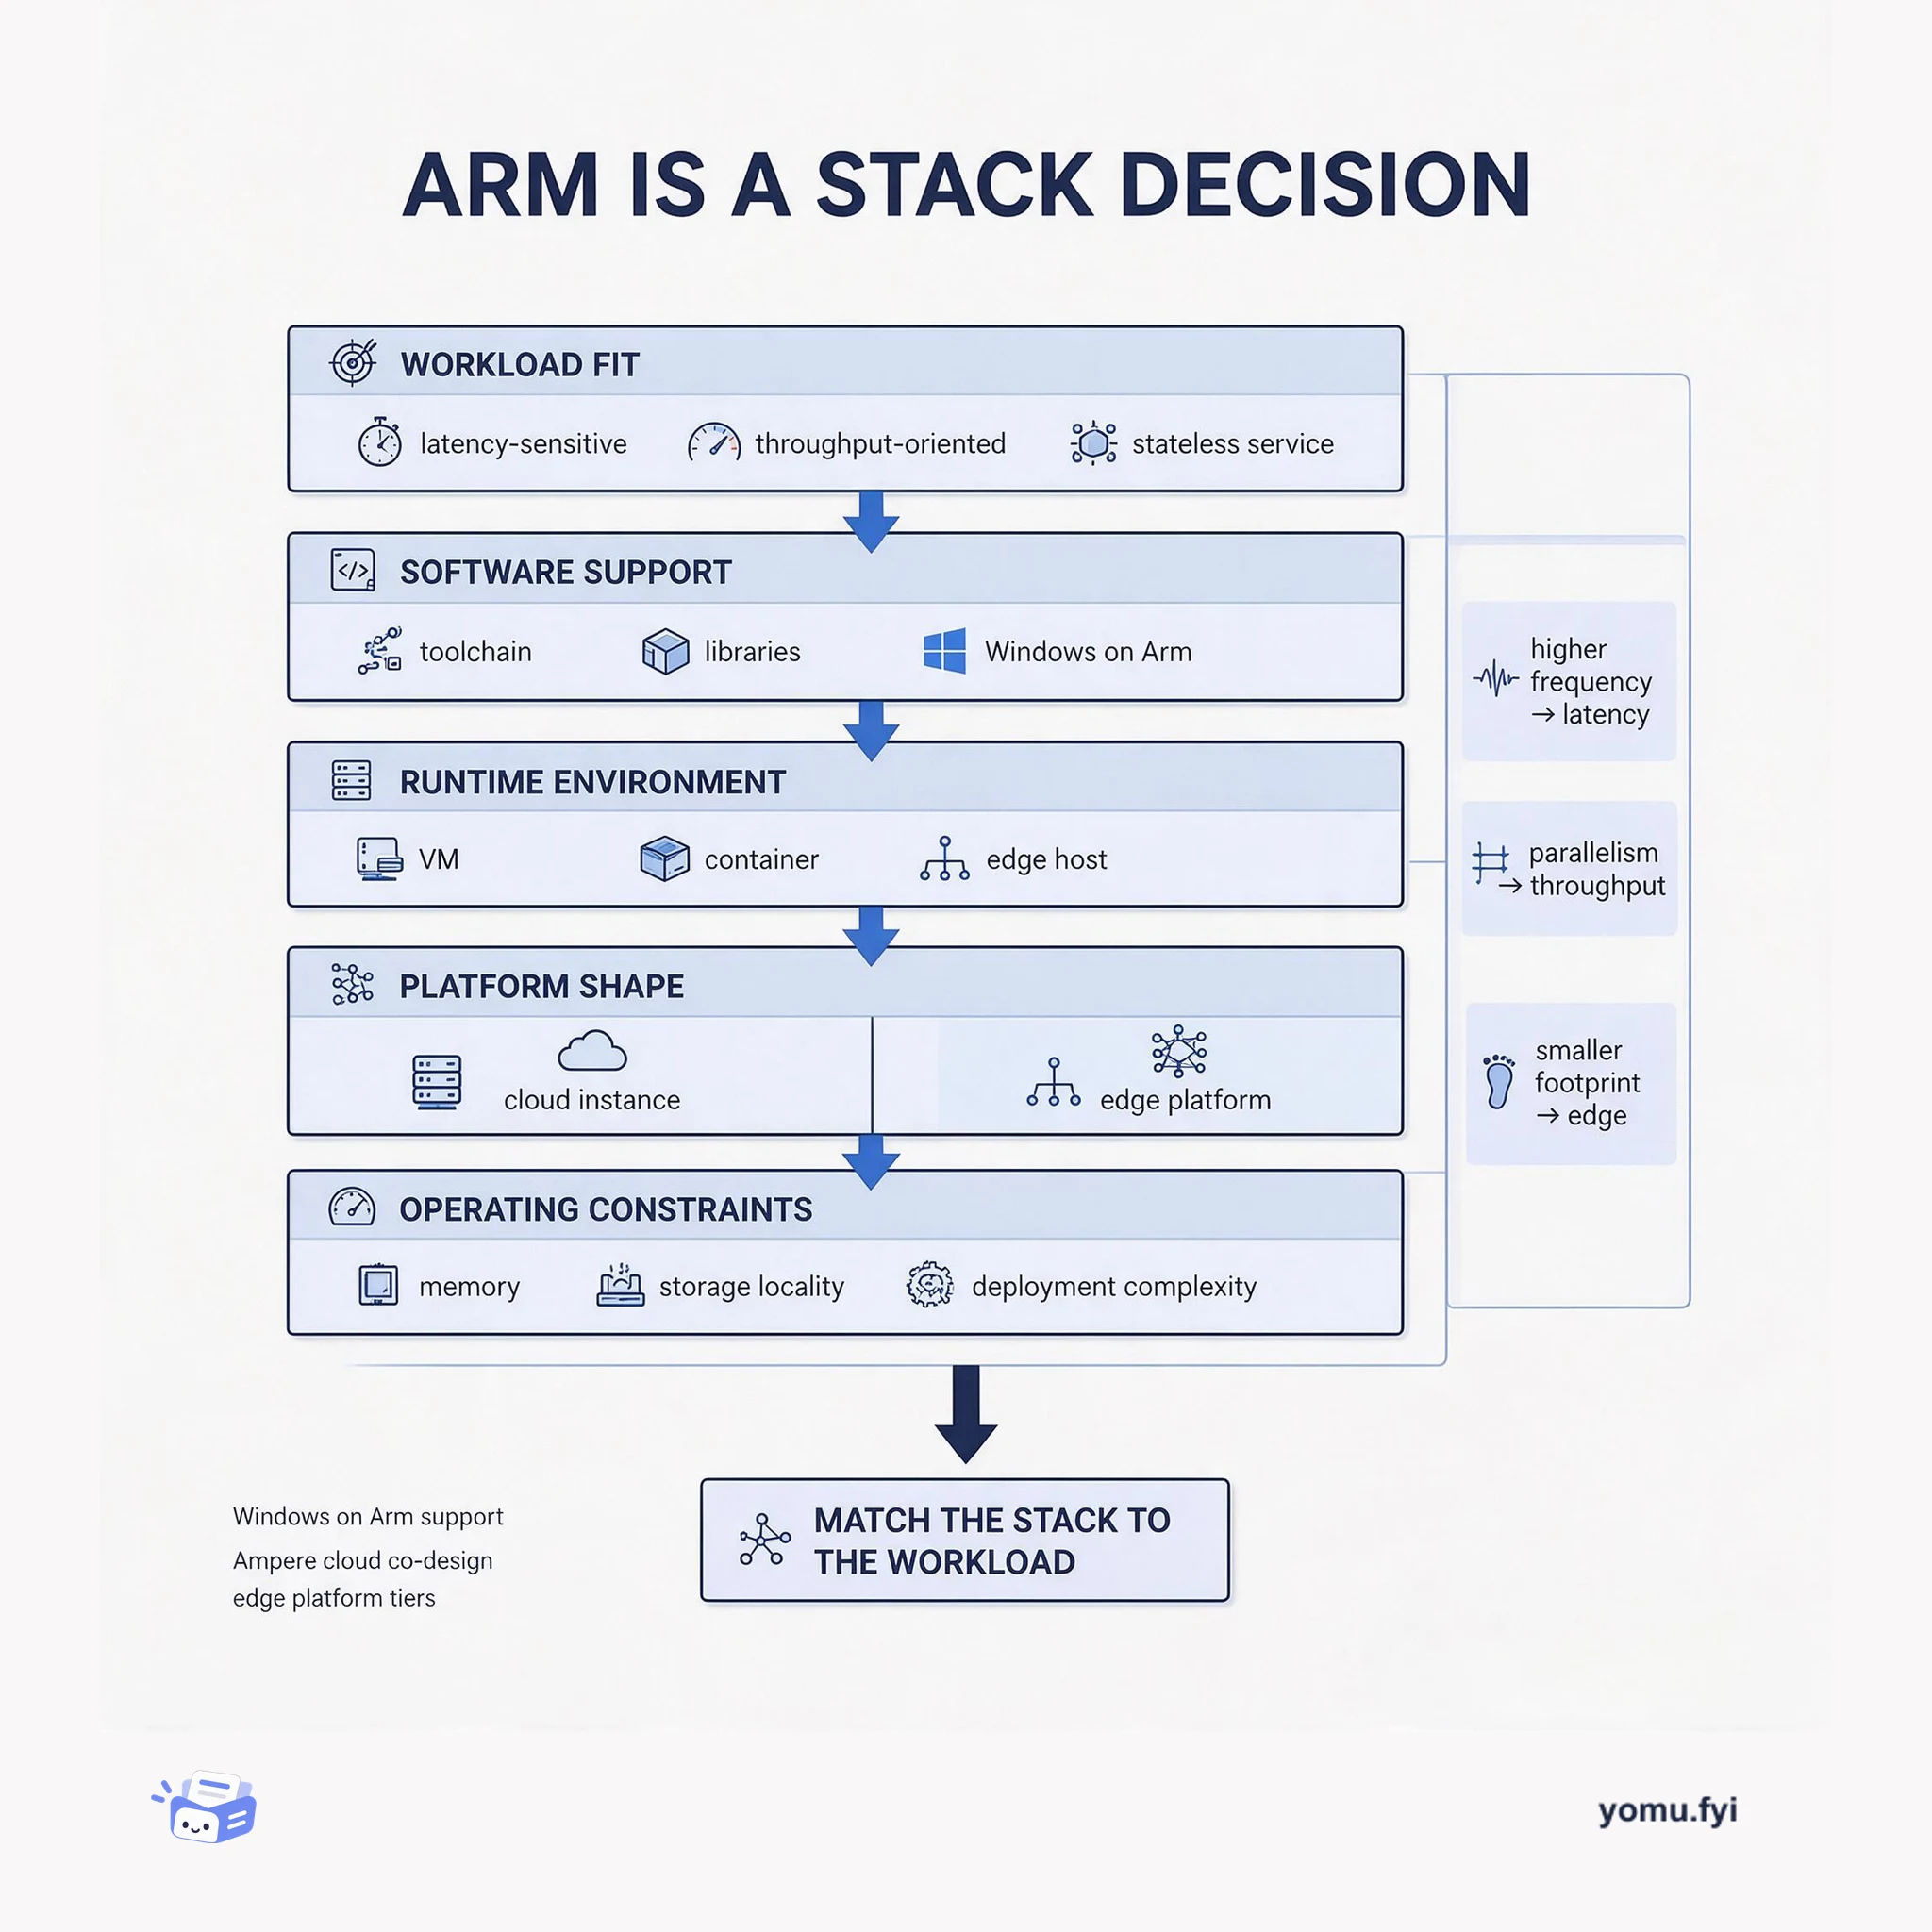
An architecture view of ARM deployments, from workload fit and software support to platform choice, showing where performance, memory, storage, and operations shape the decision.
 NVIDIAJonathan BentzAnnouncement
CUDA Toolkit 13.4 extends CUDA application support to Windows on Arm and provides preview support for NVIDIA Rubin (compute capability 107), alongside updates to GPU management, CUDA Python, CCCL, Nsight tools, and core math libraries. Multi-Process Service V3 adds a scriptable CLI, named server instances, namespaces, TOML configuration, streaming multiprocessor partition controls, and cgroup-integrated GPU memory limits for shared, containerized GPU workloads. CUDA Compute Fabric Transport lets communication-library developers address named NVLink endpoints and issue asynchronous put, get, and reduction operations without mapping every remote allocation into virtual address space; it is exposed only through the Driver API. The release also decouples driver installation from the toolkit, exposes locality and unified-memory residency queries, and changes coherent platforms to CDMM by default while retaining NUMA support.
CUDA Toolkit releases add functionality and performance improvements for developers using NVIDIA GPUs and the broader NVIDIA software platform. This release extends platform support to Windows on Arm and adds capabilities for shared GPU management, communication, memory locality, Python development, profiling, and math libraries.
CUDA Toolkit 13.4 adds Windows on Arm support, preview compilation and functional support for Rubin, Multi-Process Service V3 controls for partitioning shared GPUs, CUDA Compute Fabric Transport for NVLink data movement, locality and unified-memory residency APIs, expanded CUDA Python functionality, and updates across developer tools and libraries.
Multi-Process Service V3 supports named server instances, namespaces, TOML configuration, streaming multiprocessor partitioning, cgroup-integrated GPU memory limits, and a scriptable CLI for shared GPU workloads.
CUDA Compute Fabric Transport uses named logical endpoints, endpoint IDs, and offsets for asynchronous put, get, and reduction operations over NVLink; it is available only through the CUDA Driver API.
CUDA SDK installers no longer bundle the NVIDIA driver. On coherent platforms, CDMM is now the default memory-management mode, while NUMA remains available through a kernel module parameter.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
An architecture view of ARM deployments, from workload fit and software support to platform choice, showing where performance, memory, storage, and operations shape the decision.
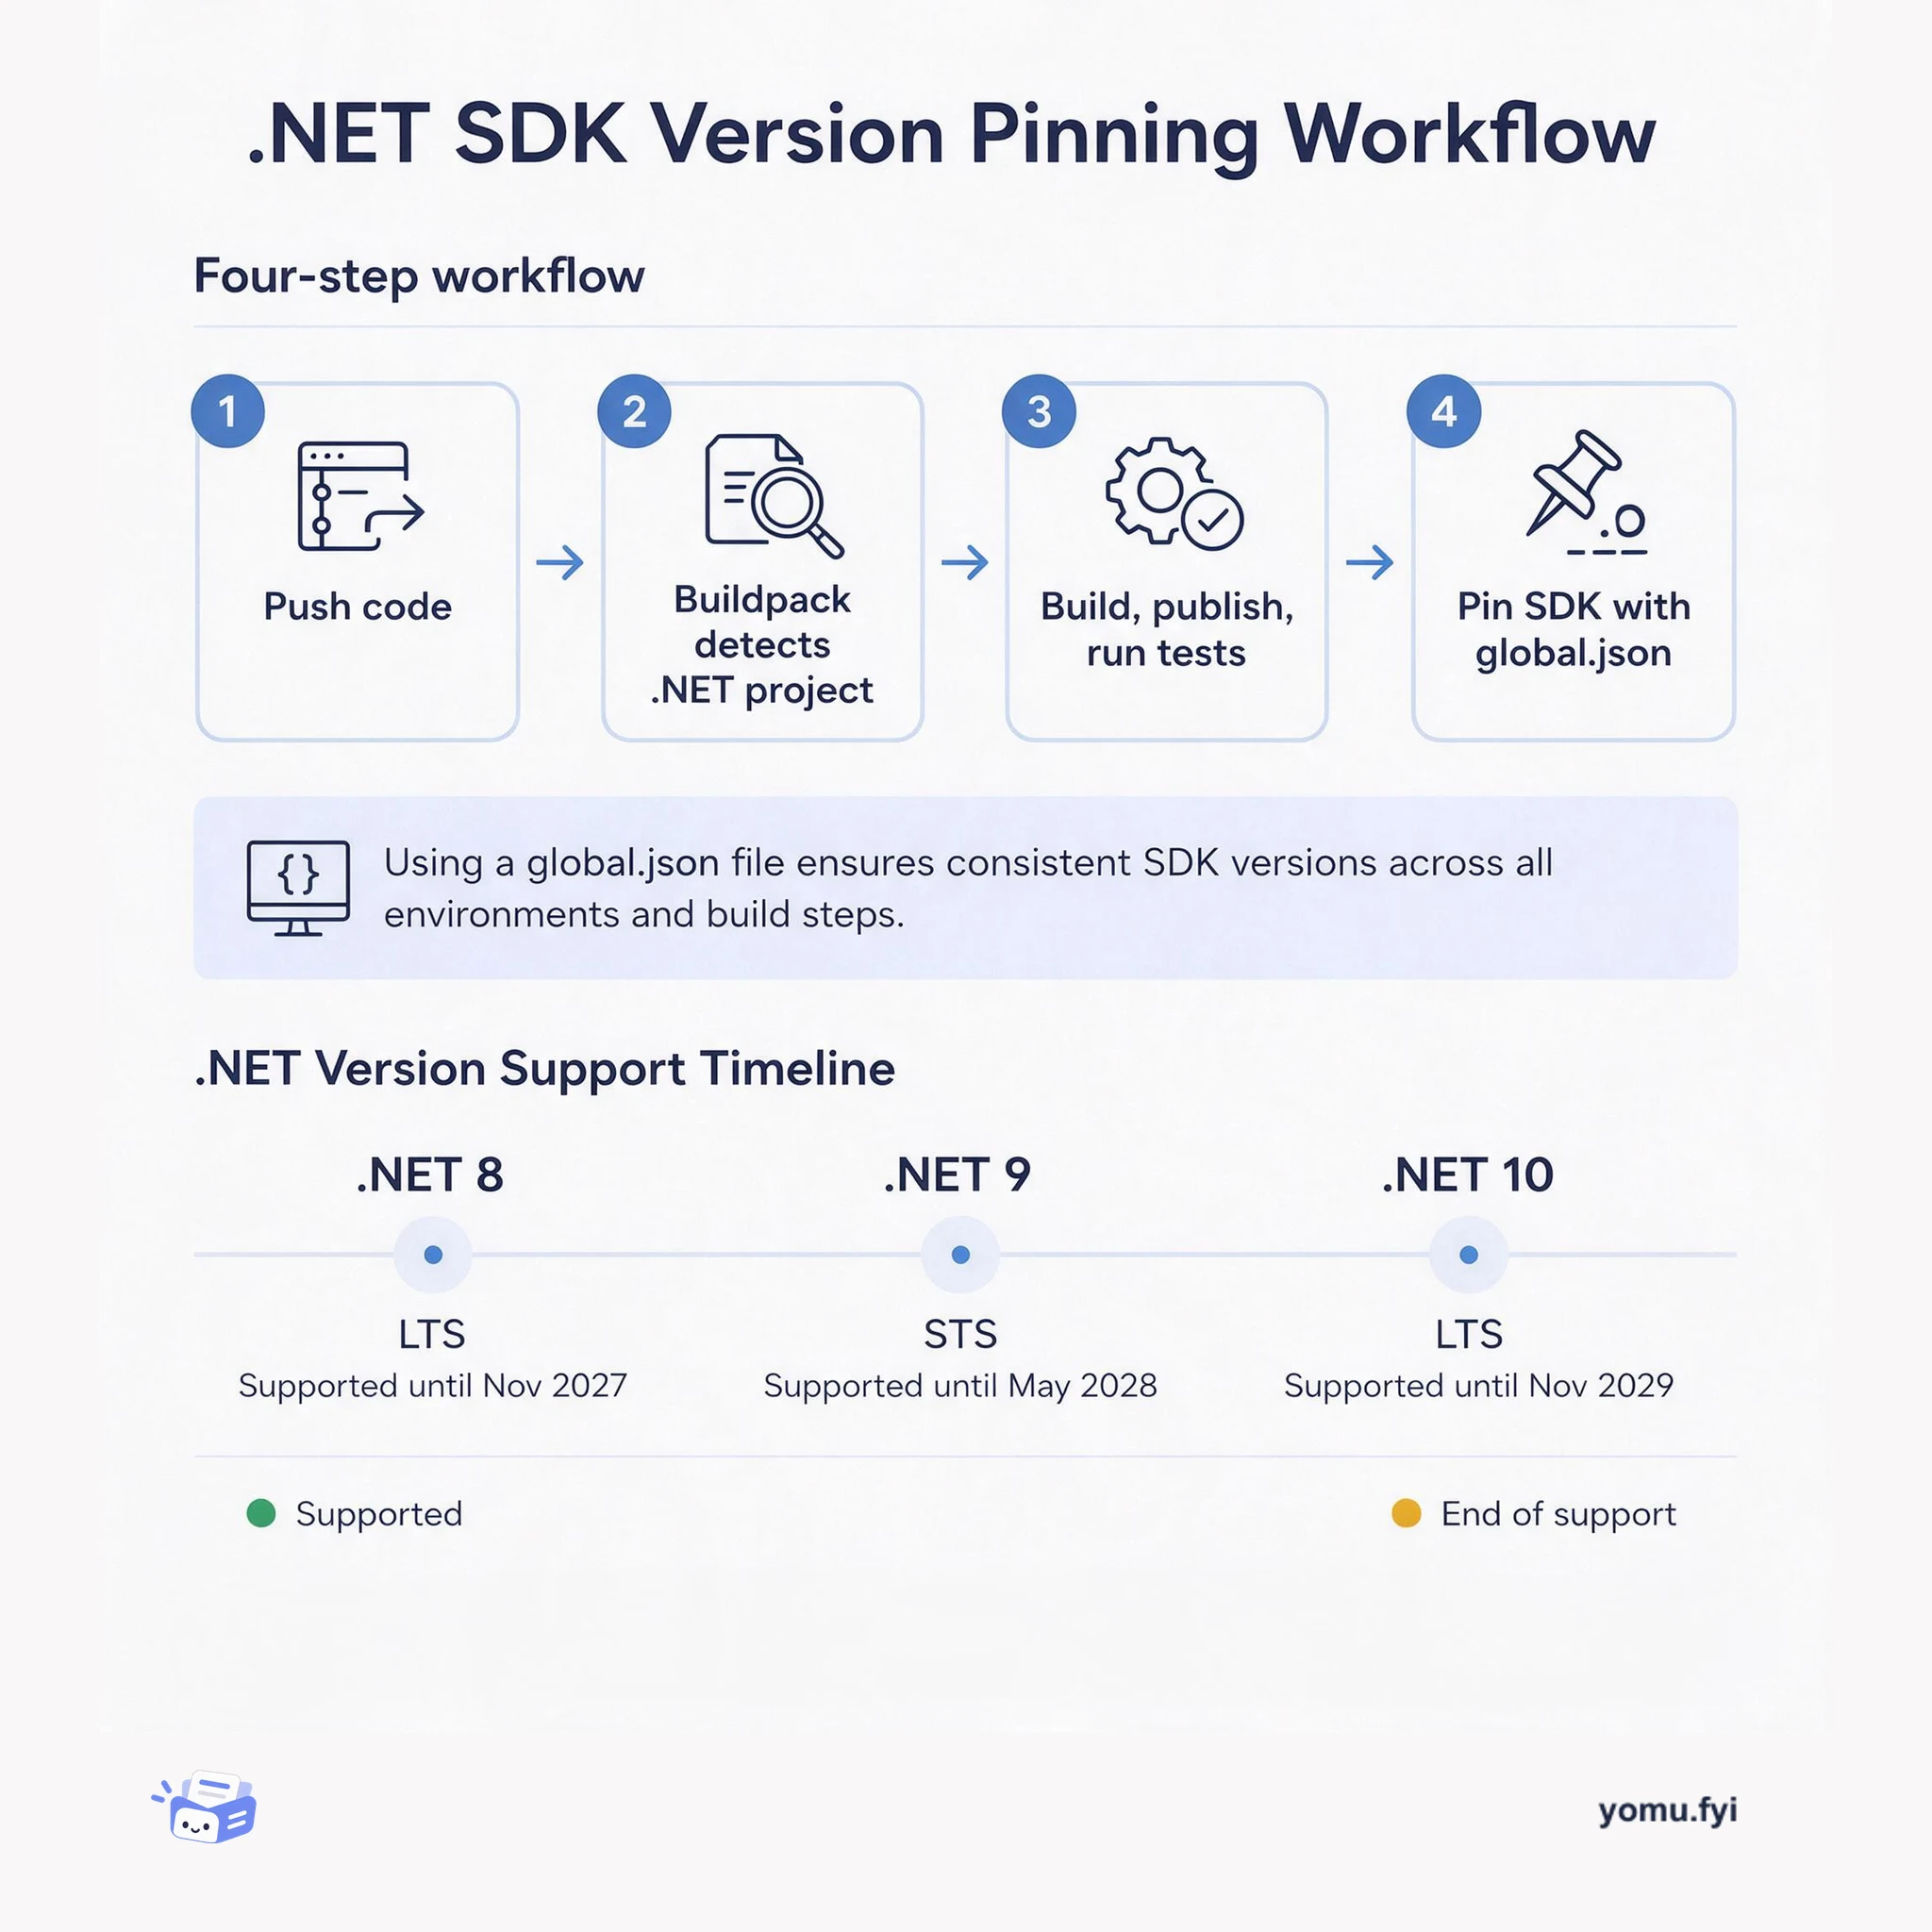
Learn the step-by-step process for deploying .NET 10 applications to Heroku, from buildpack detection to SDK pinning, and understand the lifecycle of .NET LTS releases.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.