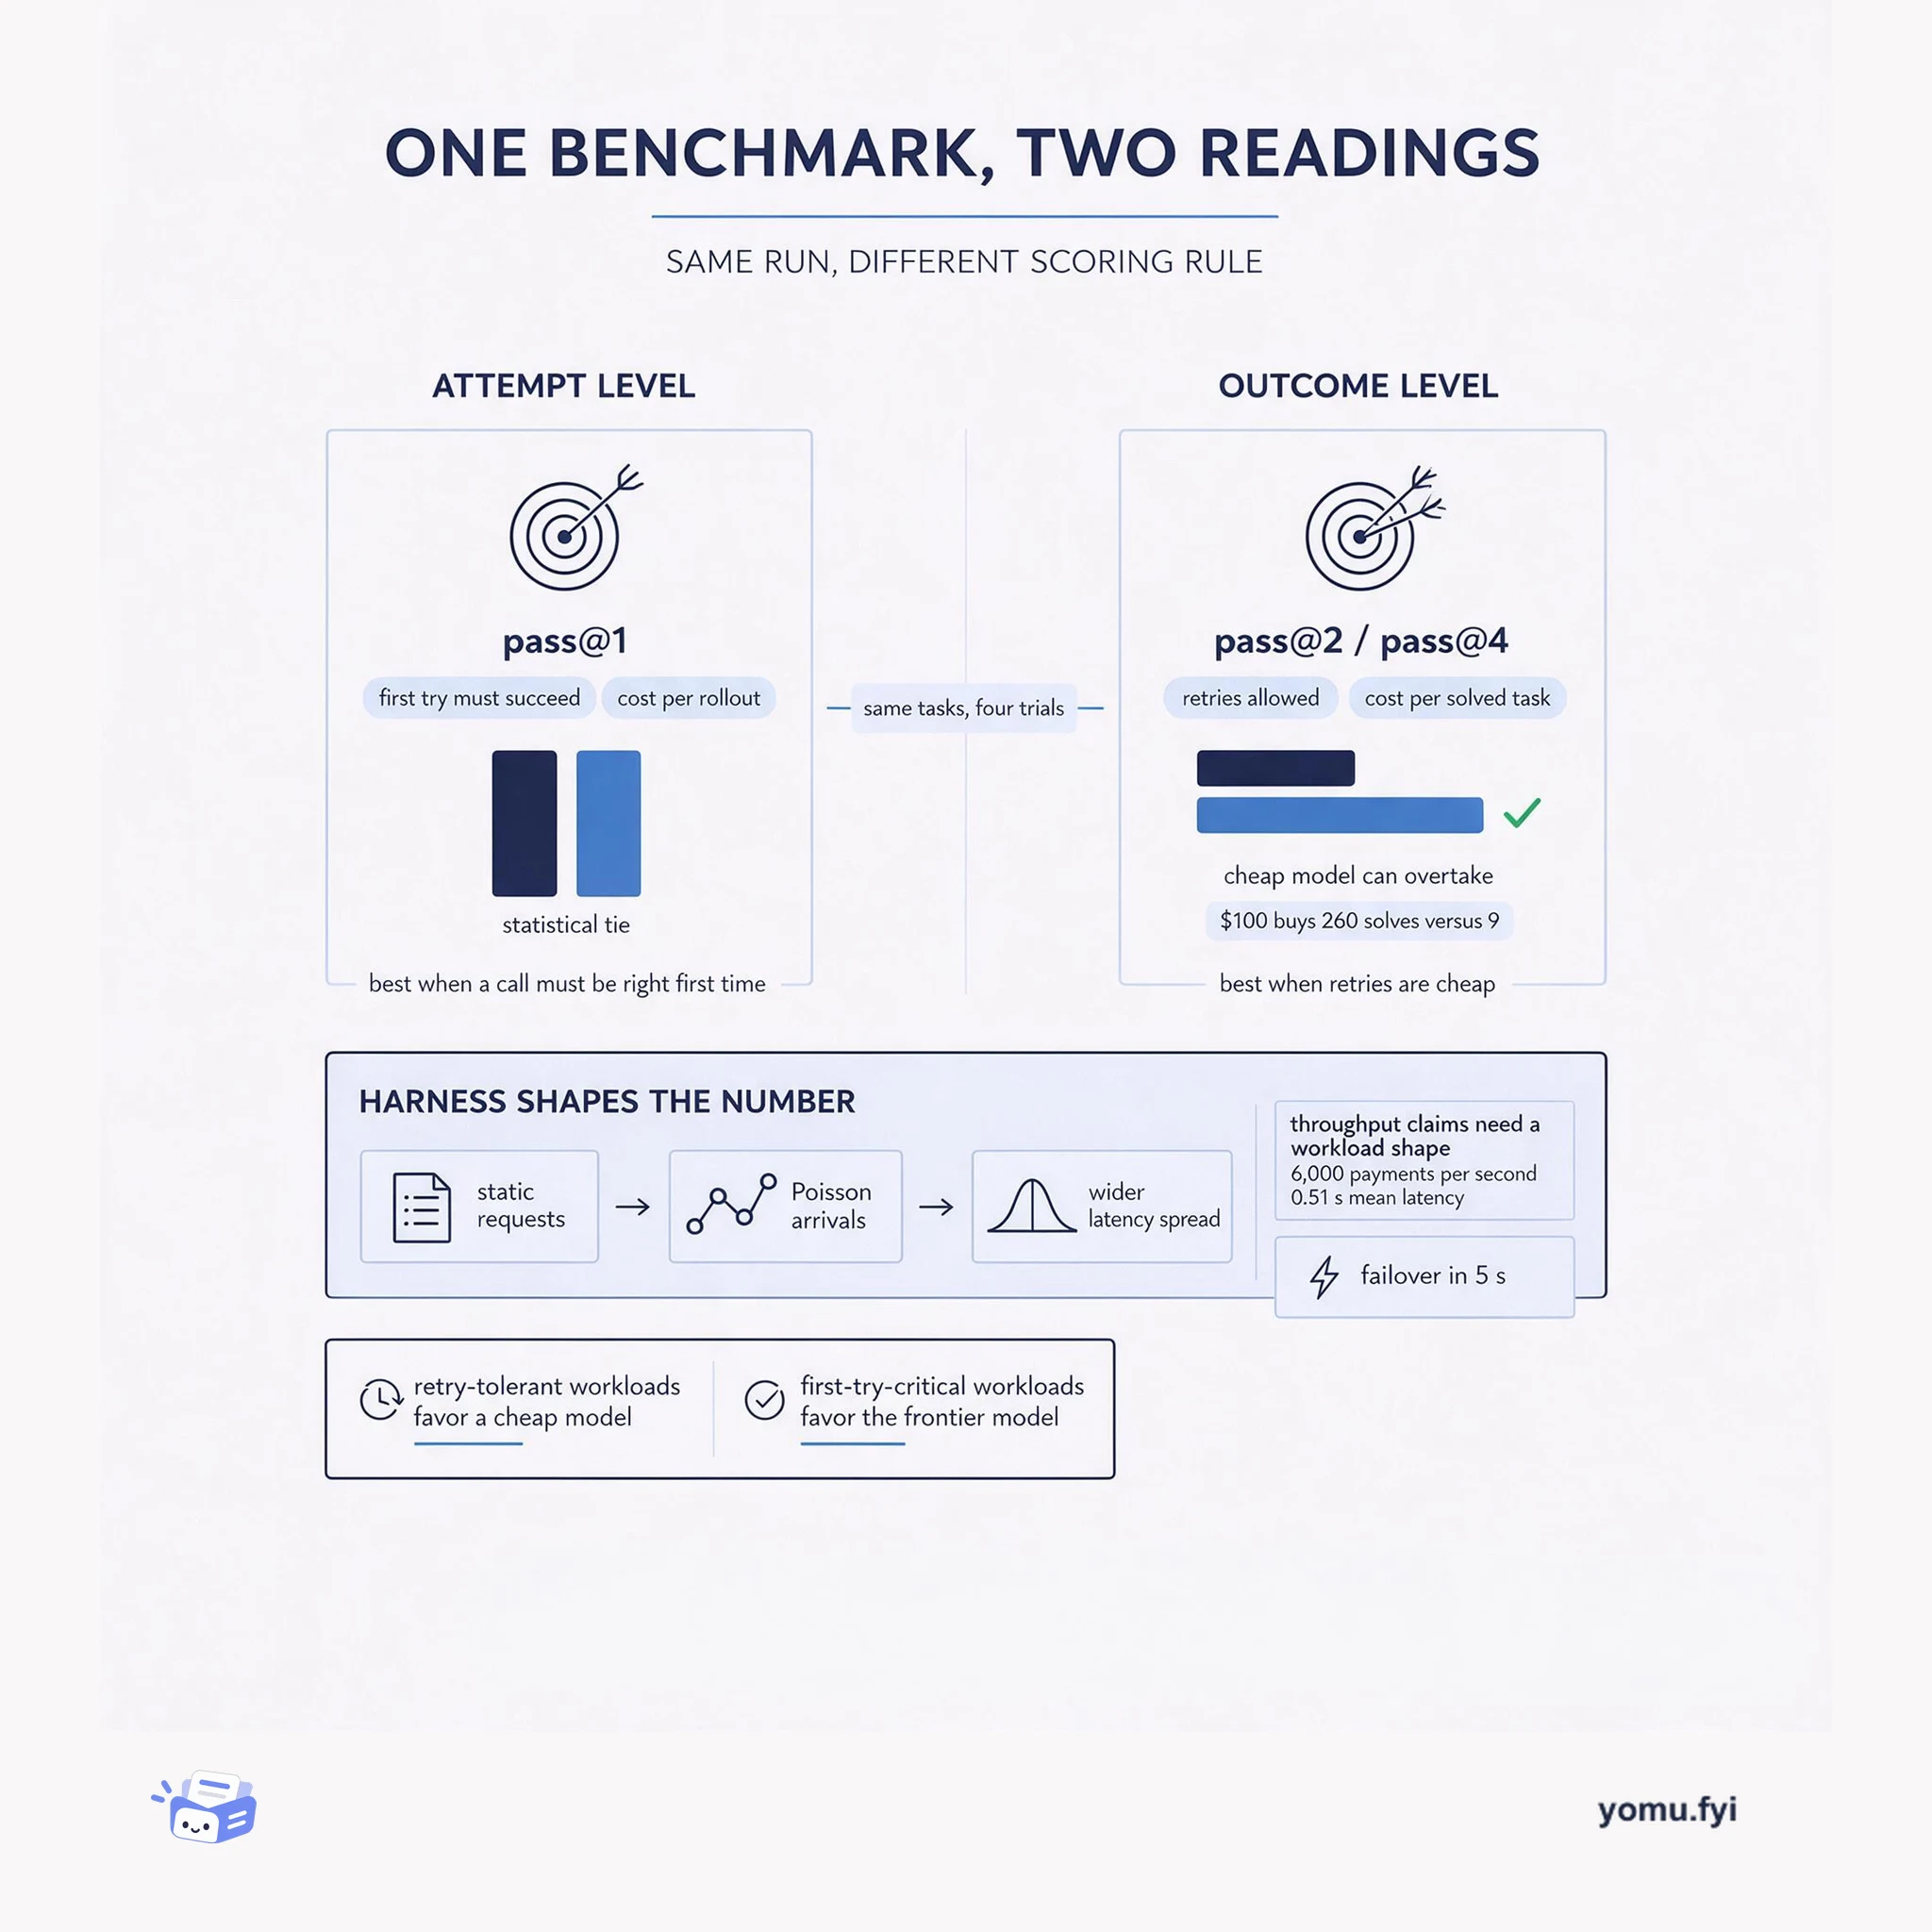
Pass@1 vs. pass@k: Two Ways to Read One Benchmark
A benchmark can support two different verdicts: pass@1 on the first attempt, or pass@k with retries measured as cost per solved task. This comparison shows which reading matches your workload.
 Together AIBenchmark
DeepSeek V4 Pro 0813 costs $0.24 per rollout and achieves 62.8% pass@1 on DeepSWE, while GPT-5.6 Sol reaches 72.7% pass@1 at $8.37 per rollout—a 35x price gap. At four attempts, DeepSeek V4 Pro 0813 surpasses Sol, with 88.5% pass@4 versus 85.8%. Sol is faster and more reliable, completing a rollout in 17 minutes and 53 steps, and breaking tests in only 11% of its failures. A cascade strategy—running DeepSeek V4 Pro 0813 first and escalating to Sol on test failure—solves 83.0% of tasks at $3.35 each, outperforming either model alone. Per $100, DeepSeek V4 Pro 0813 solves 260 tasks versus Sol’s 9, making it the value leader for budget-constrained workloads.
The authors ran 904 DeepSWE rollouts (452 per model, four trials across 113 tasks) to compare DeepSeek V4 Pro 0813 and GPT-5.6 Sol on software engineering ability, cost, and routing strategies.
The recommended cascade: run DeepSeek V4 Pro 0813 first; if the test suite rejects its answer, escalate to GPT-5.6 Sol for a second independent attempt.
DeepSeek V4 Pro 0813 costs $0.24 per rollout and achieves 62.8% pass@1, while GPT-5.6 Sol achieves 72.7% pass@1 at $8.37 per rollout—a 35x price difference.
At four attempts, DeepSeek V4 Pro 0813 surpasses Sol (88.5% pass@4 vs 85.8%), making best-of-k routing where Pro leads cheaper and more accurate than using Sol alone.
A cascade that runs Pro first and escalates to Sol on test failure solves 83.0% of tasks at $3.35 each, beating Sol alone (72.7% at $8.37) and even a perfect single-shot oracle (80.8%).
The cascade costs $3.35 per task, less than half of Sol's $8.37 per task, while solving 10.3 percentage points more tasks (83.0% vs 72.7%).
DeepSeek V4 Pro 0813 alone solves no task that Sol misses entirely, while Sol solves two tasks that Pro never solves. Pro adds minimal new reach; its value is clearing shared tasks at low cost.
DeepSeek V4 Pro 0813 is more conservative: only 11% of its failures break existing tests, versus 20% for GPT-5.6 Sol. Pro is safer to accept unreviewed.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A benchmark can support two different verdicts: pass@1 on the first attempt, or pass@k with retries measured as cost per solved task. This comparison shows which reading matches your workload.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
