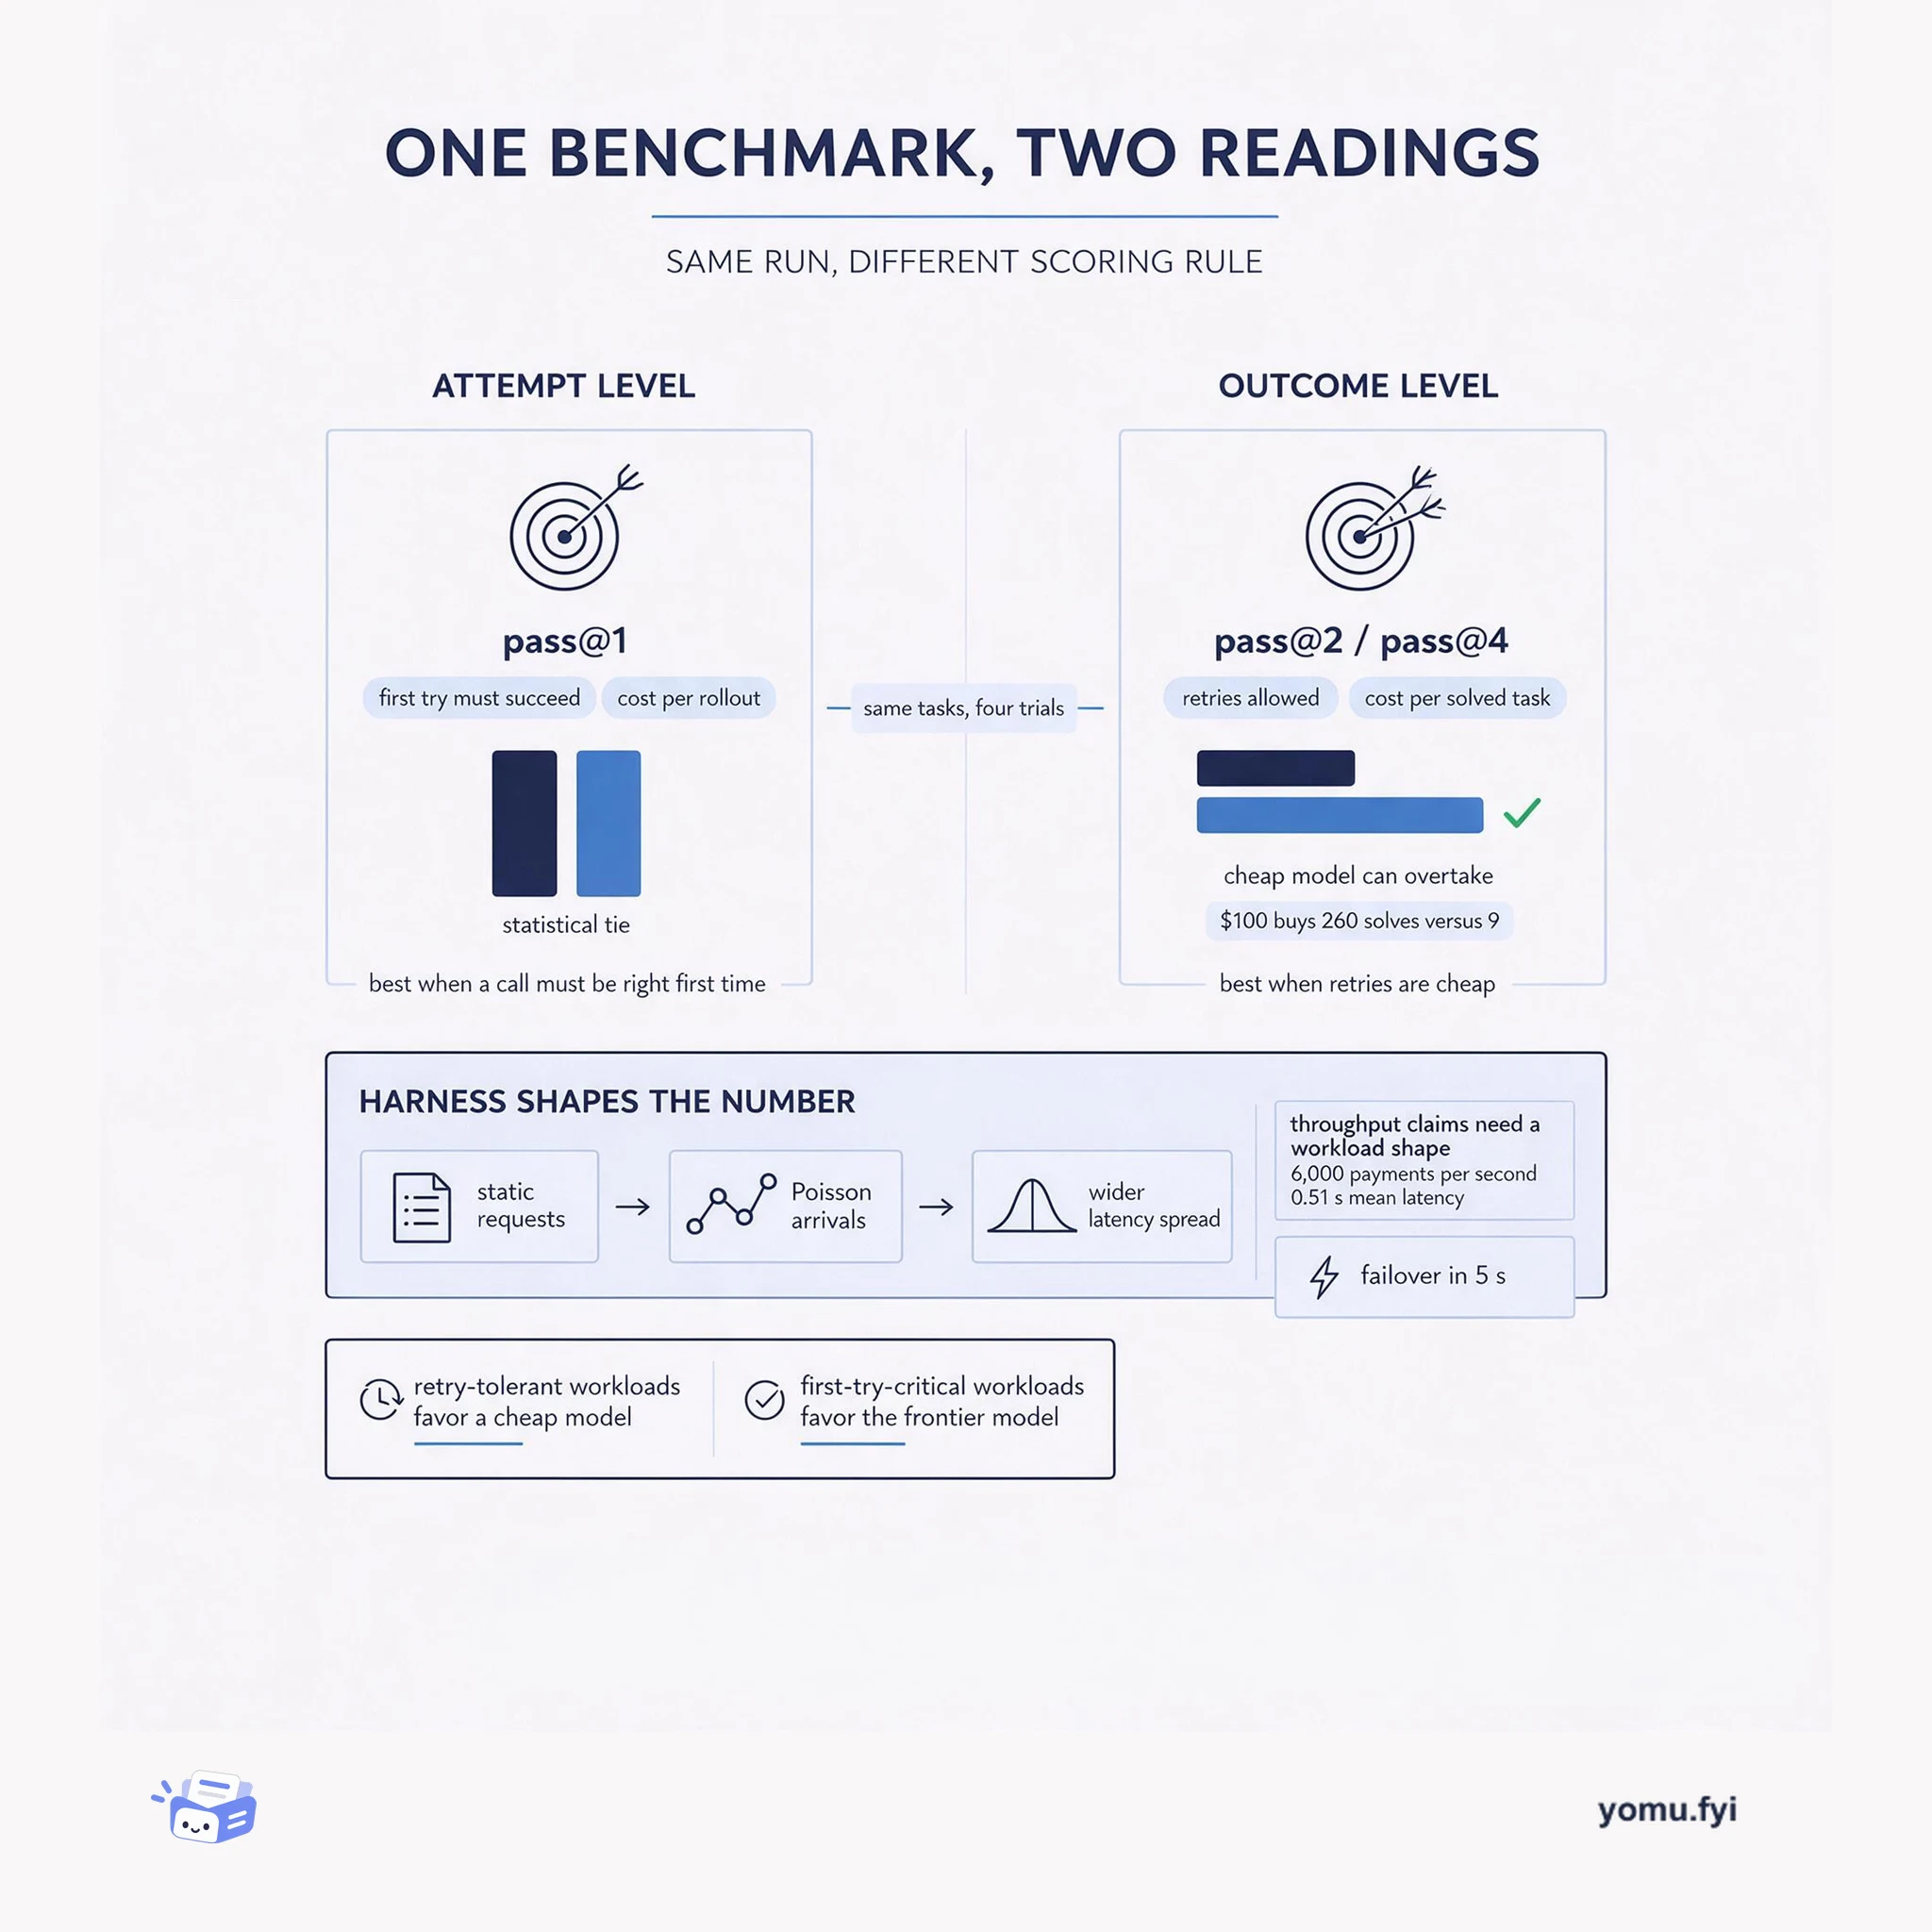
Pass@1 vs. pass@k: Two Ways to Read One Benchmark
A benchmark can support two different verdicts: pass@1 on the first attempt, or pass@k with retries measured as cost per solved task. This comparison shows which reading matches your workload.
 Together AIBenchmark
GLM-5.3 and Claude Fable 5 were compared on the DeepSWE benchmark across 113 tasks with four trials each, totaling 904 rollouts. On first-attempt accuracy, Fable 5 scored 69.7% and GLM-5.3 scored 69.0%, a statistical tie inside error bars. GLM-5.3 led on pass@2 (81.1% vs. 77.1%) and pass@4 (87.6% vs. 84.1%), and cost $3.99 per rollout versus Fable’s $21.63, a 5.4x price gap. Per $100, GLM-5.3 solved 17 tasks while Fable solved 3. Both models regress test suites in only 11% of failures, and GLM-5.3 averages 35 minutes per rollout with 80k output tokens versus Fable’s 34 minutes and 114k tokens. The models are near-substitutes with 0.65 per-task correlation; GLM-5.3 won five of eight domains including JavaScript and concurrency, while Fable excelled only in Rust and serialization, making GLM-5.3 the practical default.
The post compares GLM-5.3 and Claude Fable 5 on the DeepSWE benchmark, which tests software engineering ability across multiple task types and programming languages. The comparison uses 113 tasks with four trials each, analyzing accuracy, cost, and domain performance.
The authors ran 904 rollouts (452 per model) on all 113 DeepSWE tasks, four trials each, using the published per-trial records. They compared pass@1, pass@2, pass@4, cost per rollout, solves per $100, per-task correlation, domain performance, and failure modes.
GLM-5.3 and Claude Fable 5 are a statistical tie on pass@1 (69.0% vs 69.7%), but GLM-5.3 wins on pass@2 and pass@4 and costs 5.4x less.
Per $100, GLM-5.3 solves 17 DeepSWE tasks while Fable solves only 3, making the cost gap the decisive factor.
The models are near-substitutes with 0.65 per-task correlation; GLM-5.3 dominates five domains including JavaScript and concurrency, while Fable only excels in Rust and serialization.
They are a statistical tie: Fable 5 scores 69.7% and GLM-5.3 scores 69.0%, a gap inside the error bars. The difference is not significant.
GLM-5.3 costs $3.99 per rollout, while Fable costs $21.63, a 5.4x gap. Per $100, GLM-5.3 solves 17 tasks versus Fable's 3.
Only for Rust and serialization-heavy work, where Fable has a 15-point advantage on Rust (85% vs 70%). For all other domains, GLM-5.3 is the better choice due to lower cost and comparable or better accuracy.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A benchmark can support two different verdicts: pass@1 on the first attempt, or pass@k with retries measured as cost per solved task. This comparison shows which reading matches your workload.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
