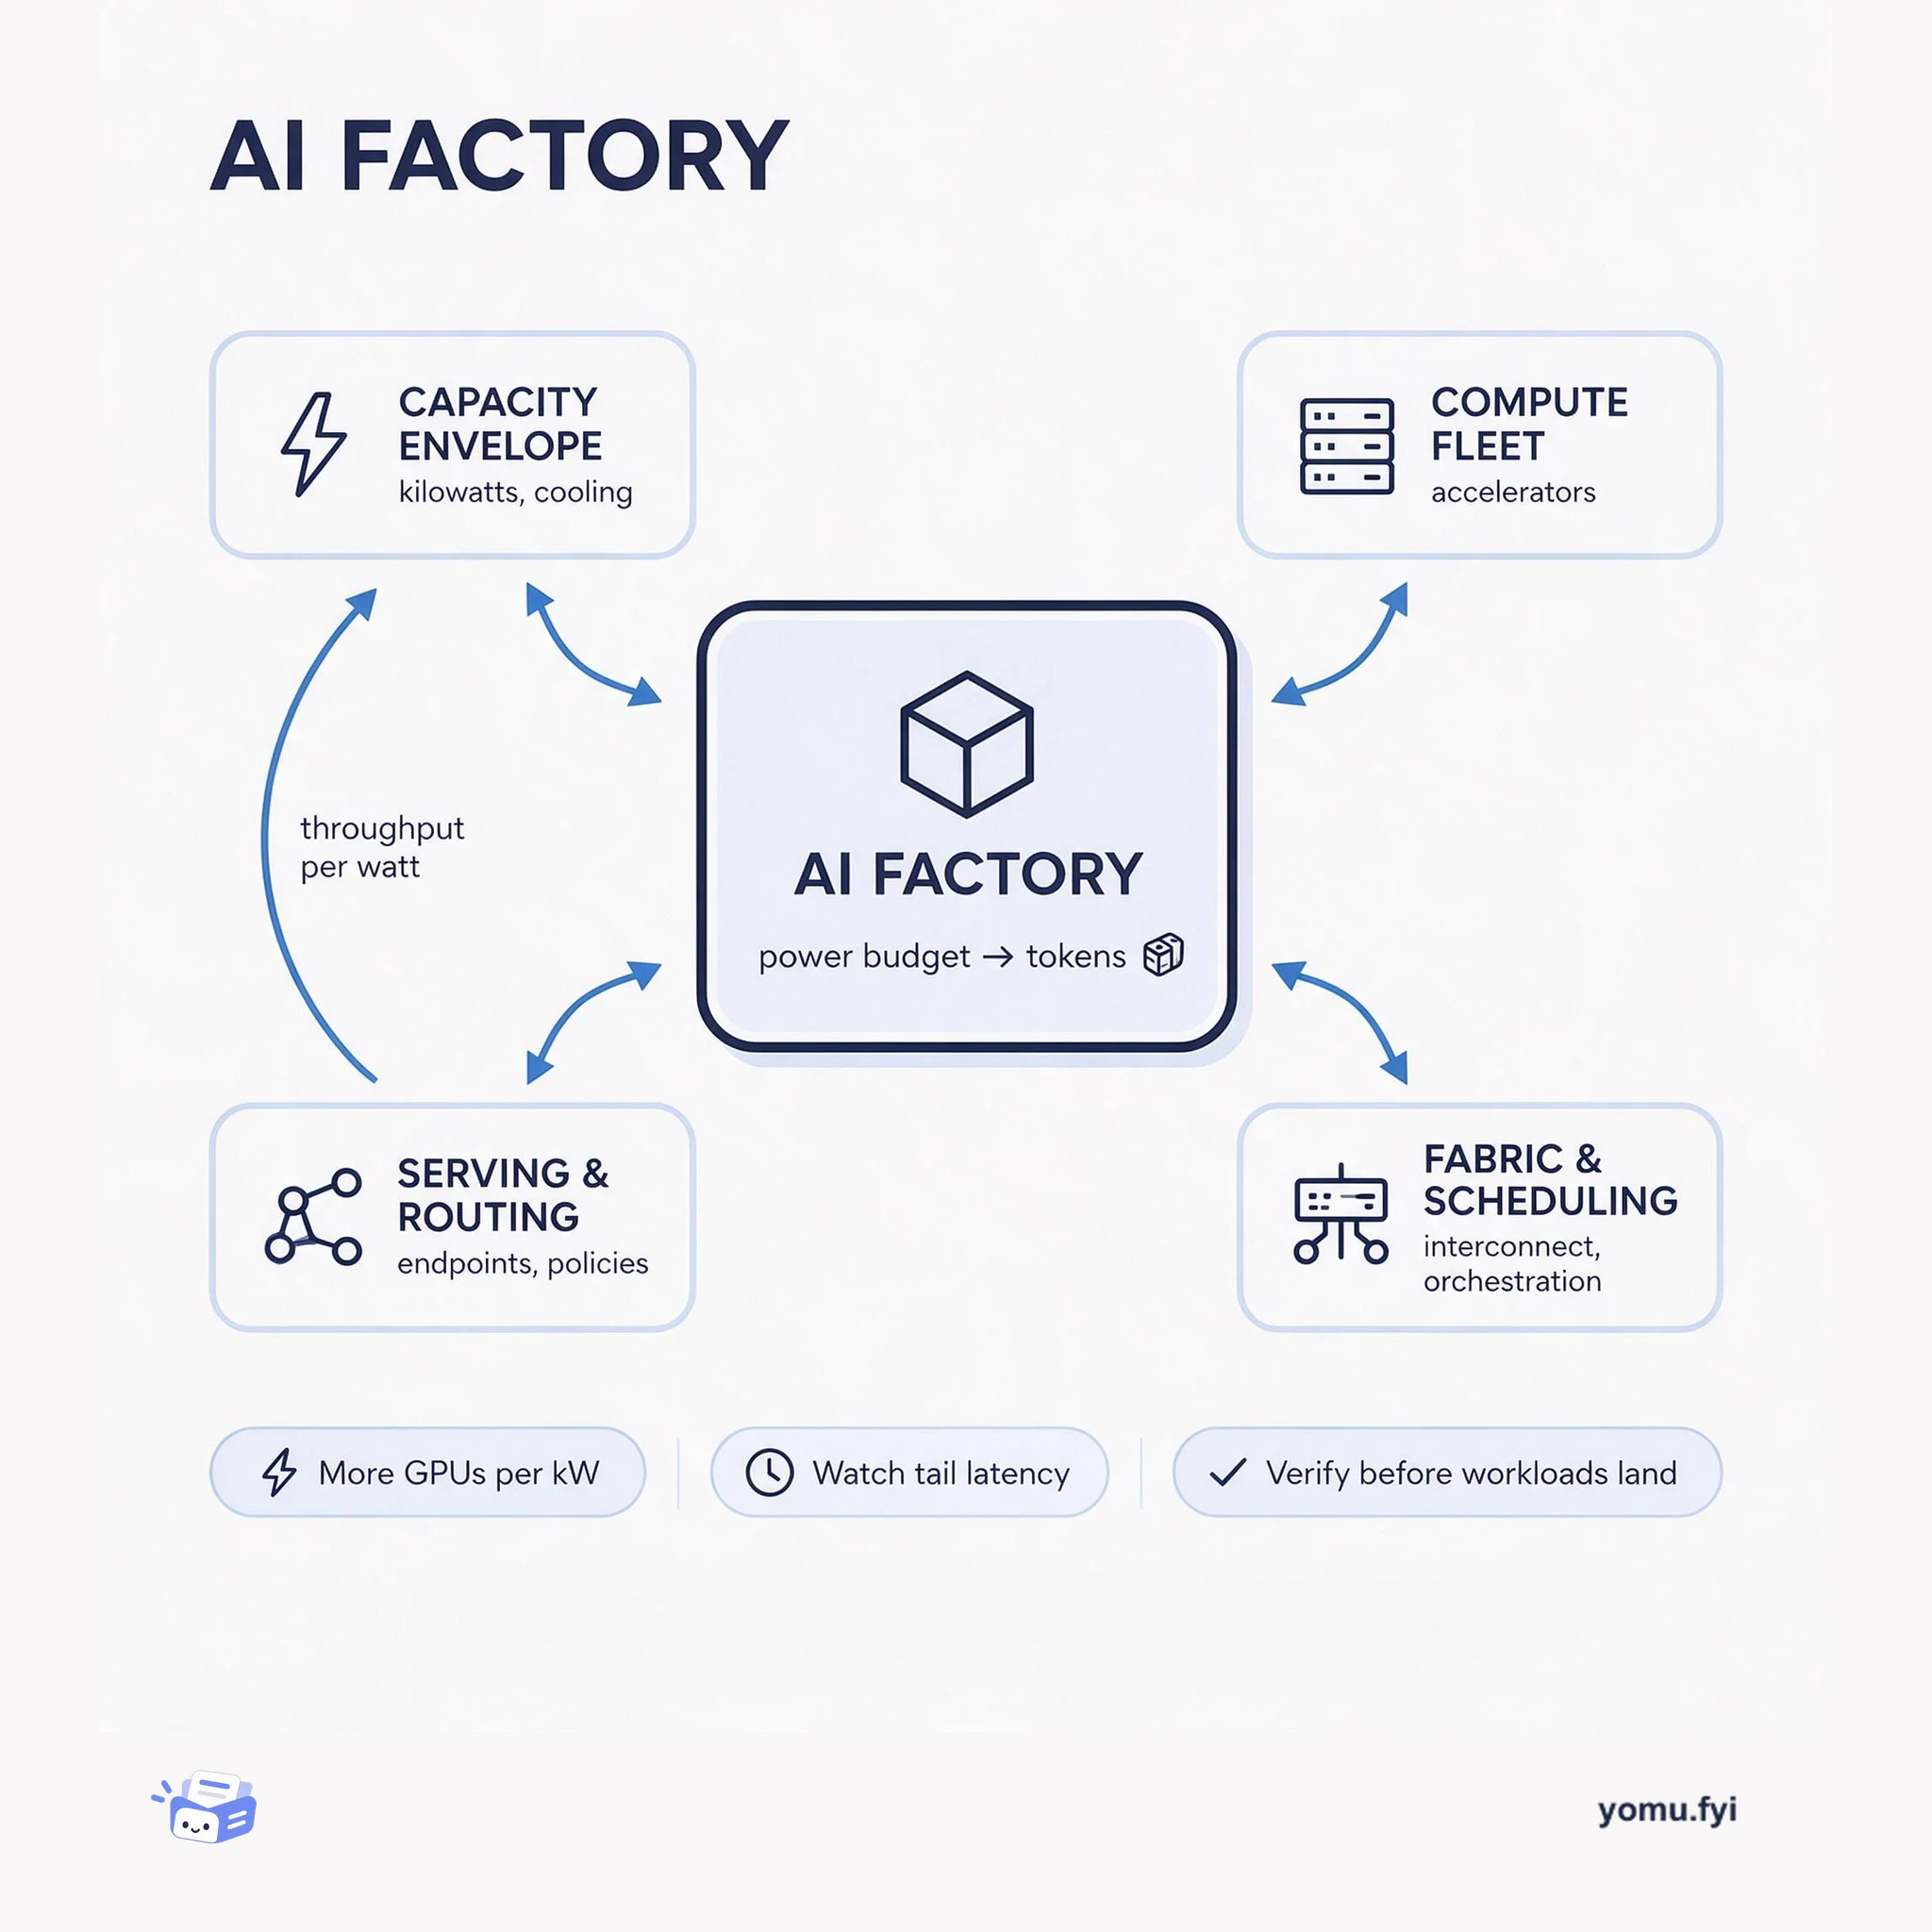
What Is an AI Factory? Power In, Tokens Out
An AI factory is a fixed power and cooling budget converted into model output. This explainer maps its four parts and the throughput-per-watt trade-offs that connect them.
 ModalProblem & solution
Modal and CMU built Quail, a query-aware inference layer for AI-SQL that combines a query planner with an inference engine to process structured LLM transformations of database entries. On a multi-join query, Quail achieves over a billion tokens per minute per H100 GPU, over 10x faster than vLLM, costing under 6 cents per billion tokens on Modal. The gain comes from using the query plan to order requests for better KV cache management, including a revised Hydragen-style cascade attention and batching small requests to reduce host overhead. On a new AI-SQL benchmark, Quail runs 1.84x faster than vLLM, but falls behind on agent trace processing. The authors see this as part of a trend toward custom inference engines for specific workloads, with a reusable core like databases post-DataFusion, and note that much work was done by prompting coding agents.
AI-SQL workloads use SQL to programmatically produce prompts for LLMs, enabling fuzzy queries on semi-structured data in business intelligence platforms. These workloads require GPUs for LLM inference but differ from chatbot and agent workloads in that they involve many small requests with known structure, making them amenable to query-aware optimization.
Quail combines a query planner with an inference engine to order requests for better KV cache management, using a revised Hydragen-style cascade attention and batching small requests to reduce host overhead and improve GPU utilization.
Quail uses a query planner to order requests for better KV cache management, achieving over a billion tokens per minute per H100 GPU on a multi-join query.
The system employs a revised Hydragen-style cascade attention and batches small requests to reduce host overhead and improve GPU utilization.
On a new AI-SQL benchmark, Quail runs 1.84x faster than vLLM geometrically averaged over tasks, but falls behind on agent trace processing due to limited cross-document prefix sharing.
By using the query plan to order requests for better KV cache management, including a revised Hydragen-style cascade attention and batching small requests to reduce host overhead.
Under 6 cents per billion tokens on Modal.
It falls behind on agent trace processing due to limited cross-document prefix sharing.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
An AI factory is a fixed power and cooling budget converted into model output. This explainer maps its four parts and the throughput-per-watt trade-offs that connect them.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
