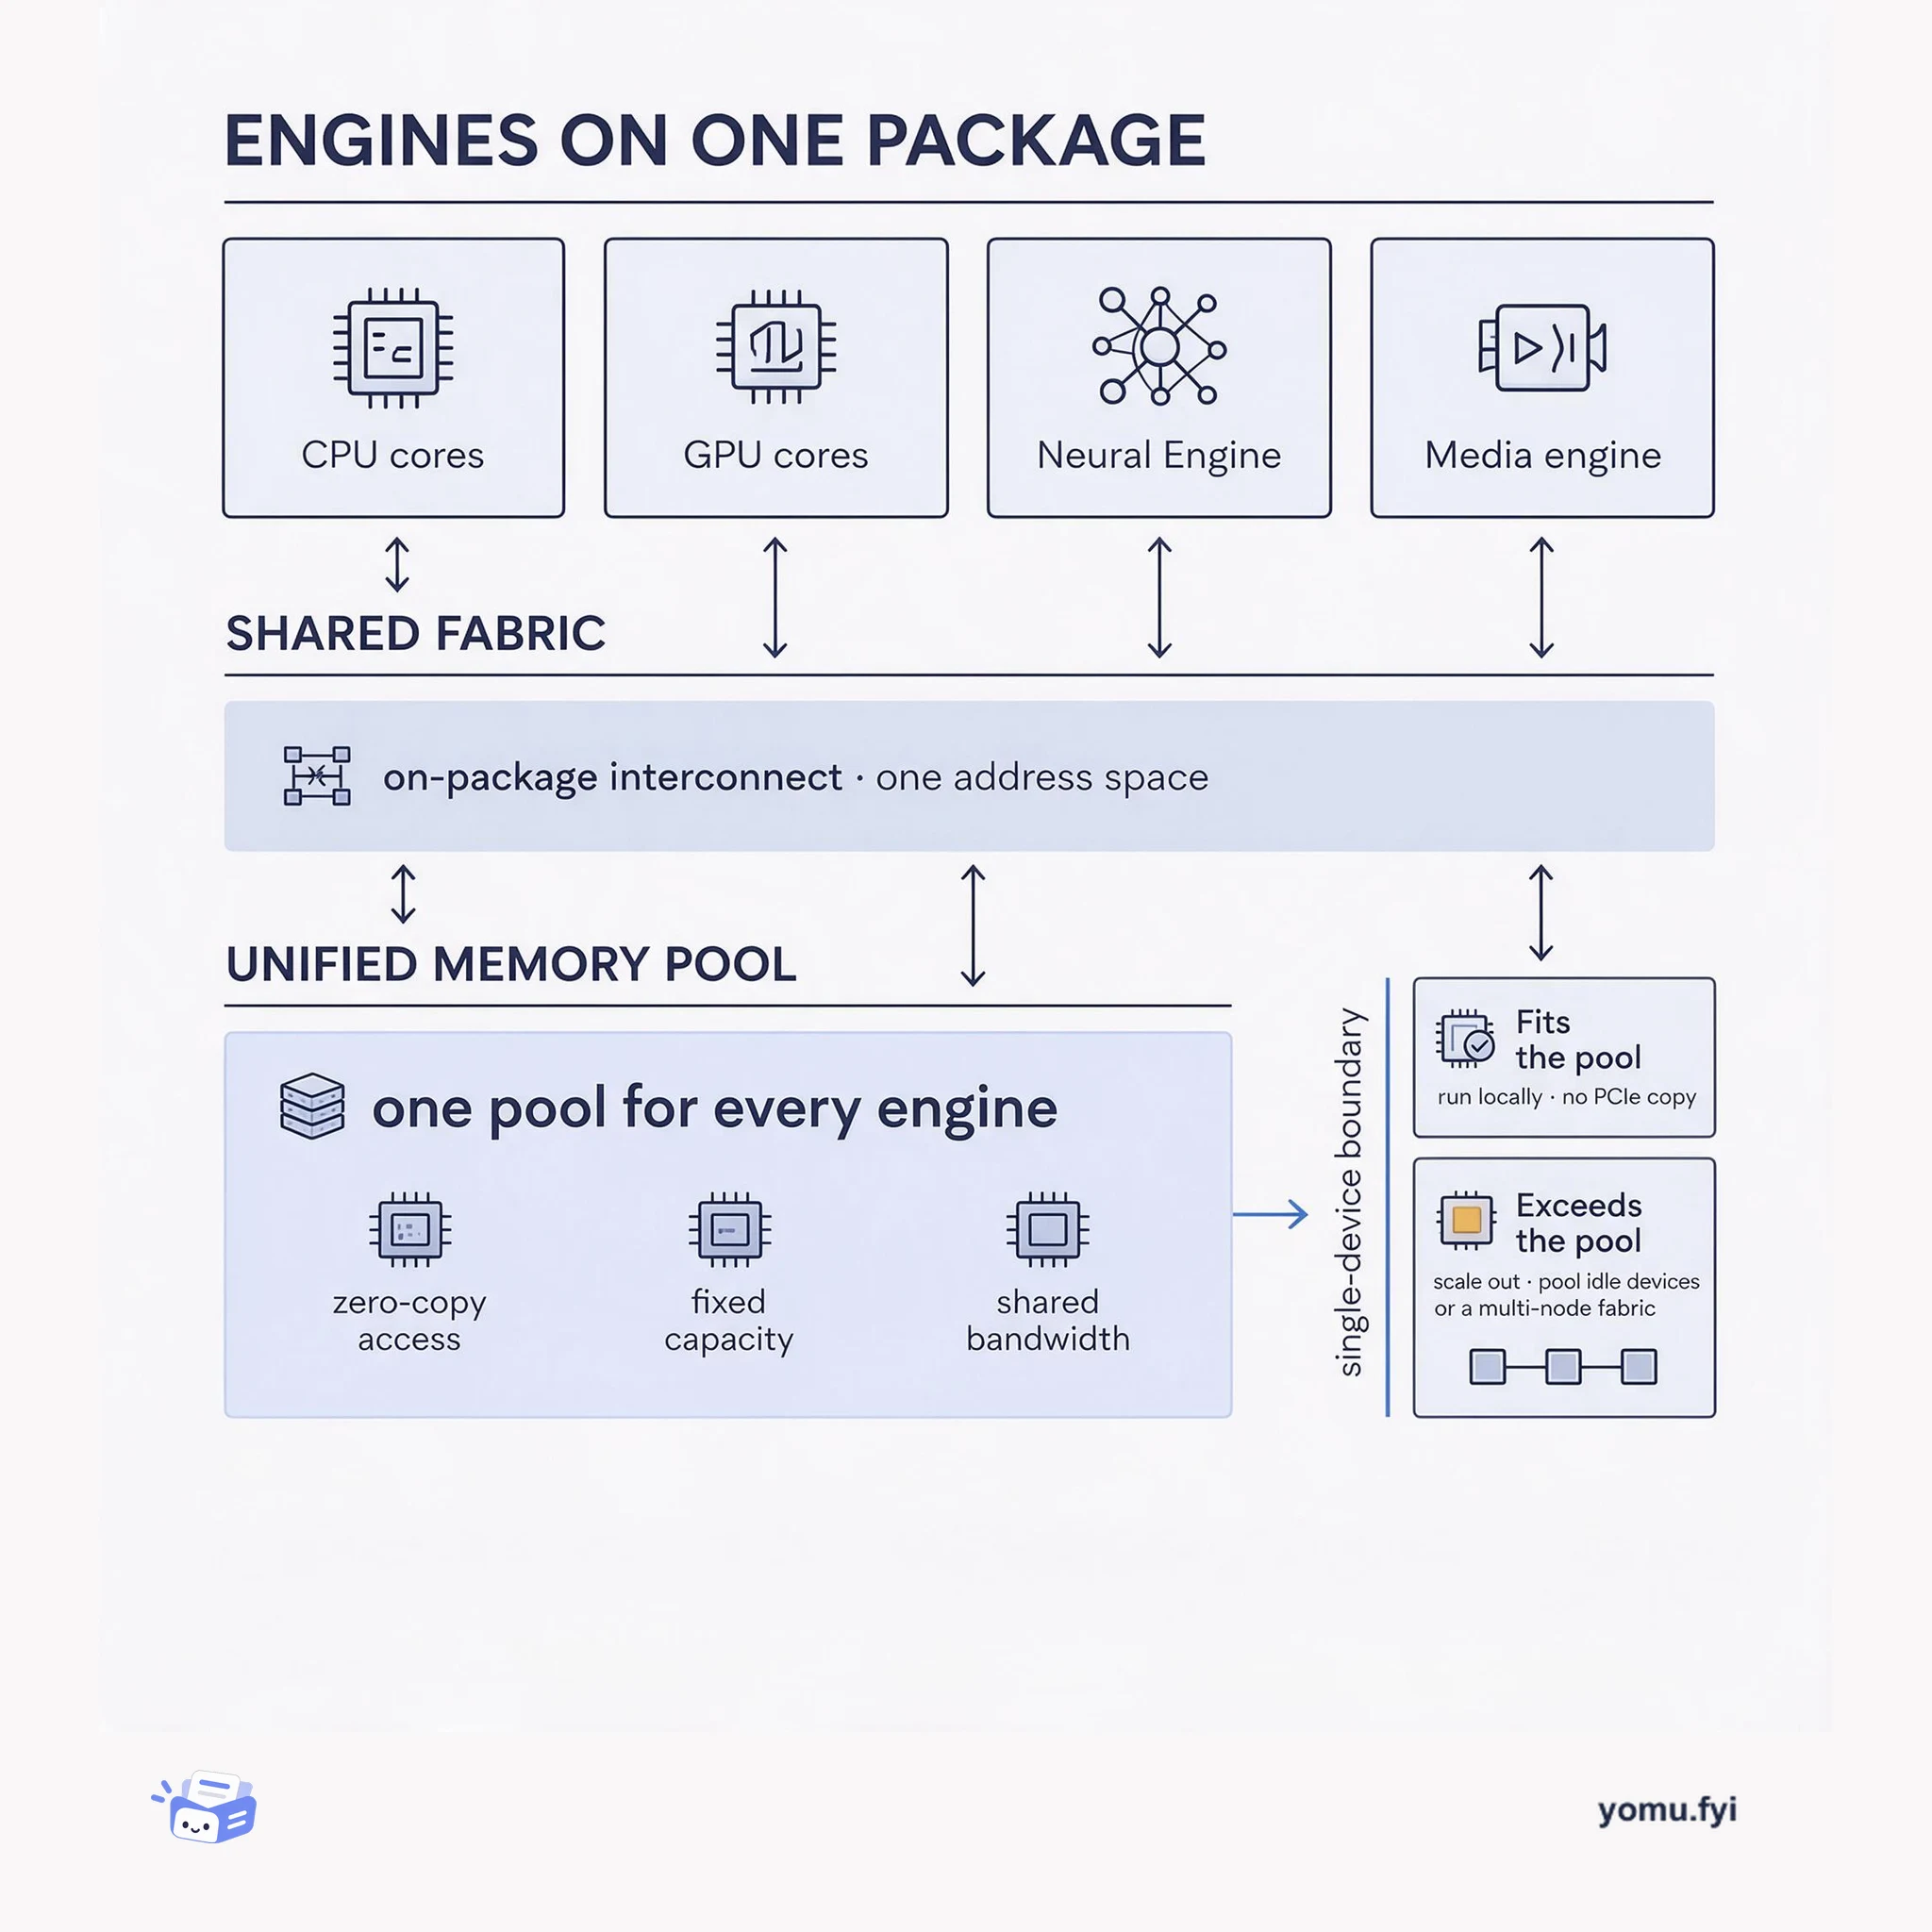
One Pool, Many Engines: The Architecture of Apple Silicon
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
 DatabricksBruce Fontaine, Pardis BeikzadehTutorial
The post describes systematic performance optimization to reduce fine-tuning time for the Qwen 3.8 27B model on AI Runtime from 7 hours 44 minutes to 1 hour 17 minutes, a 6x improvement. The baseline showed 98% GPU utilization, but torch traces revealed the CPU was stalling the GPU with too many small operations. Installing manually fused kernels such as flash-linear-attention and causal-conv1d reduced the number of GPU operations by 15x and improved training speed by 3.7x. Further gains came from switching from 2D padded batches to 1D packed tensors with correct position_ids, which reduced the number of batches by 36% and eliminated dynamic shape recompilation. The post emphasizes measuring what matters beyond GPU utilization and leveraging pre-built community kernels and efficient batching.
Fine-tuning a 27B parameter model on AI Runtime initially took 7h44m with 98% GPU utilization, but torch traces revealed the CPU was bottlenecked by too many small GPU operations. The post provides a step-by-step optimization guide using fused kernels and efficient batching.
Install flash-linear-attention and causal-conv1d Python packages to fuse many small GPU operations, reducing operation count by 15x. Then replace 2D padded batching with 1D packed tensors using correct position_ids to reduce batch count by 36% and avoid dynamic shape recompilation.
GPU utilization alone is misleading; torch traces reveal CPU-side stalls from too many small GPU operations.
Manually fused kernels like flash-linear-attention and causal-conv1d can reduce GPU operations by 15x and improve training speed by 3.7x.
Packing sequences into 1D tensors with correct position_ids reduces padding overhead and batch count, yielding a 1.6x speedup.
Standard GPU utilization only counts the percentage of time the GPU is active, not how efficiently it uses its cores. The CPU can stall the GPU by enqueuing too many small operations, causing underutilization even when utilization appears high.
Fused kernels combine multiple small GPU operations into one, reducing costly transfers between GPU memory and on-die memory and allowing more efficient scheduling. This reduced the number of operations by 15x and improved training speed by 3.7x.
It makes the input pipeline more complex and risks introducing errors that affect model quality, but it reduces batch count by 36% and eliminates dynamic shape recompilation, yielding a 1.6x speedup.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
