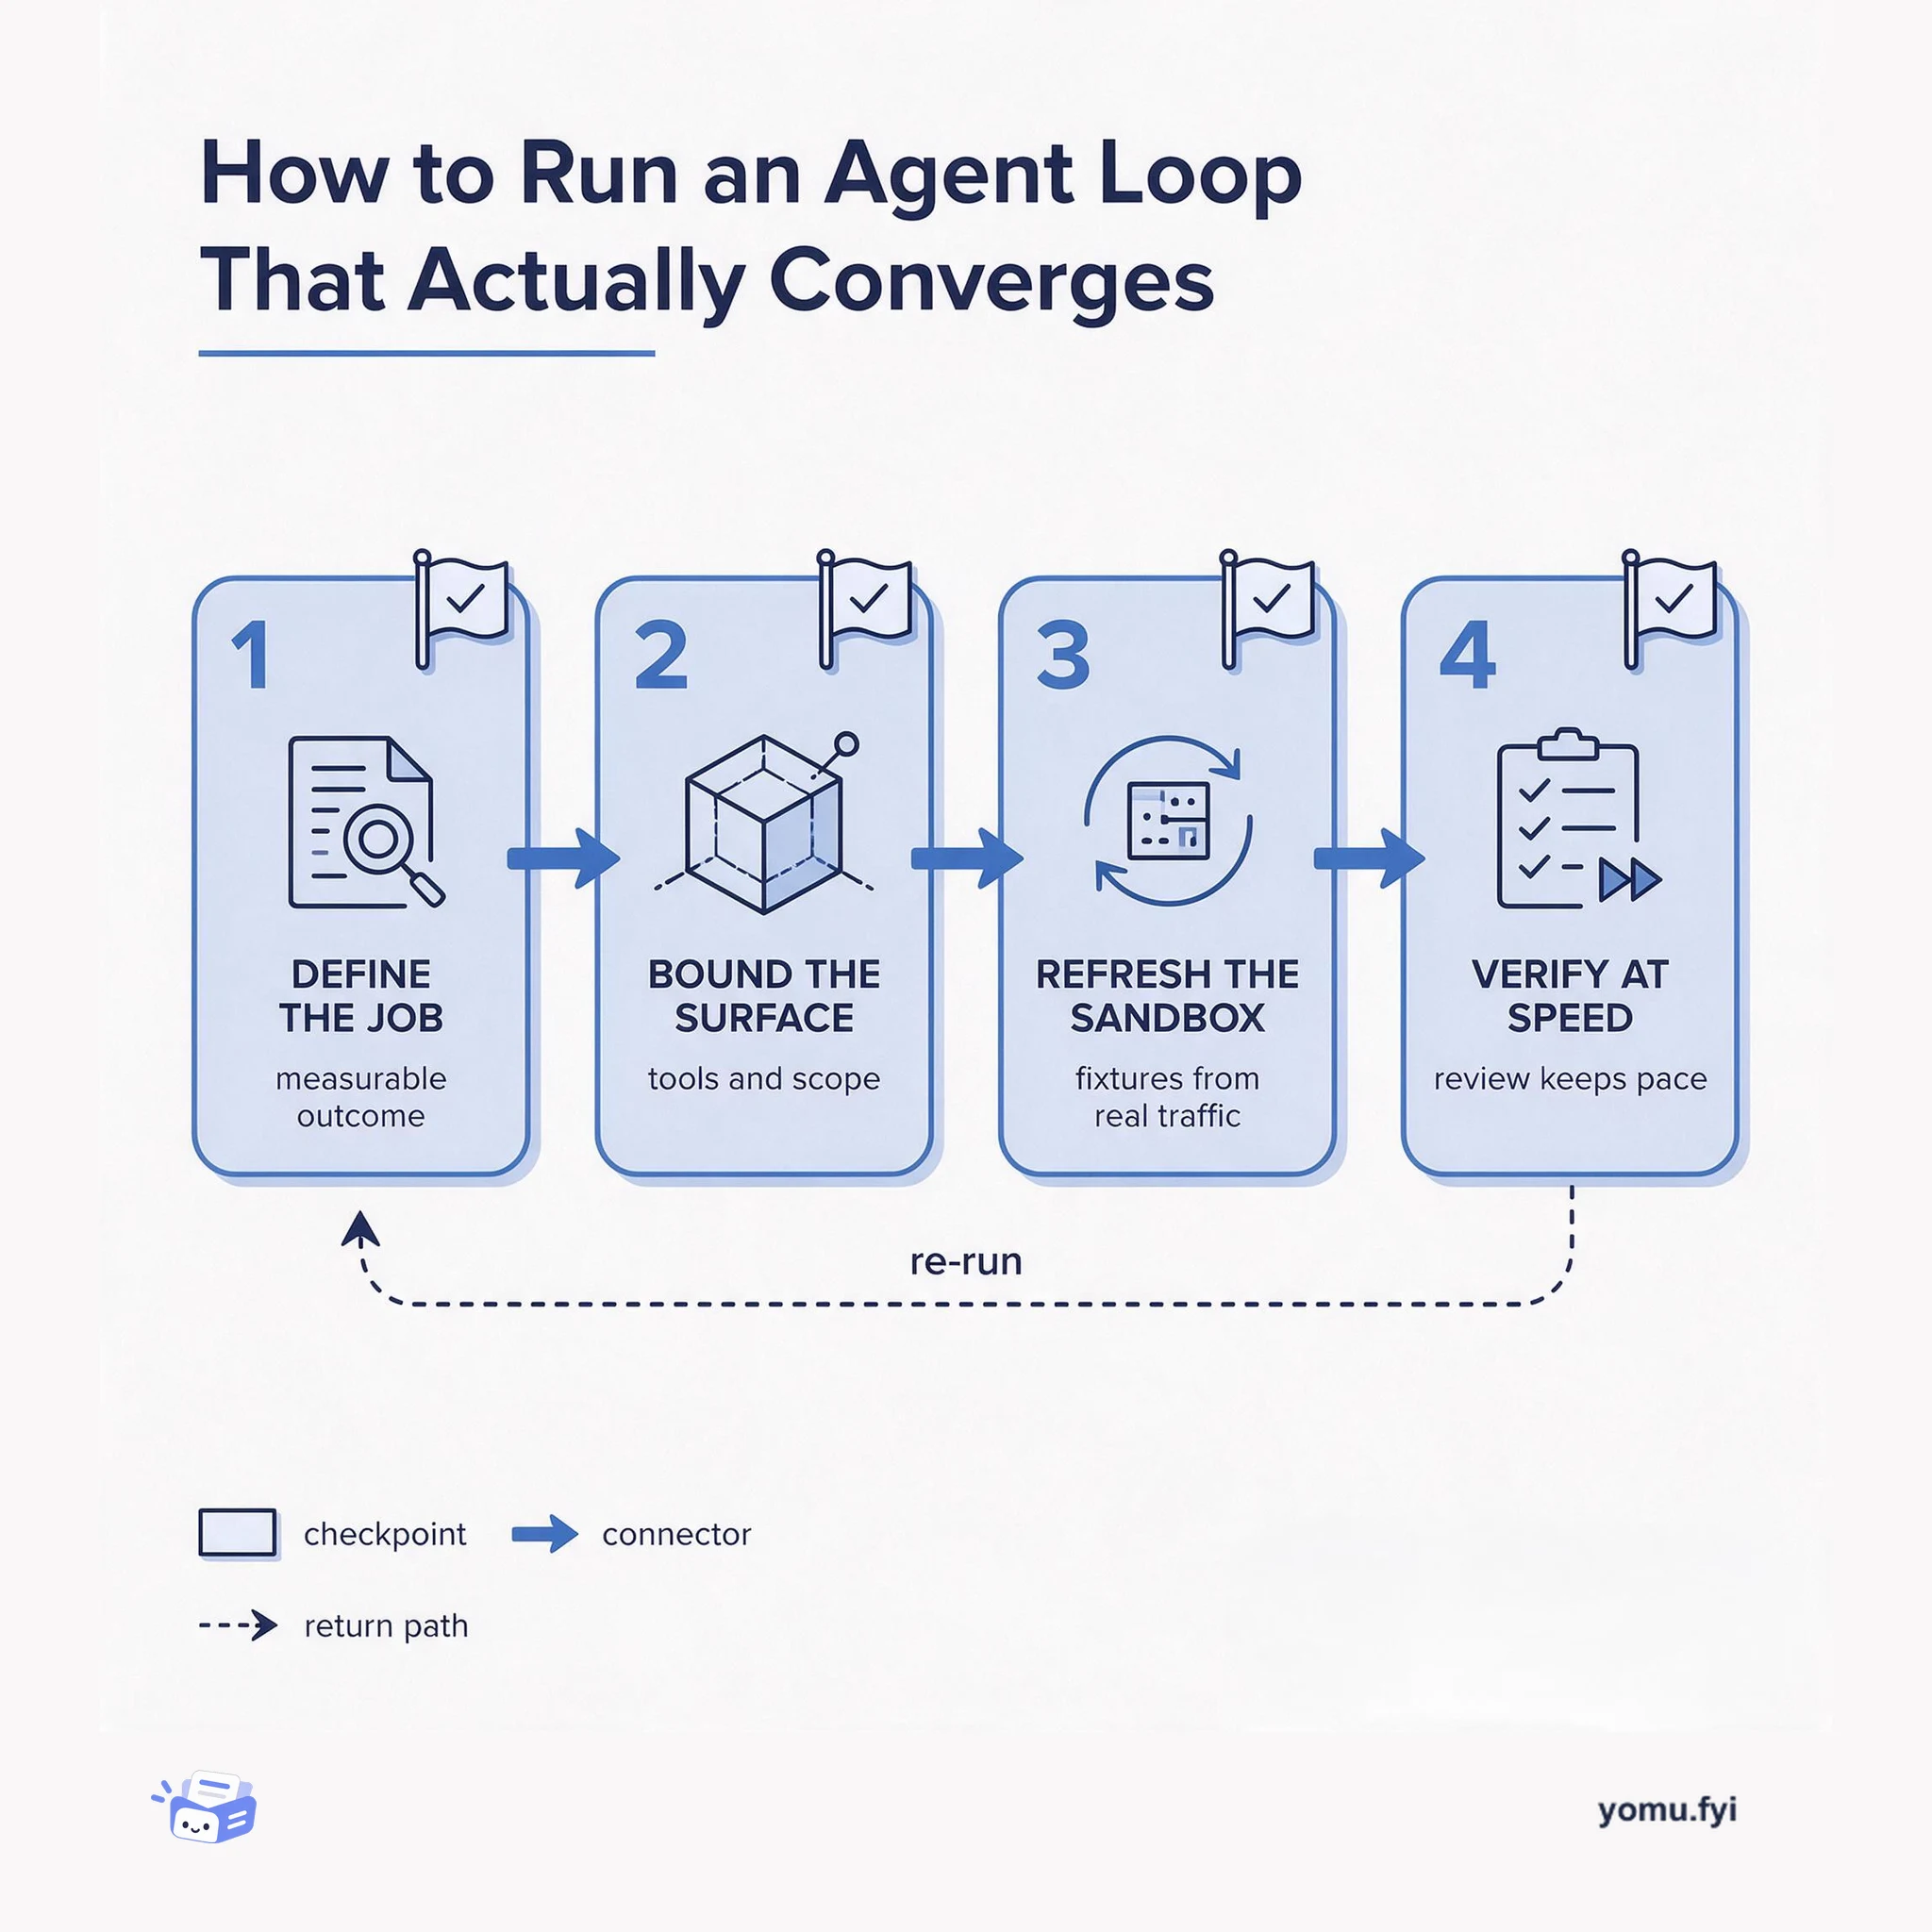
How to Run an Agent Loop That Actually Converges
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
 Hugging FaceRaahul Vignesh, Song Duong, Akhilesh Deepak Gotmare, Fernando Fernandes Neto, Jiahui Wang, Mayank Agarwal, nathan ranchin, Sergei Tilga, Sinoué GAD, Tim Seyde, Zetian Li, changyi yang, Simon Lee, Leonie Monigatti, Maxime Labonne, Karthik Macherla, Alfred Eng, Khoi Nguyen, Paul Pak, xx, Tarek Dakhran, Anthony MaltsevAnnouncement
LFM2.5-24B-A2B is a 24-billion-parameter reasoning model with only 2 billion active parameters per token, designed for fast, private on-device agents. It uses a Mixture-of-Experts architecture with 40 layers, 64 experts per block, and top-4 routing, combined with gated short convolutions and GQA. The model produces an explicit chain of thought before answering and supports tool calling and multi-step tasks. Pre-training scaled to 33 trillion tokens, followed by mid-training and a five-stage post-training pipeline including supervised fine-tuning, multi-domain distillation, and agentic reinforcement learning. On benchmarks, it leads or matches larger models on tool use and instruction following, achieving 48.09 on LiveClaw and 96.75 on IFEval, while decoding 184 tokens per second on an Apple M5 Max.
Running capable AI agents on-device requires models that are both efficient and effective at reasoning and tool use. Existing large models are too slow or require cloud infrastructure, while smaller models lack reasoning ability. LFM2.5-24B-A2B addresses this by using a Mixture-of-Experts architecture with only 2B active parameters per token, enabling fast inference on consumer hardware while maintaining strong agentic performance.
The model builds on LFM2-24B-A2B with the same architecture: 40 layers, 64 experts per MoE block with top-4 routing, and a hybrid of gated short convolutions and GQA. The context window was extended from 32K to 131K tokens, and the tokenizer vocabulary doubled from 65K to 128K tokens. Pre-training was scaled from ~17T to ~33T tokens. Mid-training added 2T tokens at 32K context and 300B tokens at 131K context, weighted toward reasoning, math, code, instruction following, and multilingual text. Post-training consisted of five stages: supervised fine-tuning, teacher specialization, multi-domain on-policy distillation (MOPD) on non-agentic tasks, MOPD on agentic tasks, and agentic reinforcement learning inside agent harnesses such as OpenClaw, Hermes Agent, Pi, and OpenCode.
LFM2.5-24B-A2B uses a Mixture-of-Experts architecture with 24B total parameters but only 2B active per token, making it efficient for on-device inference while maintaining strong reasoning and tool-use capabilities.
The model leads or matches larger models on five of eight tool-use and agentic benchmarks, including AutomationBench (27.69 vs next-best 8.72) and LiveClaw (48.09 vs 38.19), and leads all three instruction-following benchmarks.
Inference speed reaches 184 tokens/s on an Apple M5 Max and over 21K output tokens/s on a single NVIDIA B300 GPU, with day-one support across llama.cpp, MLX, vLLM, SGLang, and ONNX.
On an Apple M5 Max, it decodes 184 tokens per second, and on a Ryzen AI Max+ 395, it reaches 114 tokens per second. On a single NVIDIA B300 GPU, it achieves over 21K output tokens per second at high concurrency, making it the fastest model in its size class.
It is competitive with Qwen3.6-35B-A3B, which has ~50% more total and active parameters. It leads on five of eight tool-use and agentic benchmarks, including AutomationBench (27.69 vs 8.72) and LiveClaw (48.09 vs 38.19), but larger models keep an edge on knowledge-heavy and coding benchmarks.
Install transformers>=5.0.0, load the model from Hugging Face, and serve it behind any OpenAI-compatible backend. Then configure your agent harness (e.g., Hermes Agent) to point at the local server. The model supports tool use and multi-turn trajectories out of the box.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.
