Apache Pinot: From Event Stream to Resilient Query
Apache Pinot is a distributed real-time OLAP datastore for low-latency analytics. This architecture view shows how streams, processing, partitioning, indexed storage, and replica-aware serving fit together.
Apache Pinot sits at the serving layer between event pipelines and applications that need fast analytical answers. Kafka and Flink can deliver Schema Registry-compatible metrics, while Pinot uses partitioned, columnar, indexed data to support millisecond queries across large time ranges. Replica groups and pool-based instance assignment help preserve query and ingestion availability during zone failures. The diagram also highlights the Star-tree trade-off: faster aggregation queries can require substantially more storage.
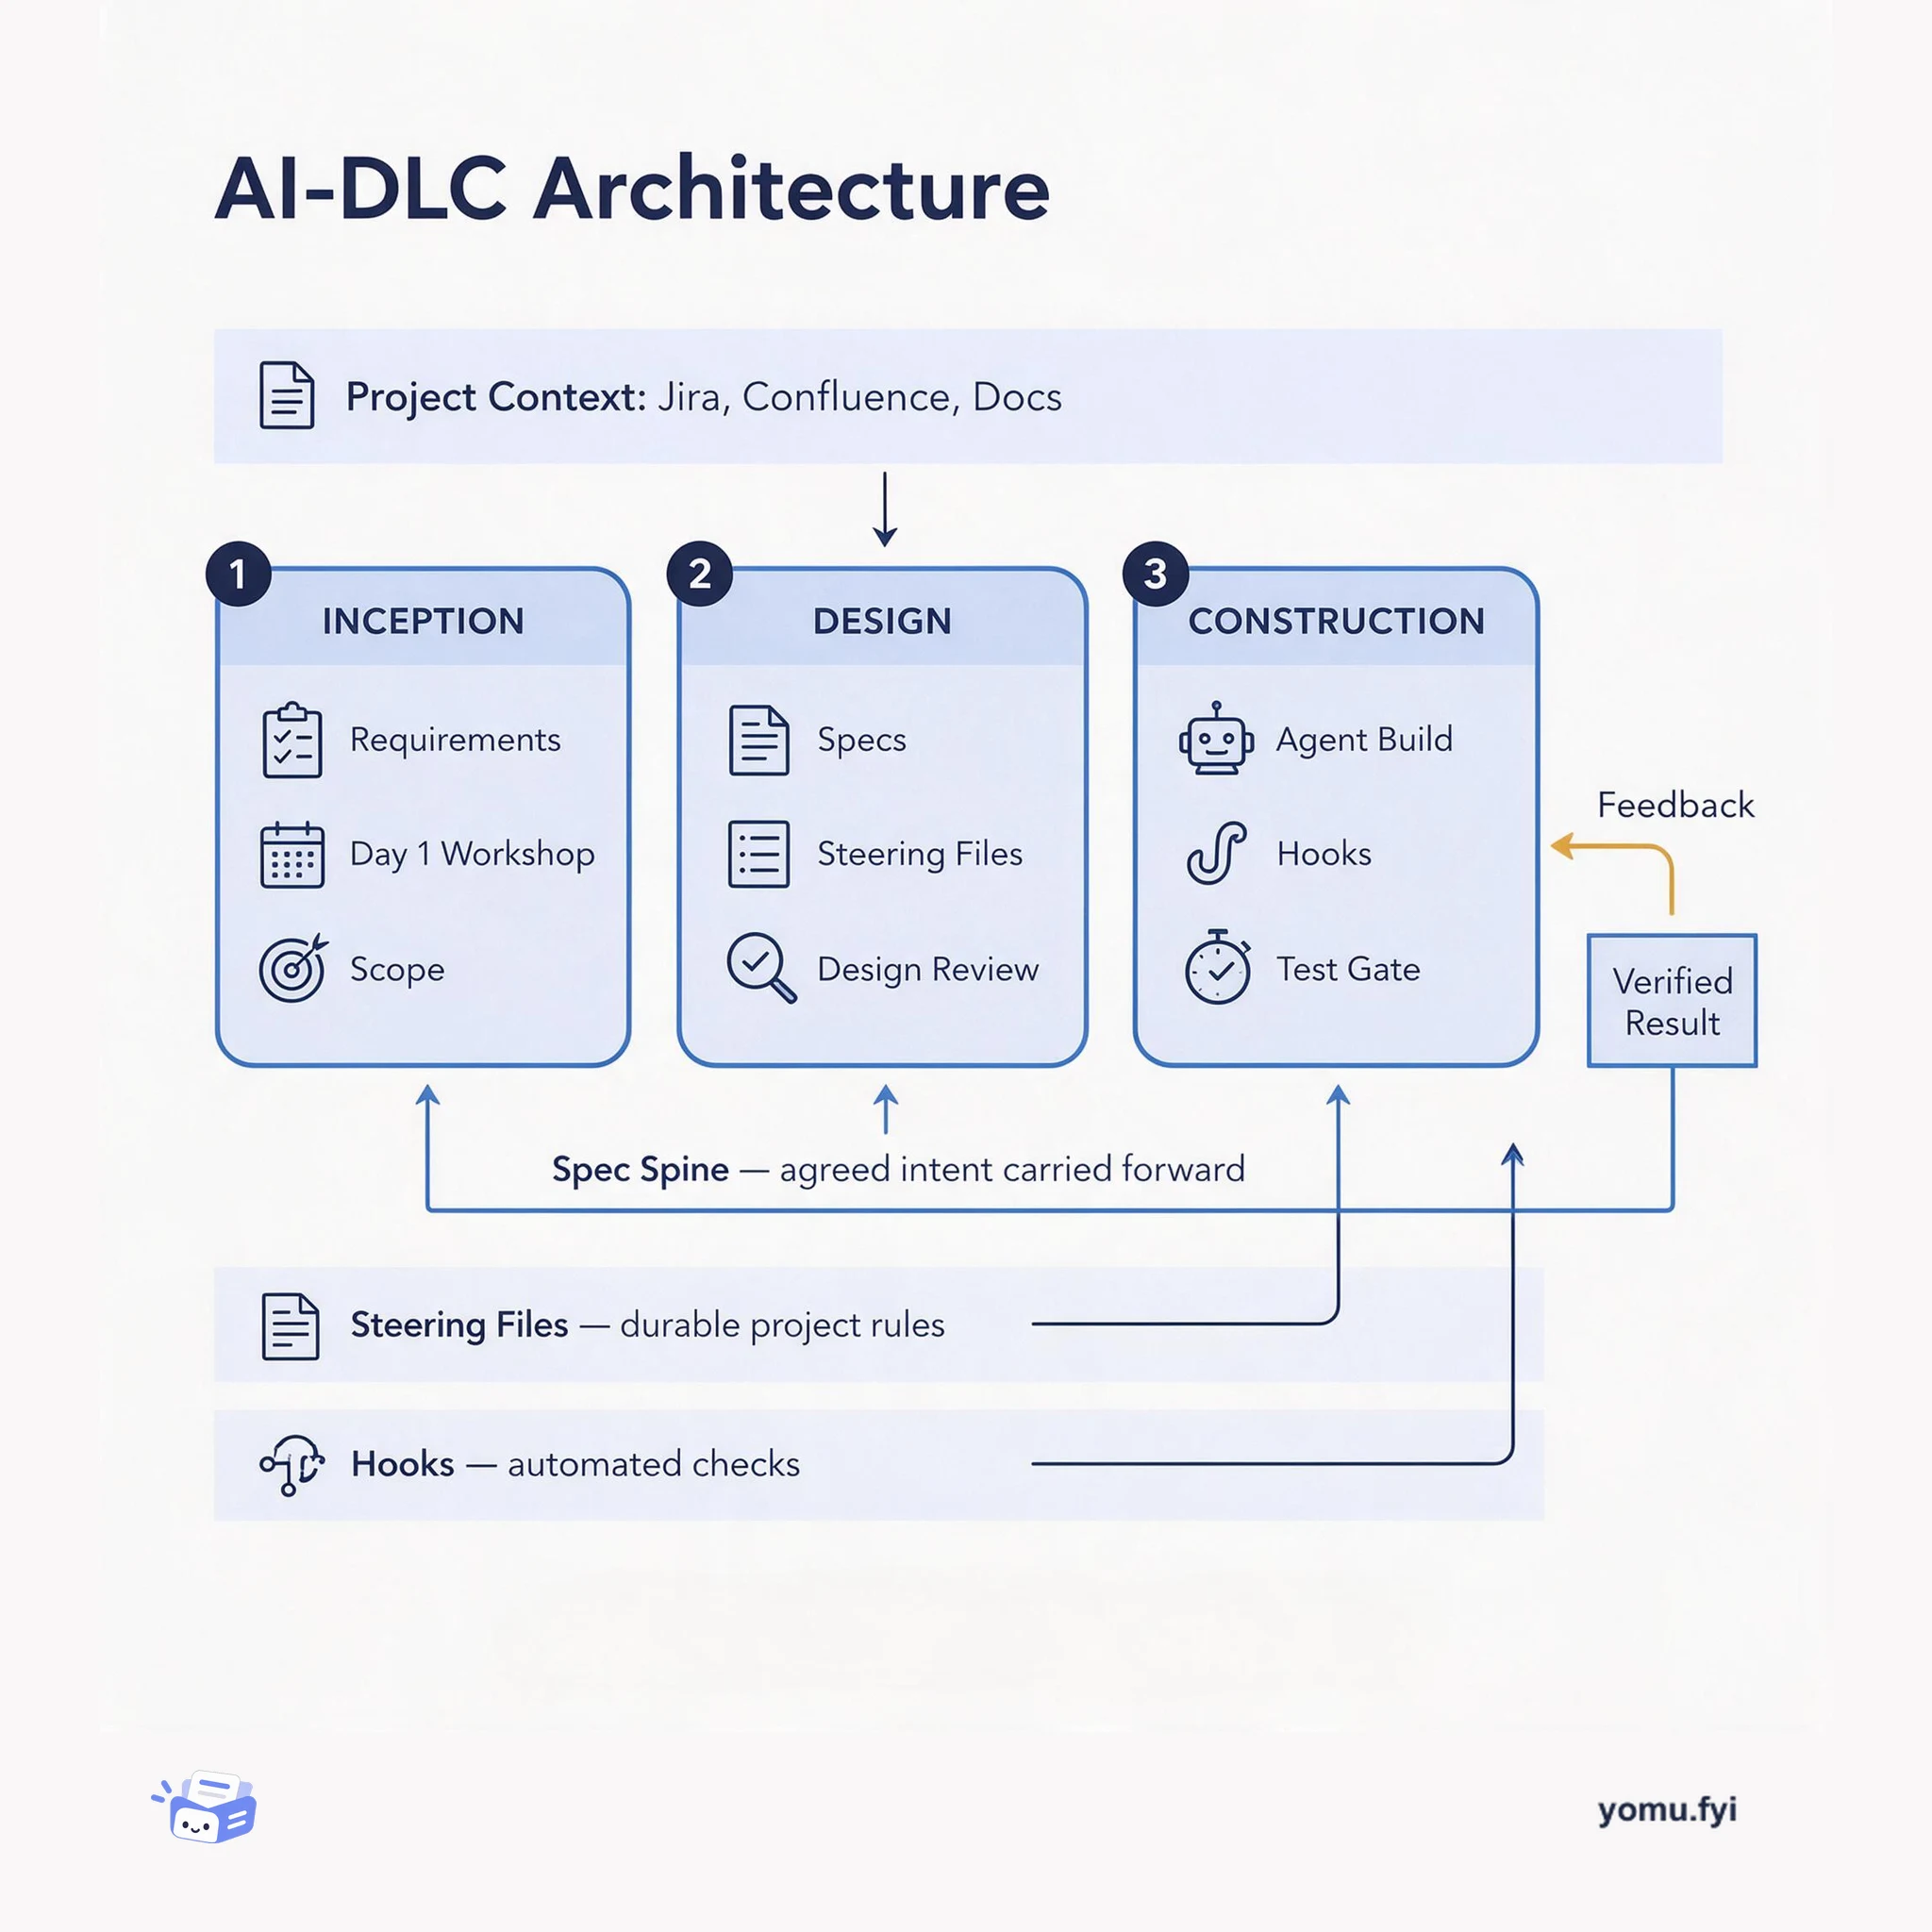
AI-DLC is an AI-driven development lifecycle that runs delivery through Inception, Design, and Construction, with specs, steering files, and hooks keeping agents aligned to agreed intent.
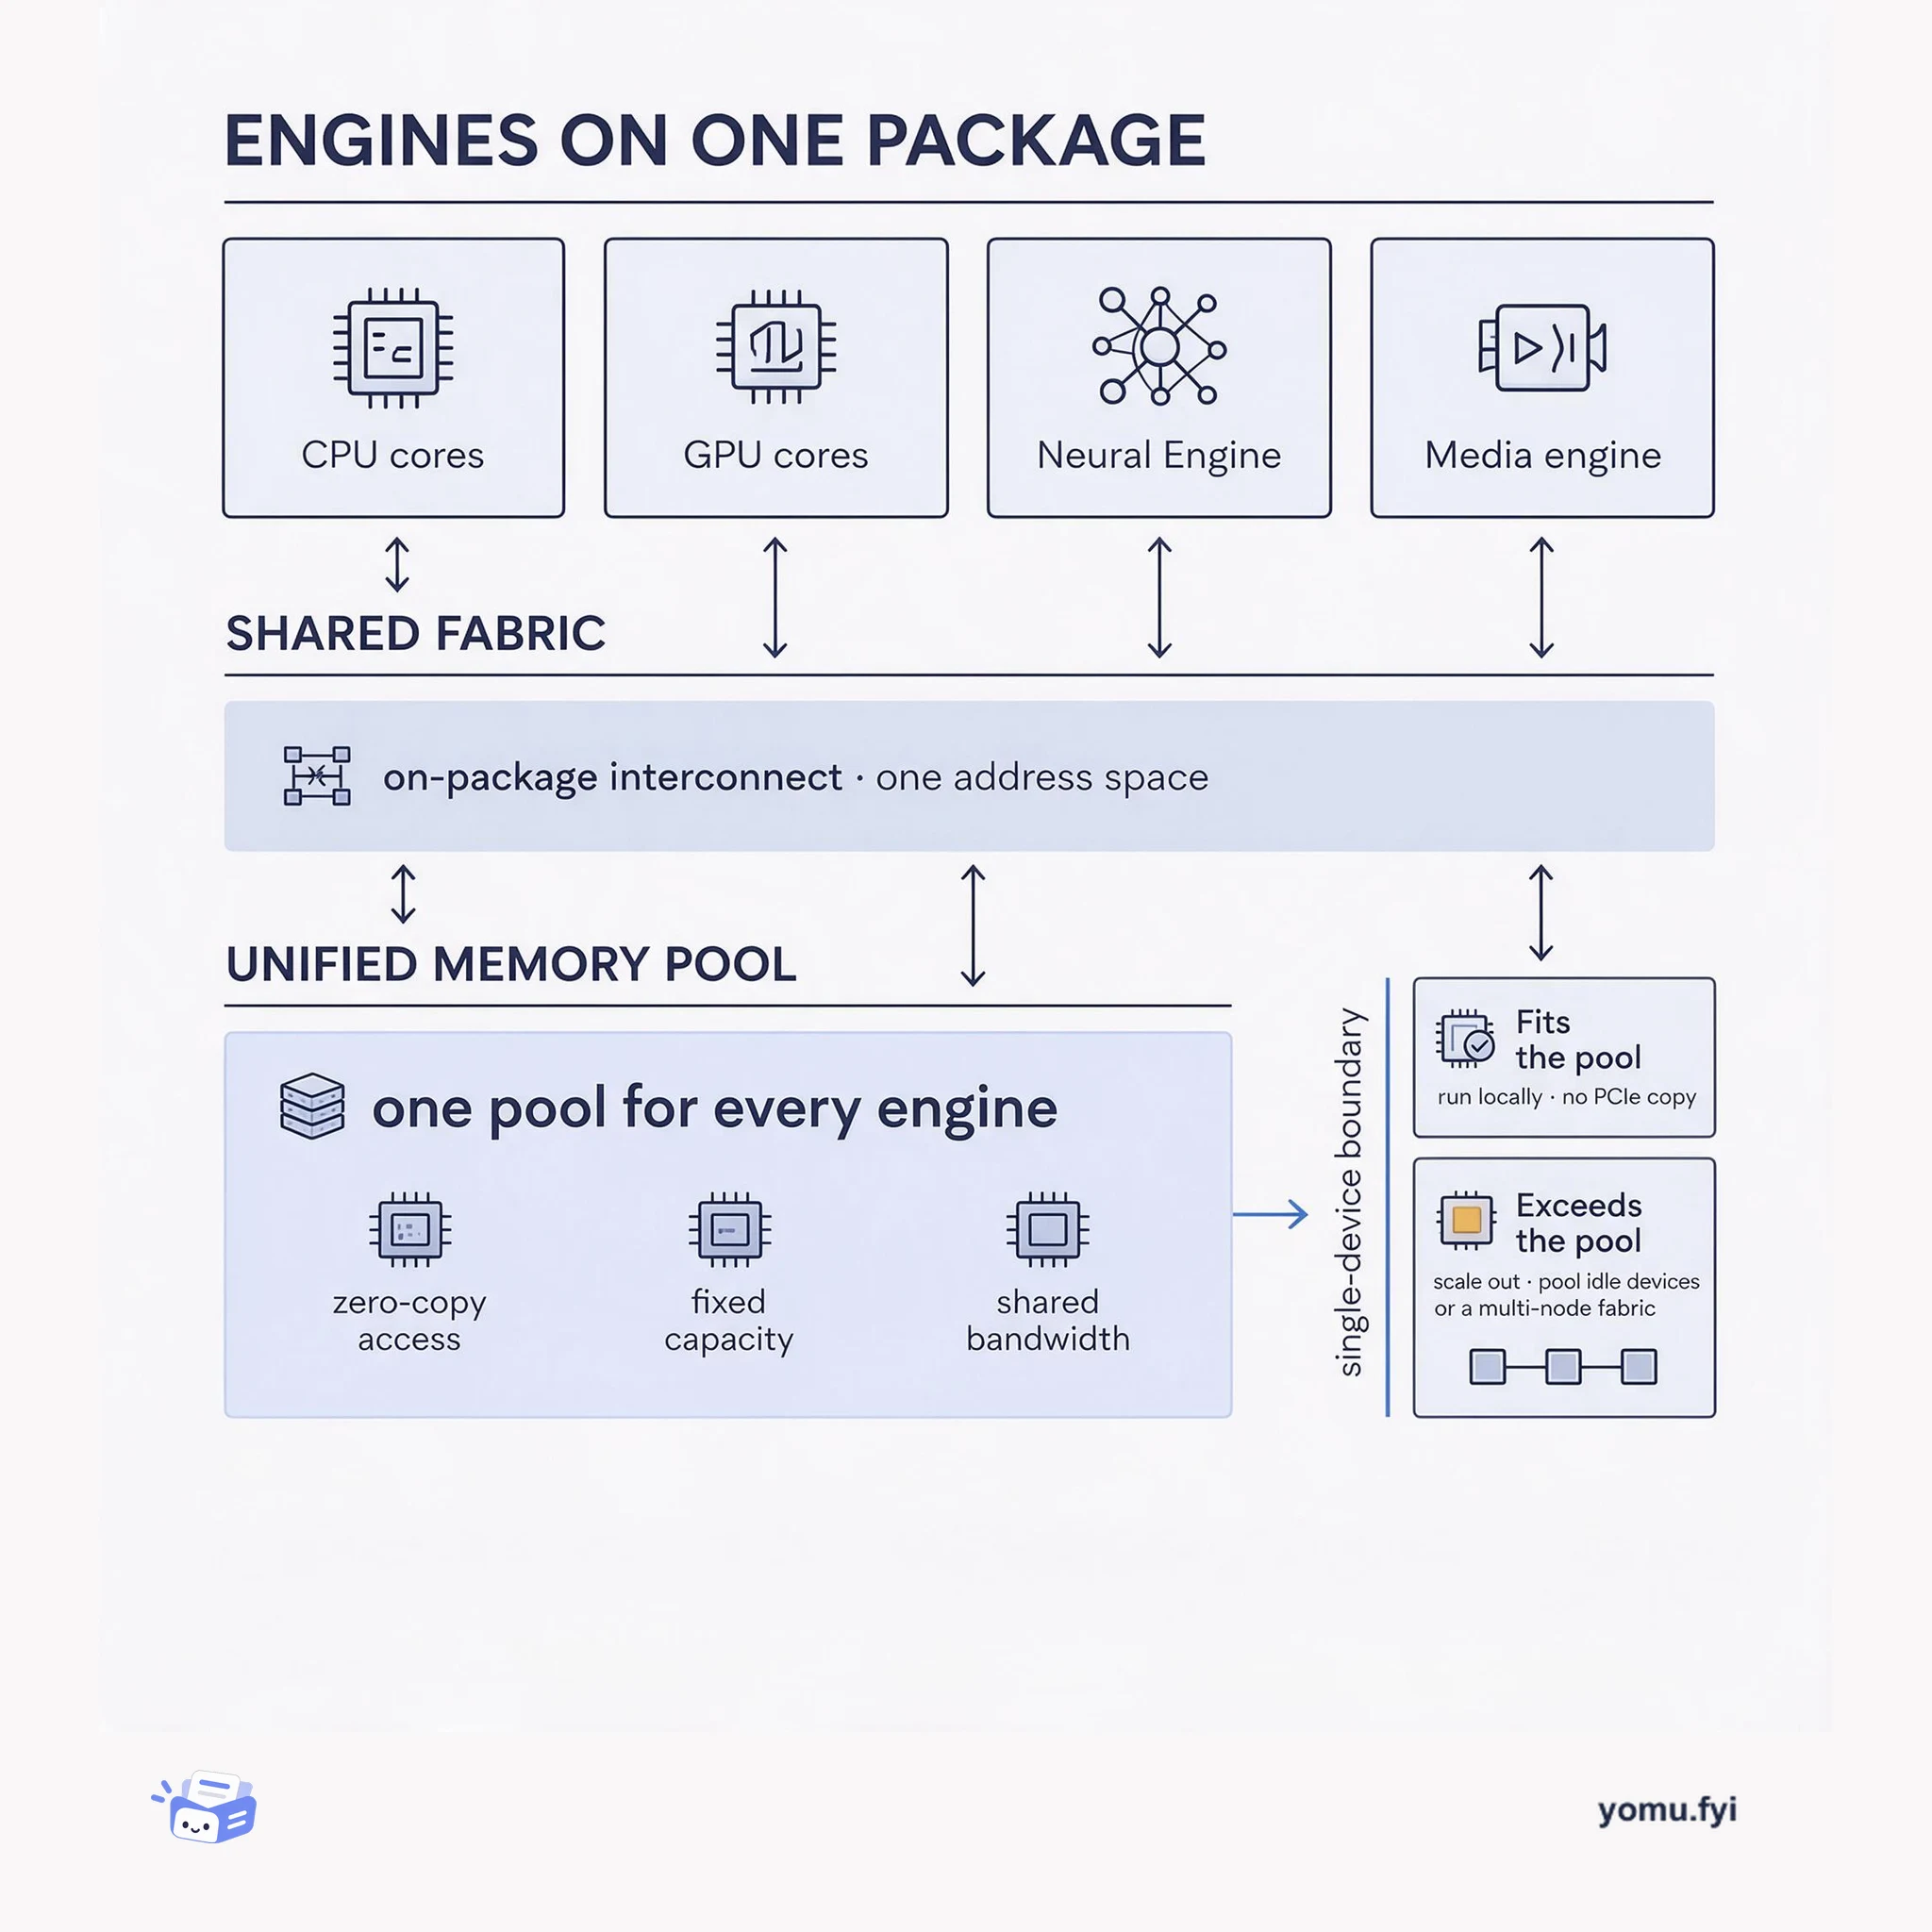
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
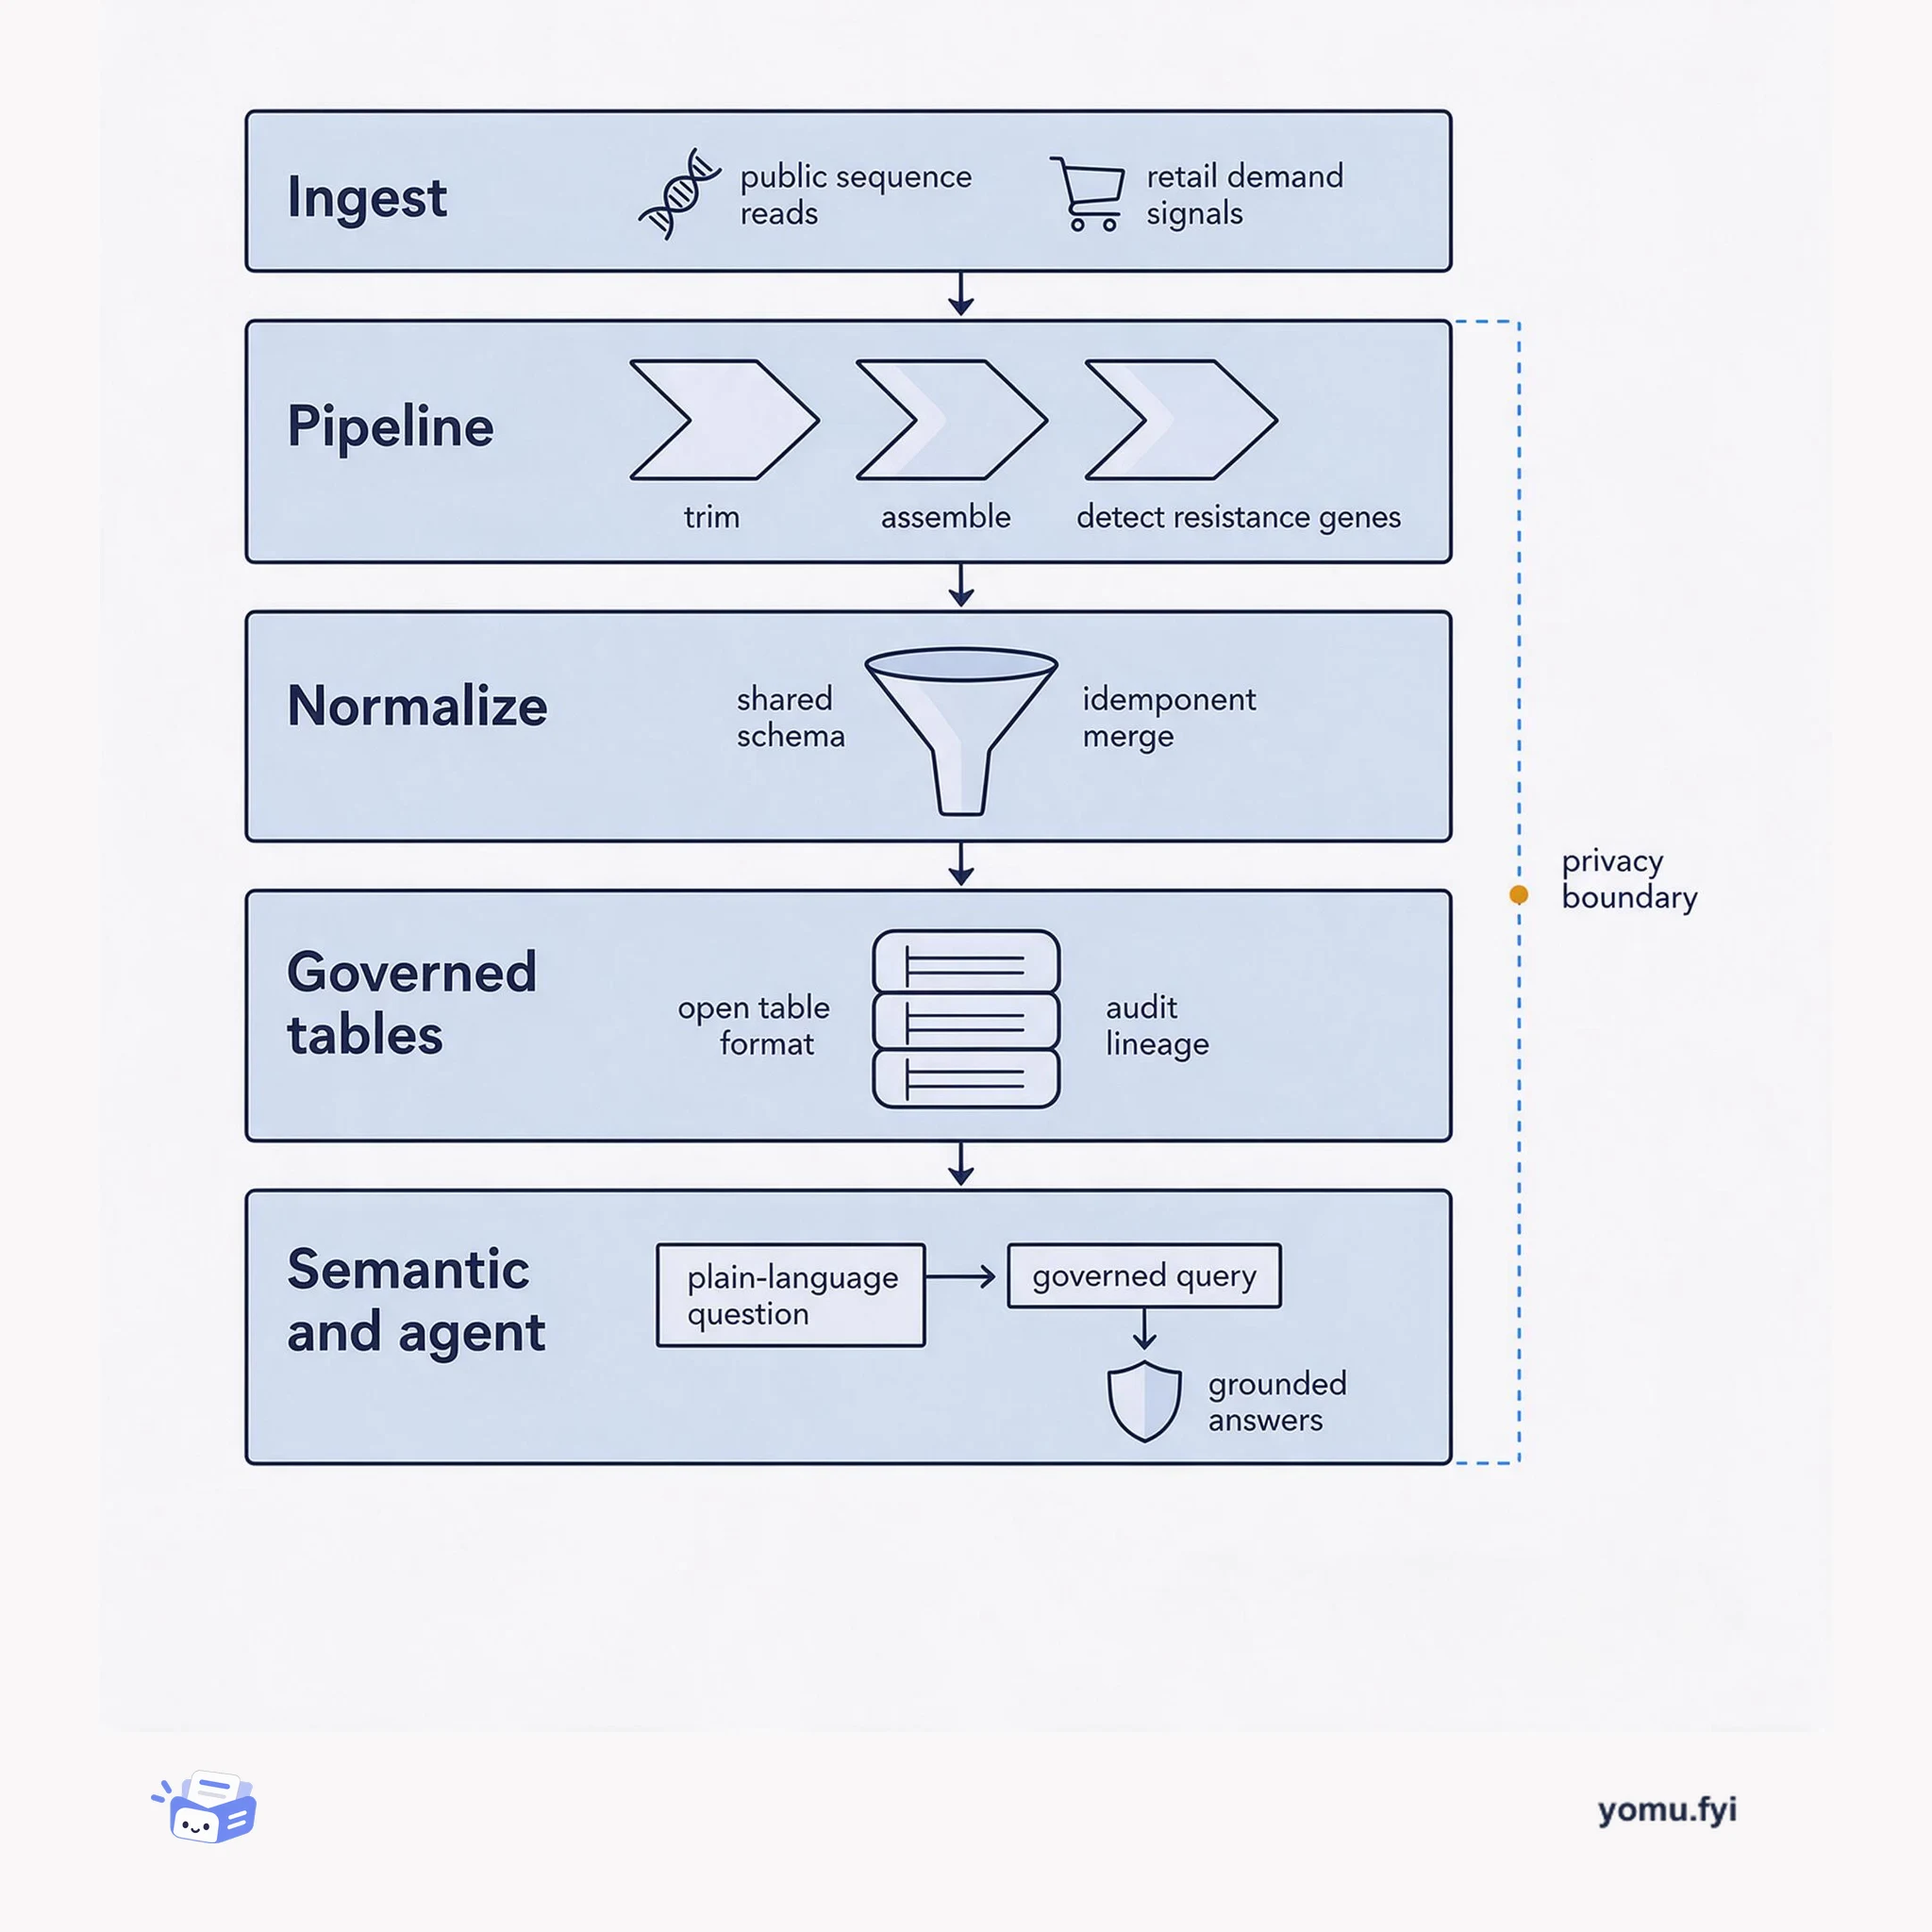
Antimicrobial resistance surveillance is a layered data architecture: raw reads and demand signals flow in, get normalized into governed tables, and answer plain-language queries. The diagram maps each boundary.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.