Clickhouse
The article examines whether ClickHouse is “winning” observability by separating the storage-and-query question from the broader work of collection, schema design, correlation, visualization, alerting, and investigation. It argues that ClickHouse fits telemetry because its columnar layout stores fields separately, enabling compression and allowing analytical queries to read only selected columns across millions or billions of events; ordering keys, sparse primary indexes, and data-skipping indexes further reduce work. The discussion covers both rich, wide events and conventional logs, traces, and metrics, and presents ClickStack as a combination of ClickHouse, an OpenTelemetry Collector, and a UI that preserves familiar workflows. The conclusion is qualified: ClickHouse has become the de facto storage and query engine for many teams and a strong default for large telemetry workloads, but it has not won observability as a whole, while full-text indexes, PromQL support, and broader product layers remain important.
 Cloudflare
's Big Pineapple platform, which powers 1.1.1.1 and other DNS services, stores over 250 billion cache entries simultaneously. To decrease fleet-wide memory consumption, engineers implemented five changes to in-memory cache data structures. Key modifications included swapping growable types like Vec and String for Box slices to eliminate capacity overhead, combining distinct record sections into a single list indexed by offsets, omitting redundant owner domain names, and serializing record bytes into contiguous buffers. In benchmarks, these optimizations decreased per-entry memory footprints by 56% while improving cache lookup latency by 19% and insert throughput by 43%. Across production instances, the rollout reduced working-set memory by approximately 100 terabytes.
 Databricks
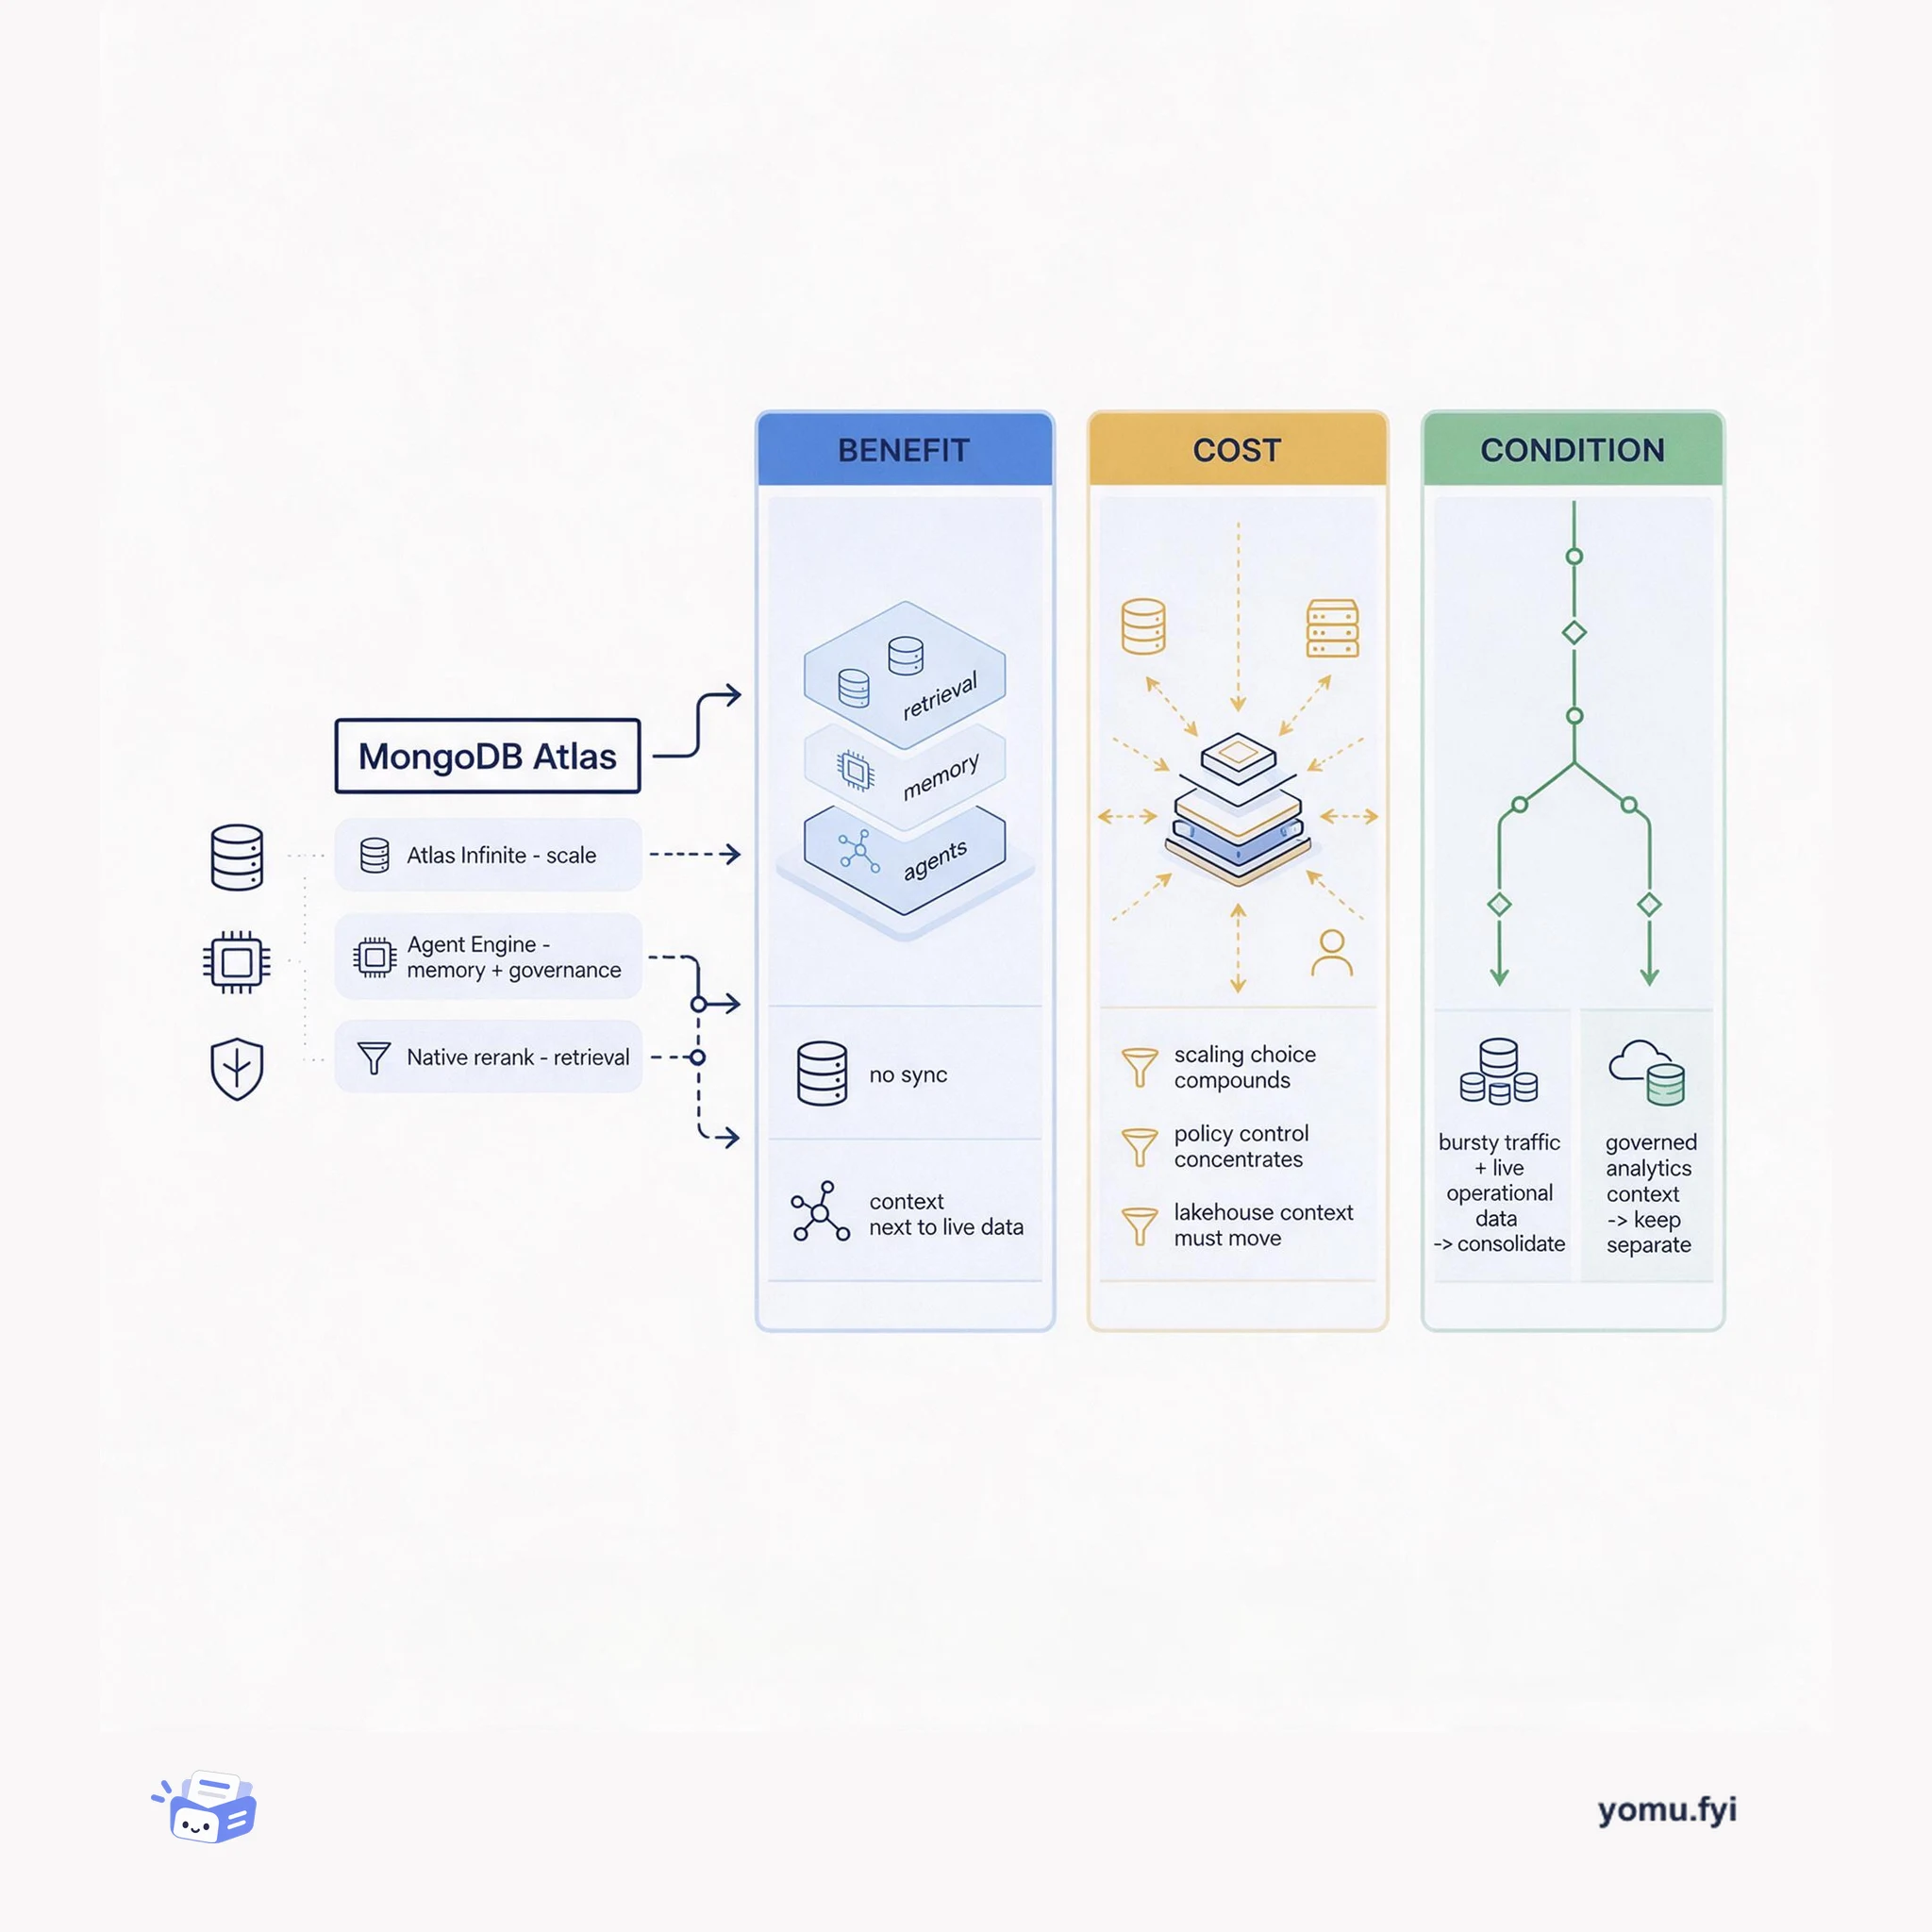
The post presents partner-built, industry-specific solutions on Databricks Lakebase for financial services, manufacturing and energy, retail and consumer sectors, travel and hospitality, healthcare and life sciences, communications and media, and the public sector. Lakebase is described as a serverless Postgres transactional database on the Databricks Data and AI Platform, combining operational and analytical workloads under unified governance and providing operational serving, agent memory, audit trails, and transactional runtime capabilities. Examples include regulation-change monitoring, AI-native claims operations, KYC and personalization accelerators, near-real-time fraud detection, telecom customer-lifecycle decisioning, and public-sector emergency Situation Reports, using components such as Unity Catalog, Lakeflow, Genie, Mosaic AI agents, and Agent Bricks. The stated outcome is production-ready acceleration from insight to action, including faster compliance response, claims adjudication in minutes, low-latency decisions, and reduced manual effort, with partners positioned to help scope pilots.
Databricks
The post presents Lakebase Postgres as a design for agent workloads that need isolated copies, restores, replicas, historical queries, and many short-lived databases without repeatedly moving large datasets. It contrasts conventional data-centric OLTP with a transaction-centric model in which PostgreSQL’s write-ahead log (WAL) is the source of truth, with LSNs making database history addressable. Lakebase splits compute, which runs standard Postgres and uses RAM and local NVMe caches, from storage, where safekeepers replicate WAL through quorum acknowledgements, a pageserver materializes pages, and object storage retains immutable history. Commits wait for replicated WAL acknowledgement, not page uploads, while reads request pages at an LSN. The design supports point-in-time queries, cheap branch or read-only compute, scale-to-zero suspension, and shared transactional and analytical access, while still relying on RAM and NVMe for performance.
 Red Hat
Shared GPU model pools allow platform teams to maximize utilization, but mixed workloads often contend for serving capacity with differing service requirements. Generally available in Red Hat AI Inference 3.5, llm-d flow control introduces explicit admission control prior to backend routing. An Endpoint Picker sits in the request path and evaluates active priority bands from highest to lowest integer values whenever pool saturation is detected. Saturation metrics combine per-replica queue depth and key-value cache pressure to determine when dispatch gates should engage. Once a priority band is admitted, tenant fairness policies distribute dispatch turns, and ordering rules select the next request to forward to a vLLM replica via Envoy.