How to Run an Agent Loop That Actually Converges
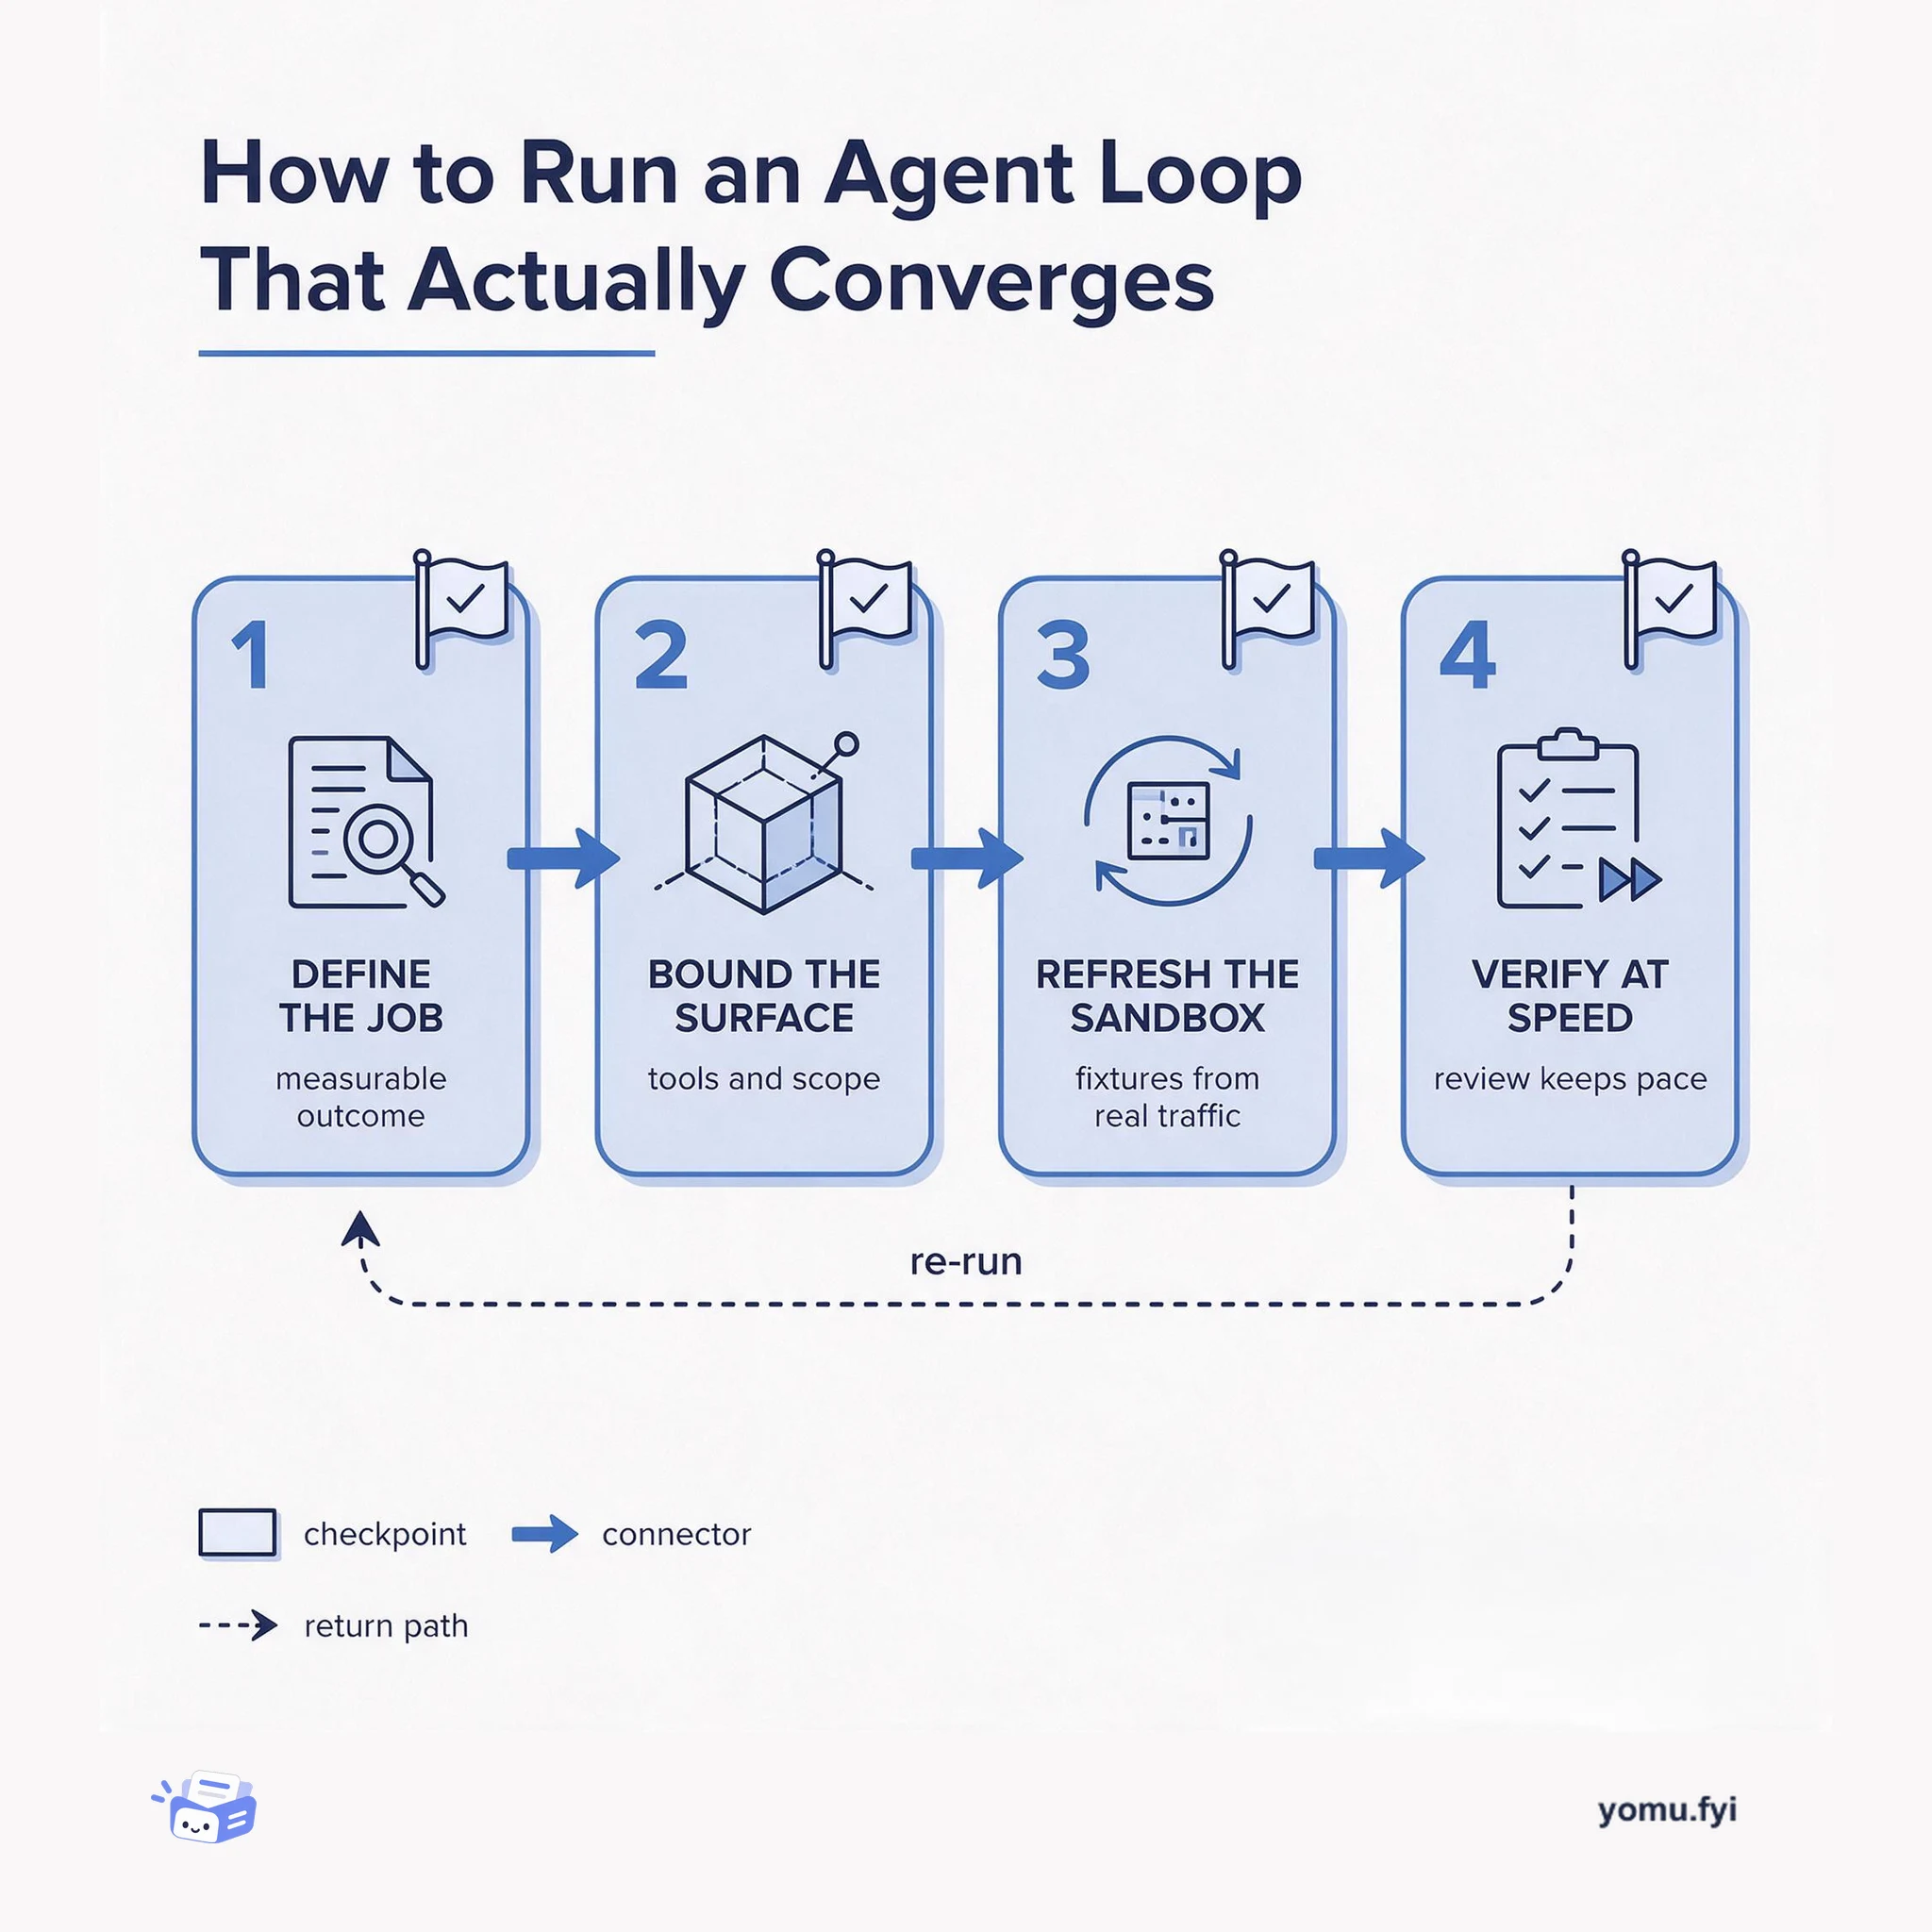
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
A five-checkpoint workflow for keeping BigQuery in the right lane: land and shape data once, tune partitions and history windows, and federate instead of copying.
BigQuery is a strong place to land, shape, and analyze large datasets, but it is not always the right place to serve them. This explainer walks through five checkpoints: land data once and tune partitions, clustering, and history windows before scaling compute; keep low-latency serving in a purpose-built store; federate across catalogs instead of duplicating tables; hold the boundary so only shaped data reaches the warehouse; and route pipeline telemetry back into BigQuery for observability. Each checkpoint pairs a concrete signal with the cost or latency it protects, so you can decide where BigQuery belongs in your own pipeline.
Not usually. Thumbtack generates embeddings into BigQuery with Airflow, then syncs them through managed reverse-ETL into pgvector tables on an existing Aurora Postgres cluster behind a query API. BigQuery does the batch shaping; the low-latency store does the serving.
Etsy moved listing data into clustered and partitioned BigQuery tables, cut the input history from two years to nine months, raised batch sizes and compute, added managed concurrency, and staggered Airflow tasks. Generation for 10 million users dropped from 21 days to three, and estimated cost per million users fell 94%.
Yes, through catalog federation. Databricks and Google Cloud use Apache Iceberg REST catalog APIs so BigQuery can read Unity Catalog-managed tables without duplication, with Unity Catalog policies, fine-grained access controls, and lineage still applying. Google Cloud's catalog federation is in preview for reads.
The posts behind it
 Databricks · · Explainer
The guide presents Google Cloud as a unified platform for enterprise data engineering, analytics, machine learning, and generative AI, with managed services intended to reduce infrastructure and integration work. It focuses on practical architectures, including medallion ETL pipelines that store Bronze, Silver, and Gold Delta Lake tables in Google Cloud Storage and expose Gold data to BigQuery through an optimized connector. For streaming workloads, Cloud Pub/Sub supplies ingestion while Apache Spark Structured Streaming processes continuous micro-batches; together with Delta Lake ACID transactions, this supports exactly-once results despite duplicates or out-of-order messages. The text also describes Cloud Run and Cloud Functions for containerized or event-driven workloads, and identifies retrieval-augmented generation applications on Vertex AI as a common starting point for generative AI. It concludes that integrated service combinations, rather than isolated tools, are the central strategic advantage for organizations building evolving data and AI platforms on Google Cloud.
 Thumbtack · · Explainer
Thumbtack describes a vector platform that lets ML engineers stand up production vector search without separately negotiating database access, building ETL, or writing a query service. The design uses an existing Aurora Postgres cluster with pgvector, while Airflow jobs generate embeddings into BigQuery and managed reverse-ETL syncs them into vector tables; a query API validates inputs and returns ranked results. Three principles guide the layers: reuse trusted infrastructure, treat embeddings as ordinary data flowing through established pipelines, and lower adoption costs for subsequent teams. Production examples include semantic customer-support escalation using cosine similarity and an internal knowledge assistant combining vector retrieval, often with keyword search, before a language model responds; planned directions include self-serve provisioning, vector-backed feature retrieval, and framework-neutral agent memory.
 Etsy · · Problem & solution
Etsy uses Kafka streams to provide fresh features and embeddings for machine learning models, which infer shopper intent and listing meaning from visits and listing data. Previously, engineers manually assembled Java and YAML applications, selected schemas and base classes, and handled testing and local execution. Etsy introduced conversational Kafka Skills that use language models to interpret requests, pass structured inputs into versioned scaffolding and validation tools, run applications locally, and open pull requests. Telemetry records Skill invocation and pull-request completion through protobuf messages in Kafka and BigQuery, while least-privilege ACLs, repository permissions, and deployment controls constrain agent actions. Initial adoption was low because developers did not know the Skills existed, so Etsy added vocabulary-specific and repository-level entry points; it now has Skills for seven Kafka workflows and is focusing on discoverability.
Databricks · · AnnouncementDatabricks and Google Cloud announce bidirectional catalog federation that lets customers access the same data from Unity Catalog or BigQuery without duplication. The interoperability uses Apache Iceberg REST catalog APIs, enabling both platforms to read and write the same tables through a common open interface. Google Cloud's catalog federation is in preview for reading Unity Catalog-managed tables from BigQuery, while Google Cloud's Lakehouse federation is in private preview for Databricks users to govern and read foreign Iceberg tables. Unity Catalog's policies, fine-grained access controls, and lineage tracking apply to federated data, and users can query it with Genie using natural language. The announcement positions open standards as a path to interoperability across data platforms and previews future catalog metadata exchange through Iceberg REST catalog APIs.
Etsy · · ExplainerEtsy is experimenting with large language models (LLMs) to create anonymous buyer profiles from browsing and purchasing behavior, capturing interests such as styles, categories, and shopping missions. The pipeline combines recent searches, item views, purchases, favorites, session data, and listing information from internal feature-store and BigQuery sources, then prompts an LLM to generate structured profiles with explanations and confidence information. To scale processing, Etsy moved listing data to clustered and partitioned BigQuery tables, shortened input history from two years to nine months, increased batch sizes and compute, added managed concurrency, and used Airflow to stagger tasks. For 10 million users, these changes reduced generation time from 21 days to three and cut estimated cost per million users by 94%; experiments apply profiles to query rewriting and refinement pills.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
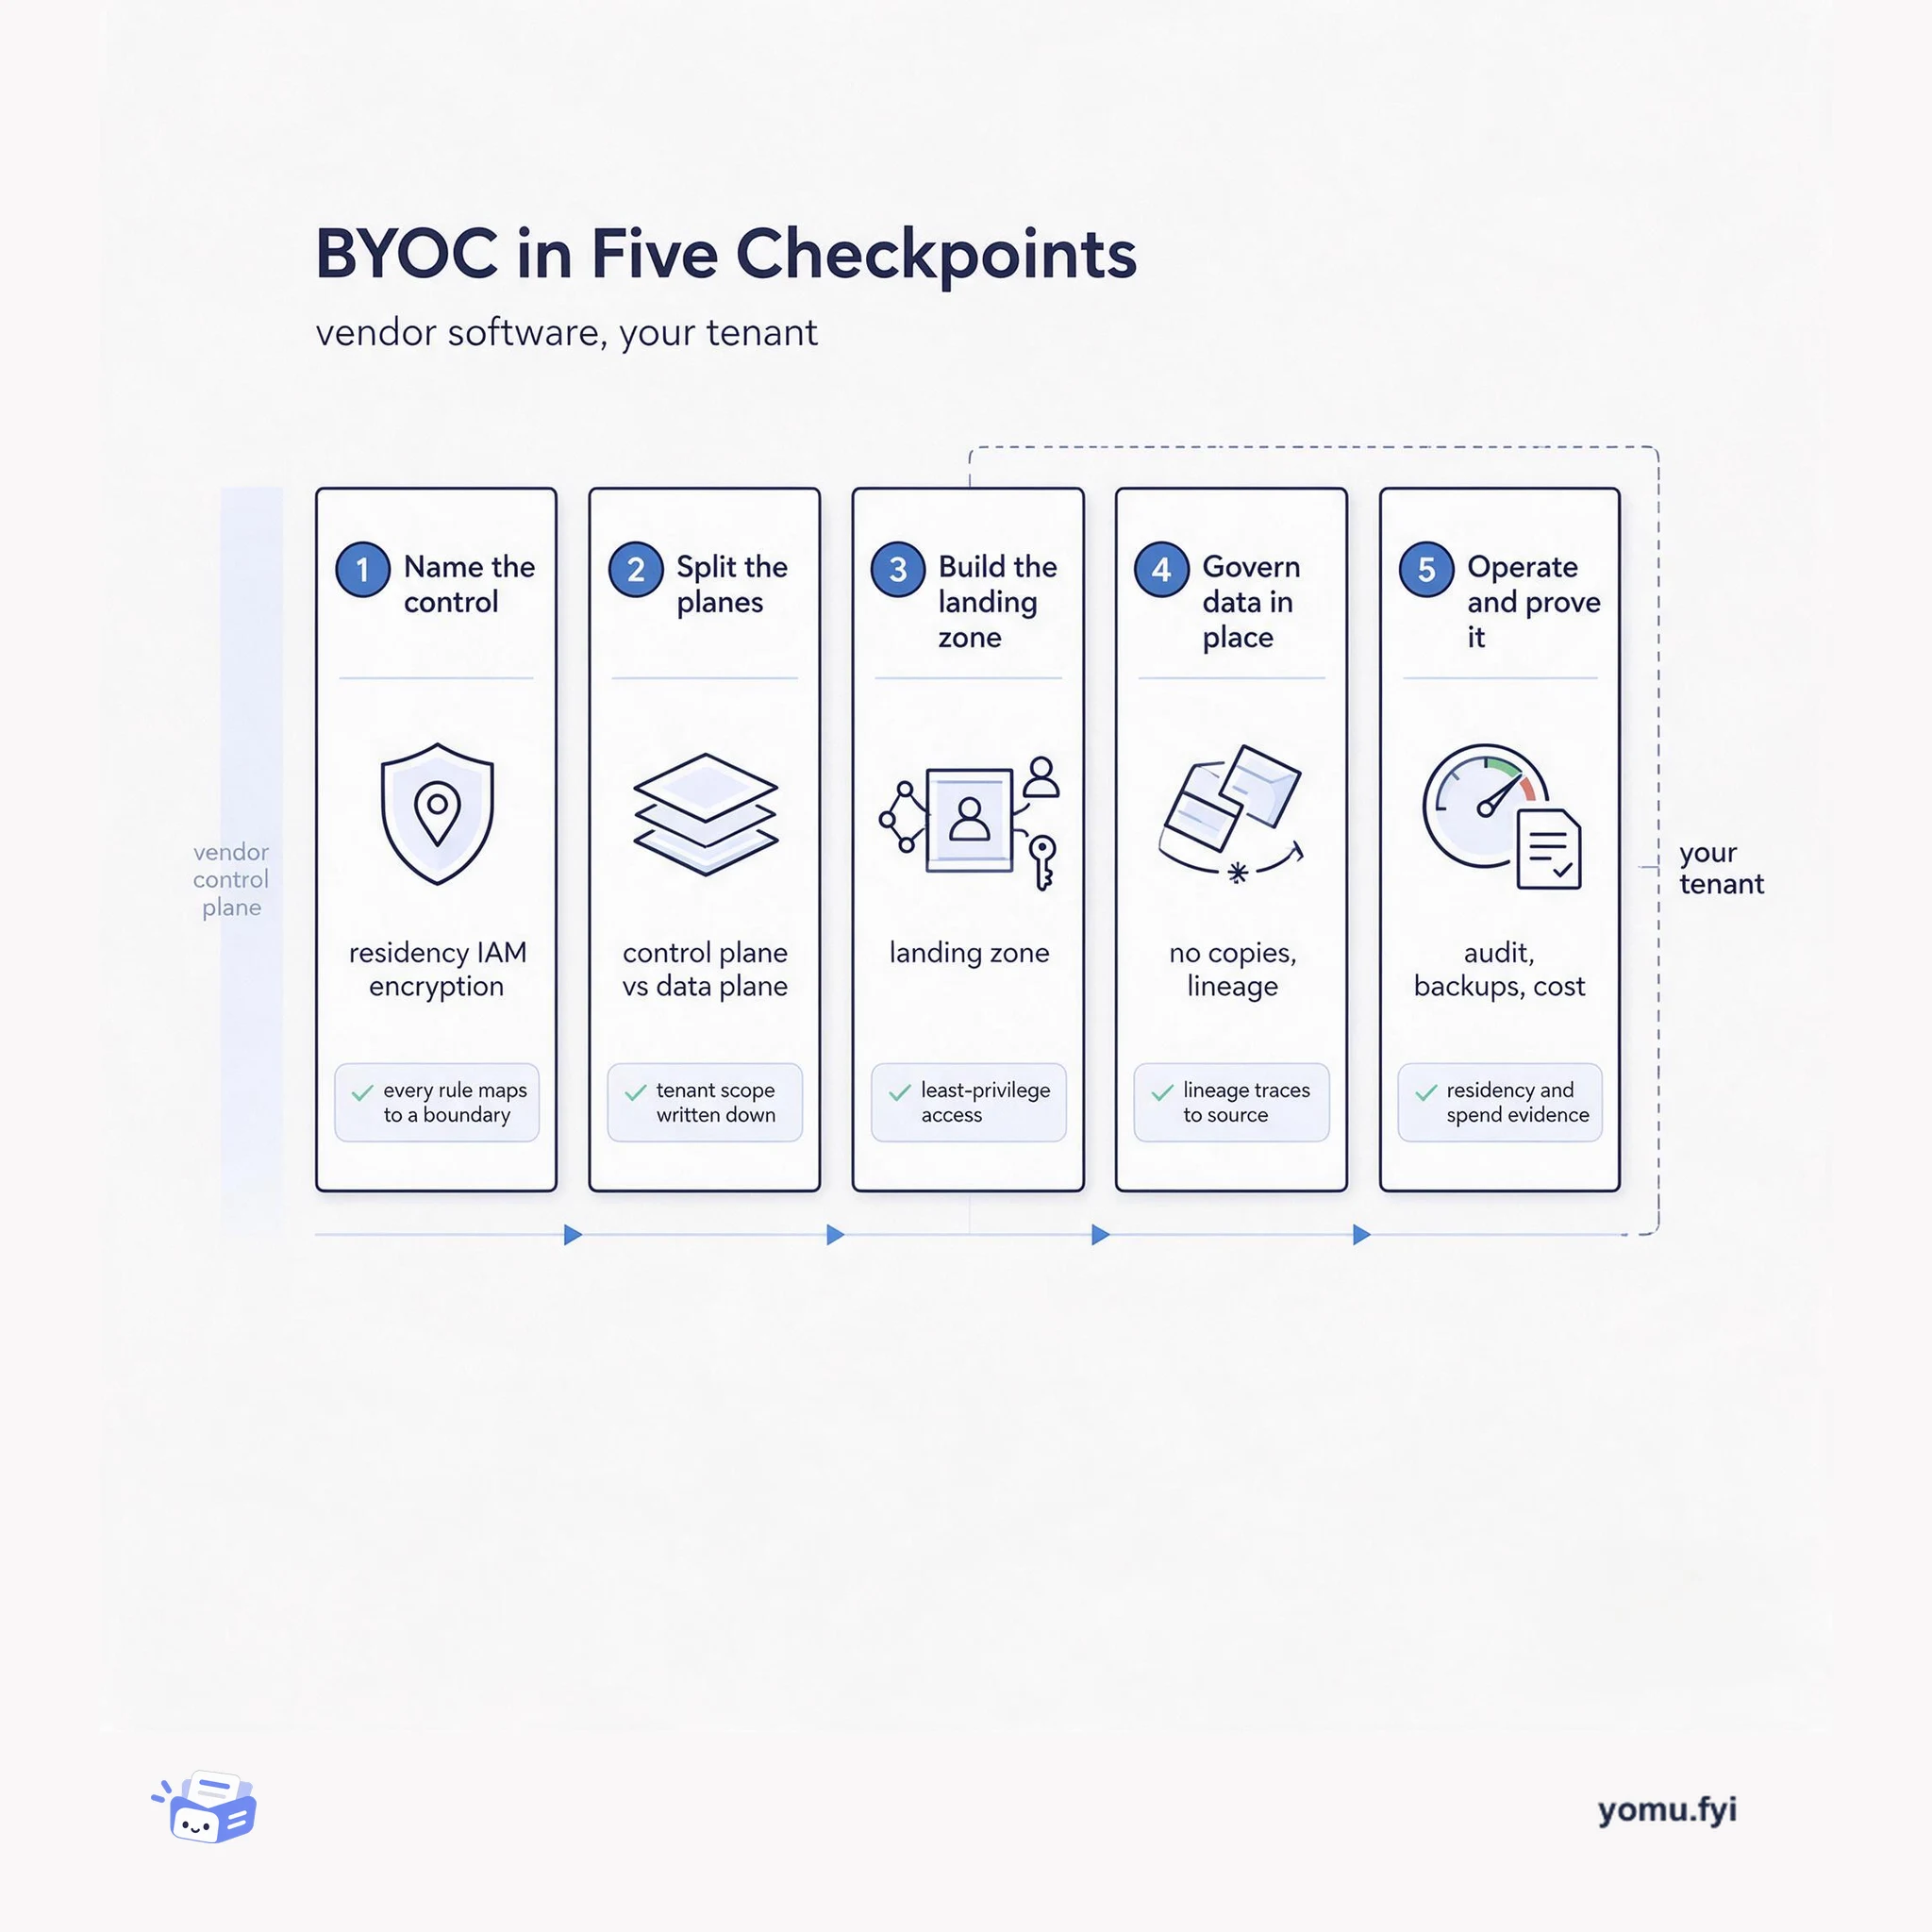
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.