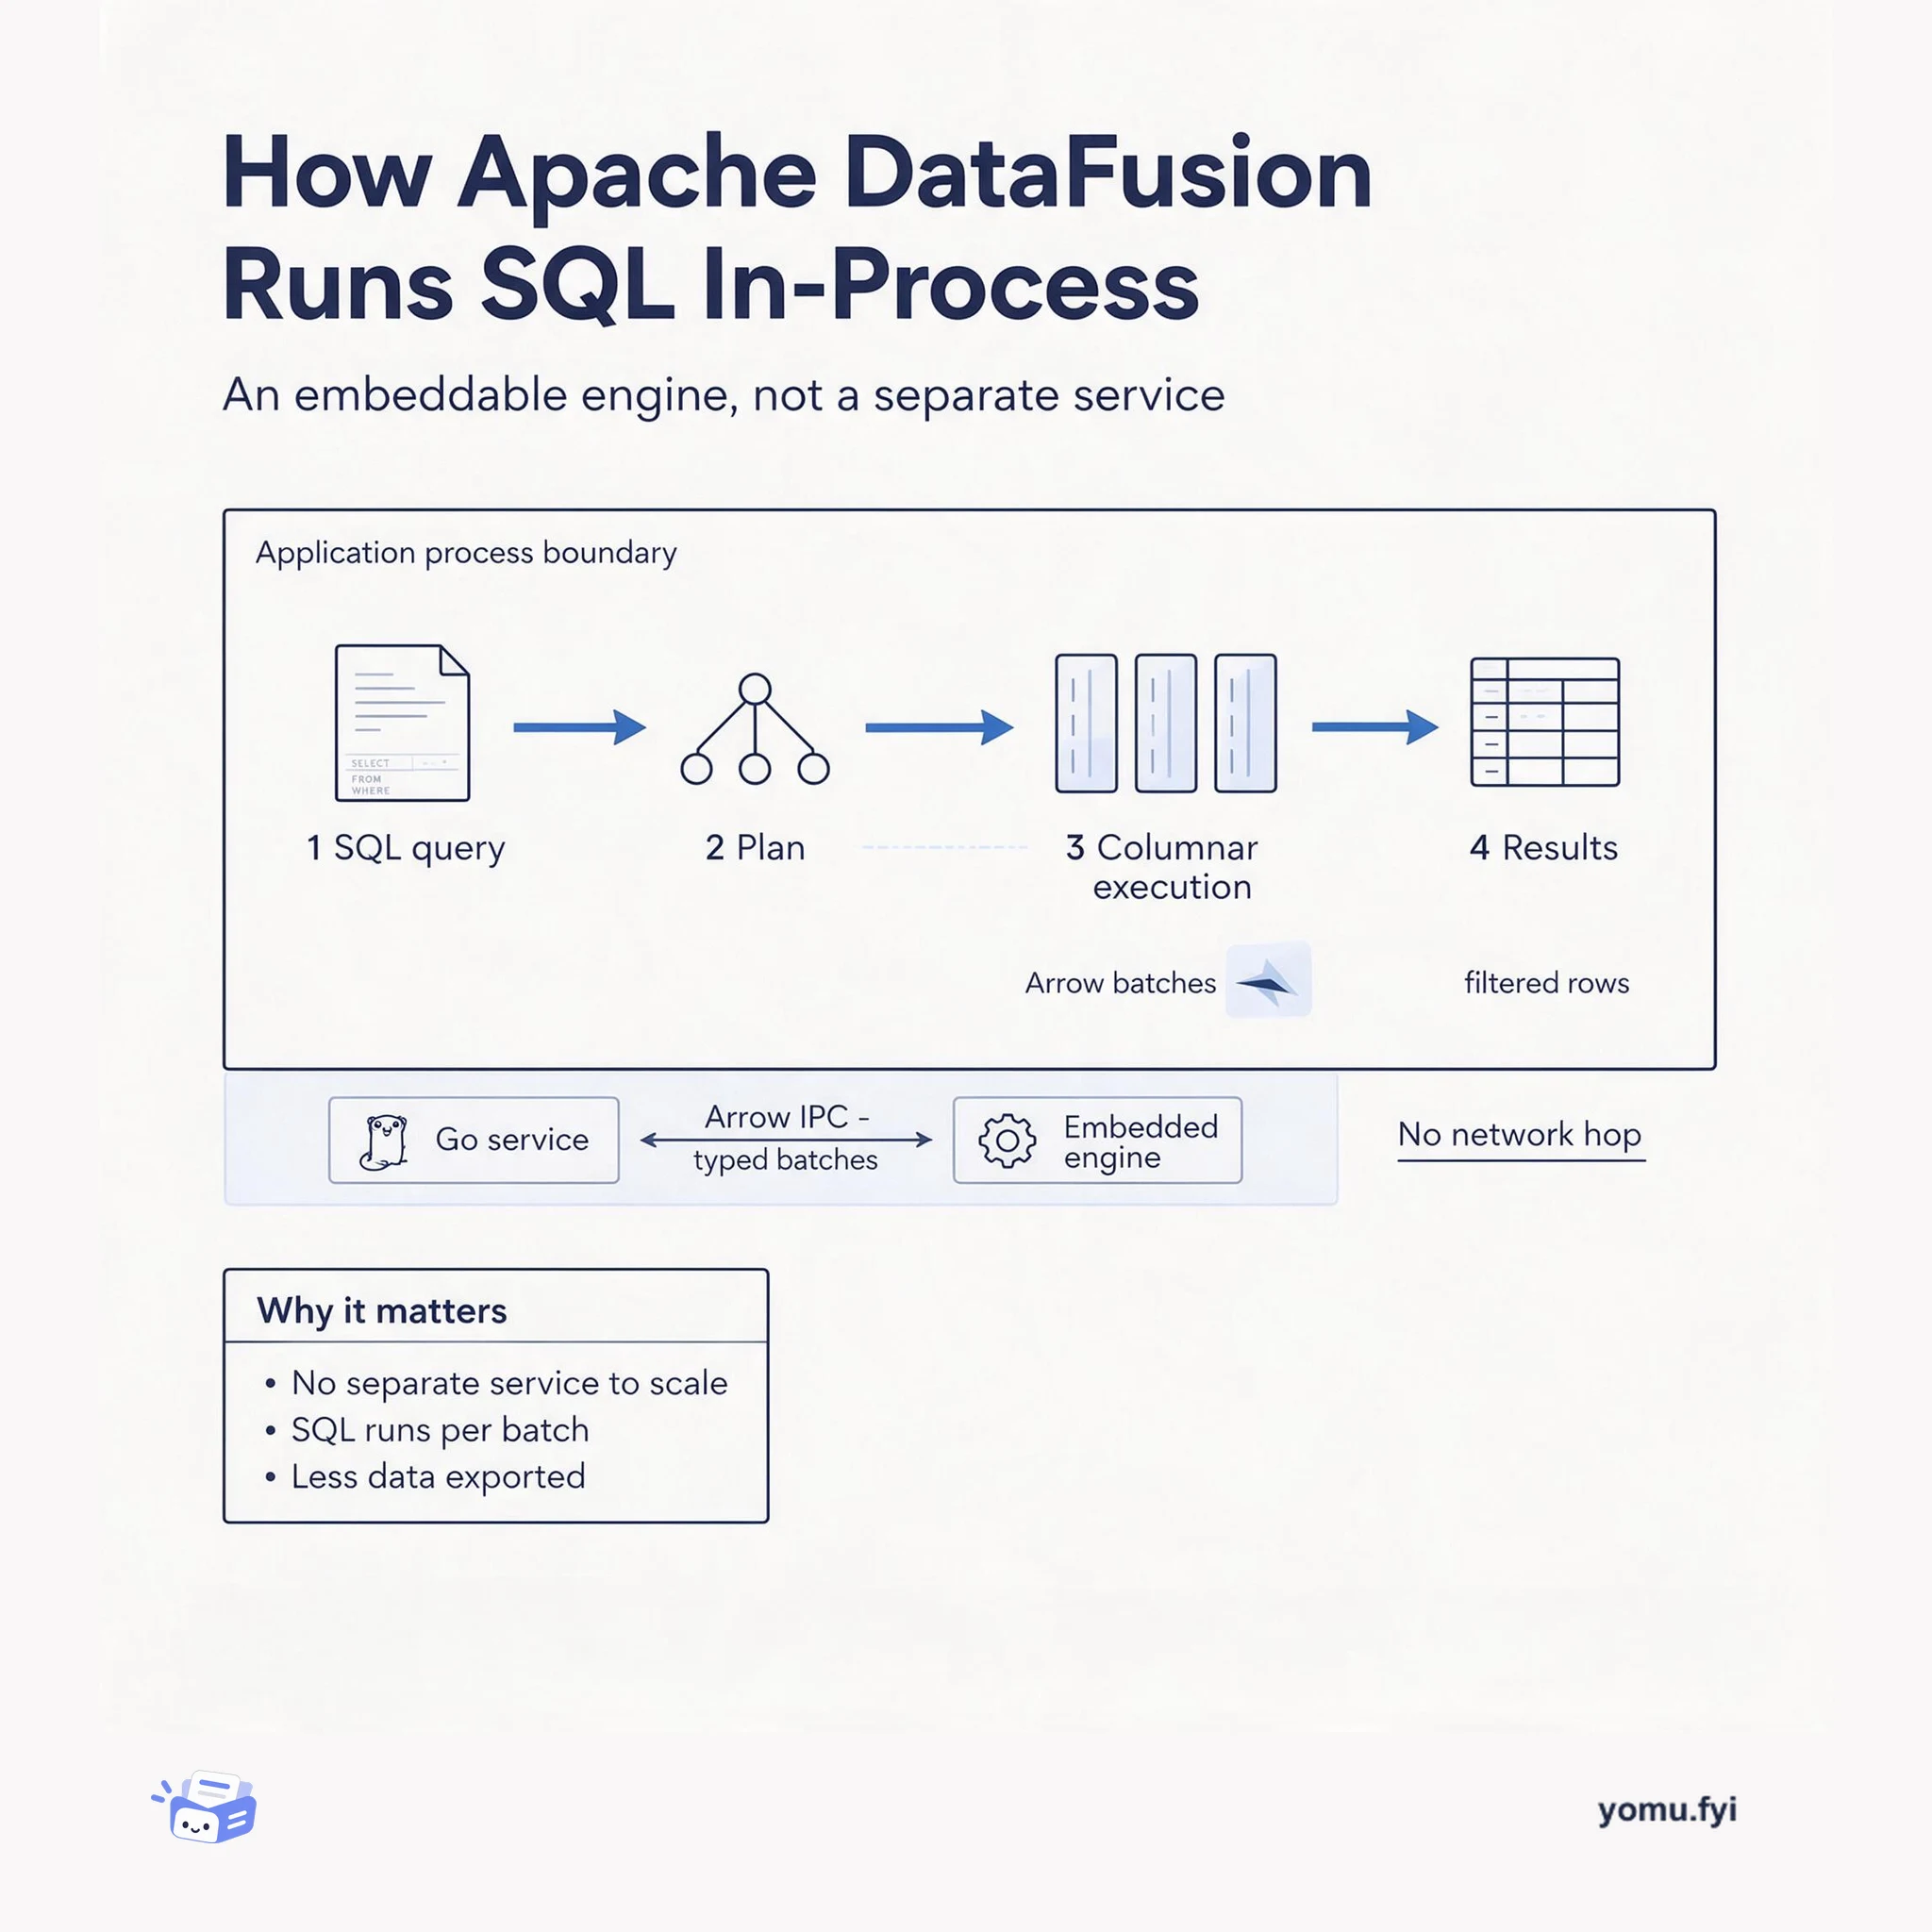
How Apache DataFusion Runs SQL In-Process
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
A walkthrough of how a 3D CT model turns a voxel volume into a structured diagnostic report: isotropic resampling, 3D patch tokens, spatial encoding, and language-model reasoning.
A 3D CT model does not read a stack of images; it reads one volume. The scan is resampled to an isotropic cubic grid, cut into 3D patch tokens, given spatial position encoding, and handed to a language model that writes a structured report. Each stage exists for a reason: isotropic resampling removes slice-thickness bias, 3D patch tokens preserve relationships between neighbouring slices, and supervised fine-tuning plus accuracy-driven refinement shapes the reasoning the model produces. Knowing which stage owns which failure tells you which outputs to trust.
Stacking slices loses the through-plane relationship between neighbouring images, so a finding that spans several slices is not represented as one connected structure. A true 3D encoder with 3D position encoding keeps those spatial relationships between patches. NV-Reason-CT follows this approach, processing volumes as genuine 3D input rather than independent 2D slices.
Scans arrive with different slice thickness and spacing, so a patch grid would otherwise mean a different physical size per scan. Resampling to a fixed cubic grid at 2 mm isotropic makes every 8x8x8 patch token cover a consistent volume, which stabilises training and makes results comparable across sources.
No. NV-Reason-CT is an open research foundation, not a cleared clinical product, even though it emits structured reports over 30 chest and 29 abdominal abnormalities. Production use also depends on governance work such as testing against simulated cases before deployment, and on private inference where scan data must stay confidential.
The posts behind it
 NVIDIA · · Announcement
NVIDIA released NV-Reason-CT, a vision language model for 3D CT analysis that processes volumes as true 3D input rather than independent 2D slices. The model generates structured diagnostic reports covering 30 chest and 29 abdominal abnormalities and emulates radiologist chain-of-thought reasoning with systematic anatomical reviews and uncertainty articulation. Its architecture pairs a Qwen3.5-4B language model with a full 3D ViT encoder that processes volumes resampled to 192³ voxels at 2mm isotropic resolution using 8x8x8 patch tokens and 3D MRoPE for spatial token relationships. Training uses supervised fine-tuning on roughly 550,000 QA examples from CT-RATE, NIH CT, and CancerVerse followed by Group Relative Policy Optimization that refines reasoning quality based on diagnostic accuracy. NV-Reason-CT is an open research foundation not a cleared clinical product and sits within NVIDIA’s Medical AI ecosystem alongside NV-Reason-CXR, NV-Segment-CTMR, and NV-Generate-CTMR.
 Databricks · · Explainer
Concurrence processes 100.8 billion input tokens and 11.2 million LLM calls every 30 days, at an annualized rate of 1.2 trillion tokens. To govern these workflows, the company consolidates on Databricks with Lakebase for operational state, Unity Catalog for governance, and Unity Gateway for centralized AI access. Patient data is recorded as immutable events in Delta tables, from which a current patient state—called the world model—is computed while preserving provenance. All agents are tested against simulated patients before deployment; simulation traffic is approximately seven times production traffic, using immutable event history to replay states. Concurrence routes all coding-agent traffic through Unity Gateway, attributing each request to the engineer, and enforces compliance-gated model routing where HIPAA requirements are met first.
 Red Hat · · Problem & solution
Default inference configurations for large language models often leave significant performance unused, even on expensive hardware like 16 NVIDIA H200 GPUs across two nodes. The author tested this setup with vLLM and Red Hat AI Inference 3.4 on a CoreWeave Kubernetes cluster, using enterprise RAG workloads with 2,000-token inputs and 100 concurrent users. By systematically comparing aggregated and prefill-decode (PD) disaggregated architectures, and tuning tensor parallelism (TP) and PD split, latency was dramatically reduced. For Qwen3-32B, time-to-first-token (TTFT) on the best aggregated configuration (2xTP8) dropped from 995ms to 304ms, and with optimized routing to 287ms — a 71% improvement without hardware changes. For Llama-70B, TTFT fell from 1,292ms to 463ms, a 64% gain. The author also built ServeIt Studio, an open-source tool that automates the full optimization pipeline on Kubernetes.
NVIDIA · · ExplainerNVIDIA Confidential Computing (CC) enables secure AI inference by using memory-encrypted confidential VMs, confidential GPUs, and encrypted NVLink. Running inference frameworks like TensorRT LLM in a CC environment introduces performance overhead because secure execution changes assumptions about memory movement, timing, and multi-GPU communication. To quantify this overhead, the post presents a controlled methodology comparing CC-on and CC-off performance on a workload with long input context, extended output generation, and low concurrency. With CC-aware adaptations—including pageable memory selection, asynchronous readback, GPU %globaltimer for autotuning, and CC-aware multi-GPU communication—TensorRT LLM retained 96.1–98.2% of baseline throughput on eight NVIDIA B200 GPUs while keeping per-token latency overhead below 5%. The post concludes that security configuration and inference optimization should be treated as a single deployment problem for organizations moving private inference into production.
 MongoDB · · Explainer
BIRD is a research framework that converts five 2D perspective drawings into a proportionate, dimensioned 3D building envelope. It uses a dual-branch CNN to separate architectural line segments from noise, a text recognition model to scale them to real-world inches, and a wrapping algorithm to fold the elevation views around the floor plan. The framework achieved a median accuracy of roughly 93% across complete building plan sets from small residences to a multi-story apartment complex. The proposed deployment on MongoDB Atlas stores each project as a single JSON document containing all drawings’ segments, corrections, and final geometry, with S3 for image storage and Atlas Stream Processing for event-driven workflow coordination. MongoDB Search and Vector Search with Voyage AI embeddings enable full-text and semantic search over past projects, allowing drafters to start from corrected models of similar builds.
More like this
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
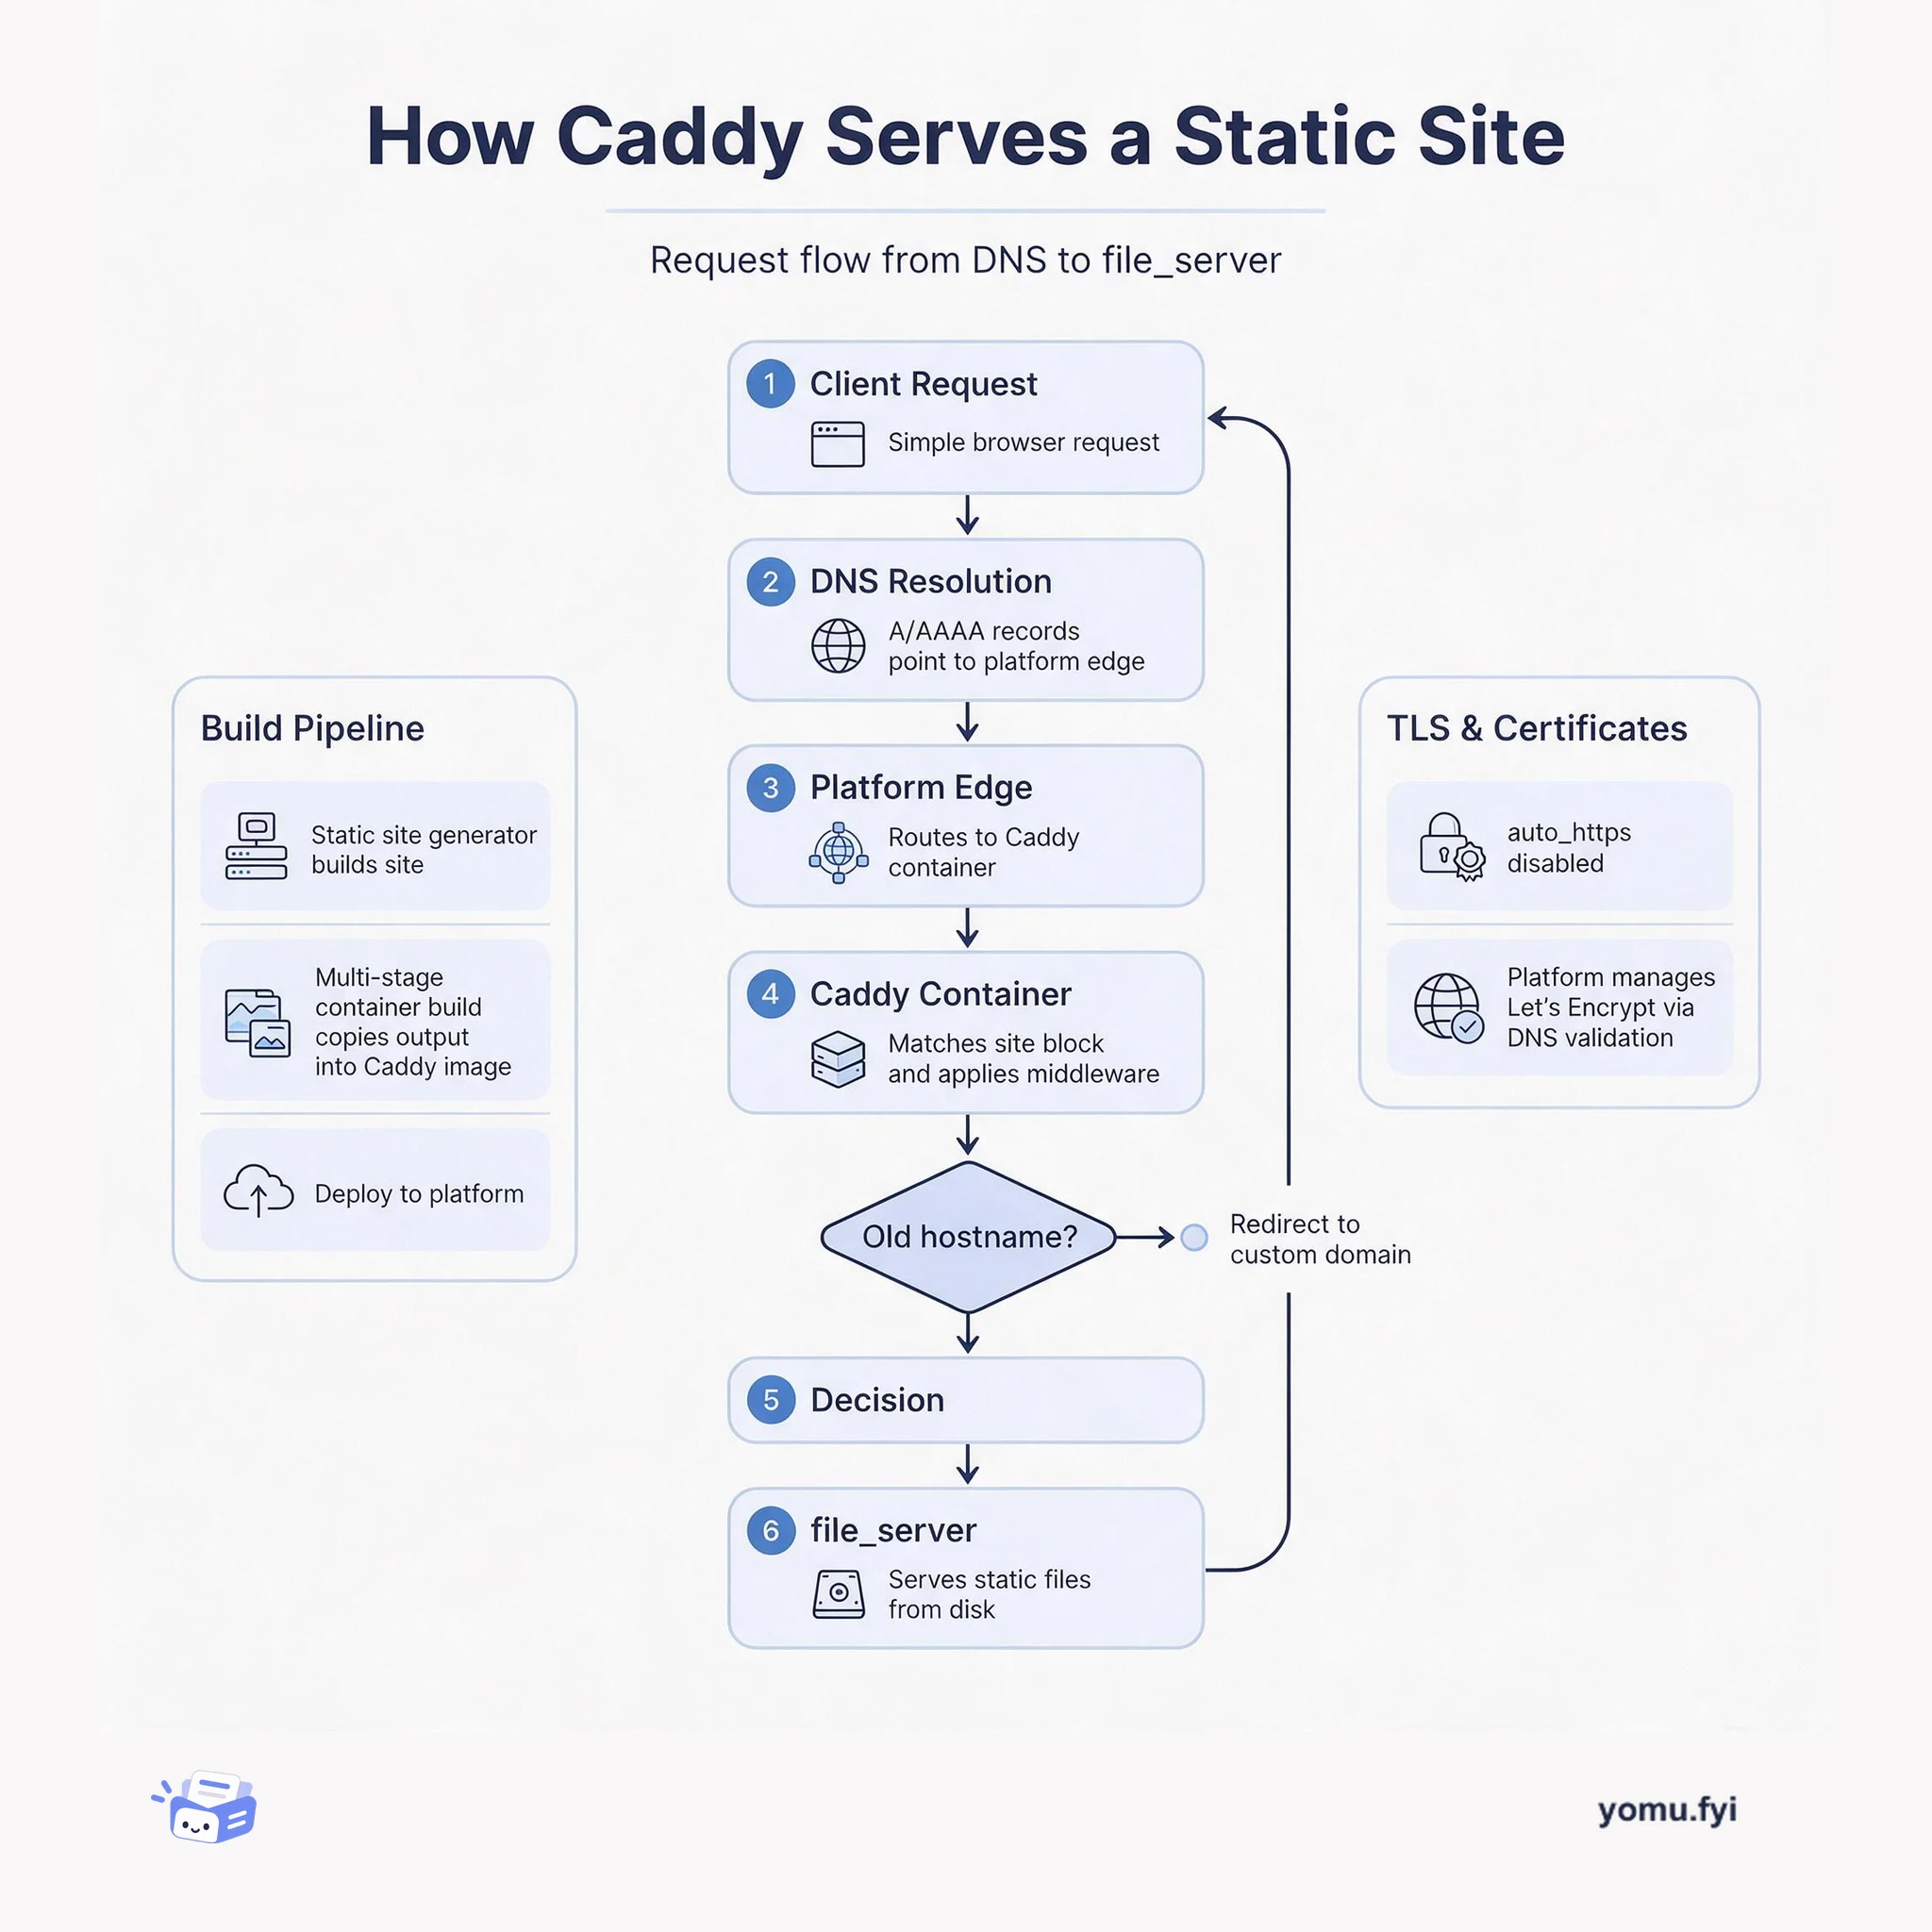
See how Caddy handles a request for a static site, from DNS resolution through container routing to file_server, and how TLS and redirects fit into the flow.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.