How to Run an Agent Loop That Actually Converges
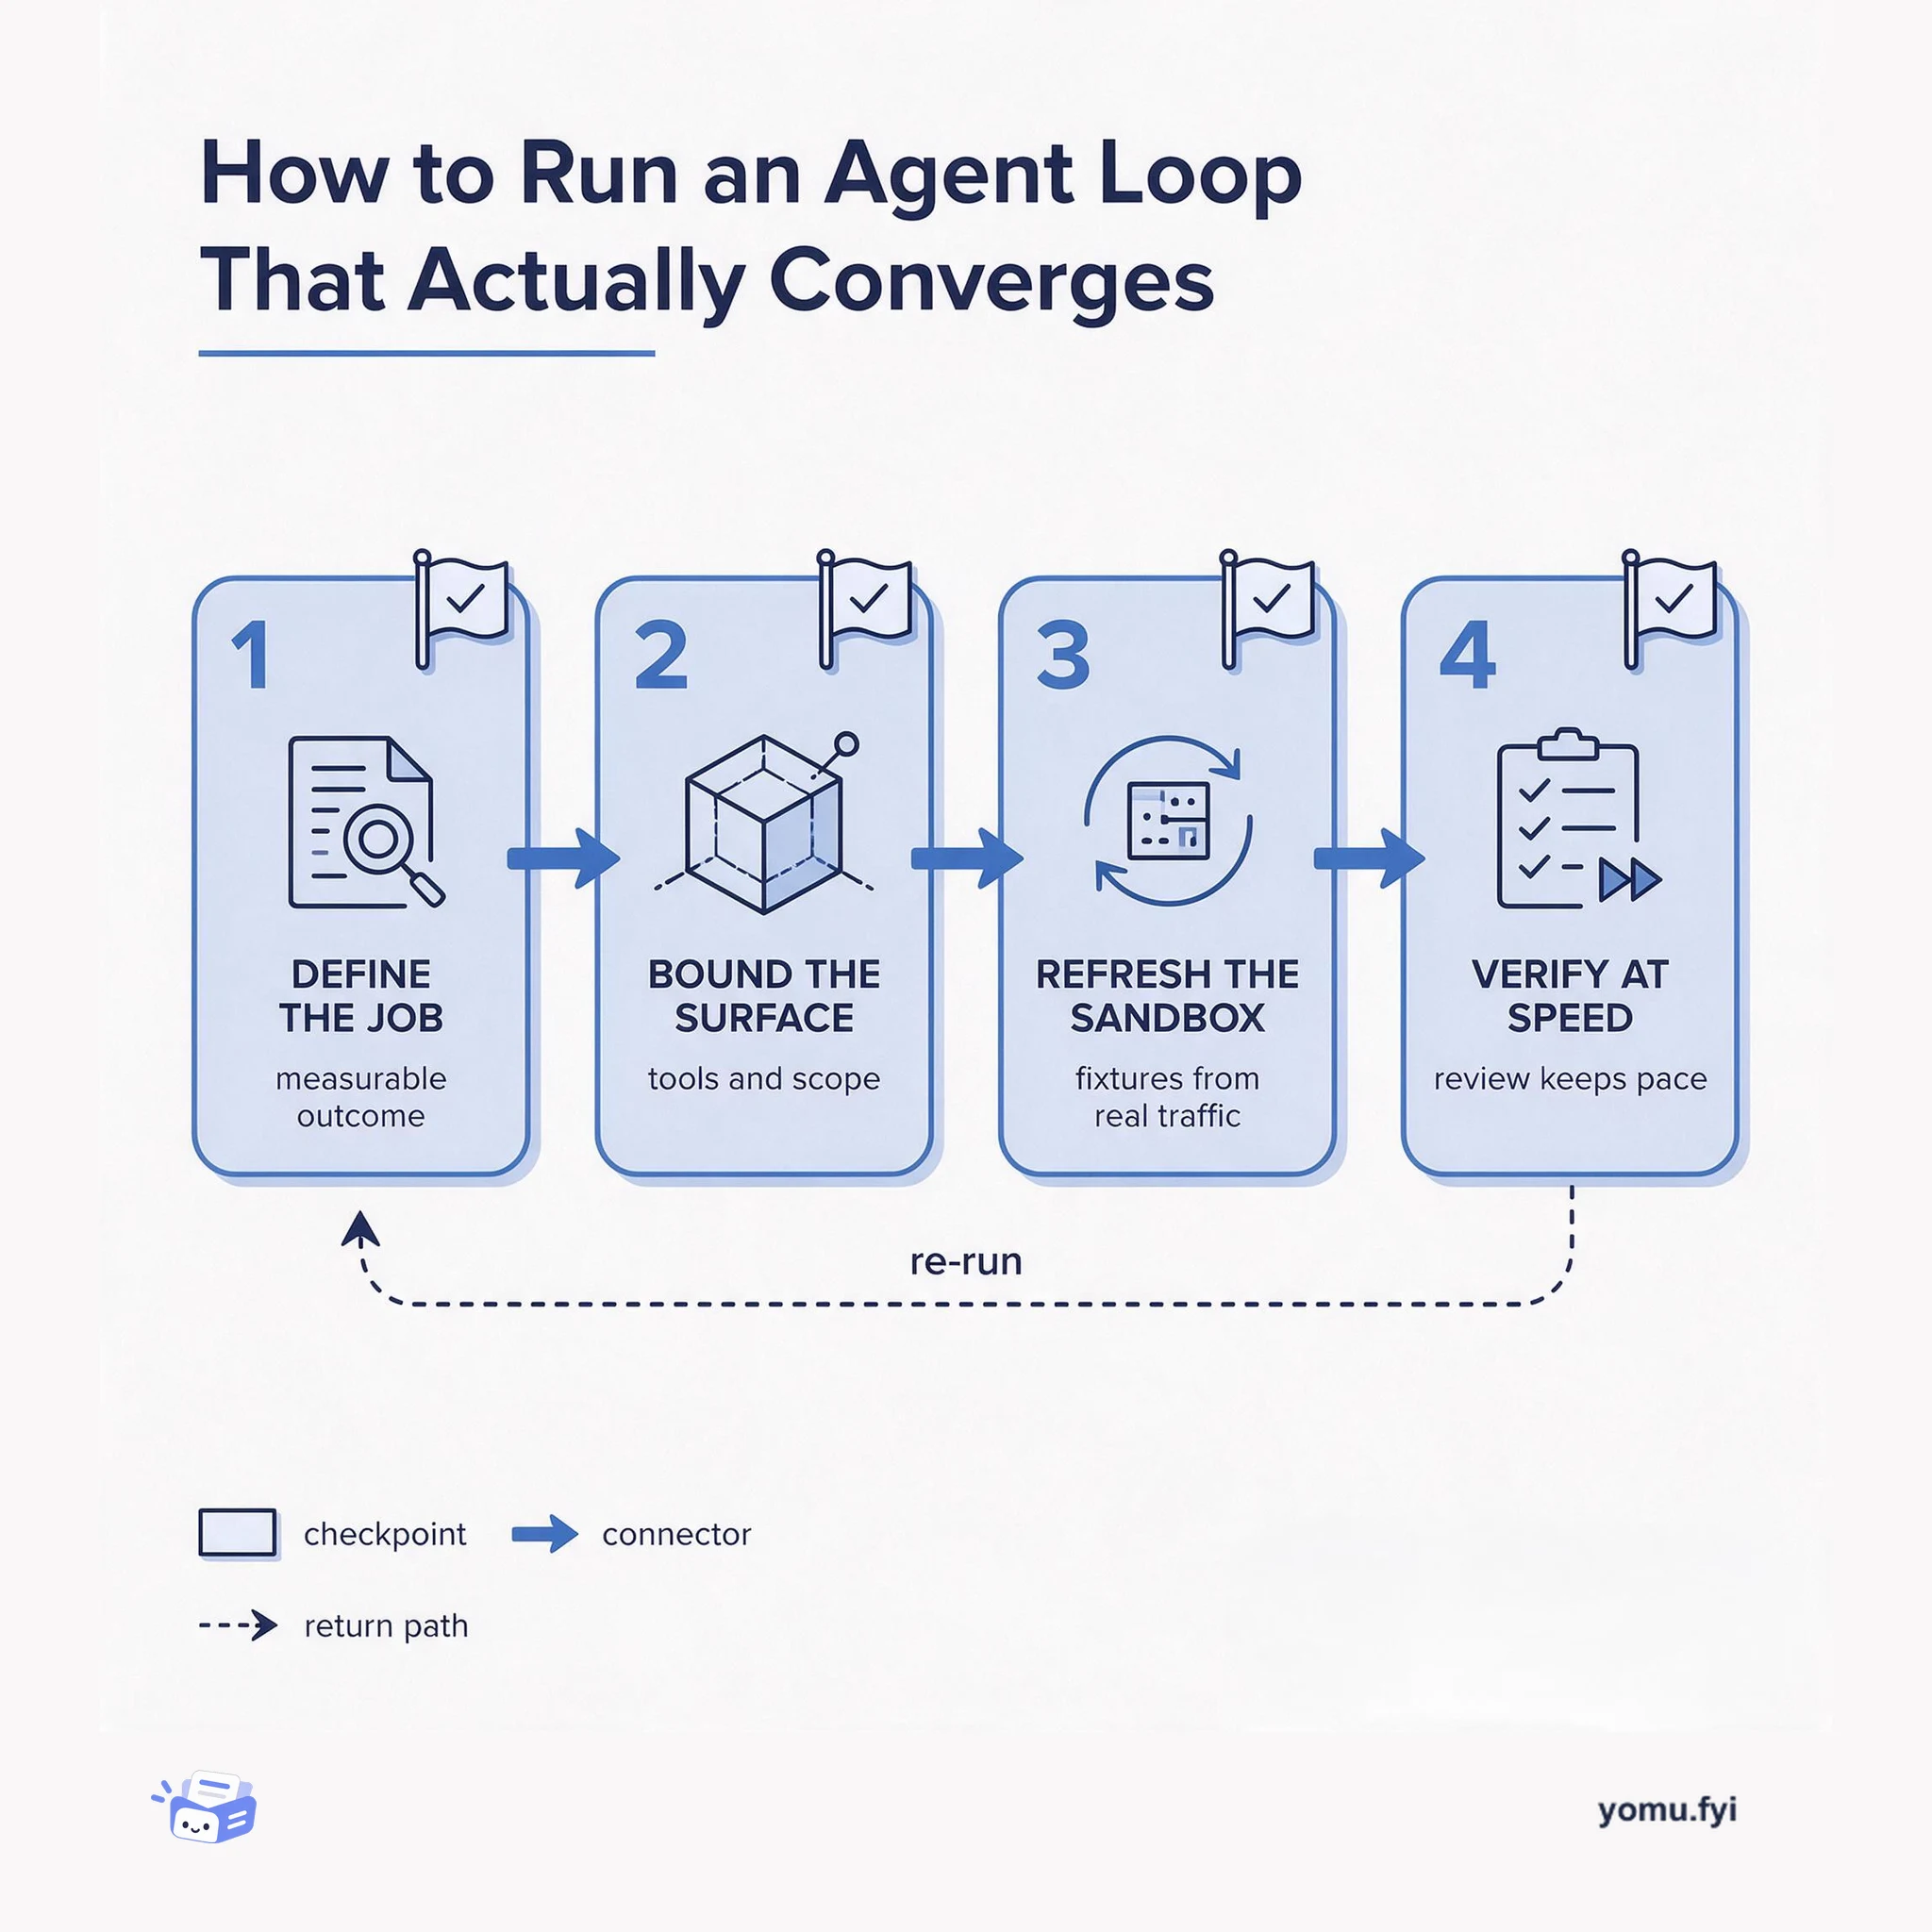
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
Learn how Apache Hudi copy-on-write upserts can use row-level file and page locations to update changed data while avoiding unnecessary decompression and rewriting.
Apache Hudi copy-on-write upserts traditionally read and rewrite entire affected Parquet files. This explainer follows a practical optimization path: map changed records to files and row IDs, locate their data pages, update only affected pages, and copy untouched pages as byte buffers. It also shows the trade-off: the approach depends on an added row-level index and should be evaluated against workload size and update rate.
It maps records to the files and row IDs containing them, helping the write path locate the specific Parquet pages that contain changed records instead of treating every affected file as fully changed.
Unchanged pages can be copied as byte buffers, avoiding decompression, re-encoding, and record reassembly for data that did not change. The supplied benchmarks report faster results than the traditional approach across update rates from 5% to 50%.
Verify the workload’s update rate, the cost of maintaining and consulting the row-level index, and whether the implementation is available in the Hudi version and execution path you use. The supplied material describes planned integration into Apache Hudi, so it should not be assumed to be a standard built-in feature.
The posts behind it
 Salesforce · · Explainer
Building real-time mobile personalization across iOS, Android, React Native, and Flutter required one architecture to handle different rendering models, lifecycles, identity flows, consent requirements, and release cycles without disrupting native app experiences. The team standardized schemas, event semantics, identity behavior, fallback handling, and SDK APIs, using bridge layers so React Native and Flutter could access native iOS and Android capabilities. Developers instrument apps once with constrained content zones and approved native components, while marketers configure templates, targeting, and content through Salesforce UI; metadata is published via a global CDN and rendered dynamically by the SDK. Data 360 performs server-side identity resolution and decisioning, limiting unnecessary raw profile storage on devices. An early customer implemented the system in two months and generated more than 150 million decisions within three weeks, while QR-code previews enabled testing against live profiles without app recompilation.
 Databricks · · Announcement
Lakeflow Connect addresses the fragmentation of Customer 360 data across ad platforms, analytics tools, CRMs, and support systems. Its fully managed native connectors ingest sources through a UI or API, incrementally landing governed tables in Unity Catalog without infrastructure to provision, manage, or scale. Connectors for Google Ads, Meta Ads, TikTok Ads, Reddit Ads, and LinkedIn Ads provide pre-built or custom reports with spend, impressions, clicks, and conversions, while OAuth flows simplify setup for some platforms. The post also describes HubSpot, Salesforce, and other journey-wide connectors, plus the Ad-Genie accelerator, which transforms bronze data into silver and gold tables for AI/BI dashboards and Genie agents. Customer examples report reduced engineering overhead and faster ingestion.
 Clickhouse · · Explainer
ClickHouse’s beta AI Functions let SQL queries call an LLM or embedding provider directly, keeping classification, extraction, generation, translation, redaction, filtering, embedding, and similarity work alongside stored data. The feature addresses workflows that export rows to separate LLM, orchestration, or vector-database systems and then reload results, with the stated goal of running the full RAG cycle in ClickHouse. Functions make remote HTTP calls per input, or batch embedding inputs, and return native ClickHouse values; in open-source deployments, named collections store provider credentials and endpoint settings. Examples use Hacker News data for topic classification and natural-language filtering, while the guidance emphasizes cheap predicates, quotas, LIMIT tests, prompt-injection defenses, non-determinism, cost, latency, and provider access to data in cleartext after TLS termination.
 Uber · · Benchmark
Large-scale lakehouse upserts can become slow and resource-intensive, especially in Apache Hudi copy-on-write mode, where affected files are read, modified, and rewritten in full. The approach adds a Parquet row-level secondary index mapping records to files and row IDs, allowing updates to locate the specific data pages containing changed records. During copy-on-write, related pages are updated while unrelated pages are copied as byte buffers, avoiding decompression, re-encoding, and record reassembly for skipped data. Benchmarks using TPC-DS sales data, Spark jobs with matching vCore and memory settings, and update rates from 5% to 50% found significantly faster speeds than traditional approaches, including Delta Lake’s default configuration. The authors plan to integrate the row-level index and fast copy-on-write into Apache Hudi for use cases such as incremental ingestion, data deletion, and CDC.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
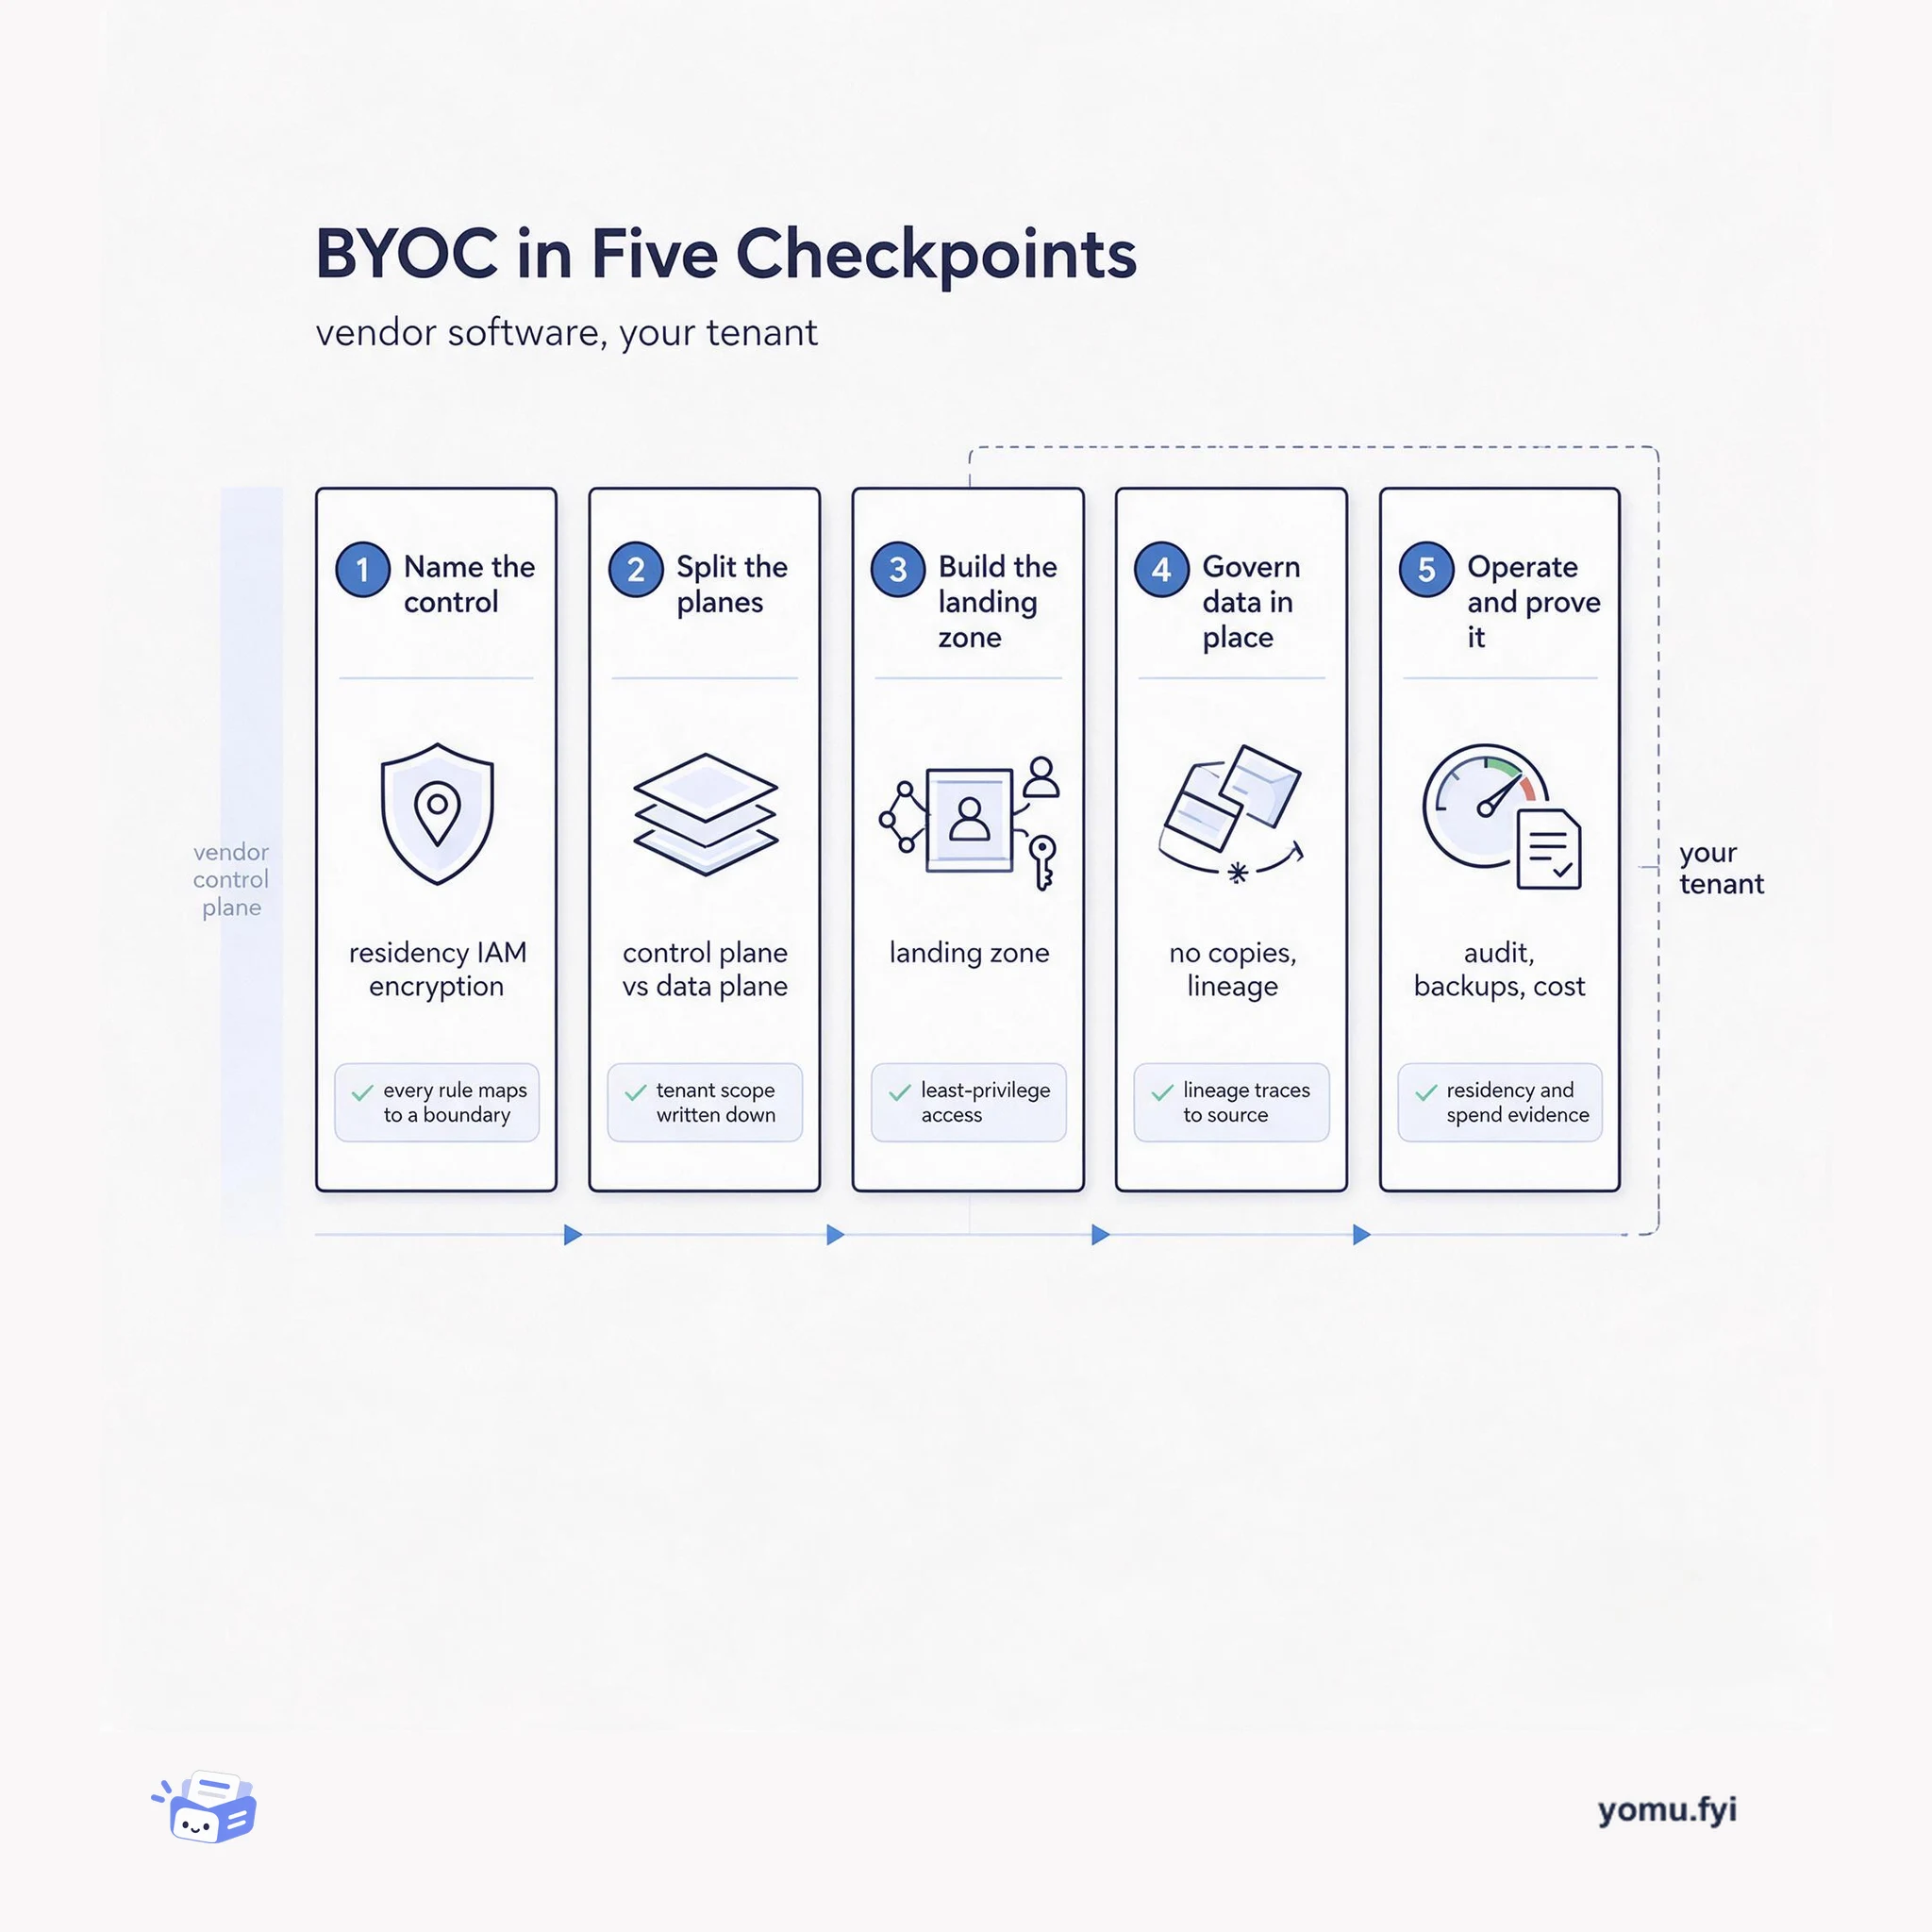
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.