How to Run an Agent Loop That Actually Converges
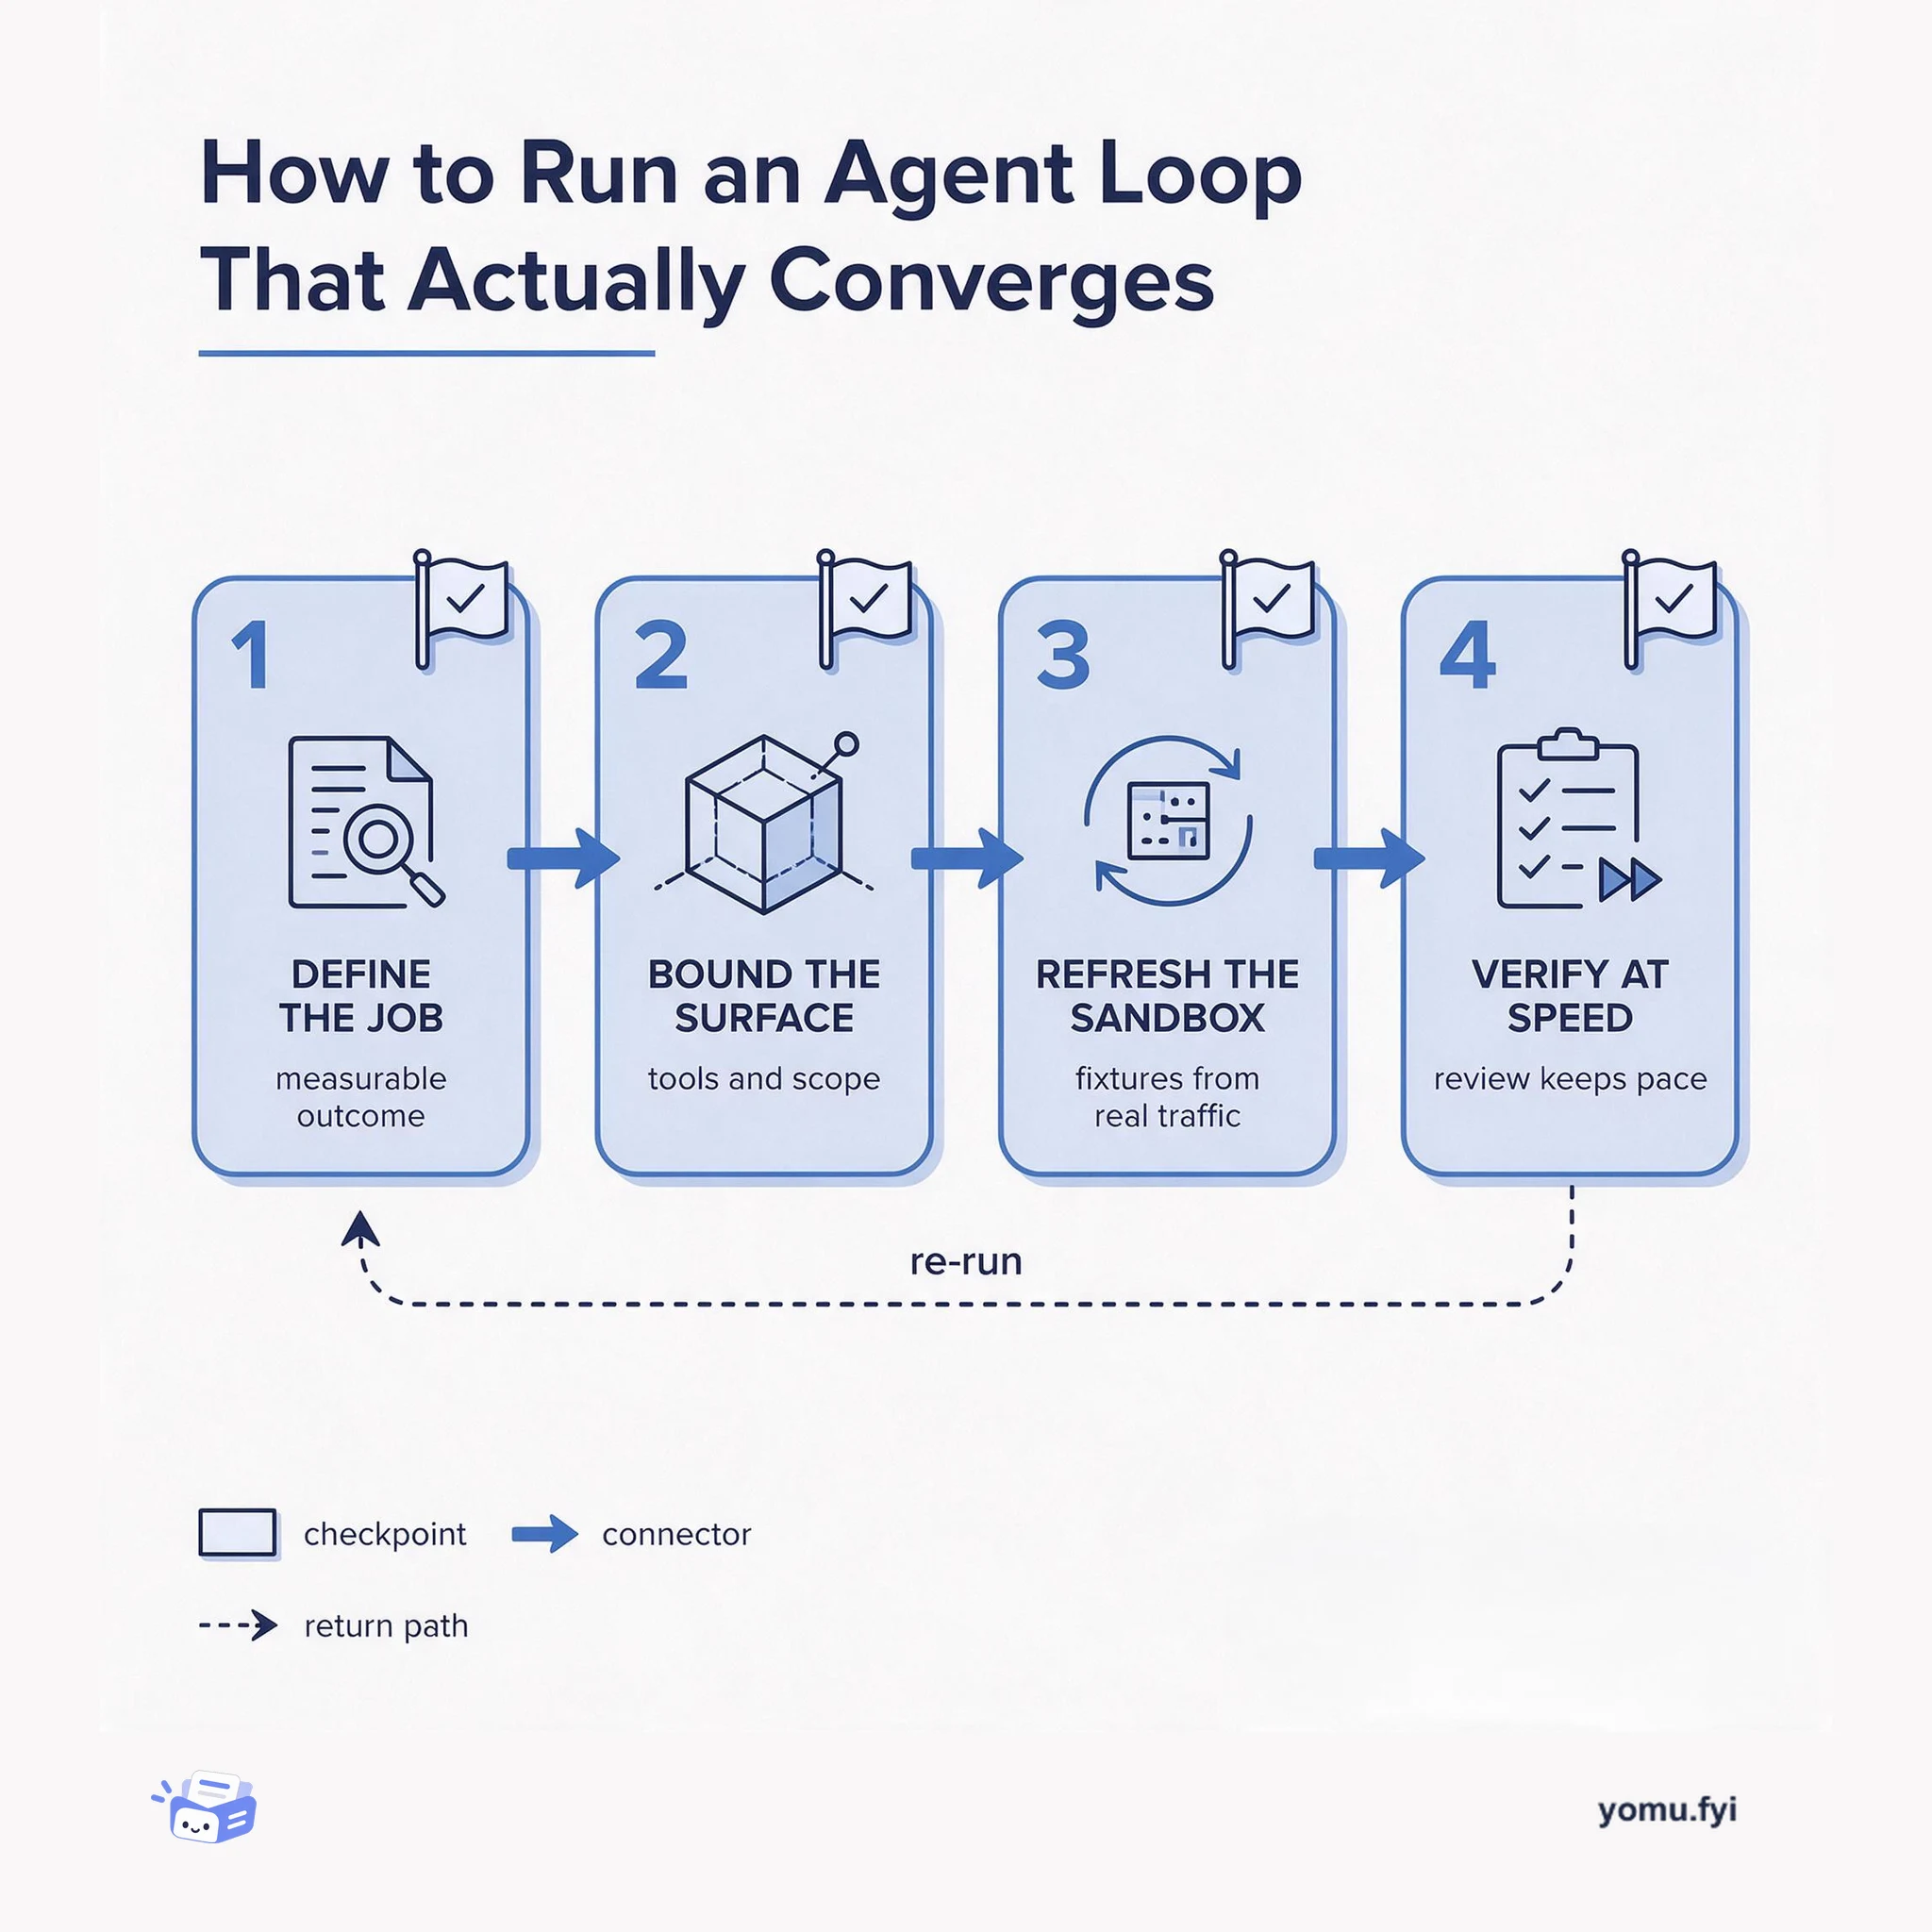
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
A five-step how-to for deciding when an AMD Instinct GPU should stay dedicated and when SR-IOV virtual functions, VMs, or sidecar isolation can safely share it.
Sharing accelerator hardware is a capacity decision before it is a configuration decision. AMD Instinct MI300X GPUs support hardware-assisted SR-IOV in CPX mode, exposing eight virtual functions per GPU with separate PCI and VRAM allocation, and validation on an eight-GPU system ran 64 VMs while retaining roughly 96-99% of bare-metal memory bandwidth. This explainer walks through five checkpoints: confirm the workload's hardware needs, pick a partitioning primitive, split trusted from untrusted code, measure what the split costs, and record the known limits. The goal is a repeatable way to decide when shared GPUs are good enough and when a dedicated device is the honest answer.
In CPX mode each MI300X can expose eight virtual functions, each with its own PCI function and VRAM allocation, so one GPU can back several VMs. Validation on an eight-GPU system created 64 VFs and ran 64 VMs with one VF each, and tested up to 32 VFs inside a single VM. Memory bandwidth stayed near bare metal, but peer-to-peer DMA and runtime VF lifecycle had limitations.
Use a full VM when the workload needs Docker stacks, FUSE filesystems, local databases, or niche kernel features that a lighter sandbox cannot provide. Lighter isolation remains the sensible default for compatible workloads. Full VMs do not have to be slow: VM Sandboxes preserve sub-second cold starts and the same APIs as the existing sandbox model.
The posts behind it
 Red Hat · · Benchmark
Enterprise AI environments are moving from dedicated GPU servers to shared accelerator infrastructure, requiring higher GPU utilization with strong isolation. AMD Instinct MI300X GPUs support hardware-assisted SR-IOV in CPX mode, each exposing eight virtual functions with separate PCI and VRAM allocation. When integrated with Red Hat OpenStack Services on OpenShift, the control plane runs on OpenShift while RHEL compute nodes use EDPM, with Nova scheduling VFs via VFIO PCI passthrough. Validation on an 8-GPU system created 64 VFs, demonstrated 64 VMs with one VF each, and tested up to 32 VFs per VM. BabelStream benchmarks showed approximately 96-99% of bare-metal memory bandwidth, while the testing also identified limitations in GPU peer-to-peer DMA and runtime VF lifecycle.
 Modal · · Announcement
Modal has launched VM Sandboxes in general availability, providing agents with full Linux VMs accessible via a single flag. The VMs support Docker stacks, local databases, dev servers, and other real-machine features that agents increasingly require, as demonstrated by Ramp’s internal agent driving the entire software development lifecycle. Modal built a custom runtime on the Rust-based Cloud Hypervisor, layering innovations in host filesystems, lazy image loading, memory bursting, and snapshotting to preserve the same APIs and sub-second cold starts as their existing gVisor Sandboxes. Early customers like Linear, Legora, and Snorkel have launched over 20 million VMs, using them for coding sessions, legal agent evaluations, and agent simulations that require multiple containers and real-world environments. Modal recommends using VM Sandboxes when workloads need Docker, FUSE filesystems, or niche kernel features, while gVisor remains the default for compatible workloads.
Modal · · AnnouncementModal announced several new features at its inaugural Runtime conference. VM Sandboxes provide agents with full Linux computer access, supporting Docker stacks, databases, graphical environments, and kernel experimentation, already used at Linear, Legora, and Snorkel for coding agents and evals. Sandbox Sidecars run alongside main sandboxes with isolation but share a host, allowing agent code in the main sandbox while trusted operations run in a sidecar the agent cannot access, avoiding network round trips in execution-heavy loops. Modal Clusters, now generally available via @modal.clustered, enable multi-node jobs for training or serving trillion-parameter models, powering post-training at Decagon and real-time inference at Runway. Sticky Sessions maintain client state by routing to the same container using a session token, critical for voice model serving, while Endpoint Candidates allow mirroring production traffic to compare quality, latency, throughput, and cost before promoting.
Modal · · AnnouncementModal introduces Sidecars, isolated containers that run alongside a main Sandbox on the same host, establishing a trust boundary between trusted and untrusted code. Sidecars enable communication across trust boundaries at least 3x faster than using separate Sandboxes, reducing latency for operation-heavy agent workloads. The feature addresses the security risk of running an agent’s harness and tool calls together, which creates the “lethal trifecta” of private data, untrusted content, and external communication. Existing solutions either move the harness to a remote service (adding network latency) or rely on egress controls that lack flexibility. Sidecars allow trusted services such as credential injection, proxy traffic, and harness logic to run locally alongside the Sandbox, with independent network policies and dynamic creation via the Modal SDK.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
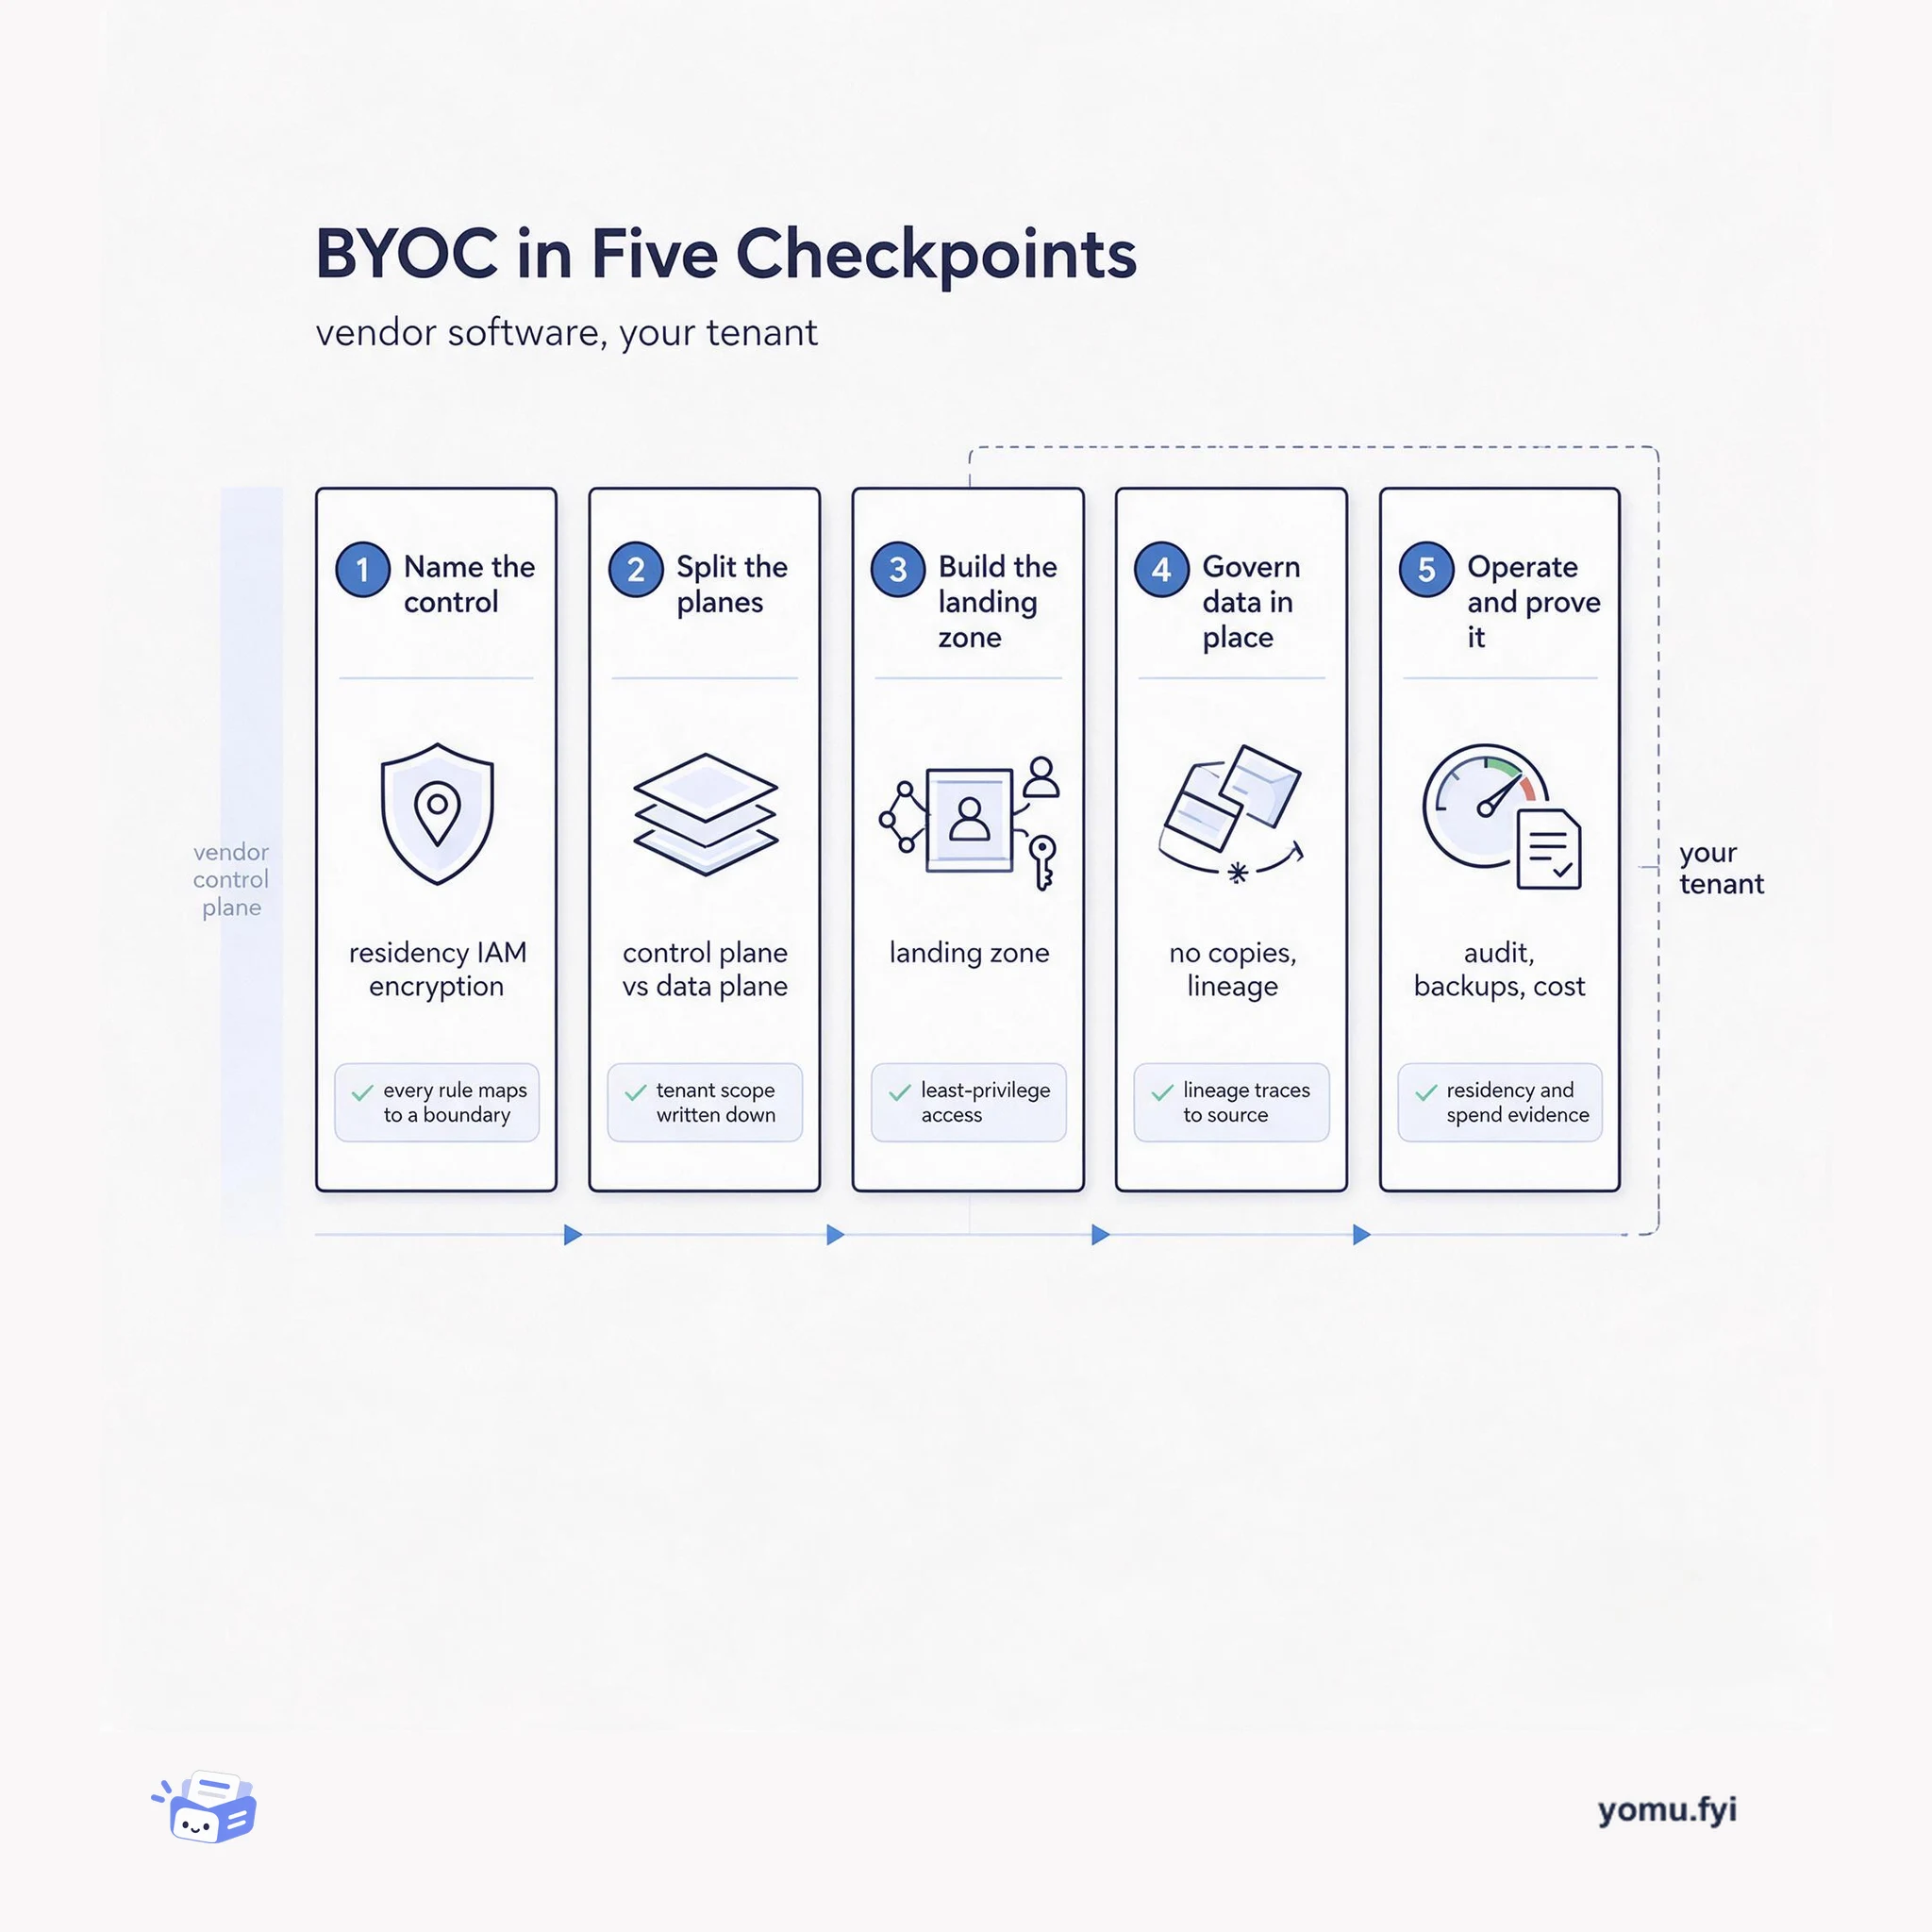
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.