How to Run an Agent Loop That Actually Converges
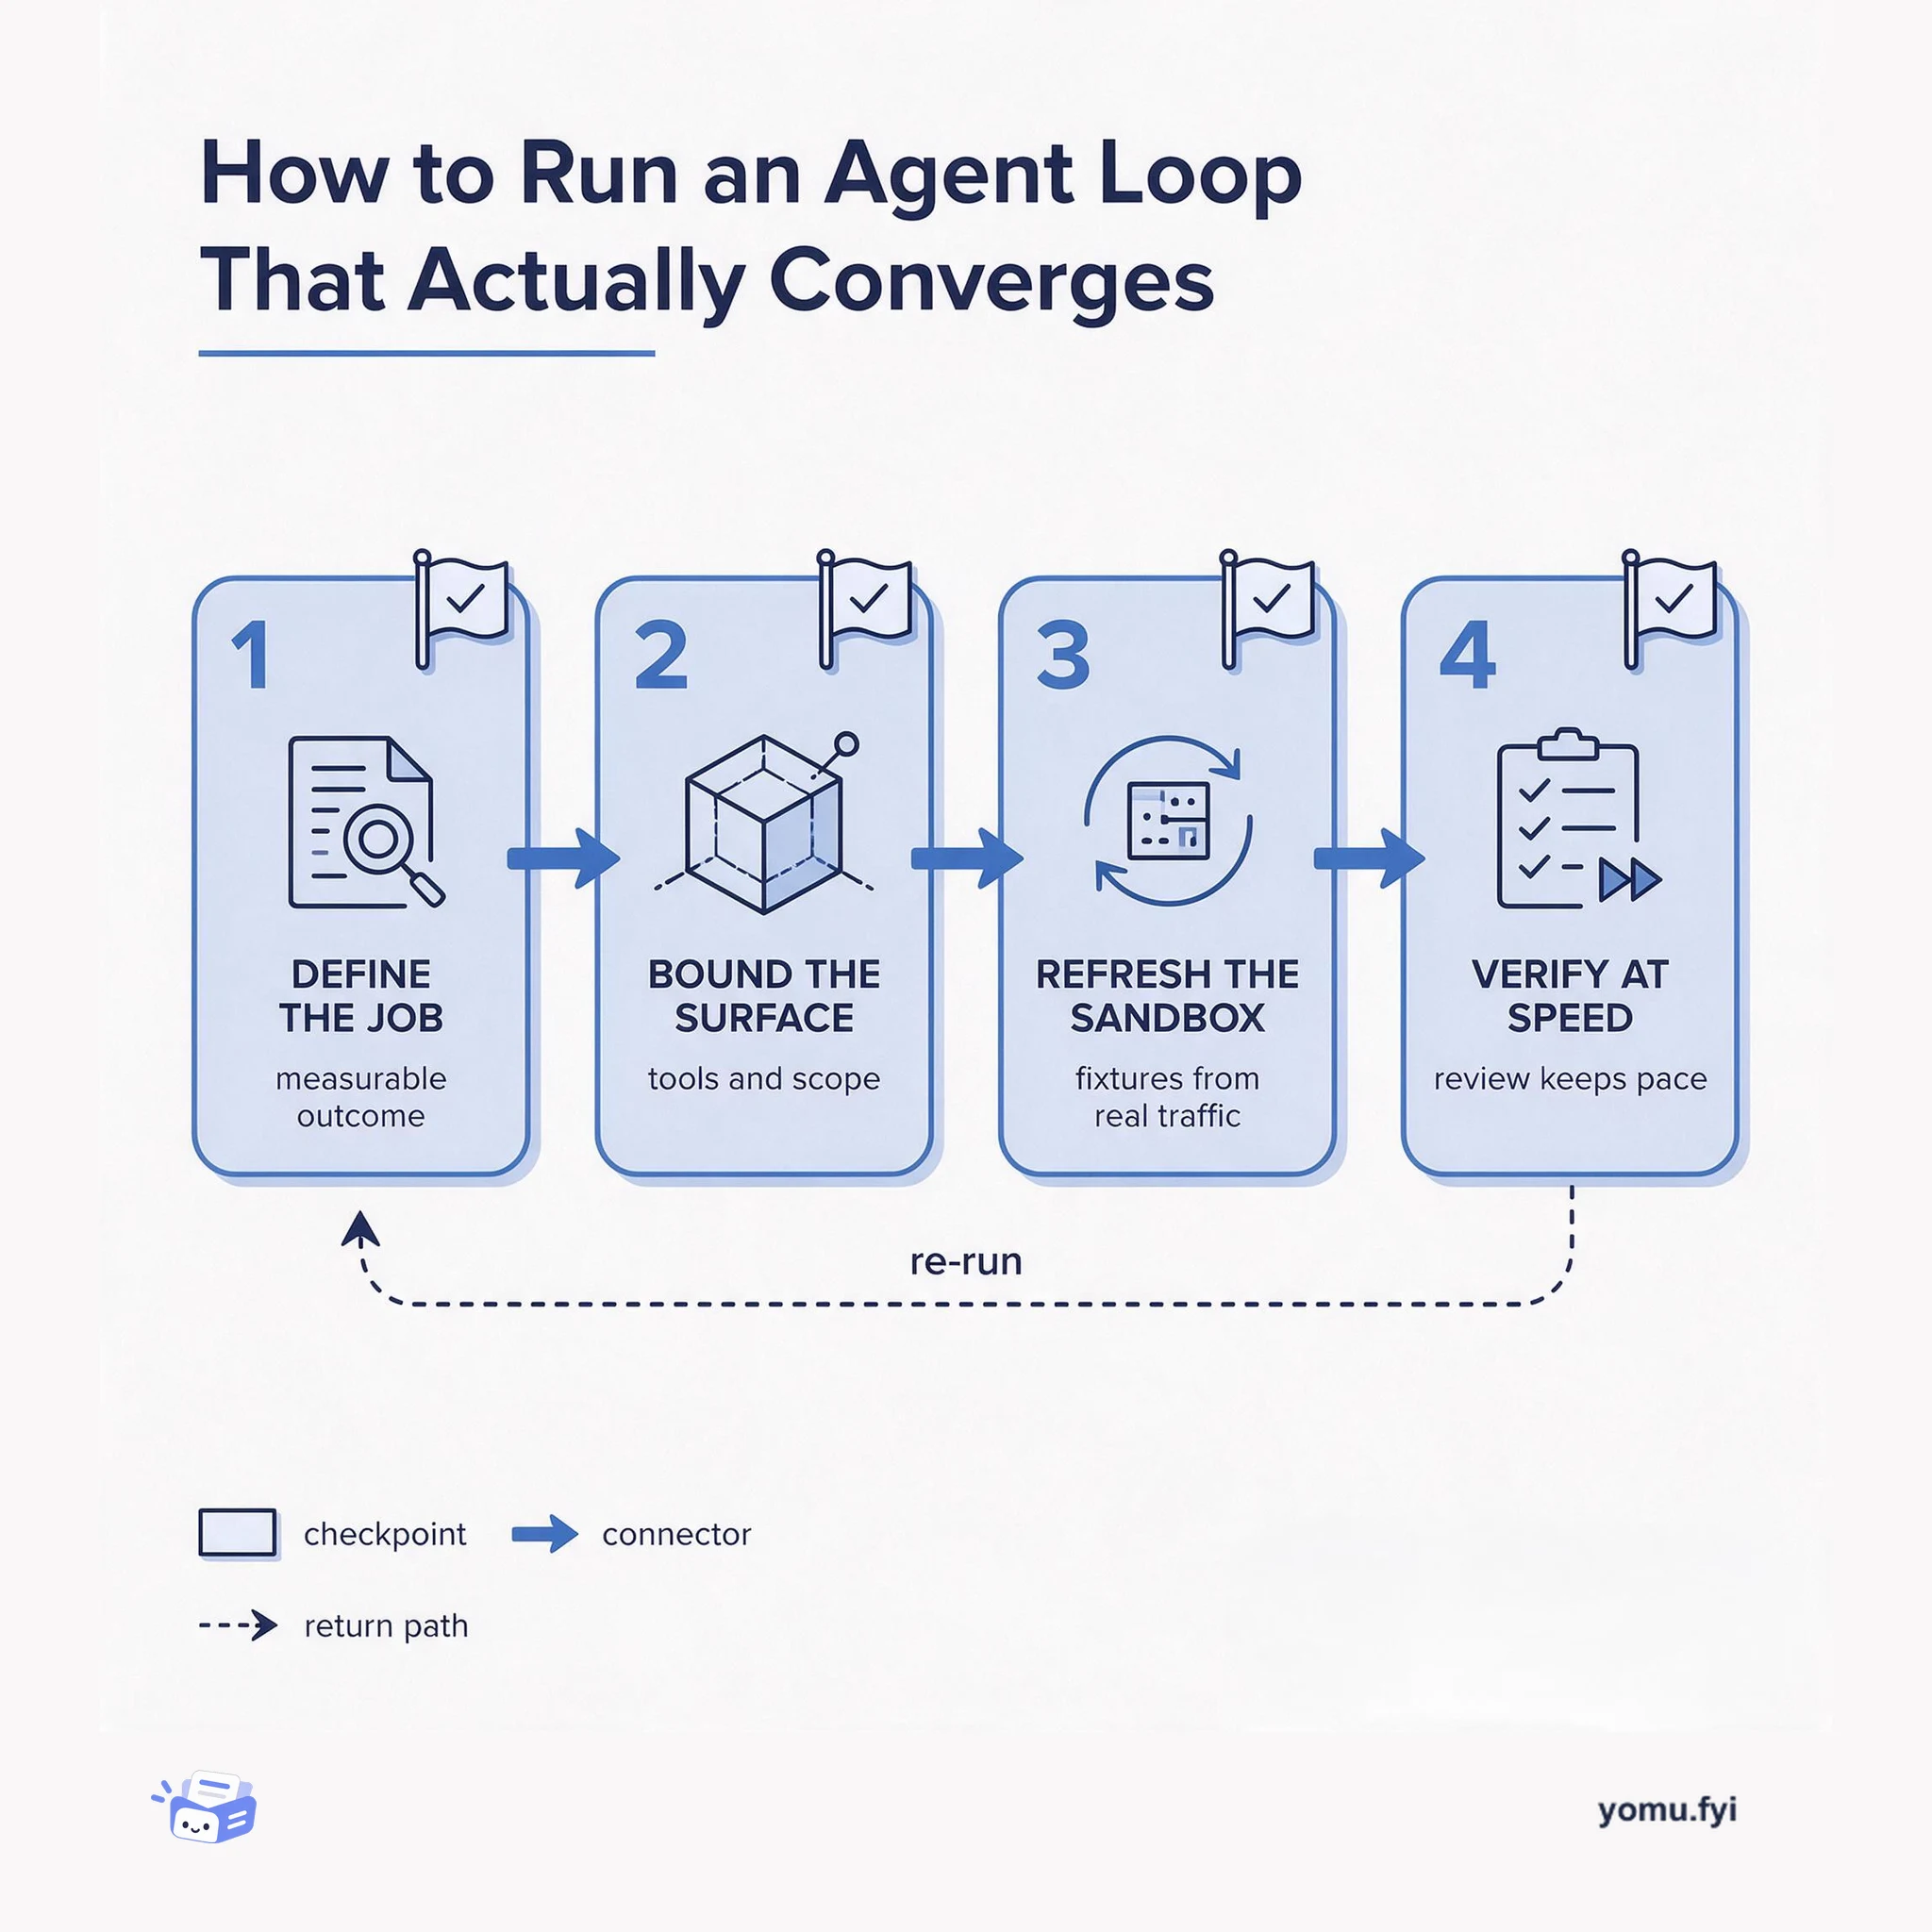
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
A five-checkpoint workflow for assignment problems: write the spec, name the objective, test whether choices interact, pick a solver class by scale, then validate against live state.
An assignment problem asks which objects go into which bins under a set of constraints, and the hard part is usually the framing rather than the solver. This explainer follows five checkpoints: separate the problem specification from the solution, name the objective and constraints, check whether choices interact, choose a solver class by scale and latency, then validate against live state. It matters because production systems solve these problems millions of times a day, and a skipped checkpoint yields answers that look correct but cannot be reproduced.
Mixed integer programming gives a provable optimum, so it fits smaller problems where correctness or auditability matters. Local search instead evaluates millions of moves per second and handles large sets; Meta's Rebalancer reports over a million objects and 5k bins at roughly 171 seconds average solve time. Choose by scale and by how much optimality you actually need.
No. The OpenShift autoscaling comparison notes that Cluster Autoscaler and KEDA cannot coexist on the same MachineSet because they would fight over replica counts. Give each resource a single owner and one clear trigger, then validate the resulting state instead of running competing decision loops.
The posts behind it
 Meta · · Announcement
Meta has open-sourced Rebalancer, a generic library for solving assignment problems that has been used internally for over nine years. Rebalancer separates problem specification from solution, using a three-step approach with modeling constructs like dimensions, partitions, scopes, and utilization, and a high-level spec API for common objectives and constraints. Problems are translated into an expression graph, and Rebalancer offers two solving techniques: an optimal solver using mixed integer programming (MIP) with commercial or open-source solvers, and a local search solver that evaluates millions of moves per second for large-scale problems. The local search solver handles problems with over a million objects and 5k bins, with an average solve time of 171 seconds. Rebalancer is used for roughly 40 million assignment problems daily across Meta’s infrastructure, and the open-source release includes a debugging UI called Rebalancer Explorer. The accompanying paper was published at OSDI’24.
 Hugging Face · · Problem & solution
Removing entire transformer blocks is a cheap way to speed up large language models, yielding predictable inference gains and stacking with quantization and other compression methods. The challenge is that block choices interact, making it a combinatorial problem rather than a simple ranking task. The authors reformulate block selection as a constrained binary optimization (CBO) problem, mapping it onto an Ising glass, a disordered spin system with all-to-all interactions and a fixed number of removed blocks. They note that mean-field methods, which treat each block independently, are inadequate for this interacting system. Block removal composes with quantization, low-rank compression, width pruning, and knowledge-distillation-based healing, fitting into a larger pipeline rather than competing with it. The paper is titled ‘LLM Compression by Block Removal with Constrained Binary Optimization.’
 Red Hat · · Explainer
This article compares two autoscaling approaches for Red Hat OpenShift compute infrastructure: the built-in Cluster Autoscaler and the KEDA-driven MachineSet Autoscaler. The key difference is the trigger mechanism: Cluster Autoscaler reacts to Pending pods, while KEDA scales based on external metrics like PromQL queries. KEDA triggers faster, scaling within about 15 minutes versus 24 minutes for Cluster Autoscaler, because it acts on metric thresholds before pods become unschedulable. Cluster Autoscaler offers built-in scale-down safety and zero configuration, while KEDA provides fine-grained, metric-driven control but requires the Custom Metrics Autoscaler operator. The choice depends on workload predictability, with Cluster Autoscaler suited for general-purpose workloads and KEDA for dedicated pools with predictable metric patterns. The two autoscalers cannot coexist on the same MachineSet, as they would fight over replica counts.
 Cloudflare · · Explainer
Cloudflare describes how excessive memory use in pingora-ketama, the consistent-hashing component of its Pingora Backend Router, was investigated as a resource-efficiency problem at global scale. Consistent hashing maps servers and cache keys onto a circular hash space, but a single hash per server creates uneven ranges, while multiple hashes improve balance; with 160 points per server, the coefficient of variation falls to about 8% in the 100-server example. The work produced a v2 ring with compacted storage, faster sorting, and a configurable base number of hashes per node, while retaining the existing v1 ring and supporting simultaneous use during migration. After the old ring was decommissioned, measured memory usage for PBR fell by 100TB globally, and the changes are available in pingora-ketama behind an unadvertised Cargo feature.
Red Hat · · TutorialAI infrastructure costs are often billed to a platform team as one lump sum, leaving Finance without a departmental breakdown and teams without feedback on their usage. The post presents a working demo on Red Hat OpenShift AI that attributes requests and token consumption through department-specific MaaS API keys, shared model servers, Prometheus metrics, Perses dashboards, and MLflow traces. In its example, three departments generate 79,420 inference requests and consume 634 million tokens against a $14,200 quarterly bill, while Marketing’s 32% GPU utilization reveals roughly $34,000 in annual waste. The system combines aggregate usage filters with request-level details such as prompts, token counts, latency, and calculated cost, and the post argues that showback helps identify inefficient allocations and model mismatches rather than police teams.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
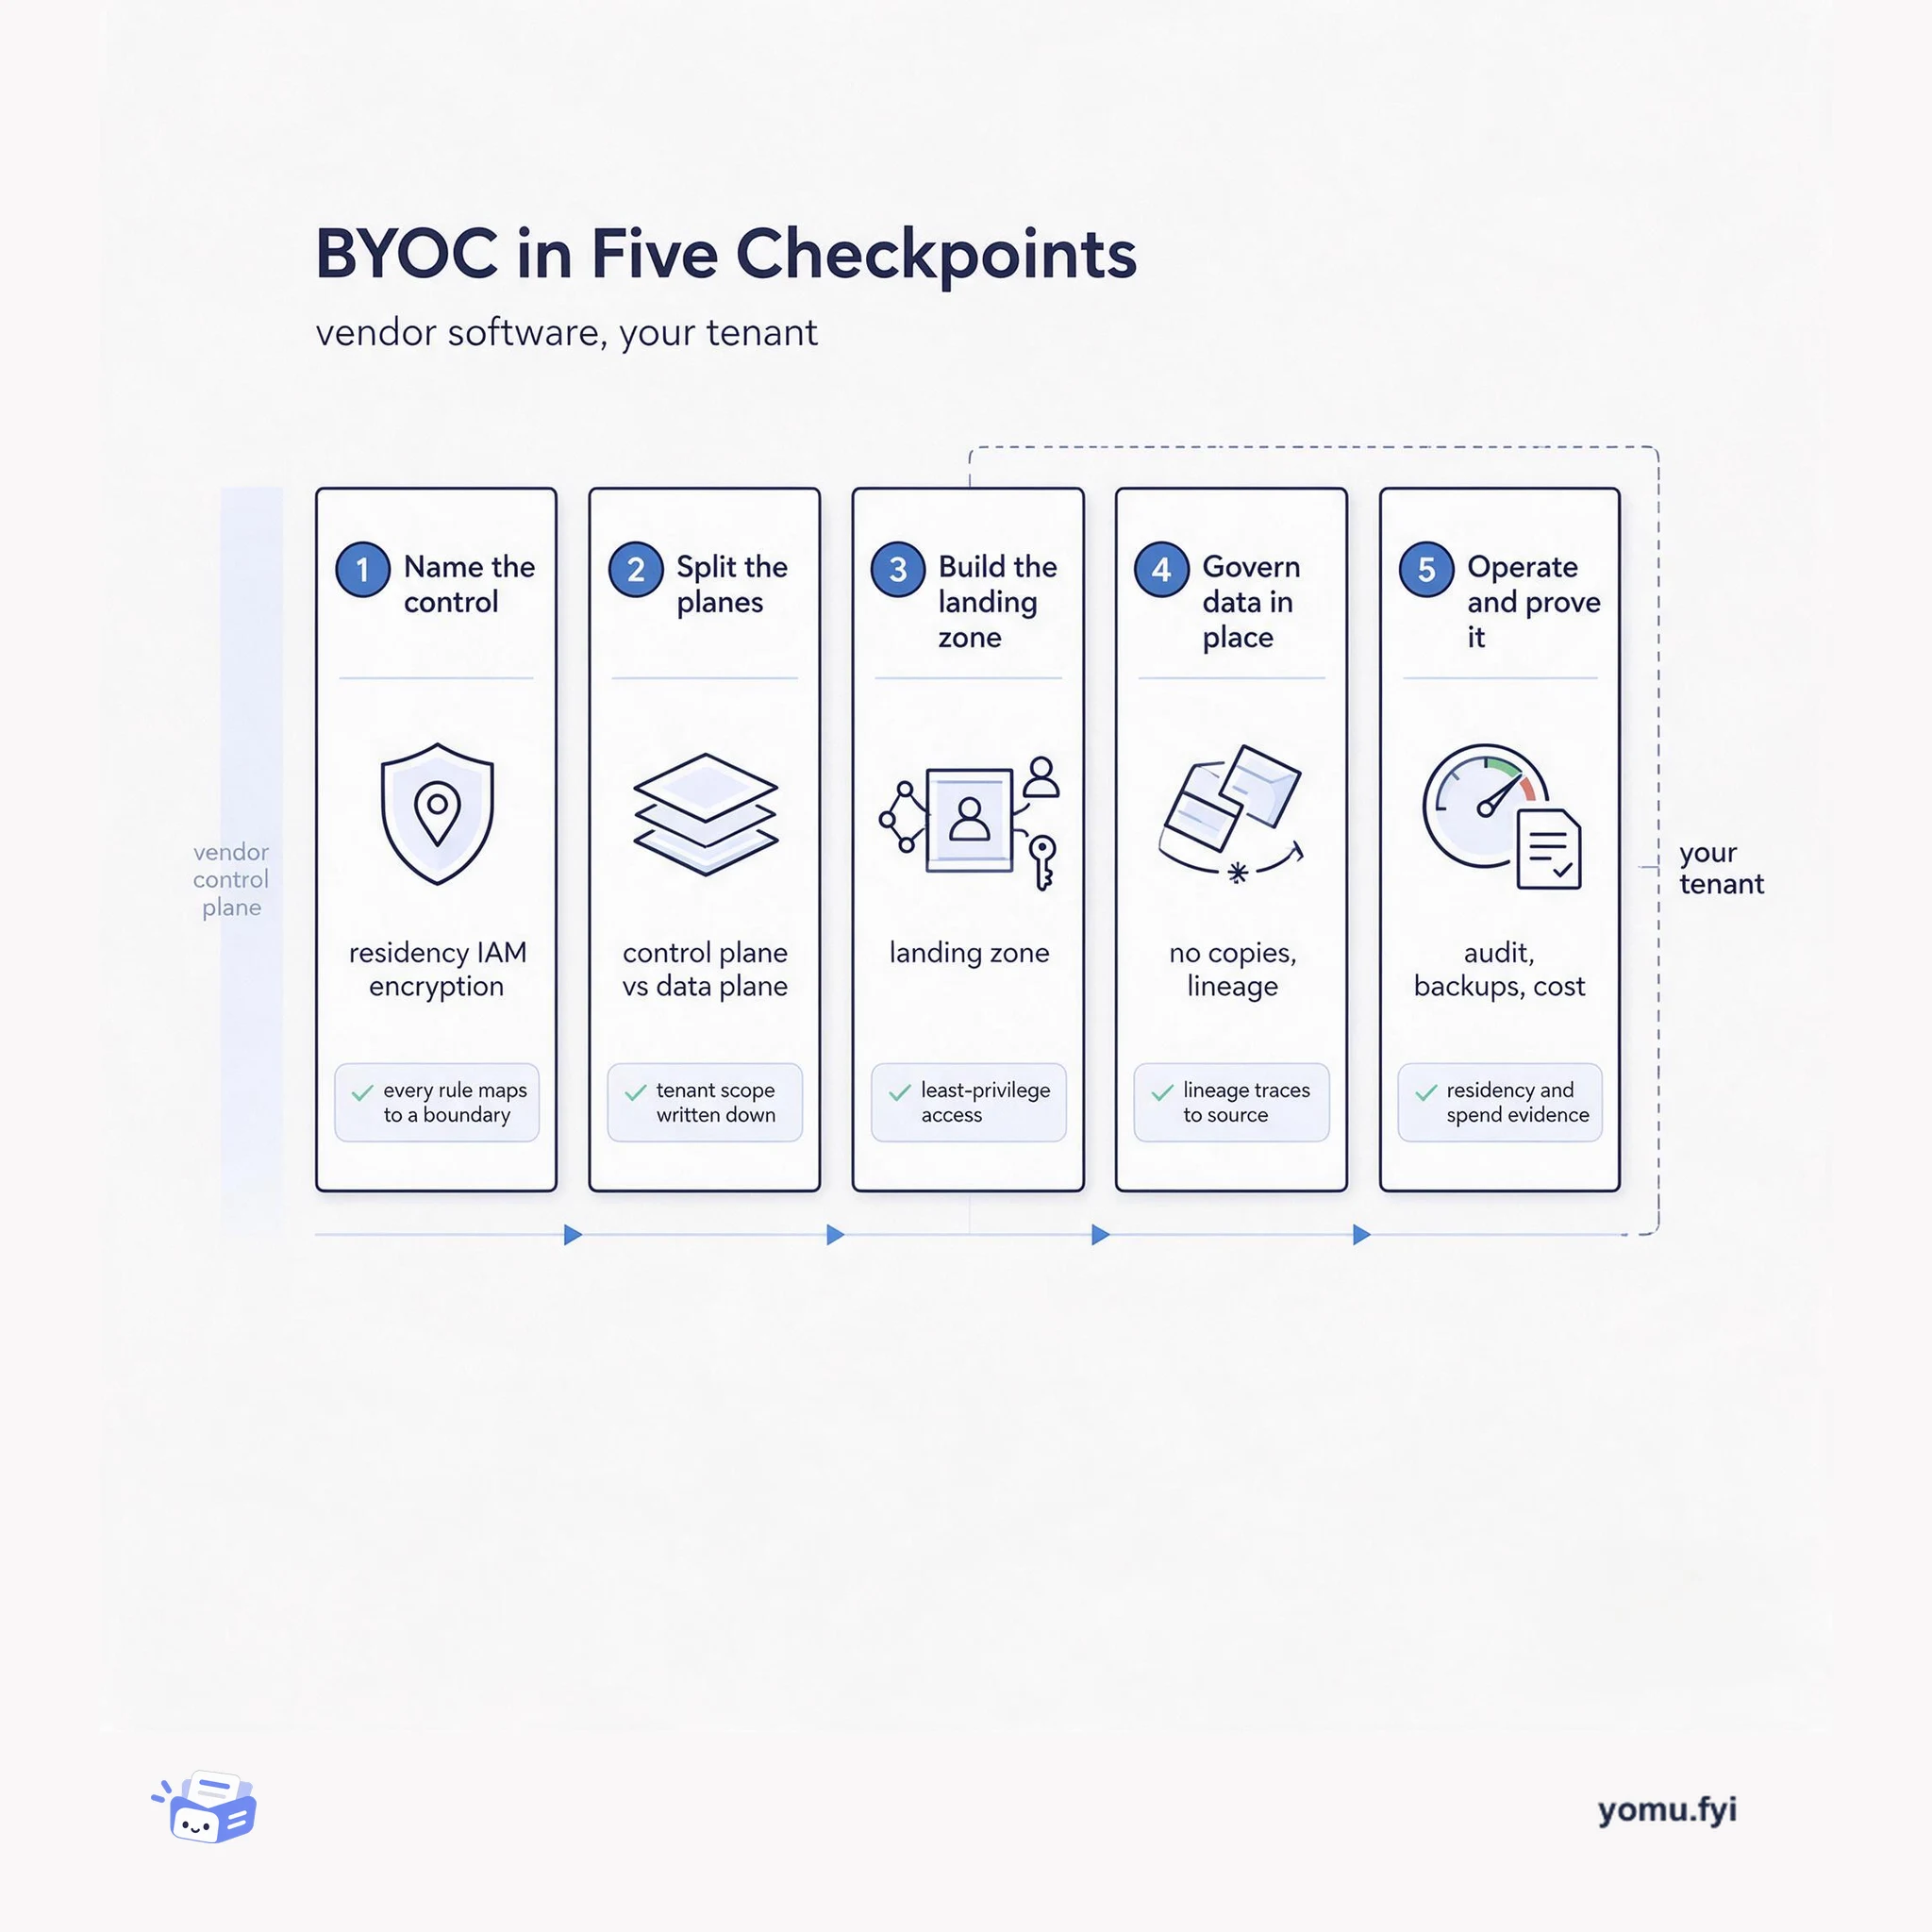
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.