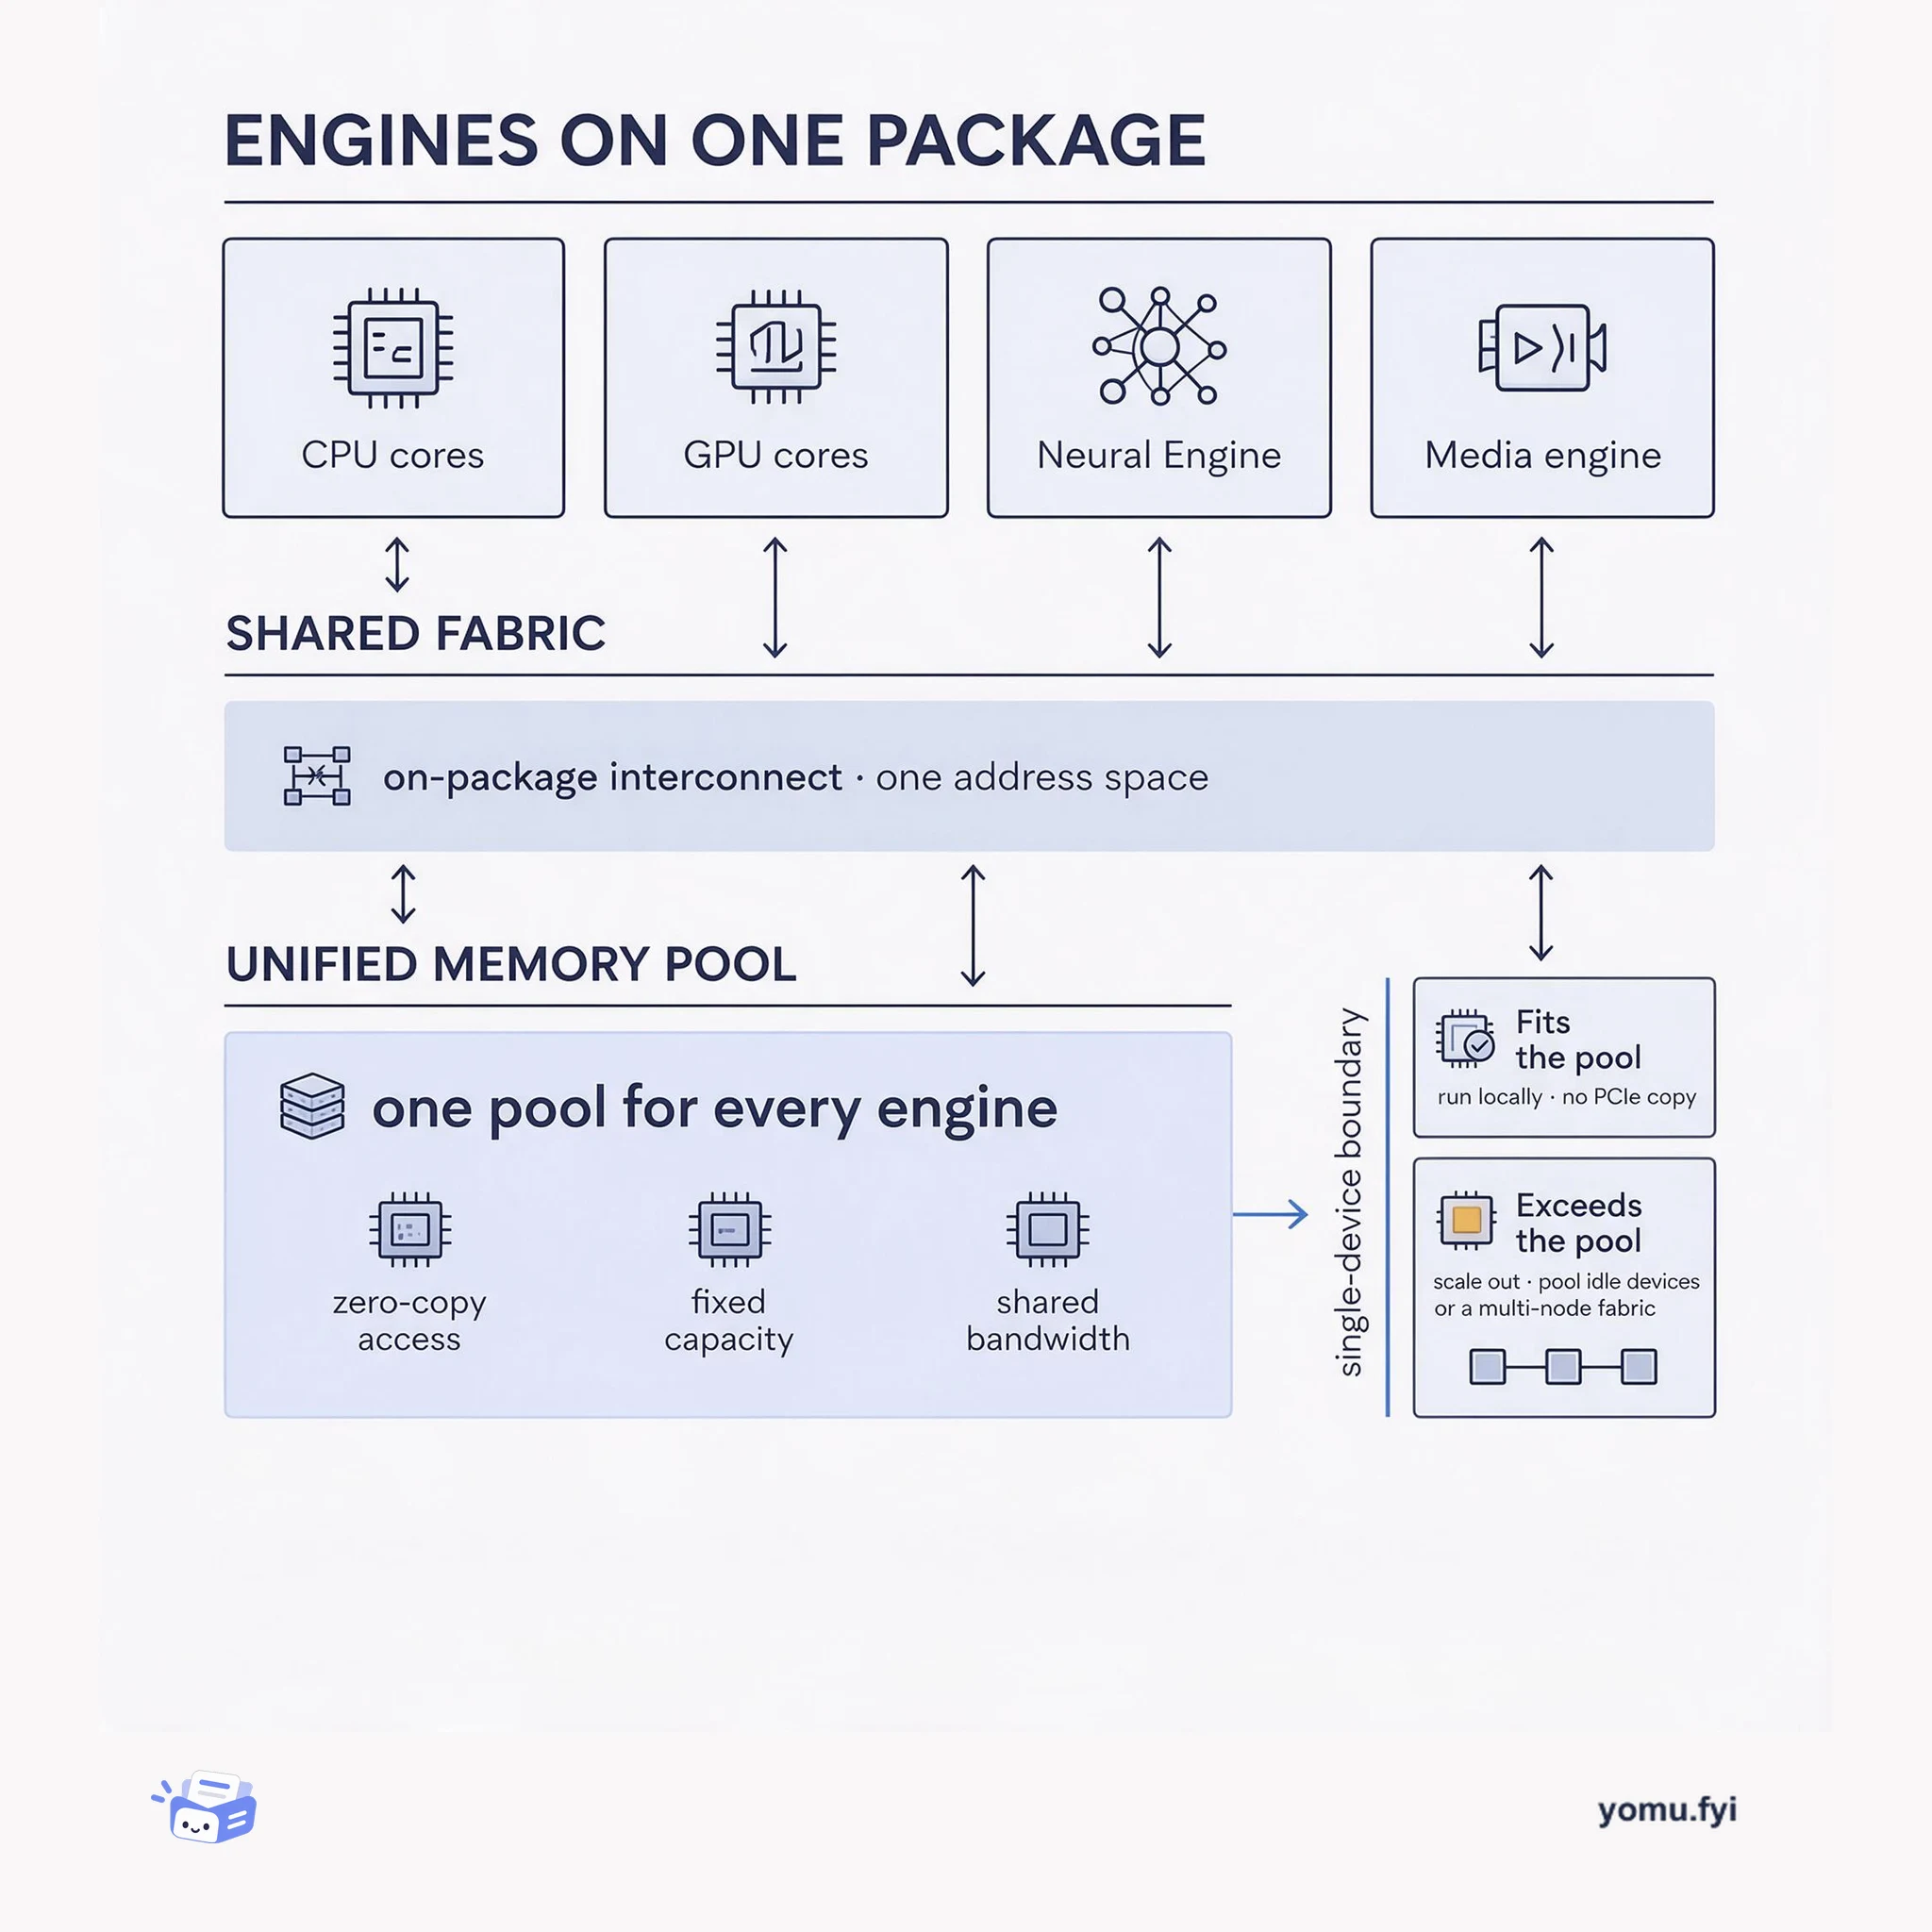
One Pool, Many Engines: The Architecture of Apple Silicon
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
Loading…
Topic
107 posts about GPU. Every summary links to the original.
See the idea
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
A GPU-resident astronomy pipeline keeps every stage of image analysis — load, align, subtract, detect, review — inside GPU memory instead of round-tripping through the CPU.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
This tutorial builds a Discord image-generation bot that uses Fooocus, an open-source interface for Stable Diffusion, to provide a Midjourney-like /imagine command. It separates the system into a normal Fly Machine running a Python Pycord bot and a GPU Machine running Fooocus-API, with Flycast connecting them over Fly.io’s private network. The bot defers Discord responses, polls for the generated image each second, and uploads the resulting file, while the post notes that this blocking flow will not perform well for hundreds of simultaneous users. Fly GPU rootfs supports the nearly 12GB image, and an L40S setup costs about $3.20/hr when running, with scale-to-zero intended to avoid charges for unused compute. GPU activity is verified with nvidia-smi, and the source code can be extended with additional commands and image-to-image features.
Fly.io announces GPU support for its cloud, extending its near-user deployment model to AI and machine-learning workloads at the edge. The offering attaches Nvidia A100 GPUs with 40GB or 80GB of RAM, CUDA support, eight AMD EPYC CPU cores, and volumes up to 500GB; L40s are also listed as coming soon and then noted as available. A sample fly.toml deploys Ollama with a 100GB model volume, while auto-start and auto-stop settings can reduce min_machines_running to zero when idle. GPU apps can scale across supported regions, retaining the same public IP address and TLS certificates, with an Amsterdam example using fly scale count 2 --region ams. Listed prices are $2.50 per hour for A100 40GB and $3.50 for A100 80GB, with reserved-instance and dedicated-host discounts available.
The post explains how graphics hardware evolved from CPU-offloaded video rendering into modern GPUs and why those devices now matter for AI/ML. It traces the path from the Commodore 64’s VIC-II and 3D accelerator cards through Quake, Tomb Raider, integrated graphics, and increasingly parallel hardware, while describing components such as framebuffers, command processors, shader hardware, memory, and display outputs. It then connects shader and CUDA cores to workloads including GPT-2, Stable Diffusion, and speech or text processing, and presents model chaining as more useful than treating models as isolated tools. A conference-video workflow combines ffmpeg, Whisper, subtitle segmentation, a large language model, Markdown, and human review to produce accessible written material. The conclusion distinguishes graphics-capable cards from A100 accelerators, which the post says cannot process graphics or encode video but are highly effective for AI/ML workloads.
Running GPU nodes for language-model inference can be costly because they often sit idle between requests, so this guide configures Ollama on a Fly.io Machine that scales to zero when idle. Ollama is described as a wrapper around llama.cpp, enabling self-hosted models with GPU acceleration, while about 70 lines of Go add authentication to protect the endpoint from unauthorized use. Deployment uses an A100-40GB GPU, a private Flycast address, automatic start and stop settings, and a 100GB persistent volume mounted at /root/.ollama so downloaded models survive stopped Machines. A stopped Machine no longer incurs GPU charges, but scaling to zero suspends it on the same host and may fail to wake during capacity issues. The setup supports CLI and API requests, WireGuard access, custom Modelfiles, and JSON-mode function-calling workflows.
The post argues that applications with critical AI features should avoid relying on proprietary, externally hosted models such as OpenAI’s ChatGPT and consider self-hosted open source alternatives. It identifies single-provider, regulation or policy, financial, and governance risks, illustrating the first with a Personal AI Fitness Trainer that failed during an OpenAI outage on November 8, 2023. When the AI is the app’s primary value proposition, an outage, changed behavior, denied usage, price increase, or provider leadership crisis can make the service unusable or threaten the business; less-central integrations may instead cause only degraded experience. Self-hosting a model can insulate an application from provider interruptions, licensing or usage-fee changes, regulator- or company-driven behavior changes, and leadership turmoil, while introducing GPU capital and operating costs with rented cloud GPU access available as an alternative to owning GPUs.
Fly GPU Machines are used to run Whisper Webservice for audio transcription, with the post noting that Fly GPUs are deprecated and unavailable after August 1. The setup uses a GPU-friendly Docker image, an a100-pcie-40gb Machine, and a Fly Volume mounted at /root/.cache/whisper so model files download and persist outside the image; ASR_MODEL=large and ASR_ENGINE=faster_whisper configure the service. It shows flyctl commands for creating the app, GPU-hosted volume, Machine, public IPs, and HTTPS routes, then verifies GPU availability with nvidia-smi and exposes the web UI and OpenAPI specification. A second path automates volume and Machine creation through the Machines API, requiring cpu_kind plus valid cpus and memory_mb values. It also demonstrates a custom Ubuntu 22.04 image with NVIDIA CUDA libraries, FFmpeg, Python, and Whisper, concluding that GPU Machines can support composable AI workloads.
Llama-2-70B is evaluated against GPT-3.5-turbo on serving cost and latency, with the comparison deliberately excluding GPT-4 and noting fine-tuning as a separate reason to choose Llama. The evaluation serves Llama on two 80-GB A100 GPUs in 16-bit precision, then uses transformer FLOP, memory-bandwidth, and KV-cache analysis to explain the difference between prompt processing and token generation. The measurements indicate that Llama-2 has worse completion-token pricing than GPT-3.5 on two A100s, while its prompt-token pricing is more than three times cheaper; eight A100s might improve pricing but introduce unacceptable latency. The resulting guidance favors GPT-3.5 for most workloads and open-source Llama models for prompt-heavy tasks such as classification or reranking, with batch processing and workloads lacking prompt tokens identified as additional cases where Llama may make sense.
The best engineering reads, once a week.




