One Pool, Many Engines: The Architecture of Apple Silicon
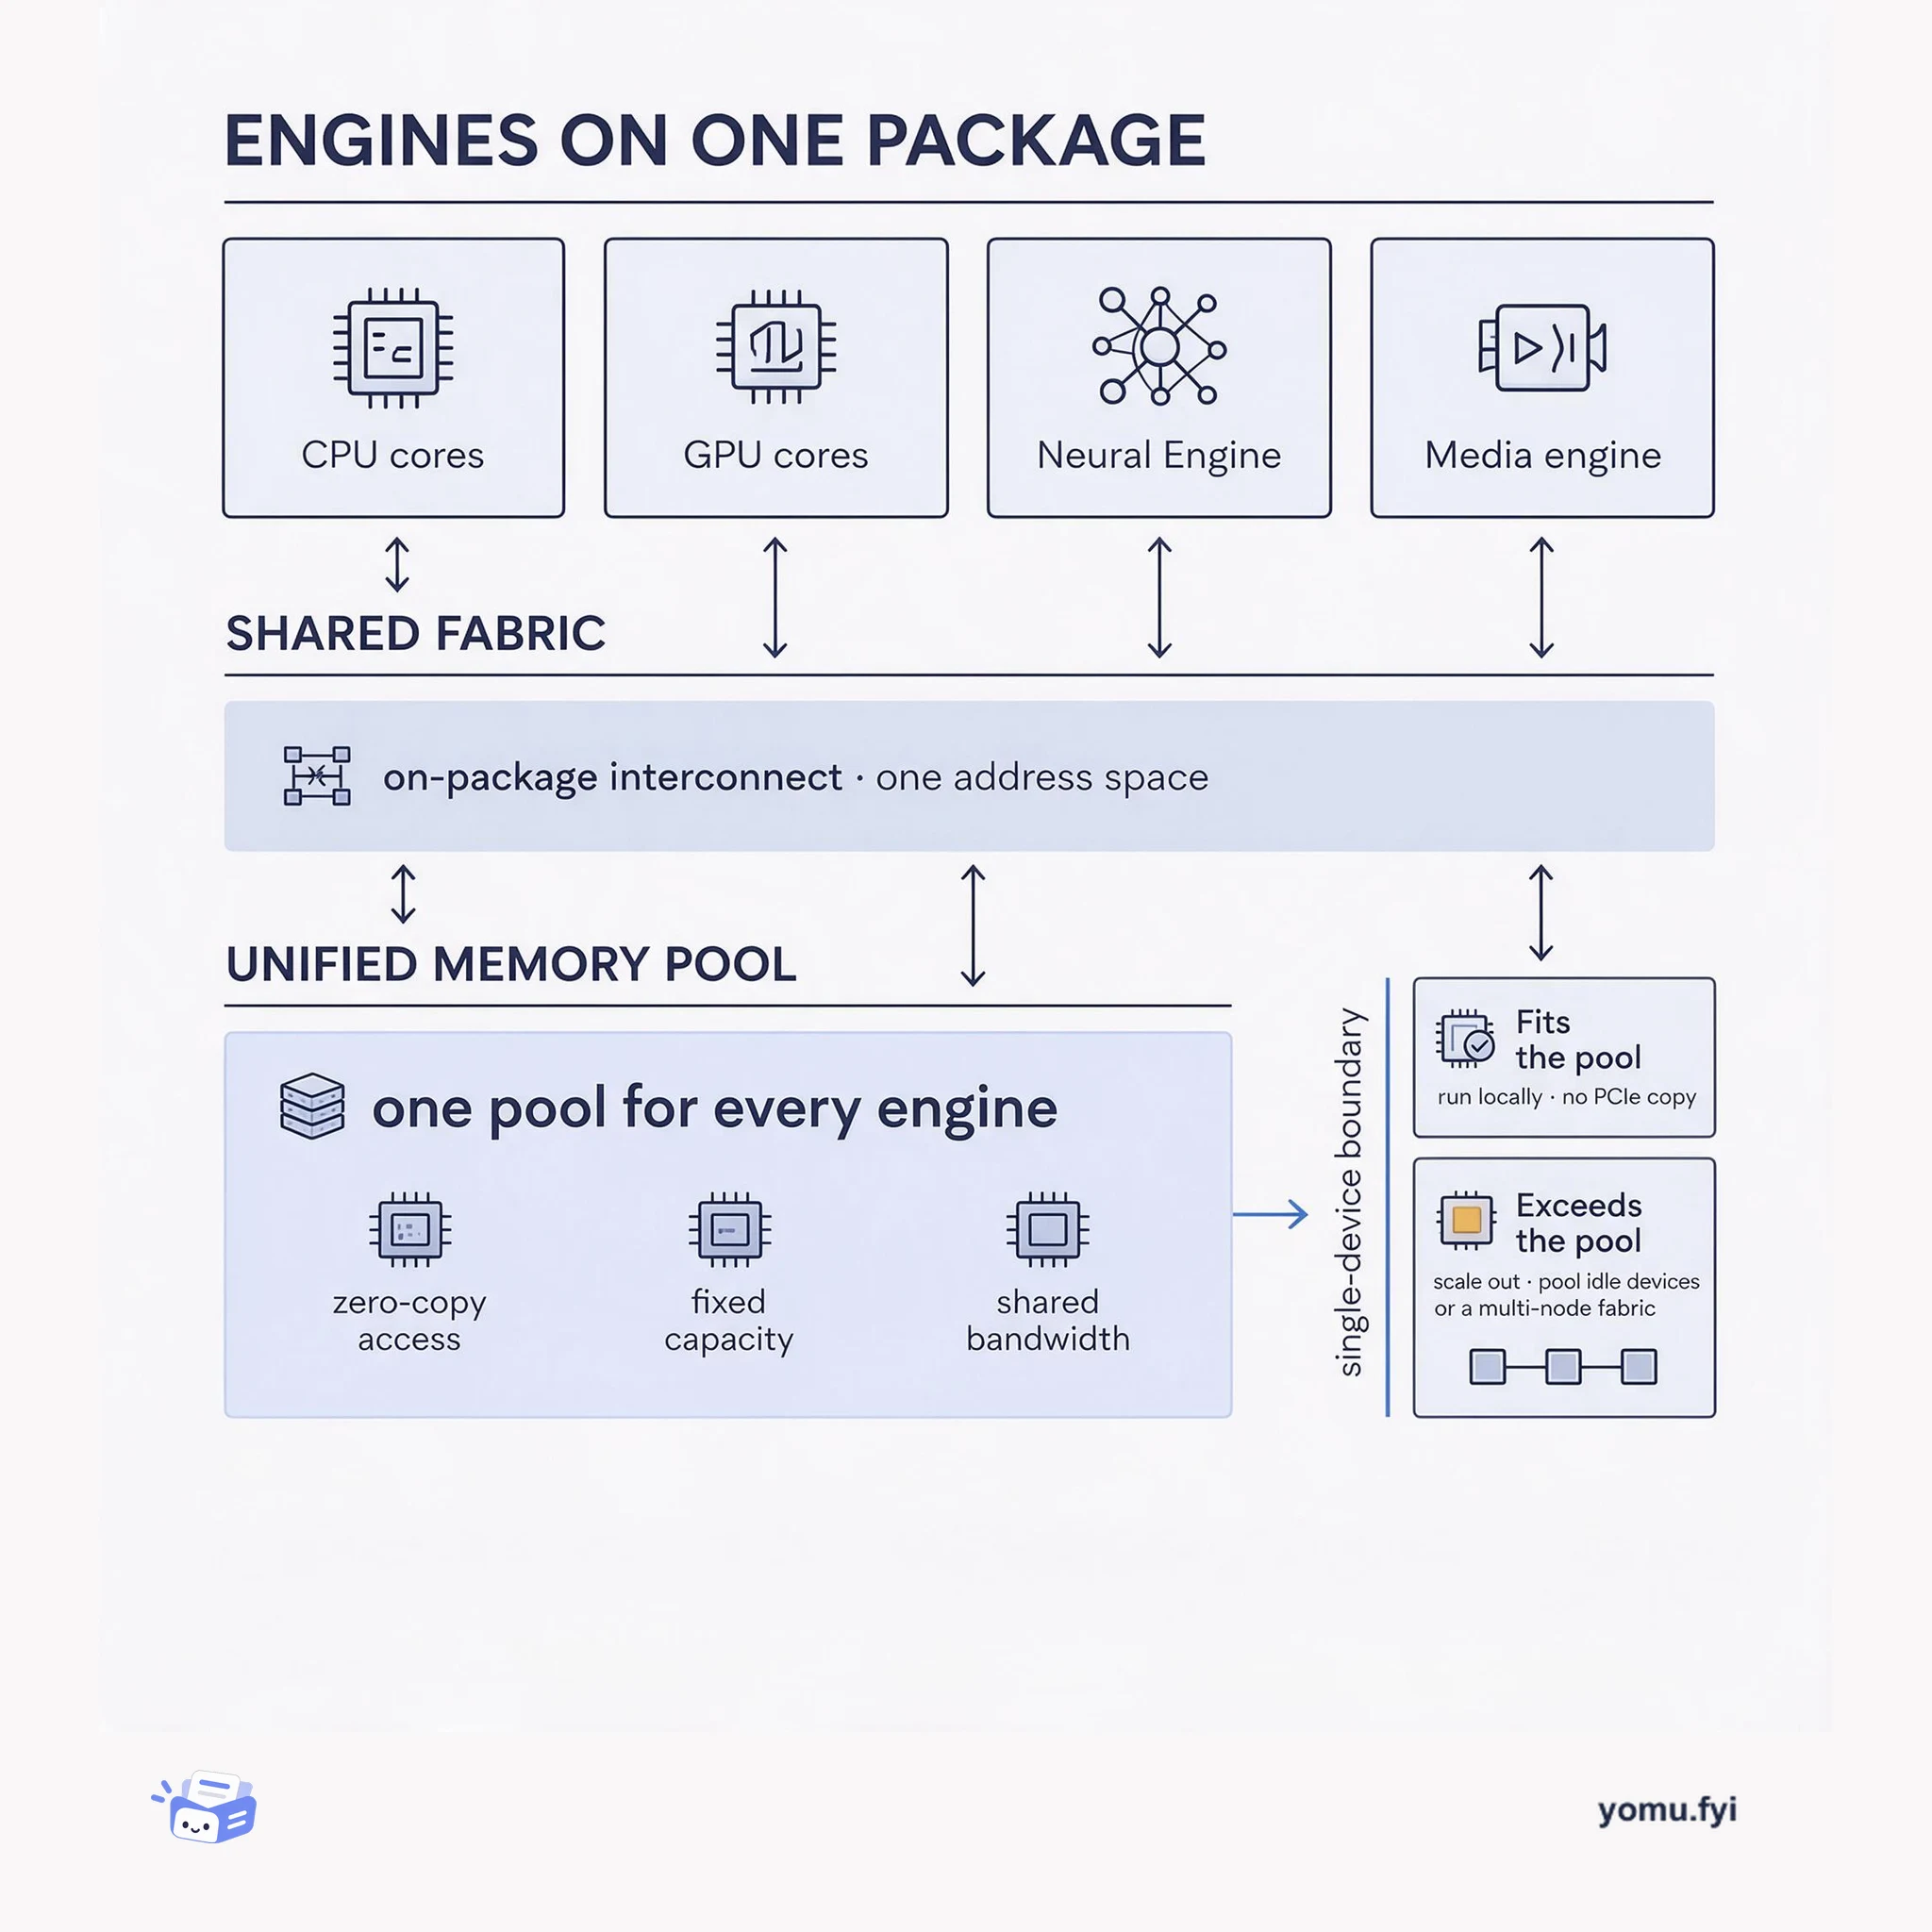
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
Loading…
Topic
107 posts about GPU. Every summary links to the original.
See the idea
Apple Silicon's defining choice is one shared memory pool for CPU, GPU, and Neural Engine. This diagram maps that fabric, the on-package bandwidth it buys, and the scaling limits it imposes.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
A GPU-resident astronomy pipeline keeps every stage of image analysis — load, align, subtract, detect, review — inside GPU memory instead of round-tripping through the CPU.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
DiffusionGemma is an experimental text-generation model and developer guide covering serving, customization, and non-autoregressive generation. Built on the Gemma 4 backbone, its 26B Mixture of Experts architecture activates 3.8B parameters during inference, refines 256-token canvases in parallel, and shifts the bottleneck from memory bandwidth to compute. Block autoregressive diffusion commits denoised 256-token blocks to the KV cache, combining bidirectional denoising with causal prefill for longer sequences; vLLM integration provides an OpenAI-compatible local server. A Sudoku fine-tuning example using Hackable Diffusion reports improvement from roughly 0% base-model success to 80%, while SFT reduces the demonstrated solve from 48 to 12 steps through adaptive stopping. The guide also identifies bidirectional attention and re-noising as mechanisms for global constraint handling and self-correction.
Google announces the Google Colab Command-Line Interface (CLI), a tool that connects a local terminal with remote Colab runtimes for developers and AI agents. It can provision GPUs or TPUs with commands such as colab --gpu A100, execute local Python scripts and ML pipelines remotely with colab exec, recover artifacts and replayable .ipynb logs, and provide interactive access through colab repl or colab console. The source demonstrates an agent-driven QLoRA fine-tuning workflow for google/gemma-3-1b-it on a Text-to-SQL dataset: an Antigravity agent provisions a T4, installs transformers, datasets, peft, trl, bitsandbytes, and accelerate, runs finetune_run.py, saves a notebook log, downloads model artifacts, and stops the runtime. The resulting safetensors adapter and configuration files can be loaded locally, while the CLI is presented as programmable and usable by terminal-based agents.
Anthropic says it has raised $65 billion in Series H funding at a $965 billion post-money valuation, with the round led by Altimeter Capital, Dragoneer, Greenoaks, and Sequoia Capital. The company says its run-rate revenue crossed $47 billion earlier this month and that the financing will support safety and interpretability research, additional compute, and expanded products and partnerships. It reports agreements for up to five gigawatts of new Amazon capacity, five gigawatts of next-generation TPU capacity with Google and Broadcom, and GPU access in SpaceX’s Colossus 1 and Colossus 2; AWS remains its primary cloud provider and training partner. The round includes $15 billion in previously committed hyperscaler investments, including $5 billion from Amazon, alongside strategic infrastructure partners Micron, Samsung, and SK hynix.
Reinforcement learning for post-training large language models has become infrastructure-constrained as teams move to multi-node configurations for larger models like Qwen 3 30B and Kimi K2.6. The RL loop divides into three independent infrastructure challenges: training with reliable forward and backward passes, high-performance inference rollouts, and thousands of concurrent sandbox environments for policy execution. Weight synchronization between trainer and rollout engine becomes the critical bottleneck in multi-node setups, with RDMA offering up to 100x speedup over TCP and significant cost savings per step. Teams commonly get stuck maintaining glue code, queueing for cluster time, and under-utilizing GPUs when sandbox buffers are not correctly sized. Modal addresses these with RDMA-connected clusters via a single rdma=True keyword, fast container boot, and the new open-source Modal Training Gym library that abstracts common scaffolding into under 100 lines of code.
Databricks describes an inference platform serving open-source and proprietary frontier models at more than 125T tokens per month, with reliability as the central challenge under spiky, multi-tenant demand. It identifies failures and latency risks from expensive GPU configurations, variable input and output lengths, long-context requests, multimodal preprocessing, and engine-level hangs. Its architecture combines rate limiting, capacity management, model units, Dicer load-aware sticky routing, and autoscaling; model units estimate multidimensional request cost and allocate capacity more predictably. For runtime reliability, prioritized black-box health checks trigger Kubernetes liveness restarts for silent hangs, completing detection and recovery in less than five minutes while eliminating false probe failures. Image-processing changes, including Torchvision processors and OMP_NUM_THREADS configuration, removed CPU throttling and increased completed requests per second by more than threefold with the same replicas and load; bursty workloads also achieved over 80% GPU savings versus static peak provisioning.
Modal announced a $355 million Series C at a $4.65 billion post-money valuation, led by General Catalyst and Redpoint, with participation from Menlo, Bain Capital Ventures, Accel, and all existing investors. The company grew fivefold since September and surpassed $300 million in annualized revenue. Modal is a cloud platform built for AI workloads, offering elastic inference, dynamic agent runtimes, and batch processing. Its Sandboxes feature, which provides isolated environments for untrusted code, has launched over 1 billion instances and accounts for more than a third of revenue. Modal plans to invest in low-latency inference, reinforcement learning infrastructure, and expanded agent computing capabilities.
Applied Compute, founded by former OpenAI Codex and o1 researchers, builds custom AI agents for enterprises through a post-training approach they call Specific Intelligence. Their core training mechanism is Reinforcement Learning, where agents repeatedly attempt tasks in replayable environments and are scored against reward functions to refine model weights. For clients like DoorDash and Cognition, this means training specialized agents for merchant onboarding and bug-catching that improve from continuous use. The company evaluated multiple infrastructure platforms before selecting Modal, which provides ephemeral sandboxes for complex environment simulation, sub-second cold starts to keep GPUs busy, and serverless fan-out for parallel grading. Modal’s primitives allow each phase of the RL loop—rollouts, evals, and inference—to operate with appropriate resources while sharing state efficiently.
GPU inference workloads suffer from spiky demand, leading to low GPU Allocation Utilization when capacity is fixed. Modal reduced replica startup latency from over 2 kiloseconds to about 50 seconds using four techniques. A buffer of idle GPUs removes instance allocation from the hot path. A custom content-addressed filesystem serves container images lazily from a multi-tier cache. CPU and CUDA checkpoint/restore fast-forward through initialization by directly restoring processes and GPU contexts into memory. These optimizations enable truly serverless GPU inference, as demonstrated by Reducto’s document processing scaling to thousands of GPUs with cold starts reduced from ~70s to ~12s.
Superhuman replaced a DIY vLLM-based serving stack for its grammar-correction model with Databricks model serving, targeting peak traffic above 200,000 QPS, sub-second P99 latency, four-nines reliability, and no quality regression. The platform combines an Endpoint Discovery Service with power-of-two-choices load balancing, concurrency-based autoscaling, and asymmetric scale policies to reduce hotspots and handle rapid traffic ramps. Lazy-loading container images changed startup from several minutes to a few seconds by fetching metadata first and retrieving 4MB blocks on demand. Runtime work on H100 GPUs raised per-pod throughput from 750 to 1,200 QPS: FP8 weight quantization contributed up to 30%, while a multiprocessing server added 20%, alongside C++ and asynchronous scheduling optimizations. The teams validated changes through shadow testing and evaluation harnesses, and Superhuman is migrating additional models and workflows to the platform.
The post walks through constructing a custom agent harness with the OpenAI Agents SDK and Modal Sandboxes, starting from a minimal coding agent that executes shell commands directly on the host. To improve safety, the agent is moved into isolated Modal Sandboxes, which are secure Linux environments that can be equipped with GPUs for compute-intensive tasks like training models. Memory is added via Sessions to accumulate context across turns, and subagents are introduced to handle focused subtasks with fresh context windows, preventing context bloat in the orchestrator while allowing long-horizon work. An async subagent pool enables parallel execution, with quotas to limit GPU spend, and filesystem snapshots allow checkpointing and deduplication of setup work across subagents, saving time and offloading memory. The harness is applied to the Parameter Golf challenge, where an orchestrator delegates parallel training experiments across different ML frameworks on GPUs, demonstrating autonomous research capabilities with composable skills.
The post reports a three-week experiment in which a multi-agent system optimized 235 CUDA kernel problems generated from workloads spanning more than 124 production open-source models. Using SOL-ExecBench on 27 NVIDIA Blackwell 200 GPUs, the system used a planner to distribute and rebalance work, while autonomous workers benchmarked, debugged, and refined kernels without developer intervention. It ran separate CUDA C with inline PTX and CuTe DSL runs, reaching assembly-level optimization and learning a documented higher-level API. Against a single-agent optimized PyTorch baseline, it outperformed 149 of 235 problems, achieving a 1.38x geometric mean ratio, while 45 solutions exceeded 2x. The highlighted cases included an 84% geomean gain over a human FlashInfer baseline for paged-prefill attention, a 39% gain for NVFP4 MoE linear, and a GEMM reaching 86% of a tuned cuBLAS baseline; median SOL was 0.56, leaving room for improvement.
MoE inference commonly organizes decode around experts, but the post describes “warp decode,” an output-centric kernel for small-batch generation on NVIDIA Blackwell GPUs. Instead of staging tokens into expert-major buffers, each warp owns one output scalar, streams the required weight rows, accumulates contributions from all eight routed experts in FP32, and uses warp-level reductions; the gate/up and down projections are compressed into two kernels. This removes padding, scatter, combine, activation gather, and per-expert output buffers, while keeping BF16 activations and avoiding intermediate quantization. On B200s, the approach delivered 1.84x higher decode throughput, sustained 3.95 TB/s at batch size 32, and produced outputs 1.4x closer to a full FP32 reference.
Composer 2 is a coding model for agentic software engineering, and its technical report describes training from continued pretraining of the open Kimi K2.5 base model through large-scale reinforcement learning. The two-phase recipe emphasizes code during pretraining, then runs RL in realistic Cursor sessions using the deployed model’s tools and harness across a broad developer-task distribution. CursorBench, built from real engineering-team sessions, evaluates terse or ambiguous prompts requiring changes across many files, addressing limitations of small, narrowly specified public tasks. Composer 2 scores 61.3 on CursorBench, 37% above Composer 1.5, plus 73.7 on SWE-bench Multilingual and 61.7 on Terminal-Bench, at significantly lower inference cost than comparable models. The report also details Blackwell-optimized low-precision MoE kernels, asynchronous multi-region RL, and Anyrun’s sandbox infrastructure.
Composer is a mixture-of-experts agent model for software engineering that targets interactive use, with reported frontier coding results and generation speed four times faster than similar models on the authors’ benchmarks. It is trained with reinforcement learning on real-world software engineering challenges in large codebases, using production search and editing tools, terminal commands, and codebase-wide semantic search. Training responses may be code edits, plans, or informative answers, while the process rewards efficient tool use, parallelism, minimal unnecessary responses, and evidence-based claims. Evaluation uses Cursor Bench, built from real agent requests and curated optimal solutions, measuring correctness alongside adherence to existing abstractions and software engineering practices. The training stack combines asynchronous reinforcement learning with PyTorch and Ray, MXFP8 MoE kernels, expert parallelism, hybrid sharded data parallelism, and sandboxed cloud environments scaled to hundreds of thousands concurrently.
An upgrade from Hopper H100s to Blackwell B200s exposed the Mixture-of-Experts (MoE) layer, implemented with MegaBlocks, as a major training bottleneck: it consumed nearly 53% of forward-pass time and 27% of backward-pass time. The team rewrote the layer at the GPU-kernel level using CUDA, PTX, and some ThunderKittens, while moving from BF16 to microscaled FP8 (MXFP8) with nearly zero loss in training quality. The implementation addresses Blackwell-specific tensor memory constraints and quantization overhead, including custom MXFP8 quantization that sustains more than 6.2 TB/s and emits scale matrices directly compatible with tcgen05.mma. On an internal model, MoE execution became 3.5x faster in both passes, producing a 1.5x end-to-end speedup on Blackwell and 2x versus the original Hopper setup, measured in tokens per second per GPU.
Fly.io’s GPU bet was intended to give internet-facing apps fast AI/ML inference through Fly GPU Machines, which pair a hardware-mapped Nvidia GPU with a Fly Machine. Building them required dedicated GPU servers, Intel Cloud Hypervisor with PCI passthrough, driver work, orchestrator changes, security assessments, and handling large model-weight files. The product has not found product-market fit because most software developers want LLM APIs and services such as OpenAI, Anthropic, Claude, GPT, Replicate, or RunPod rather than raw GPUs, while serious GPU users seek much larger clusters and lightweight users may be too uncertain a market. L40S demand exists, but those GPUs are not driving the core business. Fly.io will keep existing GPU Machines but does not plan a near-term v2, concluding that the bet was worth making without compromising its isolation or developer experience.
eBay developed e-Llama, customized 8B and 70B language models, by adapting Meta’s Llama 3.1 models to e-commerce rather than training entirely from scratch. The approach uses continued pretraining on filtered public listings, product reviews, classifier-selected open-source examples, replay data, and 10% non-English general-domain data to add domain knowledge while limiting catastrophic forgetting. Training ran on 480 NVIDIA H100 GPUs using Megatron-LM, 3D parallelism, flash-attention-2, a 1:1 general-to-e-commerce sampling ratio, a learning-rate maximum set to 10% of the original, and one trillion tokens. The 70B model required about one month and 340,000 GPU-hours. E-commerce benchmarks improved approximately 25% in English and 30% in non-English, while general-domain NLU degraded 1% for e-Llama 70B; subsequent instruction tuning added safety and instruction-following guardrails.
Livebook, FLAME, and the Nx stack combine Elixir notebooks, elastic execution, and GPU-backed machine learning into a workflow that can move from a laptop to remote infrastructure. Livebook can start runtimes on Fly Machines, connect to existing Erlang/Elixir applications, and synchronize notebook dependencies and modules across nodes while preserving access to private resources within a Fly organization. FLAME wraps arbitrary code in Flame.call, manages executor pools, controls node limits and concurrency, streams results, and shuts down idle nodes or the cluster after disconnection. In the demonstrated AI workflow, video stills are processed on GPU Fly Machines with Llama, then Mistral summarizes the returned descriptions. The same setup also drives a 64-GPU hyperparameter run for BERT, with each L40s node preparing dependencies, loading data, fine-tuning, and streaming chart results to Livebook.
Fly.io lowered the hourly price of NVIDIA L40S GPUs to $1.25, making them available at the same price as A10s after customer data showed that A10s—not the more powerful cards—were its most popular GPU. The post argues that most users adding GPUs to fast networks are running inference rather than training, making networking, memory, object storage, and request latency more important than access to an H100. The L40S is described as an AI-optimized L40 with AI compute performance comparable to an A100, while the L40 retains graphics hardware and is designed for rack use with more memory and lower energy consumption than gaming GPUs. The intended combination places model parameters, datasets, and compute near one another on Fly.io’s Anycast network and Tigris object storage. Examples include Llama 3.1 70B, Flux, Whisper, SegAlign, and DOOM Eternal.
Fly.io has made GPU instances available to everyone, adding datacenter-grade accelerators to its globally distributed compute platform. Users can select Ampere A100 variants with 40GB or 80GB of memory, or a Lovelace L40s with 48GB, by setting an app or process’s vm.size to the corresponding GPU kind. The post demonstrates an Ollama deployment using an L40s, a 100GB persistent volume mounted at /root/.ollama, and HTTP service settings that allow machines to stop and start automatically with zero minimum running machines. These instances are positioned for large language model inference, text transcription, and image generation; lower-cost A10 GPUs are planned for the next few weeks, while some organizations may need additional verification based on account age and payment history.
The best engineering reads, once a week.