How Apache DataFusion Runs SQL In-Process
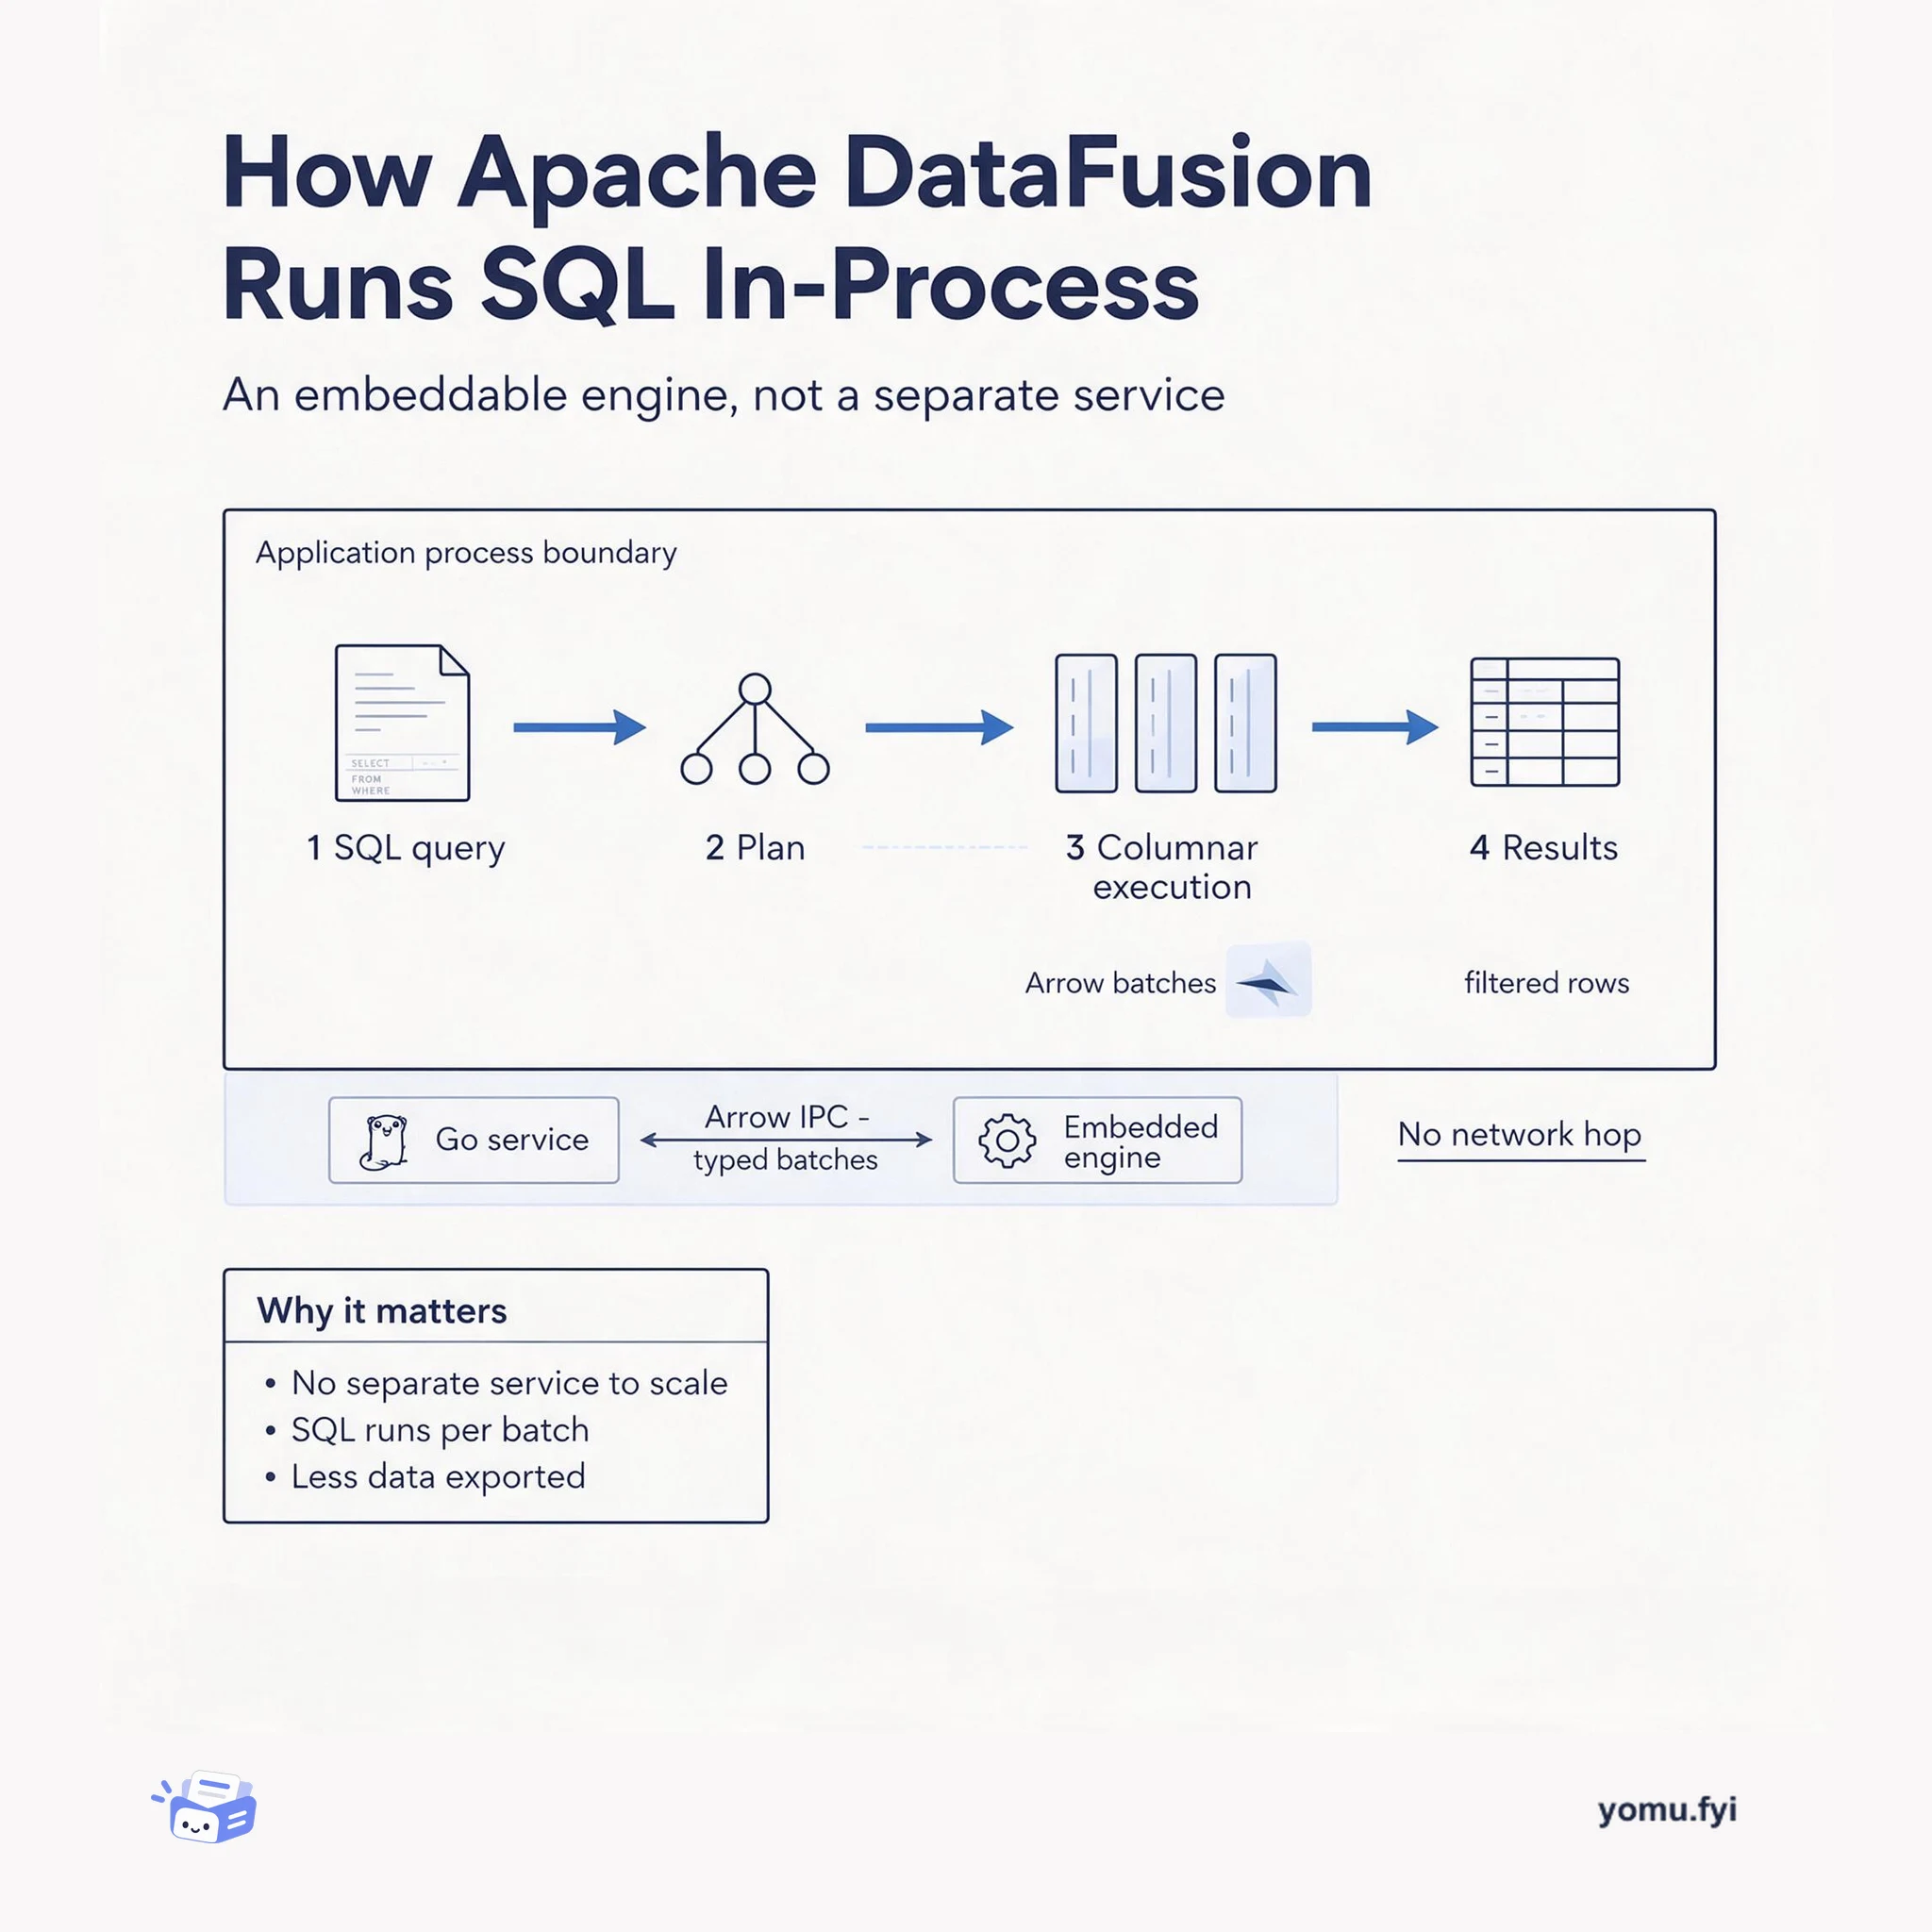
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
BioNeMo Inference Runtime runs one pipeline per target: parse, tokenize, generate features, infer on a GPU replica, and write a structure. This diagram traces those stages and the throughput trade-off.
BioNeMo Inference Runtime wraps supported structure-prediction models in a single end-to-end processor: each InputRequest moves through parsing, tokenization, feature generation, GPU inference, and PDB or mmCIF writing. A Ray backend places complete model replicas on GPUs so independent targets run concurrently, while a direct PyTorch path stays open for custom code. On a matched 1,000-target human-dimer benchmark, it folded 58.5K residues per allocated GPU-hour versus 20.2K for the tested public implementation, which ran out of memory on 29 targets. That roughly 2.90x gap and the accompanying power estimates are why the pipeline shape, not just the model, decides cost.
Because the unit of work is a whole structure prediction ending in a PDB or mmCIF file, not a token stream. Residues per allocated GPU-hour folds parsing, tokenization, features, GPU inference, and write-out into one number that matches how folding batches are billed. It also surfaces failed targets that a per-step rate would hide.
Treat it as a workload-specific reference, not a guarantee. It comes from a matched 1,000-target human-dimer benchmark: 58.5K folded residues per allocated GPU-hour versus 20.2K for the tested public implementation, which ran out of memory on 29 targets. The 11 versus 35 MWh figures are rated-power-equivalent estimates that exclude data-center overhead.
The posts behind it
 NVIDIA · · Explainer
NVIDIA Confidential Computing (CC) enables secure AI inference by using memory-encrypted confidential VMs, confidential GPUs, and encrypted NVLink. Running inference frameworks like TensorRT LLM in a CC environment introduces performance overhead because secure execution changes assumptions about memory movement, timing, and multi-GPU communication. To quantify this overhead, the post presents a controlled methodology comparing CC-on and CC-off performance on a workload with long input context, extended output generation, and low concurrency. With CC-aware adaptations—including pageable memory selection, asynchronous readback, GPU %globaltimer for autotuning, and CC-aware multi-GPU communication—TensorRT LLM retained 96.1–98.2% of baseline throughput on eight NVIDIA B200 GPUs while keeping per-token latency overhead below 5%. The post concludes that security configuration and inference optimization should be treated as a single deployment problem for organizations moving private inference into production.
NVIDIA · · ExplainerAI factories are power-limited systems where GPU workload placement is a key optimization; poor placement fragments topology domains and forces traffic across shared links, reducing throughput and raising job costs. NVIDIA Topograph discovers cluster topology from cloud APIs or on-premises fabric systems, normalizes it into a common model, and publishes it in formats each workload manager expects, such as Kubernetes node labels, Slurm topology configuration, or Slinky ConfigMaps. It uses five components: API Server, Node Observer, Node Data Broker, Provider, and Engine to keep the topology view current as the cluster changes. The post covers deploying Topograph with Helm on Kubernetes, as a system package on Slurm, and as a Helm chart on Slinky, with support for cloud providers including Google Cloud, Lambda, Nebius, Nscale, and OCI. Topograph works alongside Dynamic Resource Allocation and KAI Scheduler to enable topology-aware gang scheduling, improving AI factory efficiency and tokens per watt.
 Together AI · · Announcement
Deploying a new model checkpoint in production typically requires a tradeoff: a hard swap exposes all users to regressions at once, while a DIY staged cutover relies on manual traffic shifting. Together AI’s rollout system automates this by moving traffic between source and target deployments through configurable canary steps, such as 5%, 25%, 50%, and 100%. Each step runs health checks before shifting traffic, enforces a propagation wait for routing caches, and drains the source only after traffic has moved. Optional metric gates, like p95 latency, run after each step; if a gate trips, the rollout pauses automatically and waits for human action. In a real canary from Qwen2.5-7B to Qwen3.5-9B, a 137% p95 regression was caught at 10% traffic, allowing reversal with no failed requests.
NVIDIA · · AnnouncementNVIDIA TensorRT multi-device inference enables a single TensorRT network to execute across multiple GPUs using NCCL-backed distributed collectives, supported from TensorRT 11.0. Integrated into Dynamo-Triton release 26.07, one model instance can own multiple GPUs and expose a single gRPC endpoint so the client does not coordinate GPU ranks. The post demonstrates this with Cosmos 3 Nano video generation, where the transformer uses Ulysses context parallelism to distribute 44,160 video tokens across up to eight GPUs. End-to-end latency drops from 156.6 seconds on one GPU to 34.2 seconds on eight GPUs, achieving a 6.09x transformer RPC speedup. Teams can trade additional GPU resources for shorter request latency while keeping the application interface and surrounding workflow stable.
NVIDIA · · TutorialProteome-scale biomolecular structure prediction requires moving large worklists efficiently, and NVIDIA BioNeMo Inference Runtime (BioIR) accelerates supported models on NVIDIA GPUs while retaining a PyTorch workflow. Its end-to-end processor passes InputRequest objects through parsing, tokenization, feature generation, GPU inference, and PDB or mmCIF writing; a Ray backend places complete model replicas on GPUs for concurrent independent inputs, while direct PyTorch integration supports custom code. In a matched 1,000-target human-dimer benchmark, BioIR completed all targets at 58.5K successfully folded residues per allocated GPU-hour versus 20.2K for the tested public implementation, a 2.90× improvement, which ran out of memory on 29 targets. Rated-power-equivalent estimates for one million comparable targets were 11 versus 35 MWh at 8-GPU TDP and 21 versus 64 MWh at full-node maximum power, excluding data-center overhead and several pipeline costs.
More like this
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
See how Caddy handles a request for a static site, from DNS resolution through container routing to file_server, and how TLS and redirects fit into the flow.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.