How to Run an Agent Loop That Actually Converges
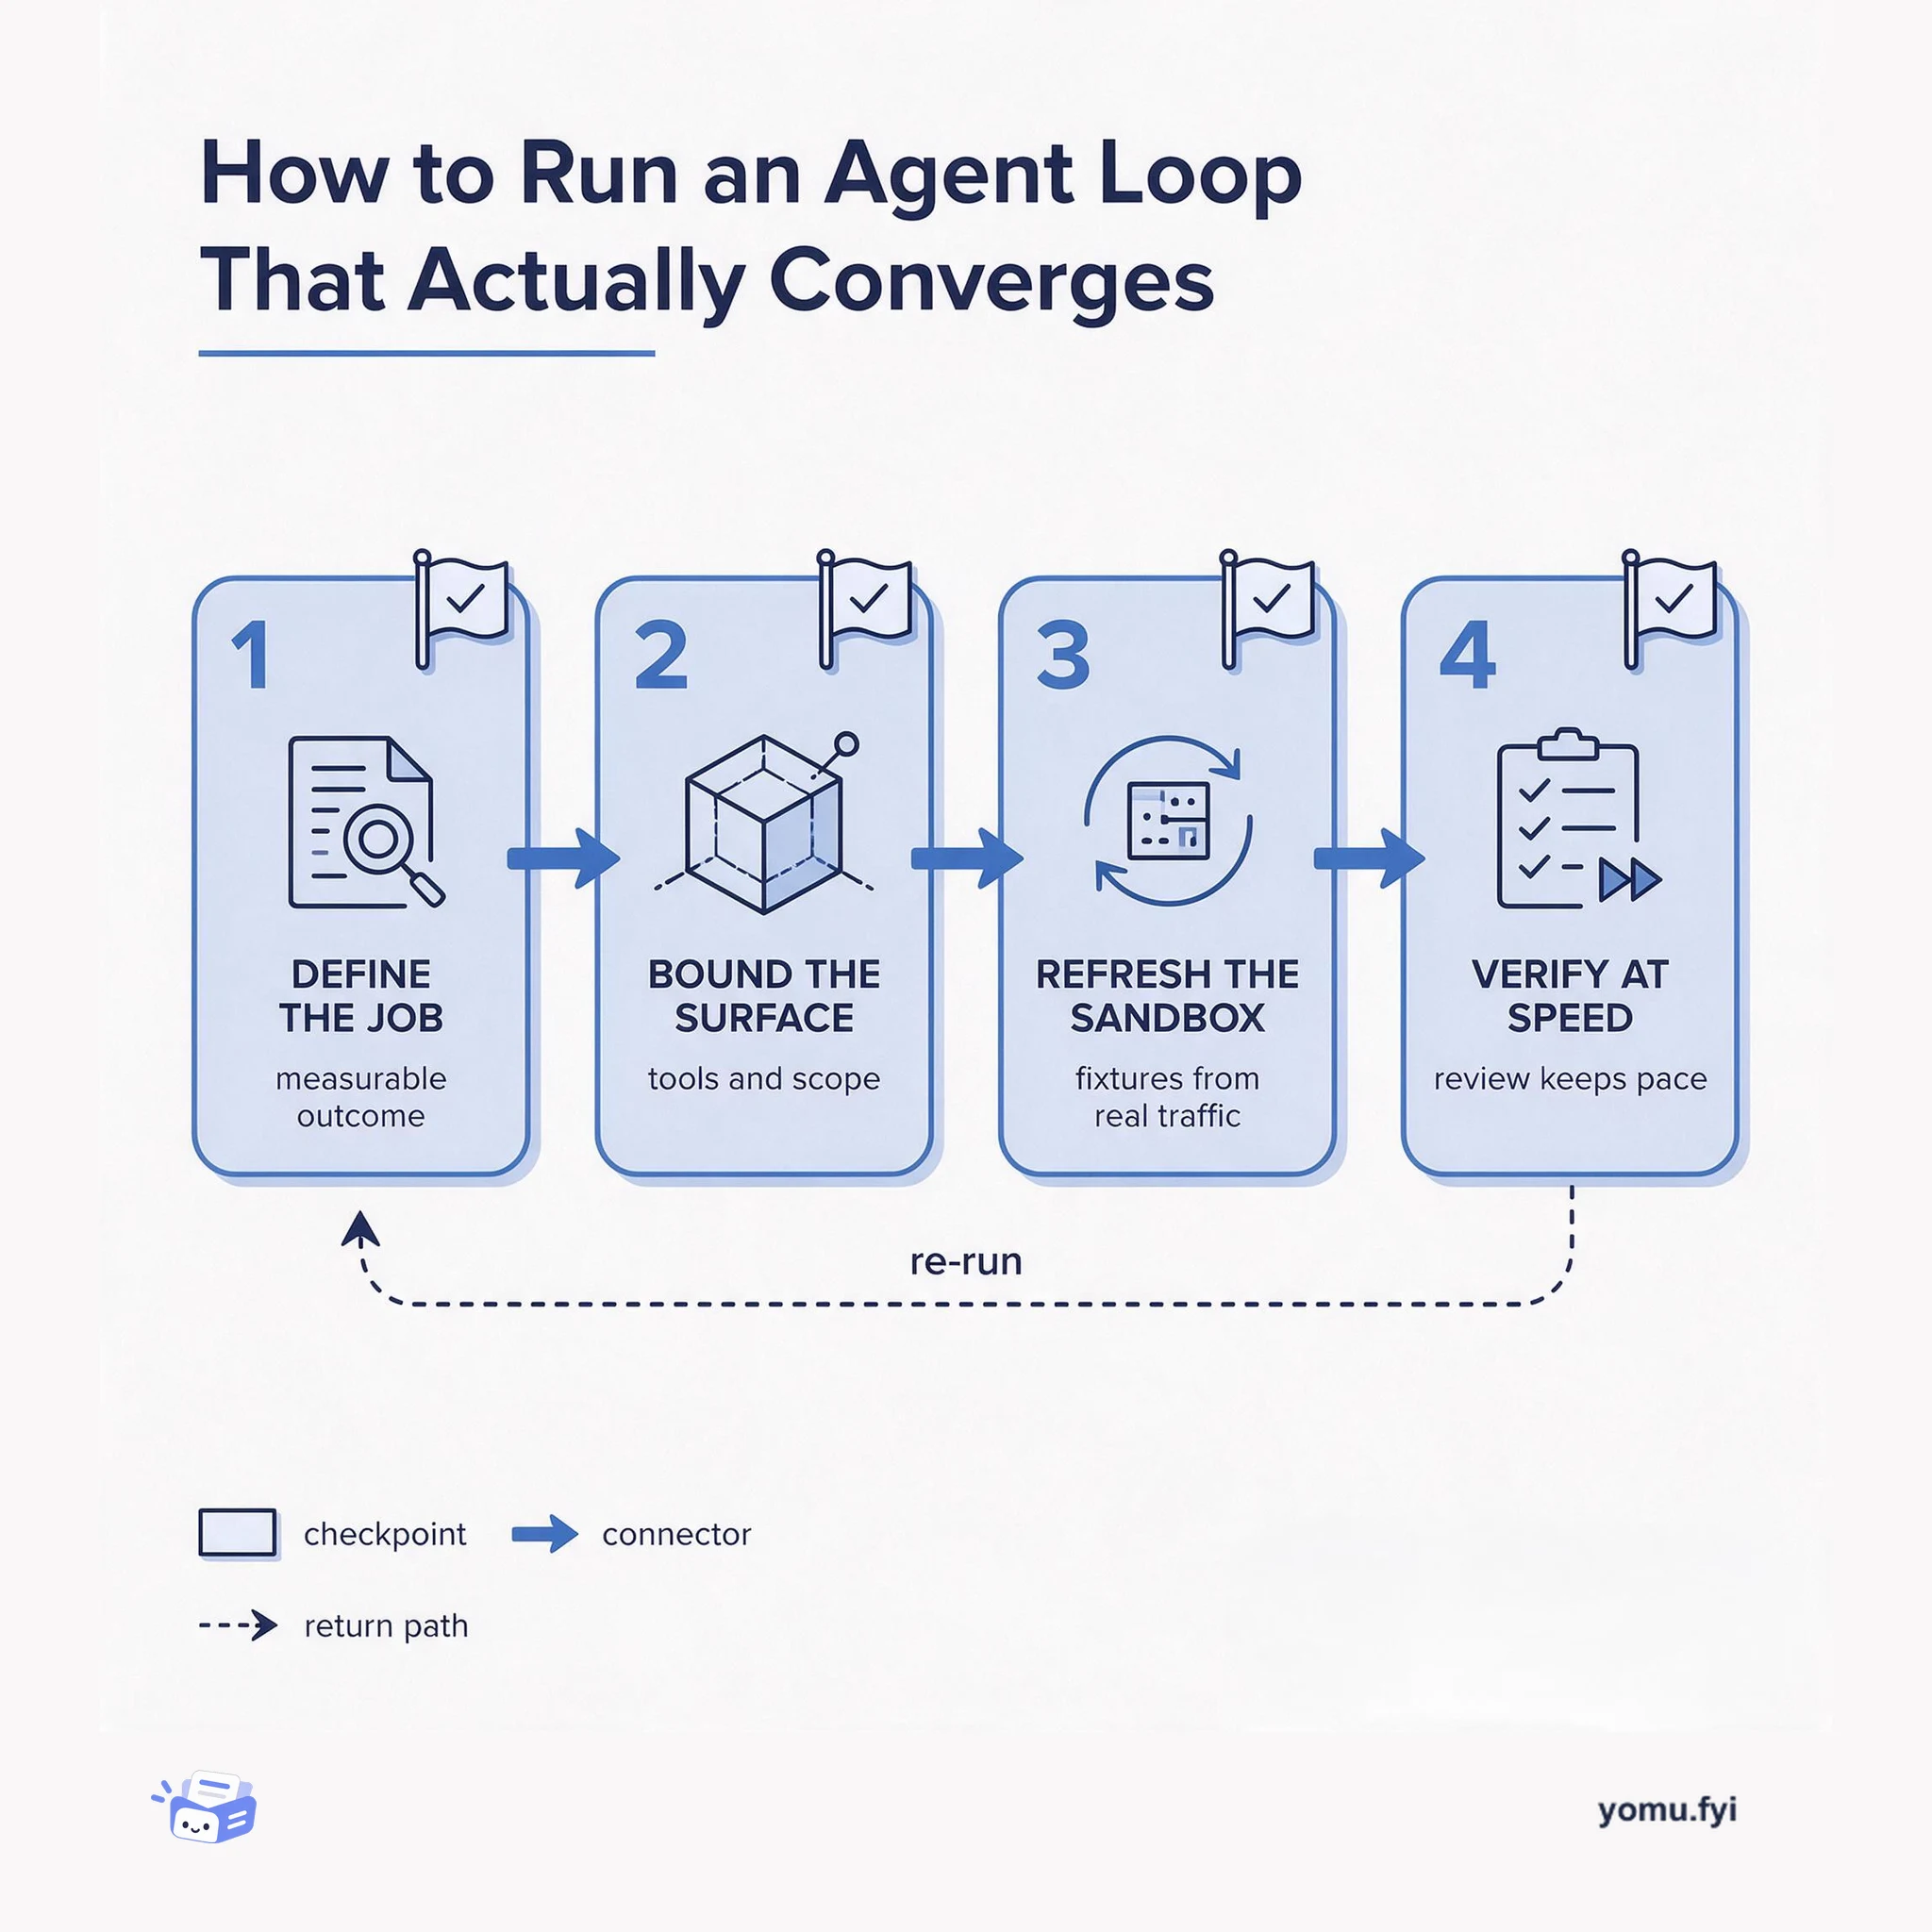
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
A practical Azure workflow for turning fragmented operational data into governed analytics and agent experiences, with checkpoints for layering, context, access, and deployment.
Building useful AI workflows on Azure starts with more than choosing a model. This guide shows a repeatable path: inventory fragmented sources, consolidate data into raw, refined, and curated layers, apply catalog-based governance, define trusted metrics and context, then expose the result through analytics or an agent interface. The checkpoints help engineers decide whether the data is ready for automation and where human review, identity controls, and monitoring still belong.
The supplied Azure examples use bronze, silver, and gold layers to separate ingestion, transformation, and reporting-ready data. Curating a gold layer and metric definitions gives analytics and agents a more stable, understandable context than querying fragmented source systems directly.
Use authenticated identity, role-aware access, catalog permissions, lineage, and quality checks before an agent can query enterprise data. The cellcentric and Scottish Water examples also emphasize governed semantic context, business rules, monitoring, and separate deployment environments.
Keep review for decisions that affect operations, safety, access, or other consequential state changes, especially when data spans multiple systems or still needs domain validation. The supplied examples show that automation can shorten investigation and reporting work without removing expert oversight from complex cases.
The posts behind it
 Databricks · · Problem & solution
Indra Renewable Technologies consolidated a fragmented EV-charging data estate spanning Cosmos DB, Synapse, Azure Data Lake Storage, Azure Functions, Power BI, and other services onto Databricks. The migration began with a parallel Synapse prototype and expanded to Delta tables, a consolidated fleet pipeline, and greater use of Databricks for operational workloads. A medallion architecture stores raw fleet data in bronze, transforms it with PySpark in silver, and publishes gold tables for reporting and client delivery; one pipeline now serves three clients and improved performance by 60% to 70%. Unity Catalog, serverless SQL warehouses, AI/BI dashboards, and Genie Agents support governed self-service analytics, while reported results include 80% to 90% business cost savings, 90% storage savings, and query latency falling from 24.4 seconds to 3.5 seconds.
Databricks · · Problem & solutionScottish Water’s Capital Investment teams had project data, reports, and metrics available, but non-technical users often struggled to find answers, creating duplicated reporting and delays. SPARK addresses this access problem through a natural-language interface in Microsoft Teams: Copilot routes questions via a supervisor agent and MCP to the Databricks Genie Agent, which queries governed Unity Catalog data. The implementation curates use-case data in a gold layer, adds metric views as a semantic layer, and configures business rules, examples, benchmarking, feedback, and monitoring for accuracy and performance. Environment-parameterised Databricks Asset Bundles, separate environments, Azure DevOps approvals, Entra ID, and Key Vault support repeatable deployment. The post reports lookup journeys shrinking from around eight clicks or four to five search steps to a direct question, with an estimated 520 to 1,300 hours saved annually under a stated usage scenario.
Databricks · · Explainercellcentric describes how it built a governed lakehouse foundation for R&D data so industrial AI agents can reason over engineering context, not isolated source-system records. On Azure and Databricks, the Data Hub combines Unity Catalog governance, Lakehouse Federation, Delta Sharing, Declarative Automation Bundles, and an MCP interface for agents. Its Fuel Cell Passport unifies five enterprise systems, models seven hierarchy levels, refreshes daily, and uses a state-based temporal model for point-in-time configuration and rework-history questions. The platform treats context coverage as a data-quality metric, with 27 published products averaging 90% column-comment coverage, while authenticated user identity and Unity Catalog authorization constrain agent access. For many R&D and process-development workflows, work that once took weeks now ships in days, though complex multi-source investigations still require substantial domain review.
Databricks · · Problem & solutionImperial College London’s Care Research and Technology Centre (CR&T) needed to scale Minder, a platform that combines in-home sensors, sleep monitors, and electronic health records to support dementia care and research. Growing data volumes caused competing workloads, tightly coupled storage and compute, and limited access for researchers and clinicians. The re-architected platform validates IoT data through Kubernetes, stores it in Delta Lake on Azure Data Lake Storage using bronze, silver, and anonymized gold layers, and adds Databricks analytics with Unity Catalog governance while retaining FHIR-based EHR interoperability and Kubeflow for model deployment. Research-to-production workflows, reusable pipelines, dashboards, and timestamped data improve collaboration, accessibility, and reproducibility. During migration, uptime remained 100%; new sources integrated in as little as one month, model development fell to about one month, and insights reached 581 people living with dementia in five months.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
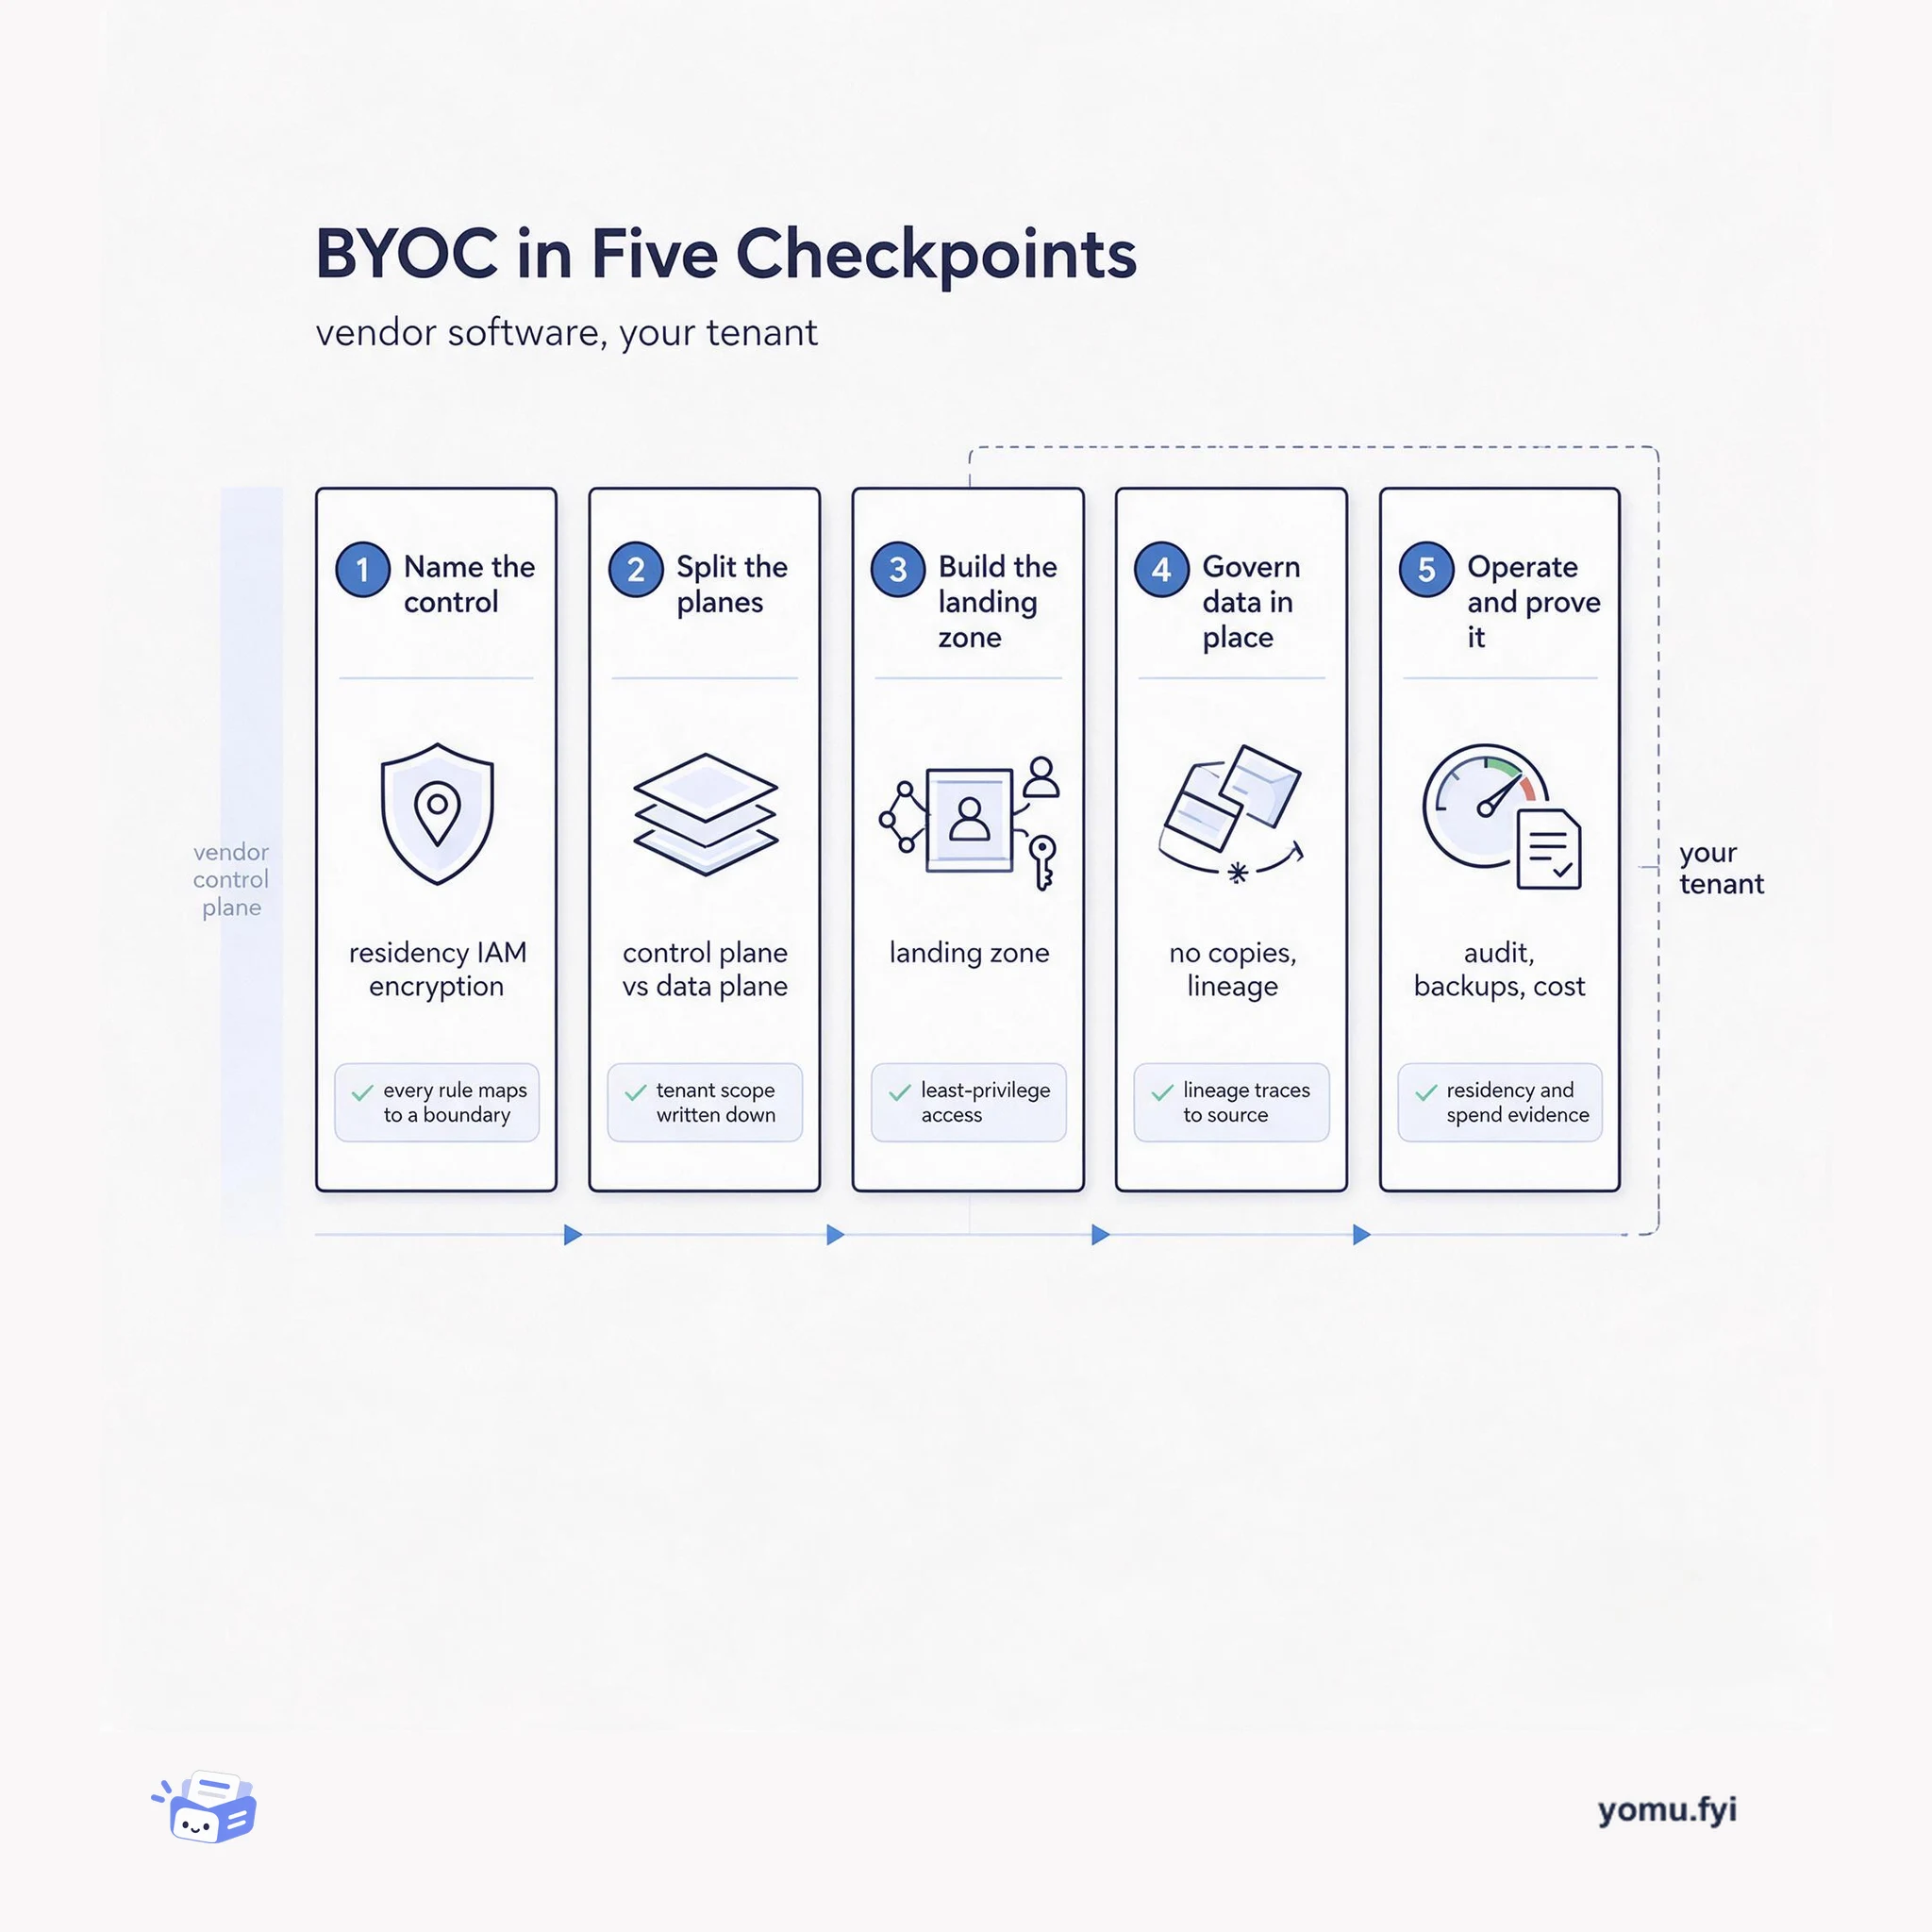
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.