What Is an AI Factory? Power In, Tokens Out
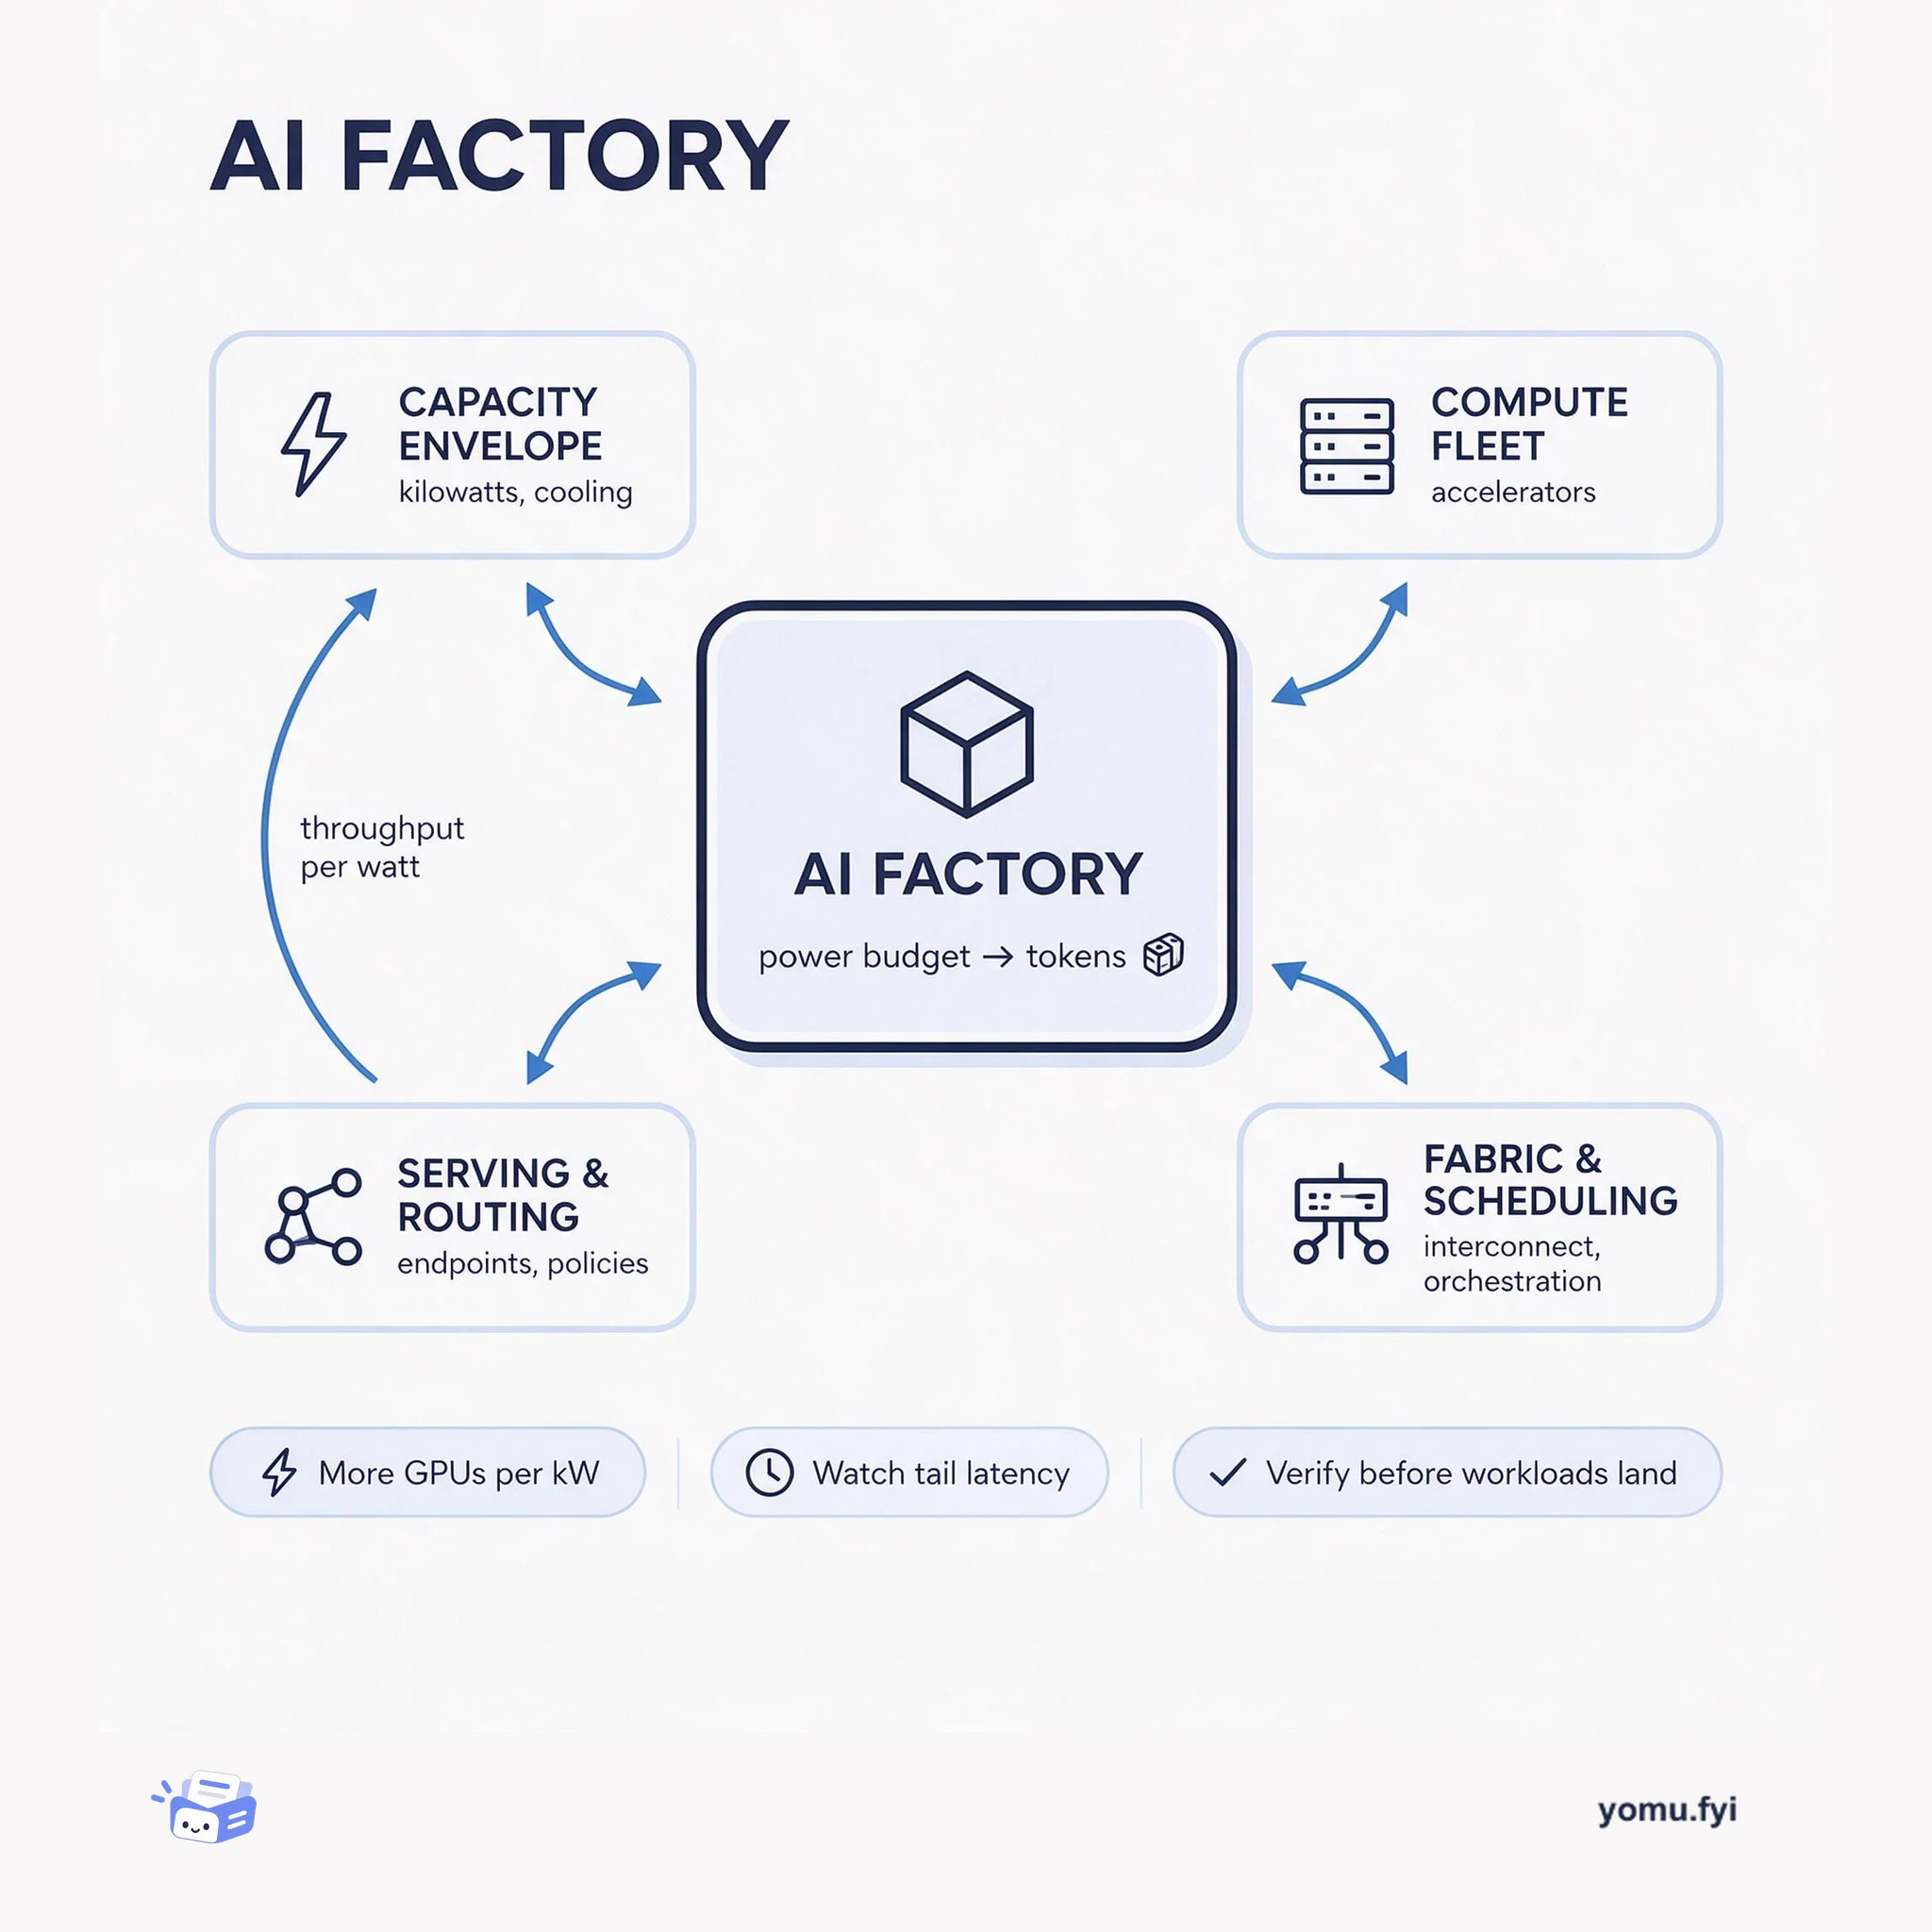
An AI factory is a fixed power and cooling budget converted into model output. This explainer maps its four parts and the throughput-per-watt trade-offs that connect them.
 NVIDIAMichelle HortonExplainer
GPU clusters can pass standard health checks yet fail under real AI training workloads due to a single degraded GPU, network link, or misrouted traffic. NVIDIA Cluster Readiness Engine (NVCRE) is an open source Kubernetes controller that runs real distributed workloads across topology-aware node groups before production jobs land, measuring results and reporting which nodes failed each test. Its layered API uses Custom Resource Definitions for Certification, Workflow, and Job resources, attributing each failure to a specific node and category such as NCCL bandwidth or training goodput. The WorkloadRun API handles platform detection, NCCL settings, shared-memory volumes, and gang scheduling, so operators do not need to write those manifests by hand. NVCRE integrates with NVSentinel for passive telemetry and is available under Apache 2.0, with a roadmap for inference and automated lifecycle validation.
NVIDIA Cluster Readiness Engine (NVCRE) is an open source Kubernetes controller that validates GPU cluster readiness by running real distributed workloads across topology-aware node groups before production jobs land. It provides a layered API with Certification, Workflow, and Job custom resources, and a WorkloadRun API that handles platform detection, NCCL settings, shared-memory volumes, and gang scheduling. NVCRE measures results and reports which nodes failed each test by category, with pass/fail criteria defined in Common Expression Language. It integrates with NVSentinel for passive monitoring and automated remediation workflows.
NVCRE runs real distributed workloads across topology-aware node groups, measuring results and reporting which nodes failed each test, eliminating manual bisection of GPU clusters.
The API hierarchy consists of Certification, Workflow, and Job custom resources, attributing failures to specific nodes and categories such as NCCL bandwidth or training goodput.
NVCRE integrates with NVSentinel to translate certification results into health events, enabling automated quarantine and drain workflows while allowing corrective actions to clear the failure signal.
NVCRE uses adaptive fault isolation with topology-aware hierarchical group testing. It splits failing groups, reruns halves, and continues until reaching minGroupSize, then flags suspect nodes with reasons for failure.
The built-in catalog covers five NCCL communication variants, the DCGM level-4 diagnostic suite, and NVIDIA NeMo pretraining with Nemotron 5 models at 8B and 56B parameters.
Pass and fail criteria use Common Expression Language expressions evaluated against measured metrics. No thresholds ship by default; users define values such as busBandwidthGBps >= 900 for communication tests.
Summaries are generated from the original by a language model. Check the original before relying on it.
See the idea
An AI factory is a fixed power and cooling budget converted into model output. This explainer maps its four parts and the throughput-per-watt trade-offs that connect them.
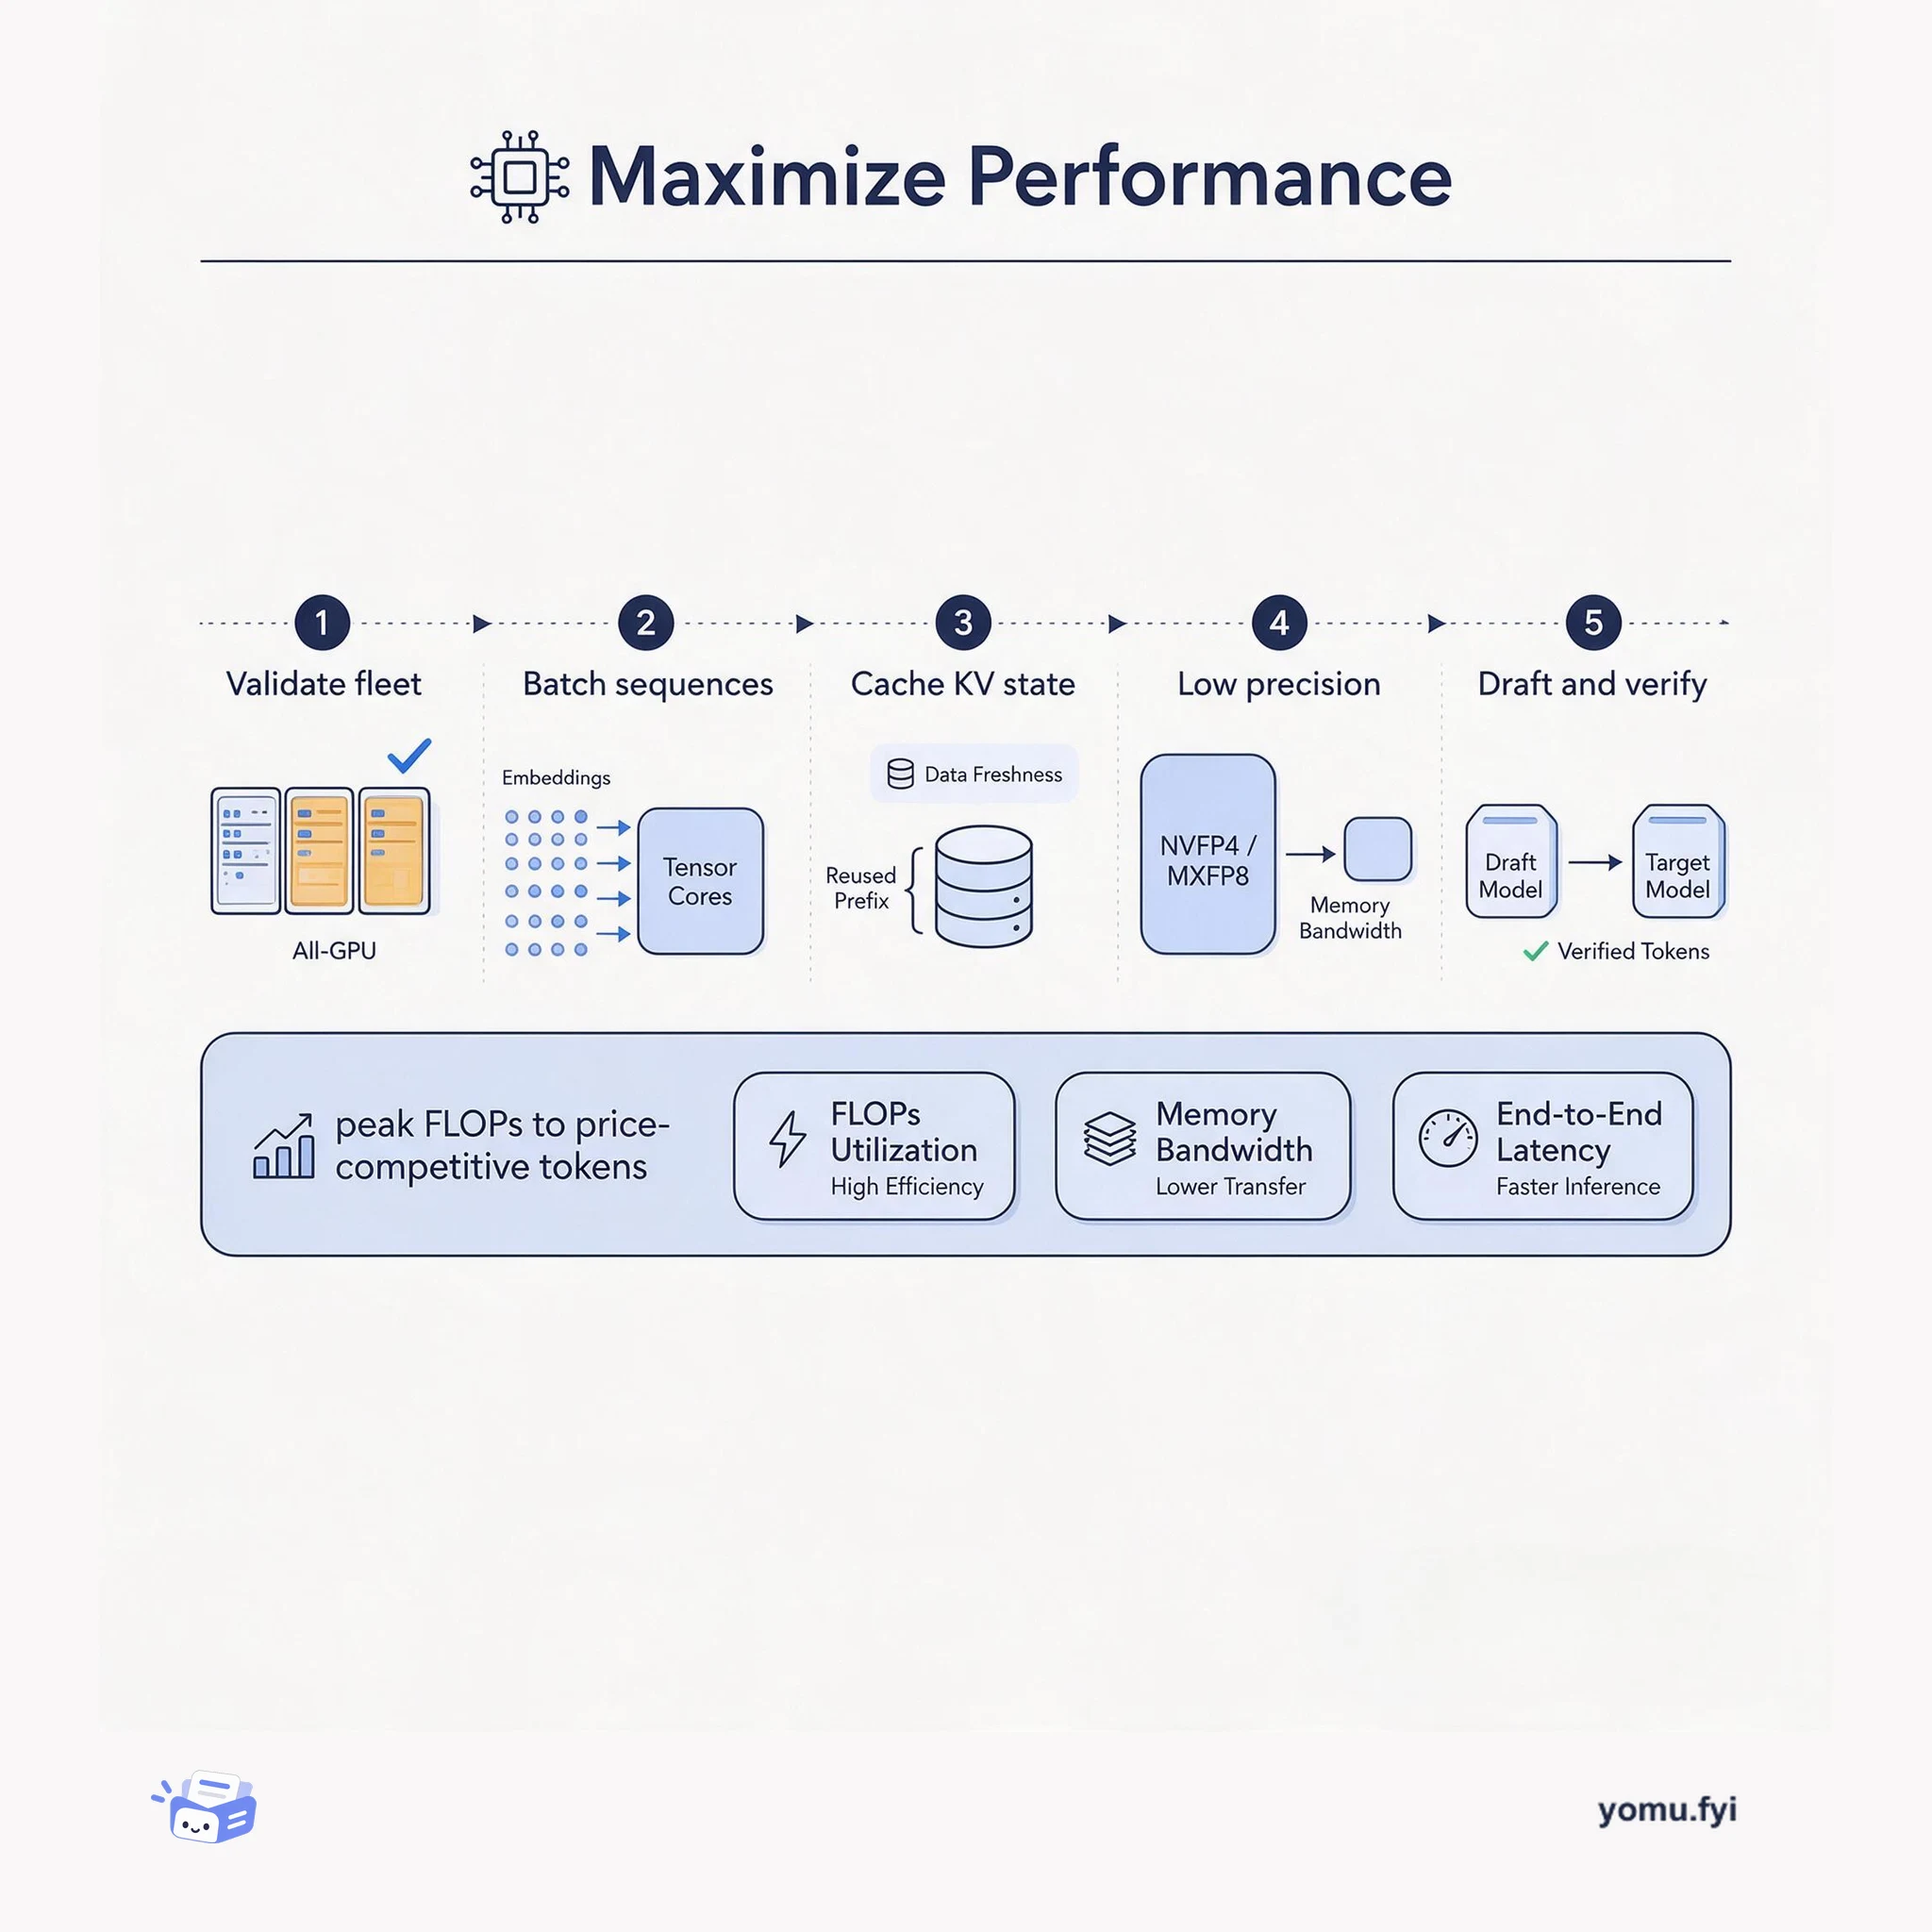
Blackwell inference is a pipeline, not a chip upgrade. This explainer walks five stages — fleet validation, batching, KV caching, low-precision kernels, and speculative decoding — that turn peak FLOPs into cheap tokens.
Argo CD is a GitOps controller that treats Git as the desired state and continuously reconciles it against what actually runs in each cluster. It maps the parts of that loop and why pull-based agents change its scale.
Keep reading
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.