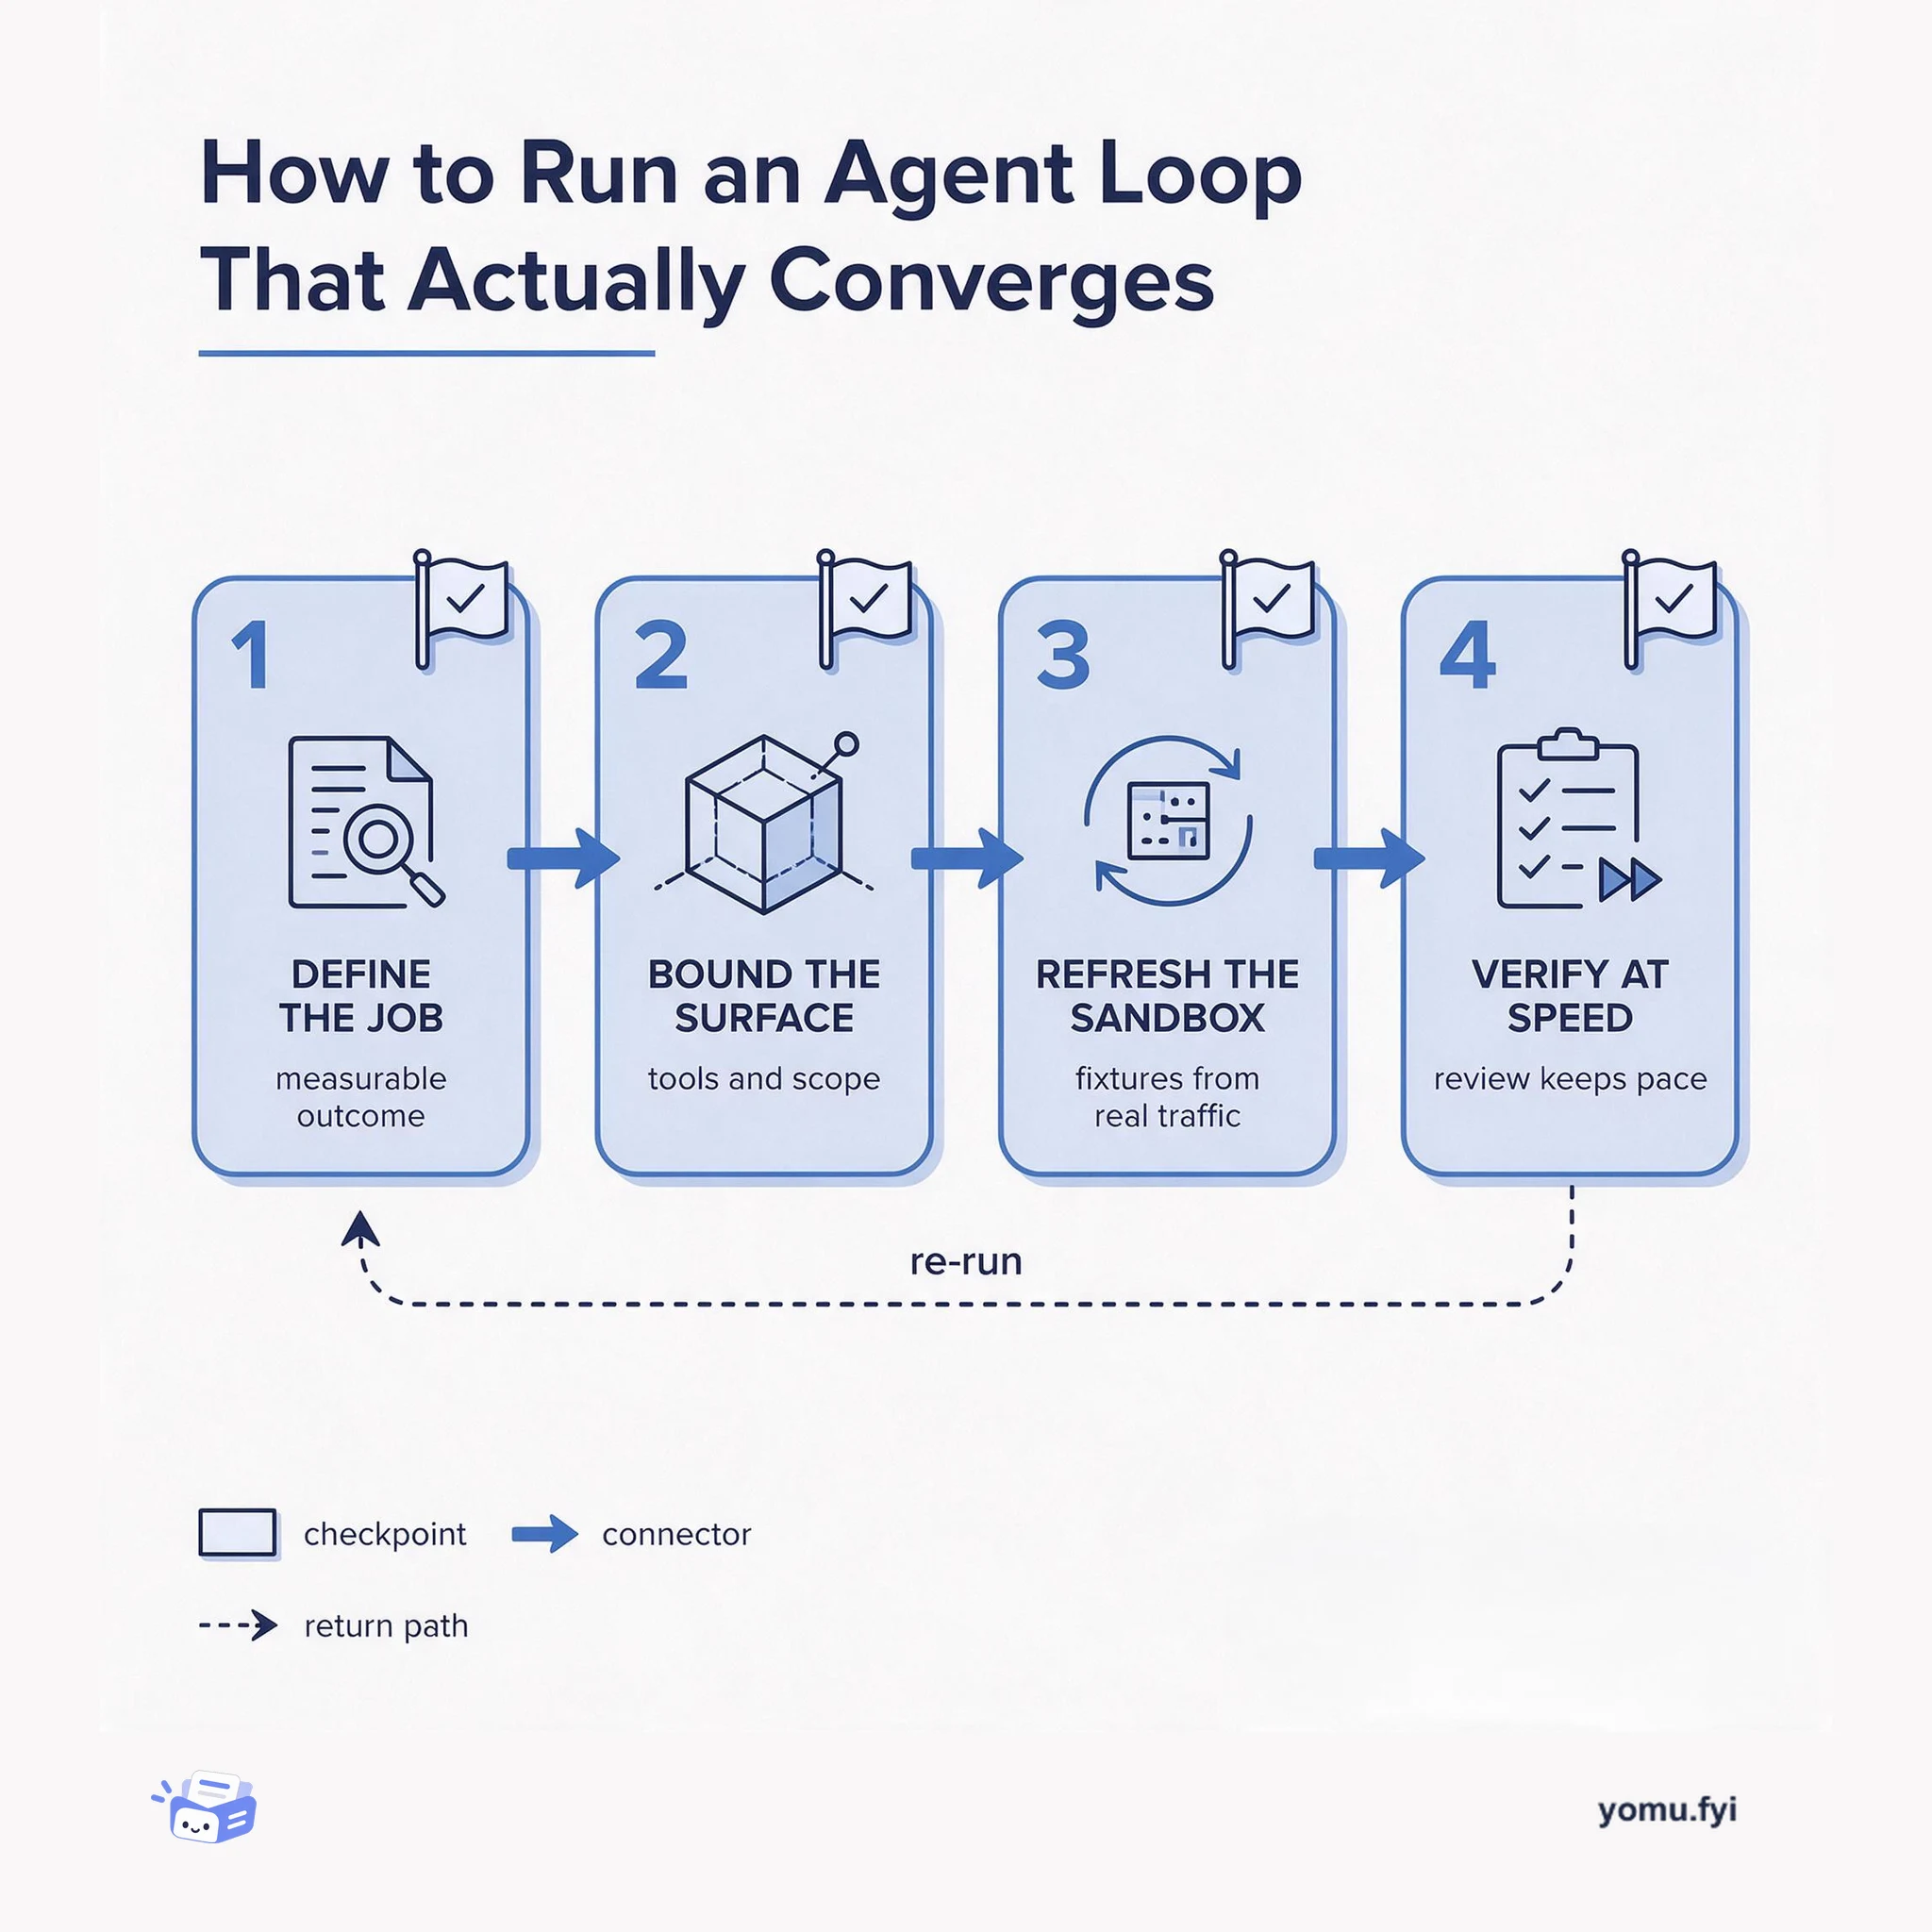
How to Run an Agent Loop That Actually Converges
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
A practical how-to for using NVIDIA DOCA Agent Skills to generate BlueField code with verified APIs and hardware checks, reducing correction cycles and failed builds.
NVIDIA DOCA Agent Skills provide a machine-readable SKILL.md file with verified API signatures, hardware capability requirements, and build constraints for BlueField components like Flow, GPUNetIO, and PCC. This how-to walks through a checkpoint workflow: detect the target hardware, load the relevant skill, generate code against those constraints, then validate on real BlueField infrastructure instead of trusting a clean agent response. In a 65-prompt evaluation, agents without skills satisfied only 19% of graded checklist items, while agents with skills reached 100%; a side-by-side demo used 73% less handwritten code and 46% fewer hardware commands.
General-purpose agents often invent APIs or skip hardware checks. DOCA Agent Skills provide a machine-readable SKILL.md with verified API signatures, hardware requirements, and build constraints for components like Flow, GPUNetIO, and PCC. In a 65-prompt evaluation, agents without skills satisfied only 19% of graded checklist items, while those with skills satisfied 100%.
Yes. In a side-by-side demo, the agent with skills used 73% less handwritten code and 46% fewer hardware commands, and it satisfied 100% of graded checklist items versus 19% without skills. The skills reduce correction cycles by giving agents verified APIs and constraints up front, so they spend less time guessing and more time building stable code.
The posts behind it
 Hugging Face · · Benchmark
ThinkingBox, a benchmark from Microsoft and Hugging Face, grades AI agents on the database state and side effects they leave behind rather than on tool calls or final responses. In a common-set ablation covering 121,680 valid trials across 12 LLM models, 79,853 attempts failed executable checks, and 67.24% of those failures still terminated cleanly and invoked a state-changing tool without error, with wrong field values in 77.61% of them. The benchmark runs every task 20 independent times from identical clean backends, reporting pass@1, pass@20, and observed 20/20 consistency to separate capability from reliability. For example, Kimi-K3 solved 93.89% of tasks at least once but only 13.41% consistently, while Claude Opus 5 completed 47.53% of tasks on every attempt, and Claude Opus 5.5 gained no additional dependability over its predecessor despite higher pass@1. ThinkingBox is available through Hugging Face’s OpenEnv with MIT-licensed code and CDLA-Permissive-2.0 benchmark data.
 Supabase · · Announcement
At Supabase Select, Supabase announced tools that let coding agents find production problems, test fixes, and report back, with controls for access and permission. A new MCP tool gives agents raw SQL access to project logs, advisor checks now include health signals for error rates across Data API, Auth, Storage, and Edge Functions, and the database connections view shows sessions, long queries, idle-in-transaction, blocked, and lock holders. Notebooks combine saved database or log queries with markdown notes, can be created in the dashboard via the Assistant, pulled locally with supabase notebooks pull, and pushed with supabase notebooks push, and are found in the new Explorer rolling out through October 12. Updated Skills provide a living document of common health, security, performance, and resource signals for agents to watch for and how to monitor them. Supabase Pipelines, available on paid plans, allow replicating data to BigQuery, ClickHouse, DuckLake, or Snowflake.
Supabase · · AnnouncementSupabase announced tools at Supabase Select that let coding agents manage backend configuration and deployment from code, eliminating the need for dashboard-only changes. Declarative Schemas 2.0 allows agents to edit SQL files as the source of truth, with pg-delta generating migrations, while config.toml holds settings like auth providers that can be pulled back from the dashboard. Local development now runs as native processes without Docker, supporting multiple instances per directory and working in environments like Claude Code’s sandbox, currently in alpha off by default. Supabase Compute provides long-running services in any language alongside the database, with configurable memory and CPU, public or private HTTP endpoints, and deployment via CLI or Management API. The new MCP server lets user agents interact with an app as the signed-in user, respecting existing RLS policies, built on @supabase/server and Supabase Middleware, with a headless app template available.
 Red Hat · · Benchmark
Enterprise generative AI applications require guardrails that balance flexibility with reliability. Decision models such as TypeSafe AI’s Jev produce fixed decisions with guaranteed schema and type safety, operating faster and cheaper than LLM-as-a-judge approaches. The Red Hat AI Safety team benchmarked nine guardrails across four methodologies for prompt injection and content safety tasks: pre-trained CPU-scale classifiers like Red Hat’s DeBERTa-v3 and Granite Guardian HAP-125m, older zero-shot models like BART-large-mnli, modern LLM-as-a-judge safety models including Shieldstral and Nemotron-3.5, and Jev-style decision models including Laya and DiffusionGemma. Each guardrail was evaluated using stock and custom risk policies, with Jev and DiffusionGemma using zero-shot questions. The results highlight trade-offs: Jev provides zero-shot flexibility and low latency, but purpose-built classifiers often match its speed and cost while delivering superior task-specific performance, and LLM-as-a-judge models can be tuned for higher accuracy.
Hugging Face · · Problem & solutionAutoSynthData, built by ServiceNow CoreAI, generates training data for enterprise agents by targeting capability gaps from evaluation, using a stronger teacher such as Qwen3.8-27B to demonstrate successes. It uses a target model’s failures and a stronger teacher’s successes to decide what to learn next. The system produces tasks composing a system specification, user prompt, and verifier, ensuring feasibility, realism, and difficulty against the target environment. After sample-level checks and batch-level review, the dataset grows via target and multiply phases, generating 2,000 samples in 18 hours for the Hybrid domain. In EnterpriseOps Gym, synthetic SFT on Gemma-4-26B-A4B-it improved mean Pass@1 by 7.2 points (35% relative) in Hybrid and from 18.77% to 27.18% in ITSM, showing the approach works across domains.
 NVIDIA · · Problem & solution
General-purpose AI agents lack domain-specific knowledge for NVIDIA DOCA development, often inventing APIs or skipping hardware checks, leading to correction cycles. DOCA AI agent skills provide a structured, machine-readable specification in a SKILL.md file containing verified API signatures, hardware capability requirements, and build constraints for components like Flow, GPUNetIO, and PCC. In a 65-prompt evaluation, agents without skills satisfied only 19% of graded checklist items, while agents with skills satisfied 100% across all prompts. The skills reduce correction cycles; in a side-by-side demo, the with-skills agent used 73% less handwritten code and 46% fewer hardware commands. The skills are available on GitHub and enable developers to build faster, ship more stable code, and deploy with fewer unknowns on BlueField infrastructure.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
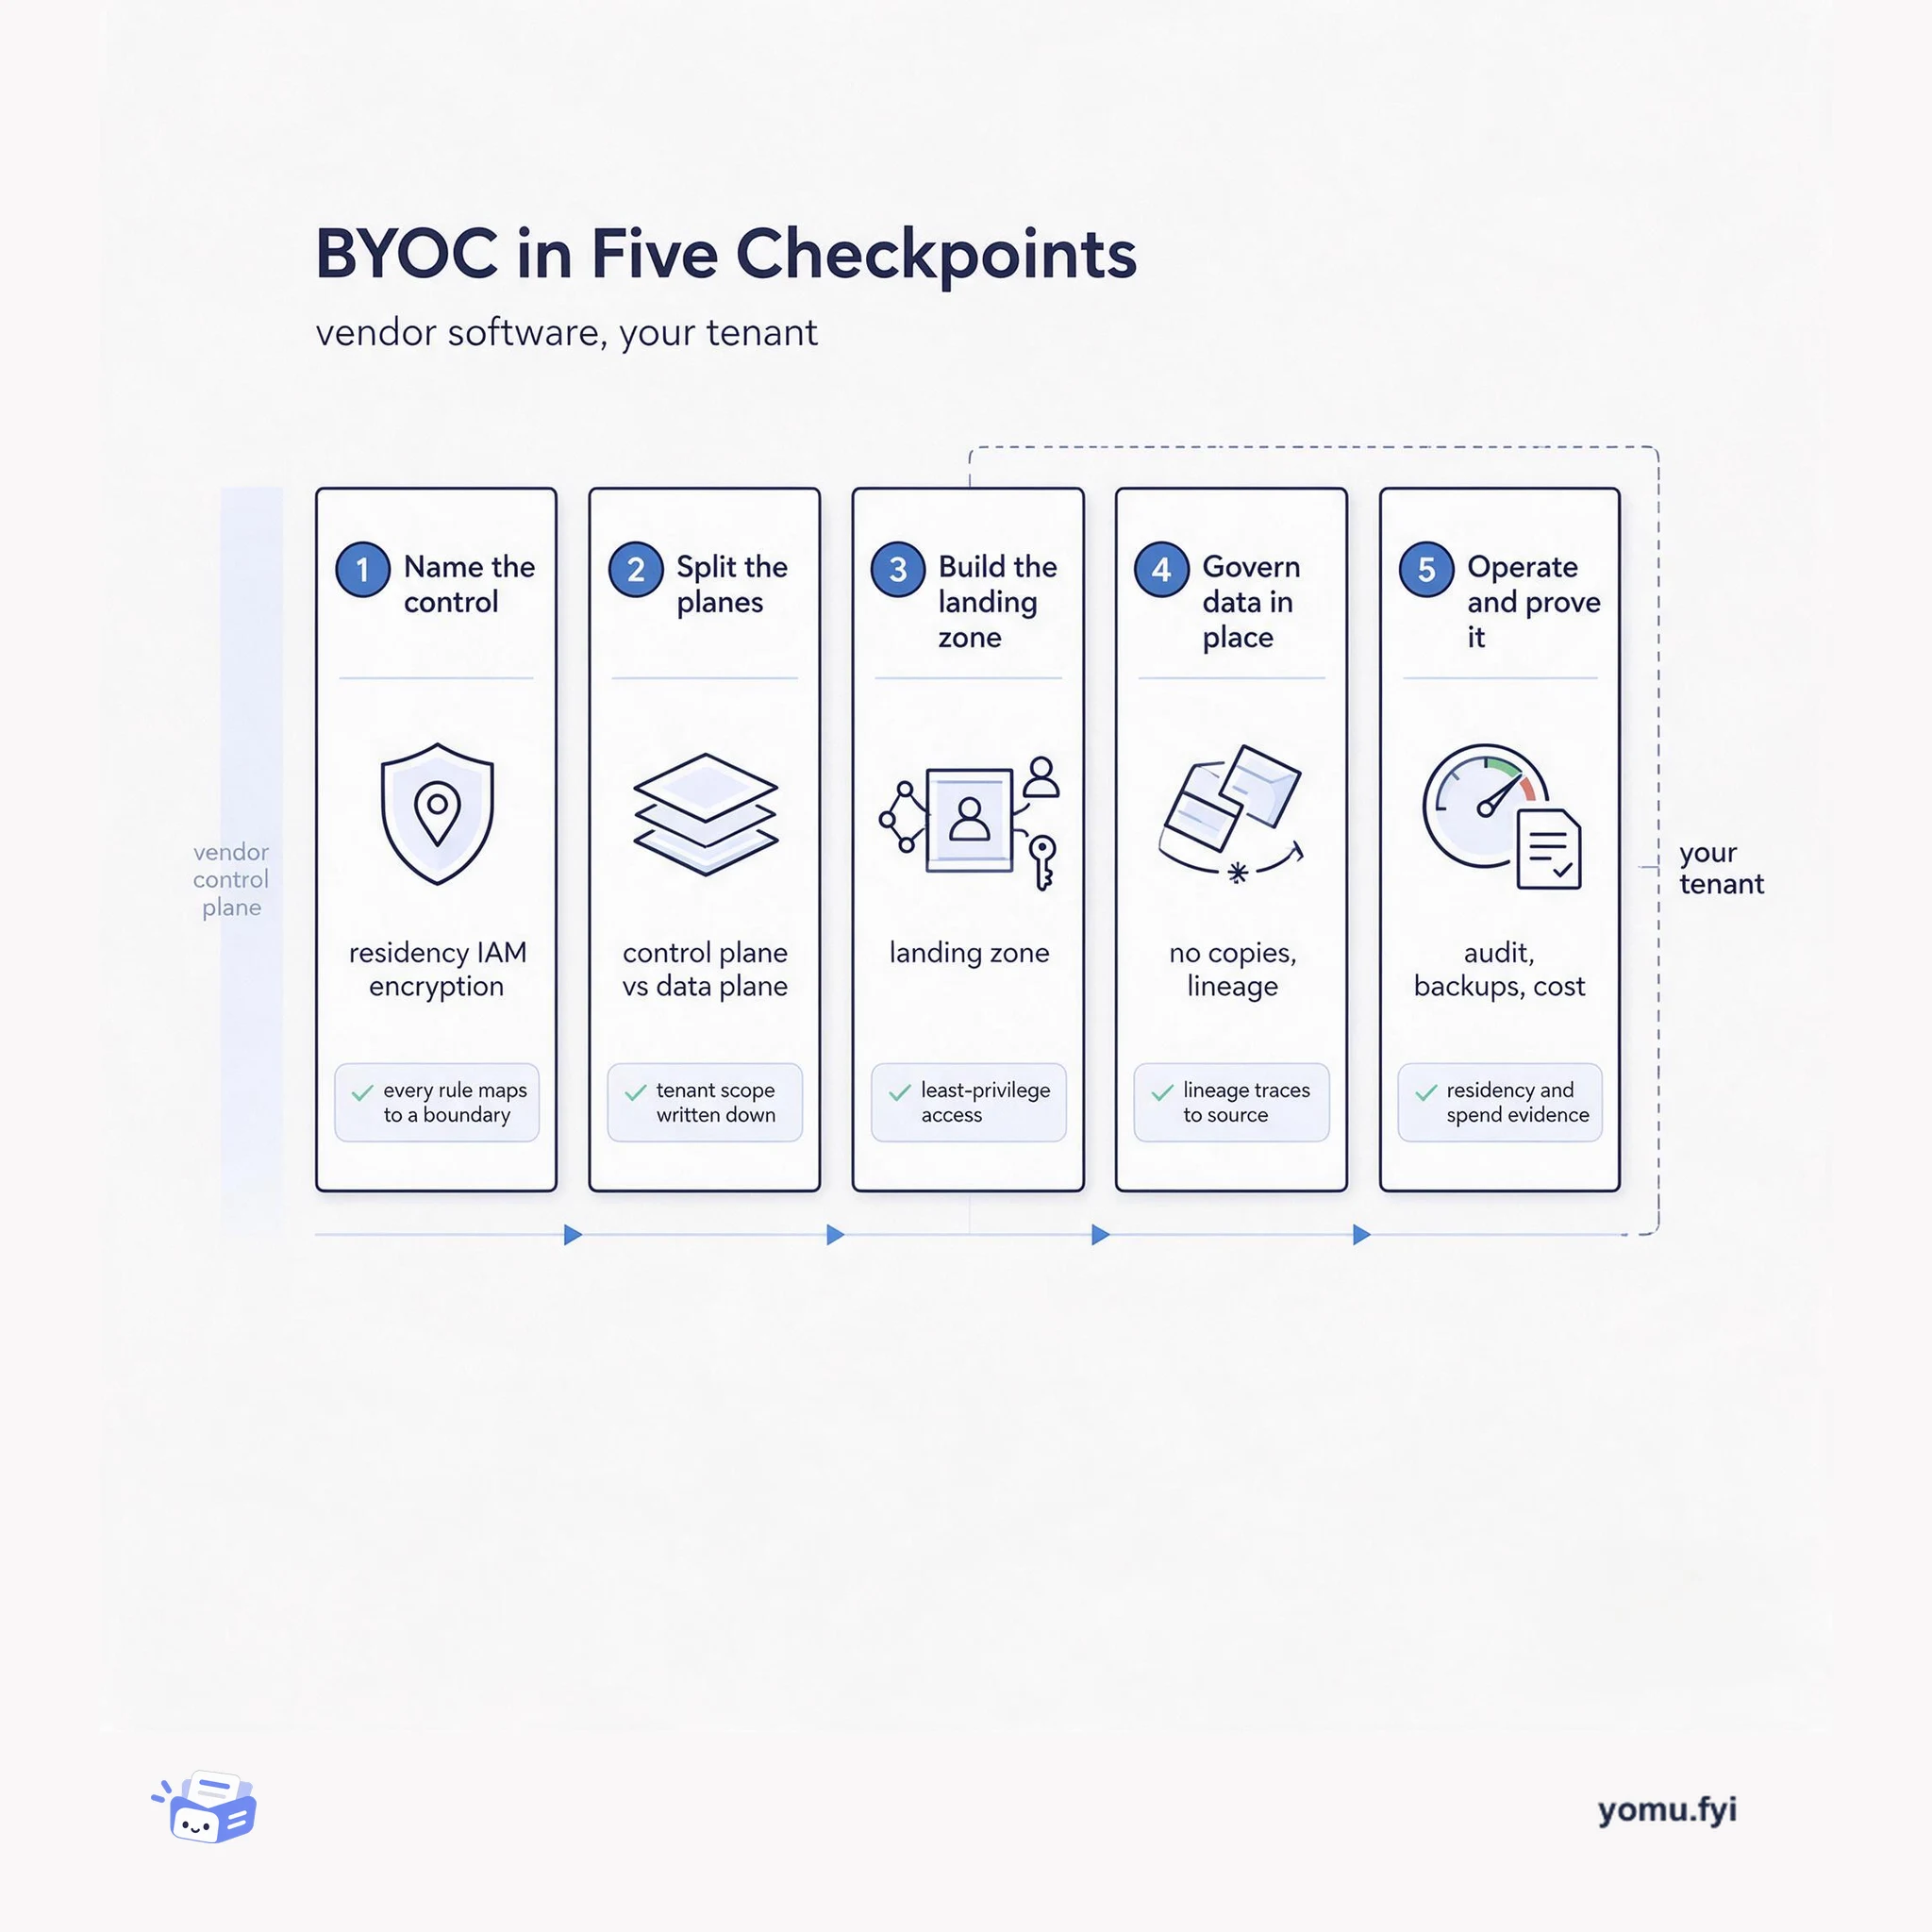
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.