How Apache DataFusion Runs SQL In-Process
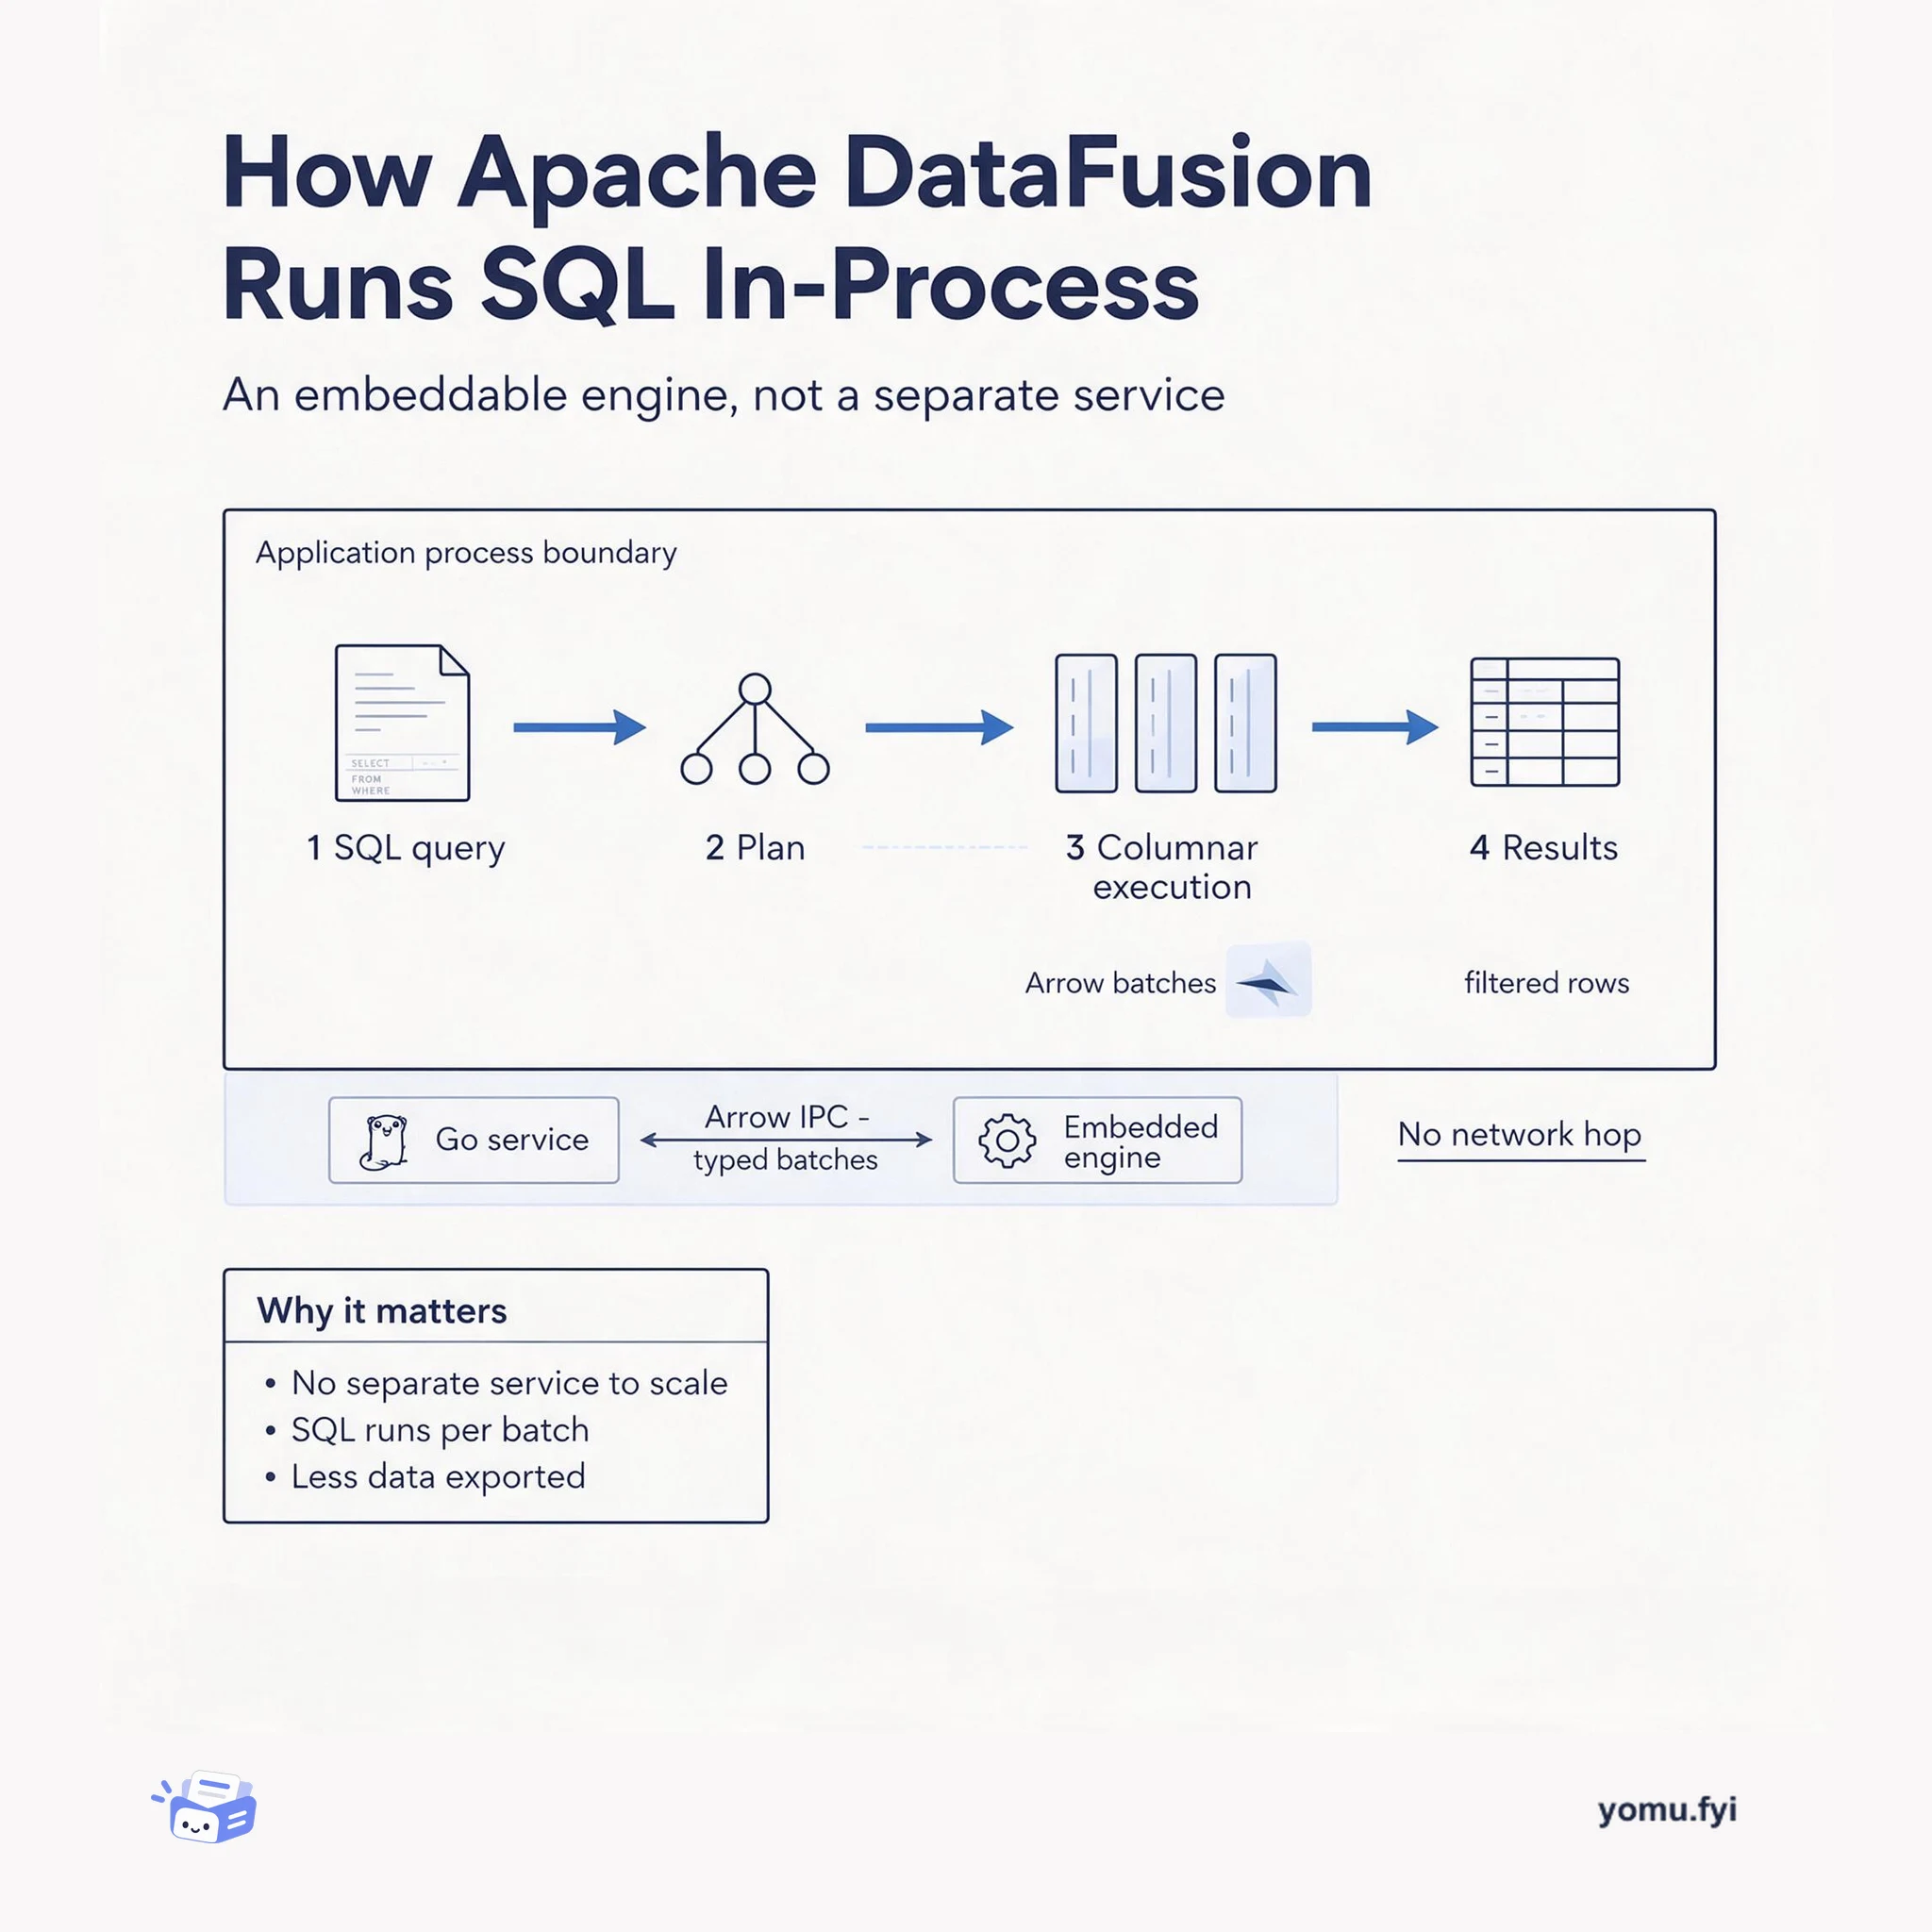
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
AML systems detect financial crime by unifying fragmented data sources, applying machine-learning models, and routing suspicious activity through analyst review—turning raw transactions into actionable cases.
Anti-Money Laundering (AML) detection begins with transaction data, customer information, and sanctions lists collected from multiple systems. These sources are unified into a governed data lake, where institution-specific machine-learning models score transactions for risk. High-confidence alerts route directly to case management; borderline cases queue for human analyst review. Analysts investigate evidence, document findings, and prepare Suspicious Activity Reports (SARs). Modern AML platforms reduce false positives through better data quality, model tuning, and integrated case history, freeing analysts to focus on genuine financial-crime intelligence rather than backlog triage.
The posts behind it
 Databricks · · Explainer
Marketing teams often have data across campaign, customer, attribution, and pipeline systems but still depend on analysts to answer questions quickly and consistently. Databricks Genie One is presented as a data-smart AI coworker that uses governed business data, organizational context, metric definitions, campaign structures, reporting rules, and access permissions to support marketing analysis. The five described uses cover channel and campaign performance, funnel attribution, customer insights, omnichannel planning, and mobile business reporting, with natural-language follow-ups, reusable skills or Genie Agents, scheduled analyses, dashboards, and shareable outputs. Examples include tracing sourced pipeline changes, identifying declining enterprise-account usage, and finding territories with weakening repeat purchases. The source recommends starting with repeatable, cross-source workflows and preparing data sources, attribution models, fiscal-calendar logic, and team terminology in Databricks; marketers retain responsibility for decisions and campaign plans.
Databricks · · ExplainerThe post argues that healthcare AI governance must extend beyond security controls to include knowledge, context, and ontology: security governs access, while semantics determine what data means and whether models can trust it. DEP frames classification tags, model cards, data contracts, and lineage as machine-readable governance artifacts, with Unity Catalog serving as the metadata runtime for agents. Build agents can generate ETL, testing, de-identification, and deployment, while analytic agents answer questions over individual data products; human stewards approve proposals and own accountability. A shared lifecycle certifies the data product and AI track through gates using scores for governance, quality, semantics, and ownership, with certification expiring after relevant changes or failures. The approach applies data-layer ABAC to SQL and vector retrieval, logs agent prompts with lineage, and connects readiness metrics to model economics by enabling smaller models when cataloged data supplies sufficient context.
Databricks · · ExplainerEnterprise data products are presented as managed assets that deliver the right data at the right time, with appropriate quality, format, and usability for users and applications. Their value depends on clear ownership, business-aware data product owners, and five trustworthiness characteristics: quality and observability, semantic consistency, privacy, security, and discoverability. The proposed lifecycle runs from inception and design through creation, publication, operation and governance, consumption, and retirement, with data contracts, quality metrics, testing, versioning, access management, and lineage supporting those stages. For Databricks implementations, the guidance recommends Delta Live Tables expectations and constraints, staged development, testing and production environments, automated monitoring, and Unity Catalog for discovery, governance, lineage, auditing, and access controls.
Databricks · · Problem & solutionAML operations are strained by fragmented systems, high false-positive volumes, manual case documentation, and opaque vendor scoring, leaving analysts focused on backlog rather than financial-crime intelligence. The proposed Databricks Data + AI Platform unifies transaction monitoring, KYC, sanctions, case history, and policy data under Unity Catalog, using Lakeflow Connect and a Bronze–Silver–Gold Delta architecture with masking, row-level security, and lineage. MLflow, Model Serving, Lakehouse Monitoring, and inference tables support institution-specific detection models, while Agent Bricks coordinates agents for evidence gathering, recommendations, and SAR drafting with analysts retaining final decisions. The architecture also uses Lakebase for governed operational state and Databricks Apps for analyst and executive experiences. Reported outcomes include a 75% reduction in false positives reaching the analyst queue and compressing three-to-six-hour investigations to minutes.
More like this
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
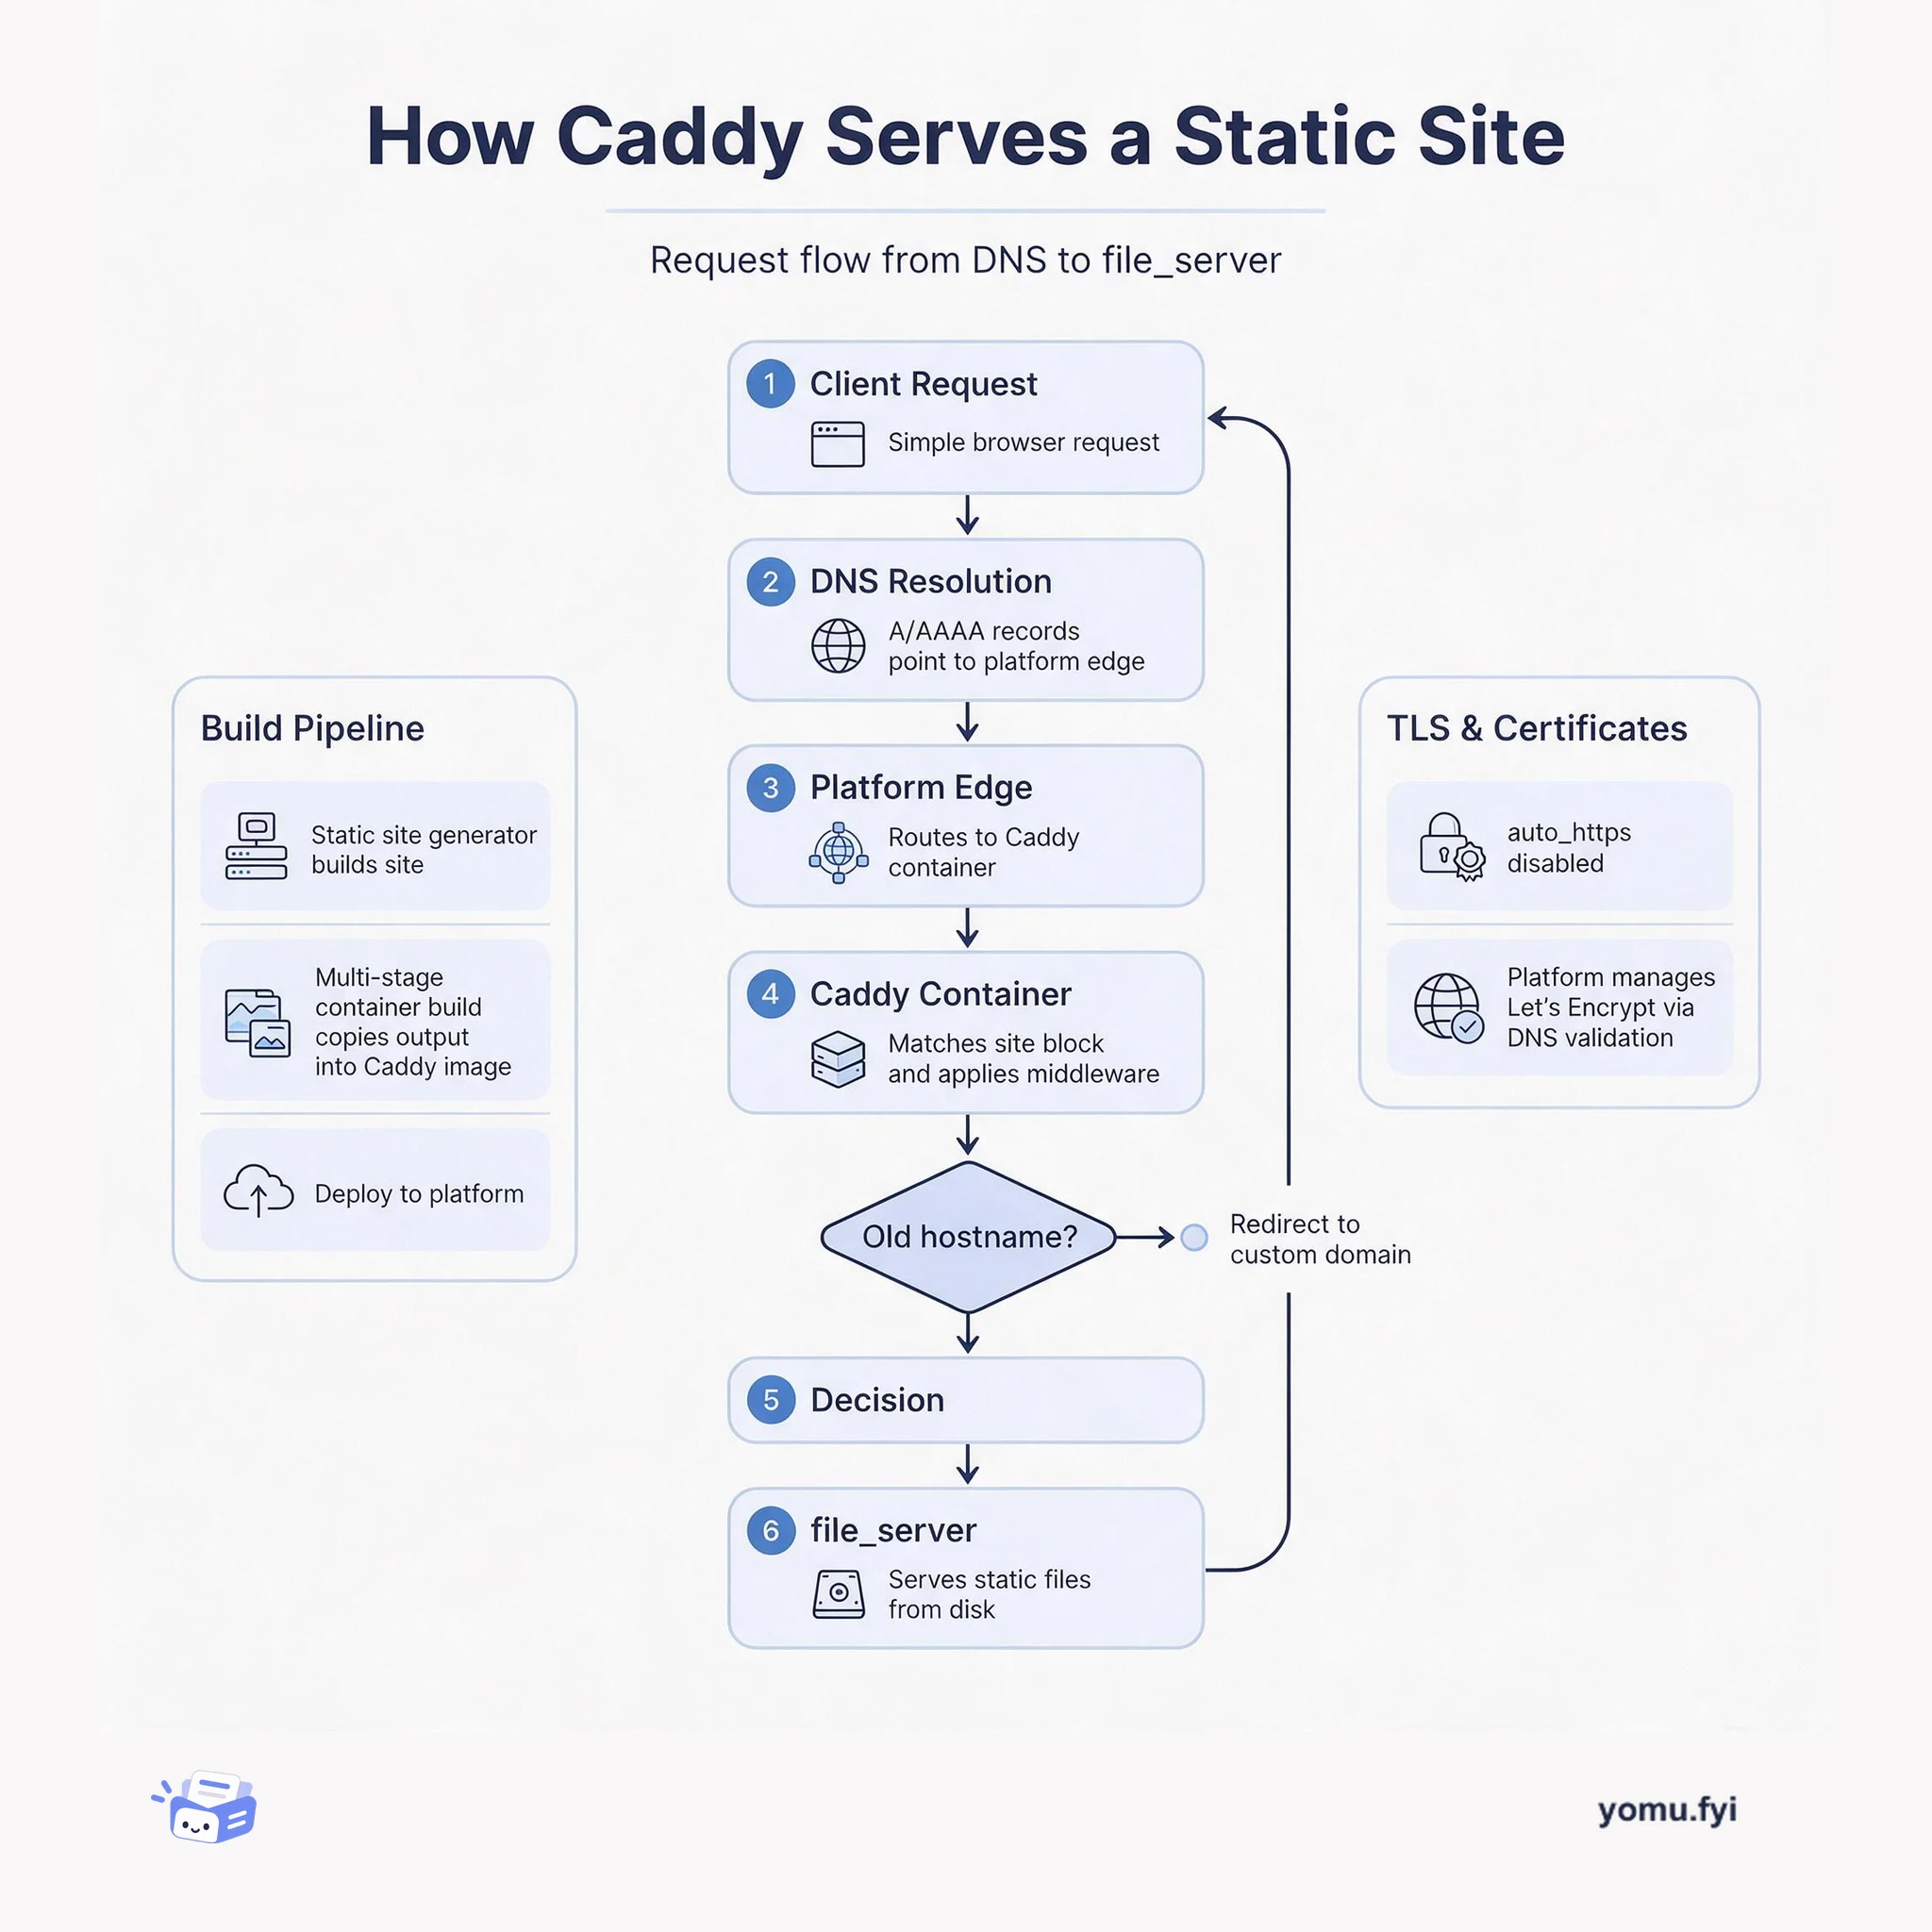
See how Caddy handles a request for a static site, from DNS resolution through container routing to file_server, and how TLS and redirects fit into the flow.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.