How to Run an Agent Loop That Actually Converges
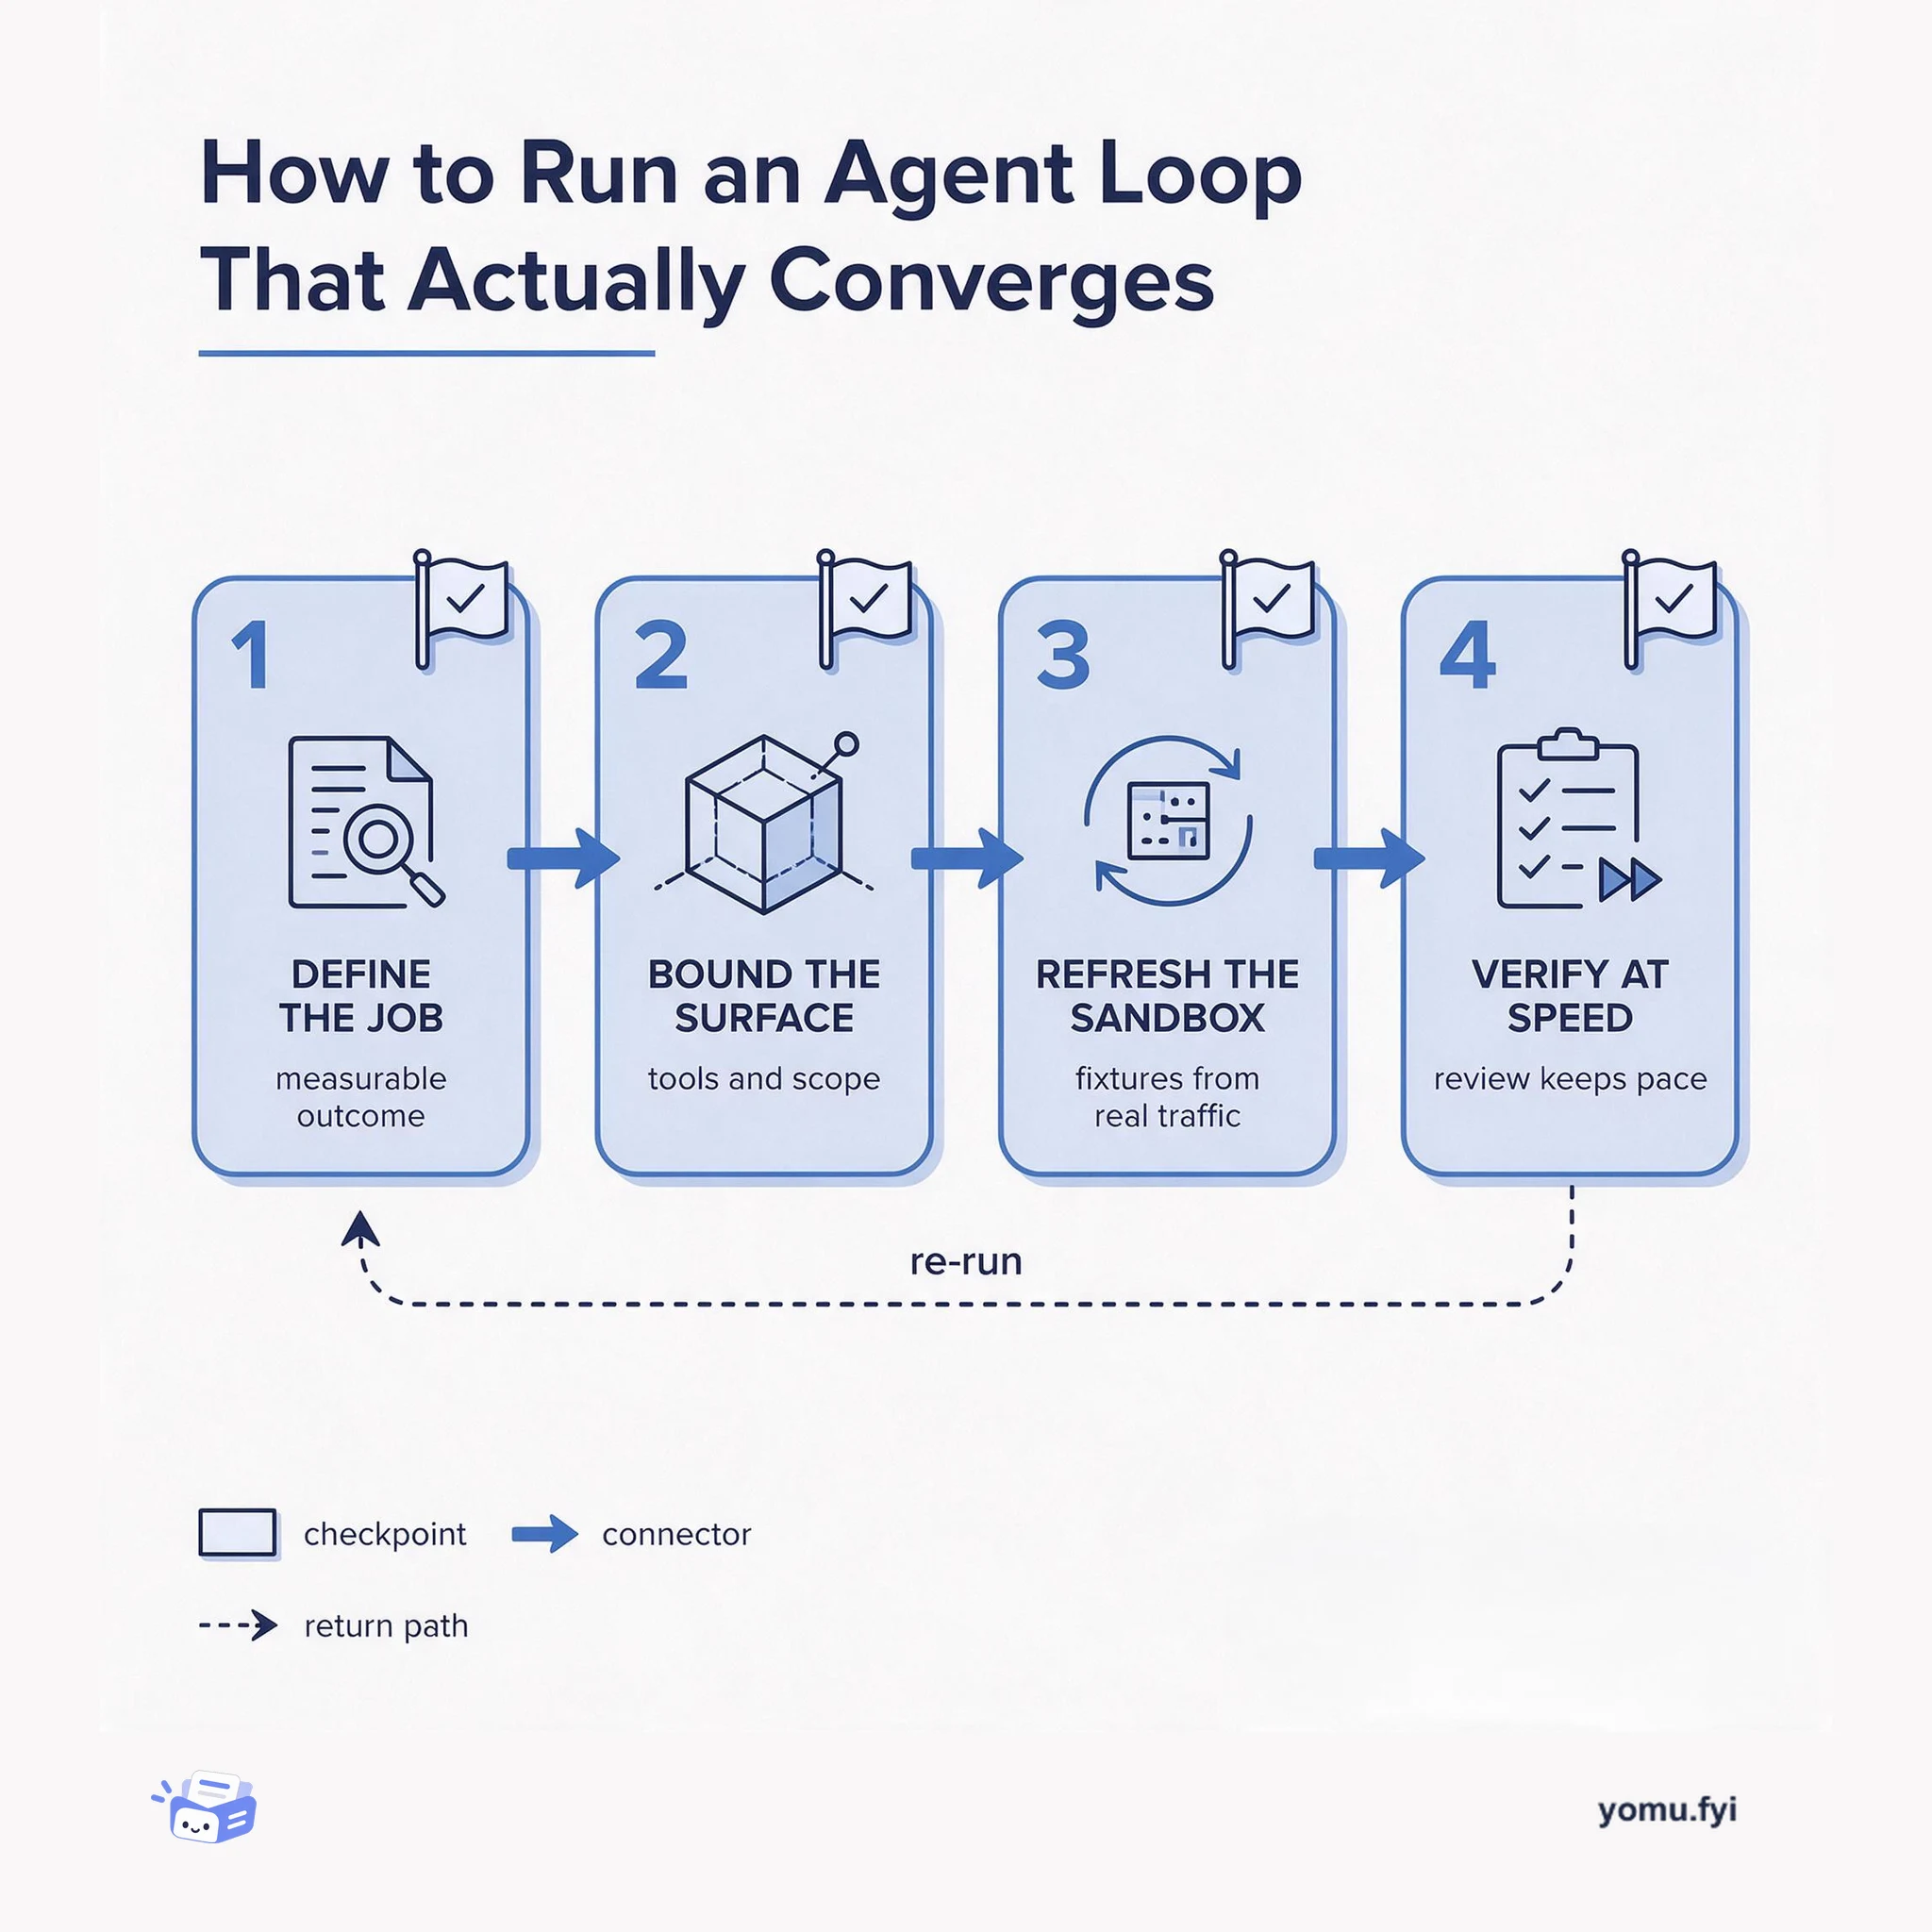
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
A four-step pattern for letting a document agent write validated aggregation pipelines instead of arbitrary code, so results come back shaped and tenancy stays enforced.
A document agent that calls fixed tools makes many round trips and floods its context with raw records. The alternative is to let the agent write an aggregation pipeline: a bounded query language the server can validate before it runs. The handler checks the pipeline, prepends a tenancy filter, executes it server-side, and returns only the reshaped result, so the agent gets comparisons and joins without holding whole collections. The trade-off is a narrower vocabulary: only a small set of stages is permitted, regex is not semantic search, and an unbounded limit can silently truncate answers. Use this pattern when the agent's job is to reshape and compare data under a strict security boundary, not when it needs general computation.
A code interpreter is a general execution surface, so every capability you grant is also an attack surface. A bounded pipeline language keeps the same expressive power for reshaping data while letting a handler validate the query before it runs. The trade-off is a smaller vocabulary: only a fixed stage set is permitted, so some operations need a second pass.
A handler validates the pipeline, prepends a tenancy filter, and only then executes it server-side. That filter is what keeps one tenant's documents out of another tenant's answer, and it is applied by the platform rather than trusted to the agent. The agent receives the reshaped result, not the raw collection.
Regex is not semantic search, so a fuzzy natural-language match will not behave the way an embedding search would. An unbounded or careless limit stage can silently truncate results, making an incomplete answer look complete. Agents also often need two passes, computing booleans or concatenating fields so comparisons happen in the database rather than in context.
The posts behind it
 Databricks · · Problem & solution
Coding agents working in parallel on shared databases create schema conflicts, test interference, and data exposure risks. Lakebase Postgres solves this with database branching, which creates an isolated copy of an entire database in under a second using copy-on-write. Each agent gets its own database branch via a post-checkout Git hook tied to a worktree, and each pull request gets an ephemeral branch through CI tooling. Schema changes are tracked in code with migration tools such as Drizzle or Alembic and promoted to the parent branch during deployment, not by merging database branches. Idle branches scale to zero, so running many concurrent agents incurs no compute cost for unused branches.
Databricks · · AnnouncementHL7v2 is the dominant healthcare messaging standard but is difficult to parse due to its nested, delimiter-encoded structure. Existing workarounds like converting to FHIR or using third-party engines add cost and latency. Funke, the successor to the open-source Smolder library, is a new open-source Python and PySpark library under the Databricks License that parses HL7v2 messages directly into native Spark types, preserving the full hierarchy losslessly. It deploys as a Databricks Asset Bundle with a Declarative Pipeline that uses Auto Loader to ingest raw messages into a Unity Catalog volume, then parses them into structured silver tables following the medallion pattern. The library supports all HL7 message types and versions, includes accessor helpers for extracting fields by segment and component, and ships with a demo using synthetic ADT events to illustrate end-to-end ingestion and gold table creation, including a live census and bed utilization dashboard.
 Stack Overflow · · Explainer
Level 5 covers operability for LLM systems: daily running, cost control, provider outage survival, and fast shutdown on misbehavior. A single gateway funnels all model traffic, measuring cost, routing requests, enabling failover, and hosting an instantaneous kill switch; a shared decision_id threads metrics, logs, traces, and the audit ledger. Observability supplements RED metrics with a decision layer capturing auto vs. human splits, guardrail blocks, judge disagreements, token spend per tenant and capability, and shadow-eval pass ratios via tiered structured logs. Cost controls attribute spending at the gateway per tenant and capability, with hard budget ceilings; optimization follows order: skip model, batch, cache, right-size, trim—each step profiled against quality. The platform spine includes stateless agent services, the gateway, an audit datastore, cache, secrets store, and object storage—scoped with least-privilege IAM and encryption, avoiding queues or vector stores until warranted.
 Intercom · · Explainer
This post from the Intercom blog tackles the difficulty of explaining technical concepts to non-technical customers, emphasizing that one misinterpreted comment can cause frustration for both sides. The author, a senior lead on customer support, positions herself as an API between developers and customers and has developed four tips from years of experience. She warns against making assumptions about a customer’s knowledge level and suggests using software that provides data like job title, tenure, and past conversations to tailor communication. She stresses using clear language, like discussing site speed instead of Mongo performance, and offering explanations in multiple formats such as numbered lists, images, or phone calls, using Pictionary as an analogy. Finally, she advises thinking like the customer by anticipating follow-up questions within the customer’s workflow rather than answering only the immediate query to prevent future confusion.
 MongoDB · · Problem & solution
Fixed-tool document agents suffer multiple round trips and context window bloat because each call returns raw data, and cross-document relationships require pulling all files into the context. The author’s solution lets the agent write a MongoDB aggregation pipeline instead of arbitrary code, avoiding the security risks of a code interpreter. A handler validates the pipeline, prepends a tenancy filter, and executes it server-side, returning only the reshaped result. The agent uses a two-pass approach, often computing booleans or concatenating fields with $addFields so comparisons happen in the database. Limitations include regex not being semantic search and $limit silently truncating results, but the bounded language of nine permitted stages improves both safety and accuracy.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
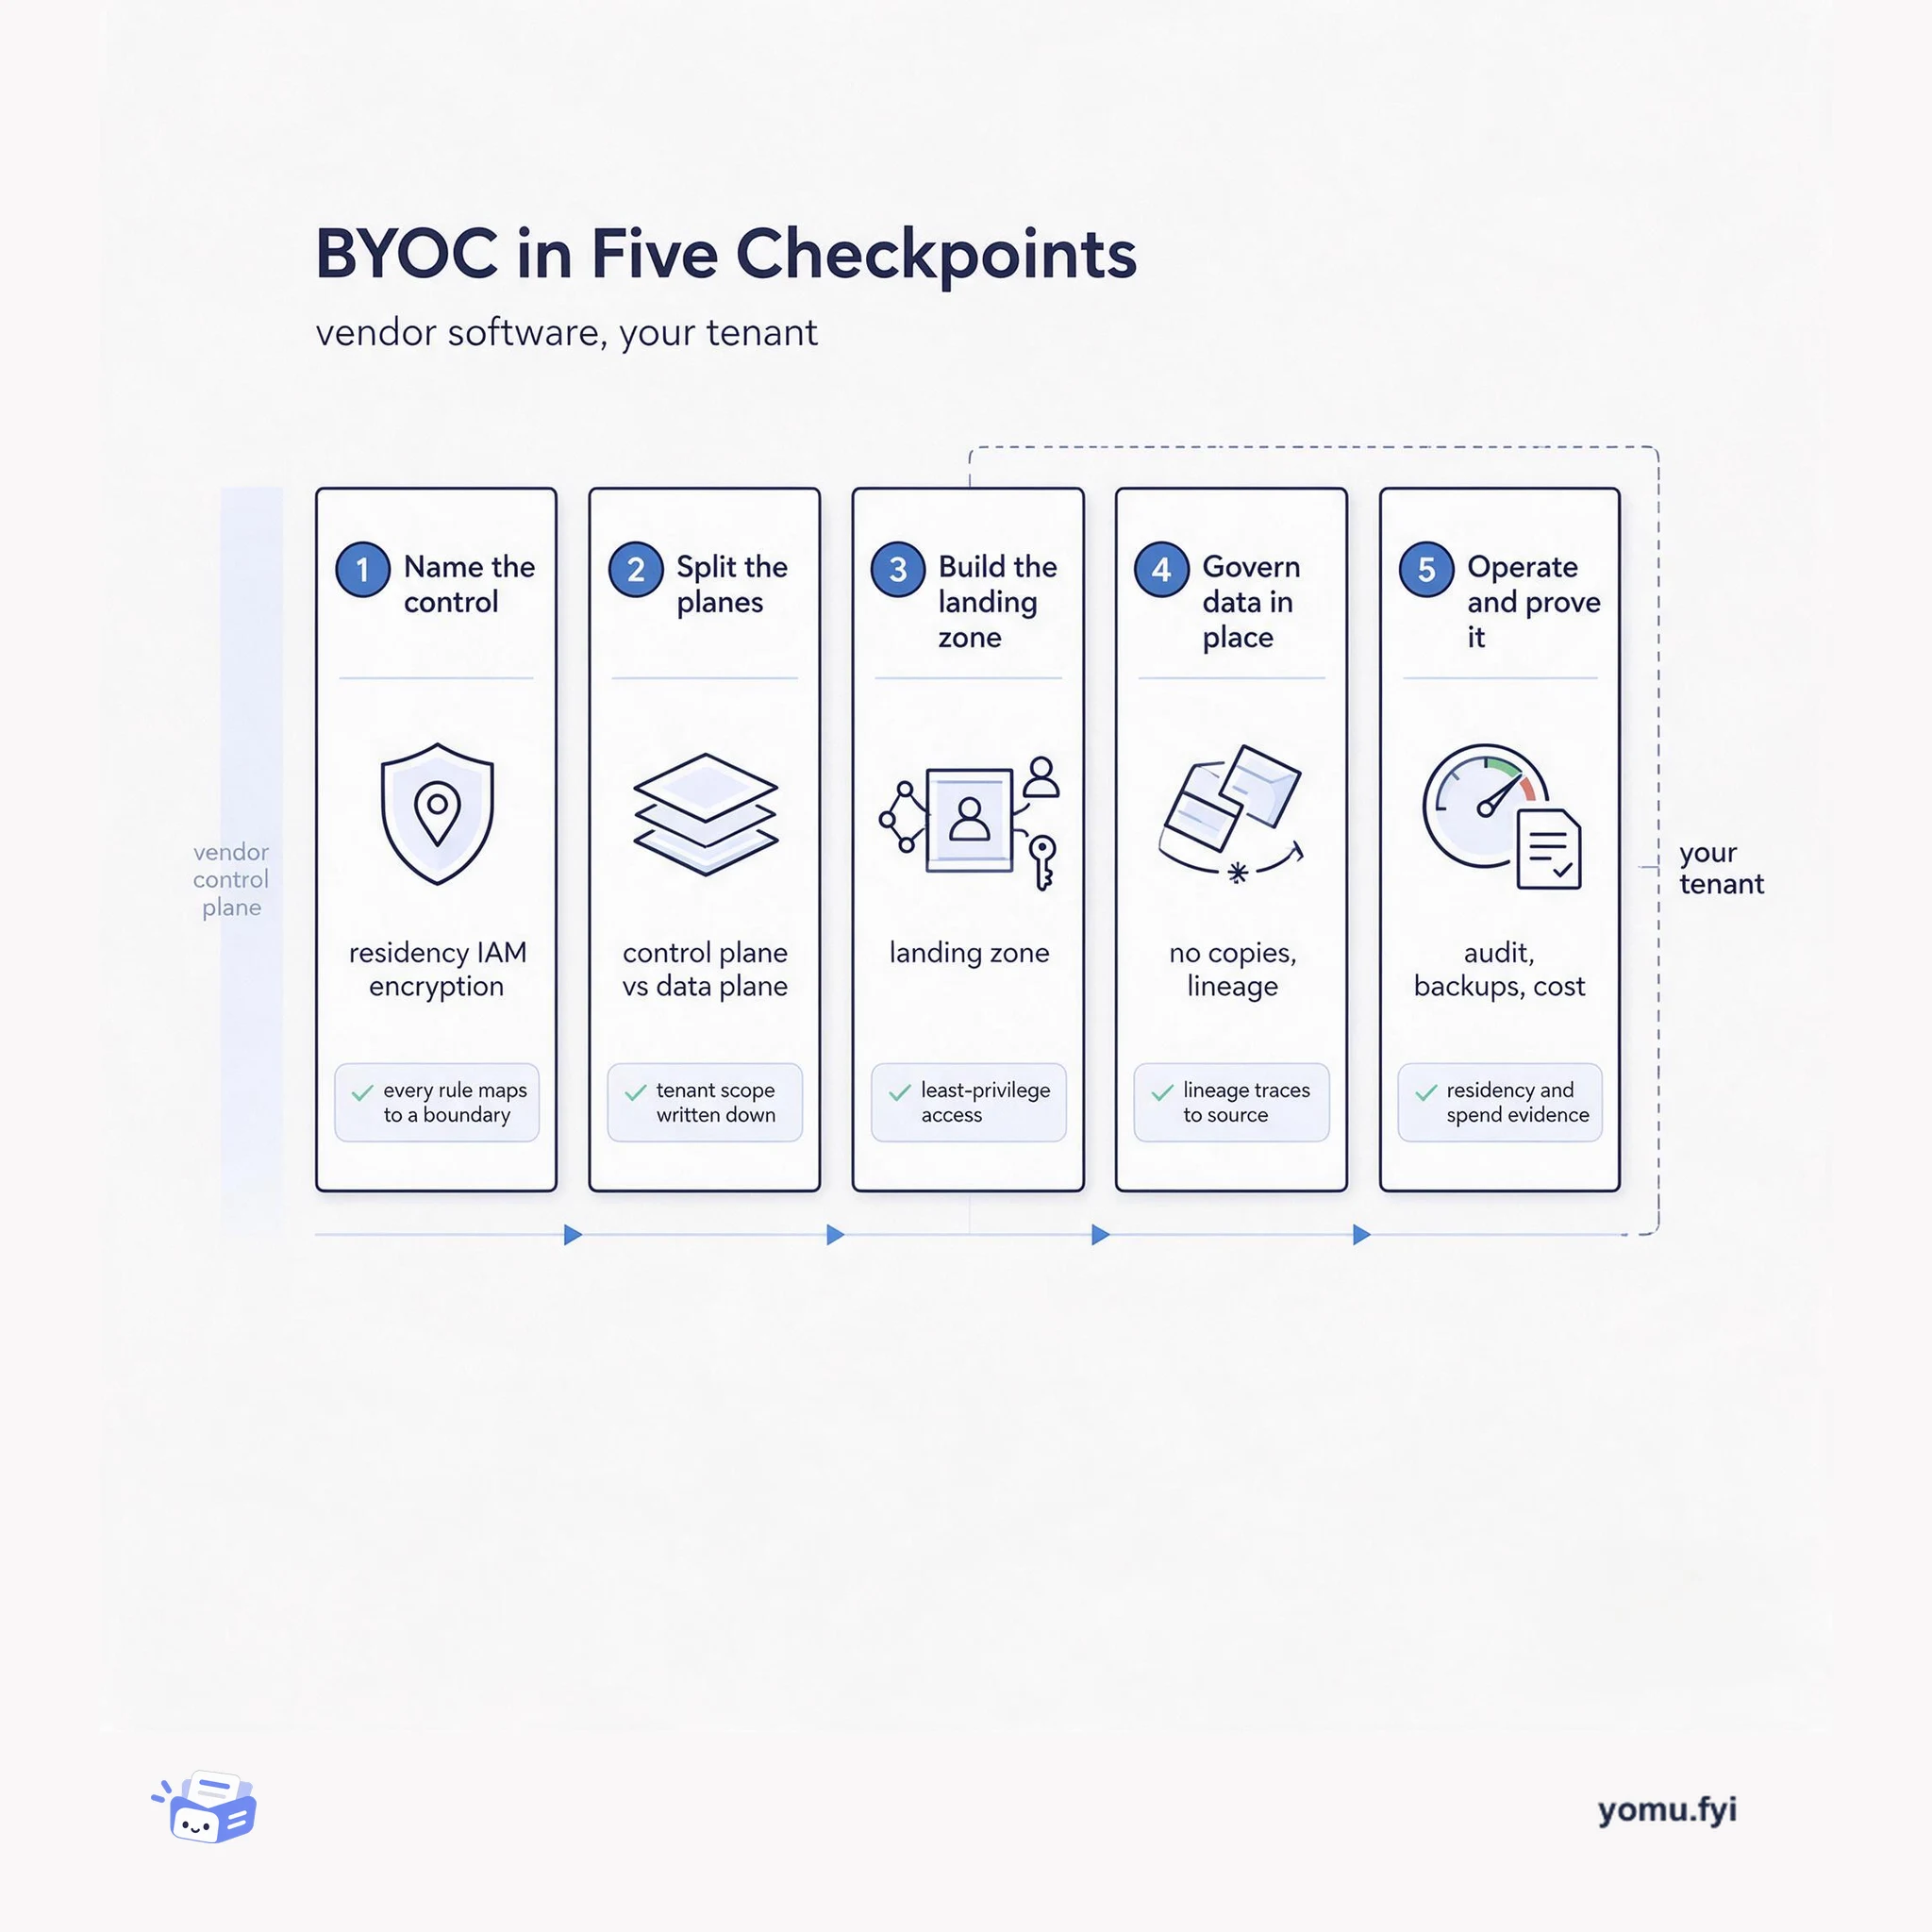
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.