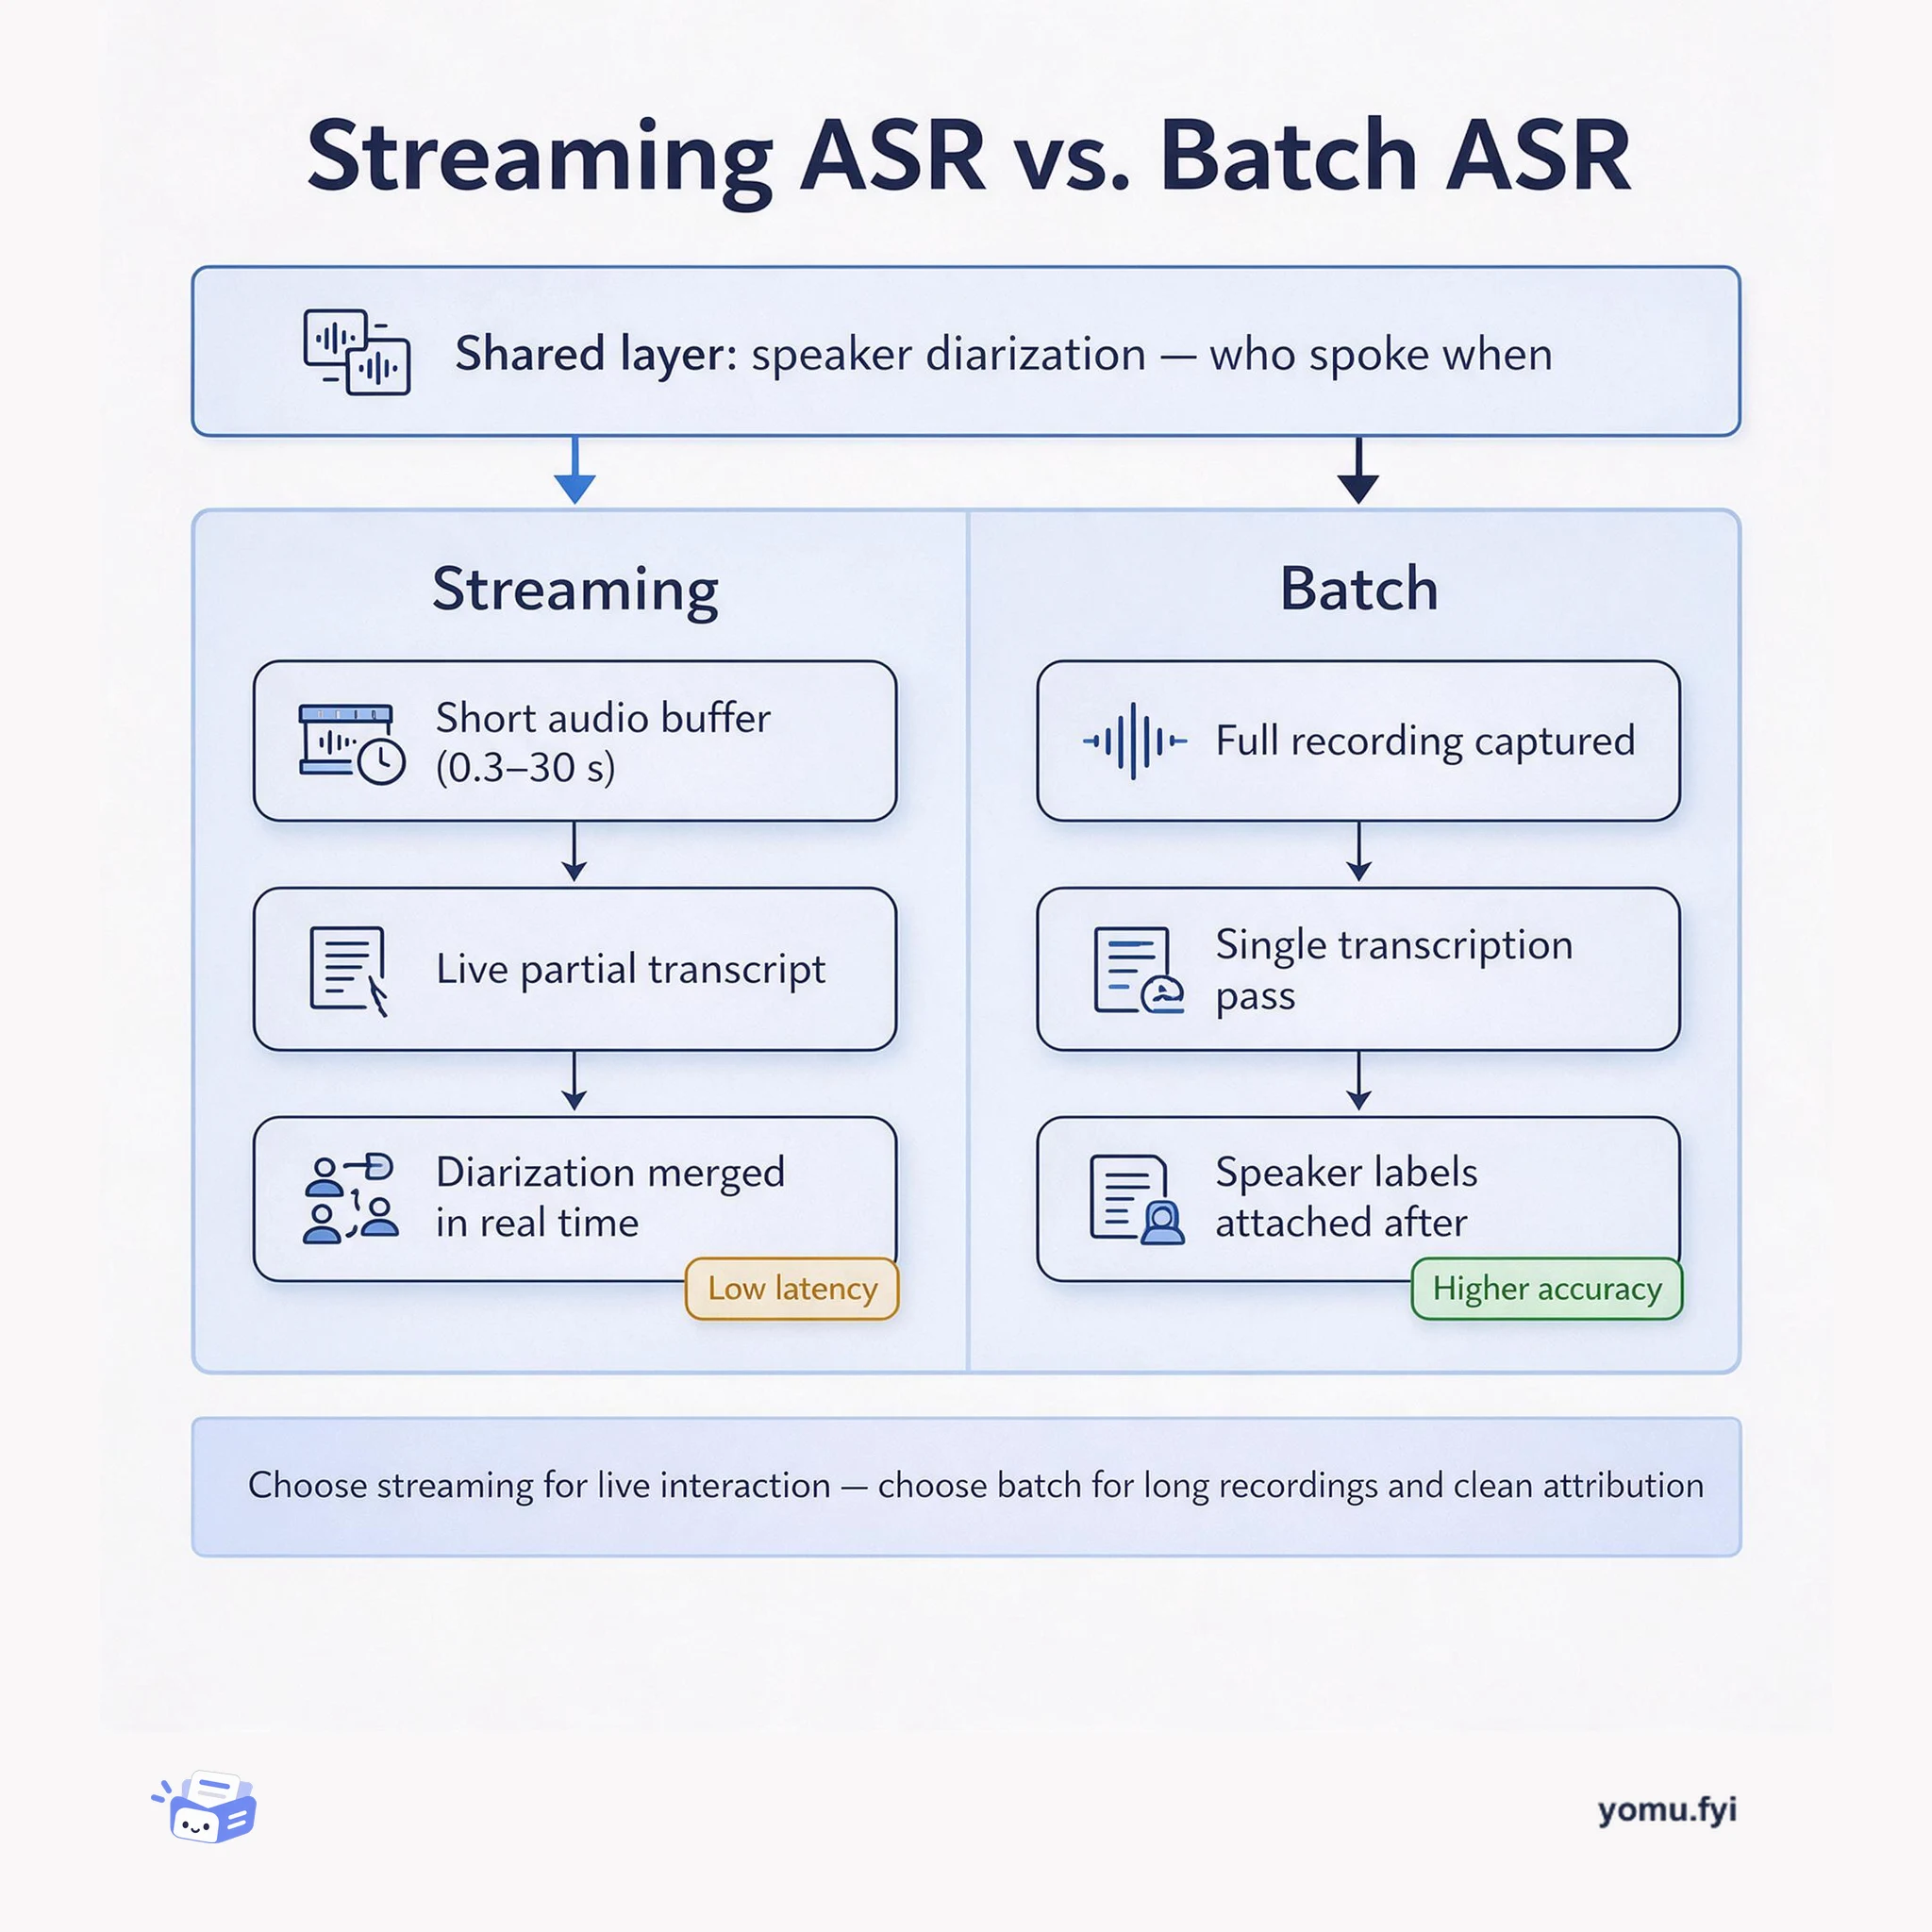
Streaming ASR vs. Batch ASR: The Buffer-Latency Trade-off
Streaming and batch ASR pipelines compared: how input buffer length, speaker diarization, and where audio is processed trade latency against transcript quality and privacy.
Loading…
Topic
1 post about Speaker Diarization. Every summary links to the original.
See the idea
Streaming and batch ASR pipelines compared: how input buffer length, speaker diarization, and where audio is processed trade latency against transcript quality and privacy.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
NVIDIA Nemotron 3 Diarization is an open-weight, 100M-parameter model that ranks #1 on VoiceArena’s Diarization-Bench leaderboard with a 14.72% Diarization Error Rate (DER). It classifies who spoke when in conversations, handling overlapping speech and supporting up to eight speakers across live and recorded audio. The model uses a Sortformer approach with arrival-order speaker labeling, a 31-layer Transformer encoder, and two memory mechanisms for streaming inference. It accepts 16 kHz single-channel audio and outputs a floating-point tensor of speaker-activity probabilities at a configurable time step. Developers can combine its timestamps with automatic speech recognition to produce speaker-attributed transcripts, with recommended input-buffer latencies ranging from 0.32 to 30.4 seconds.
The best engineering reads, once a week.

