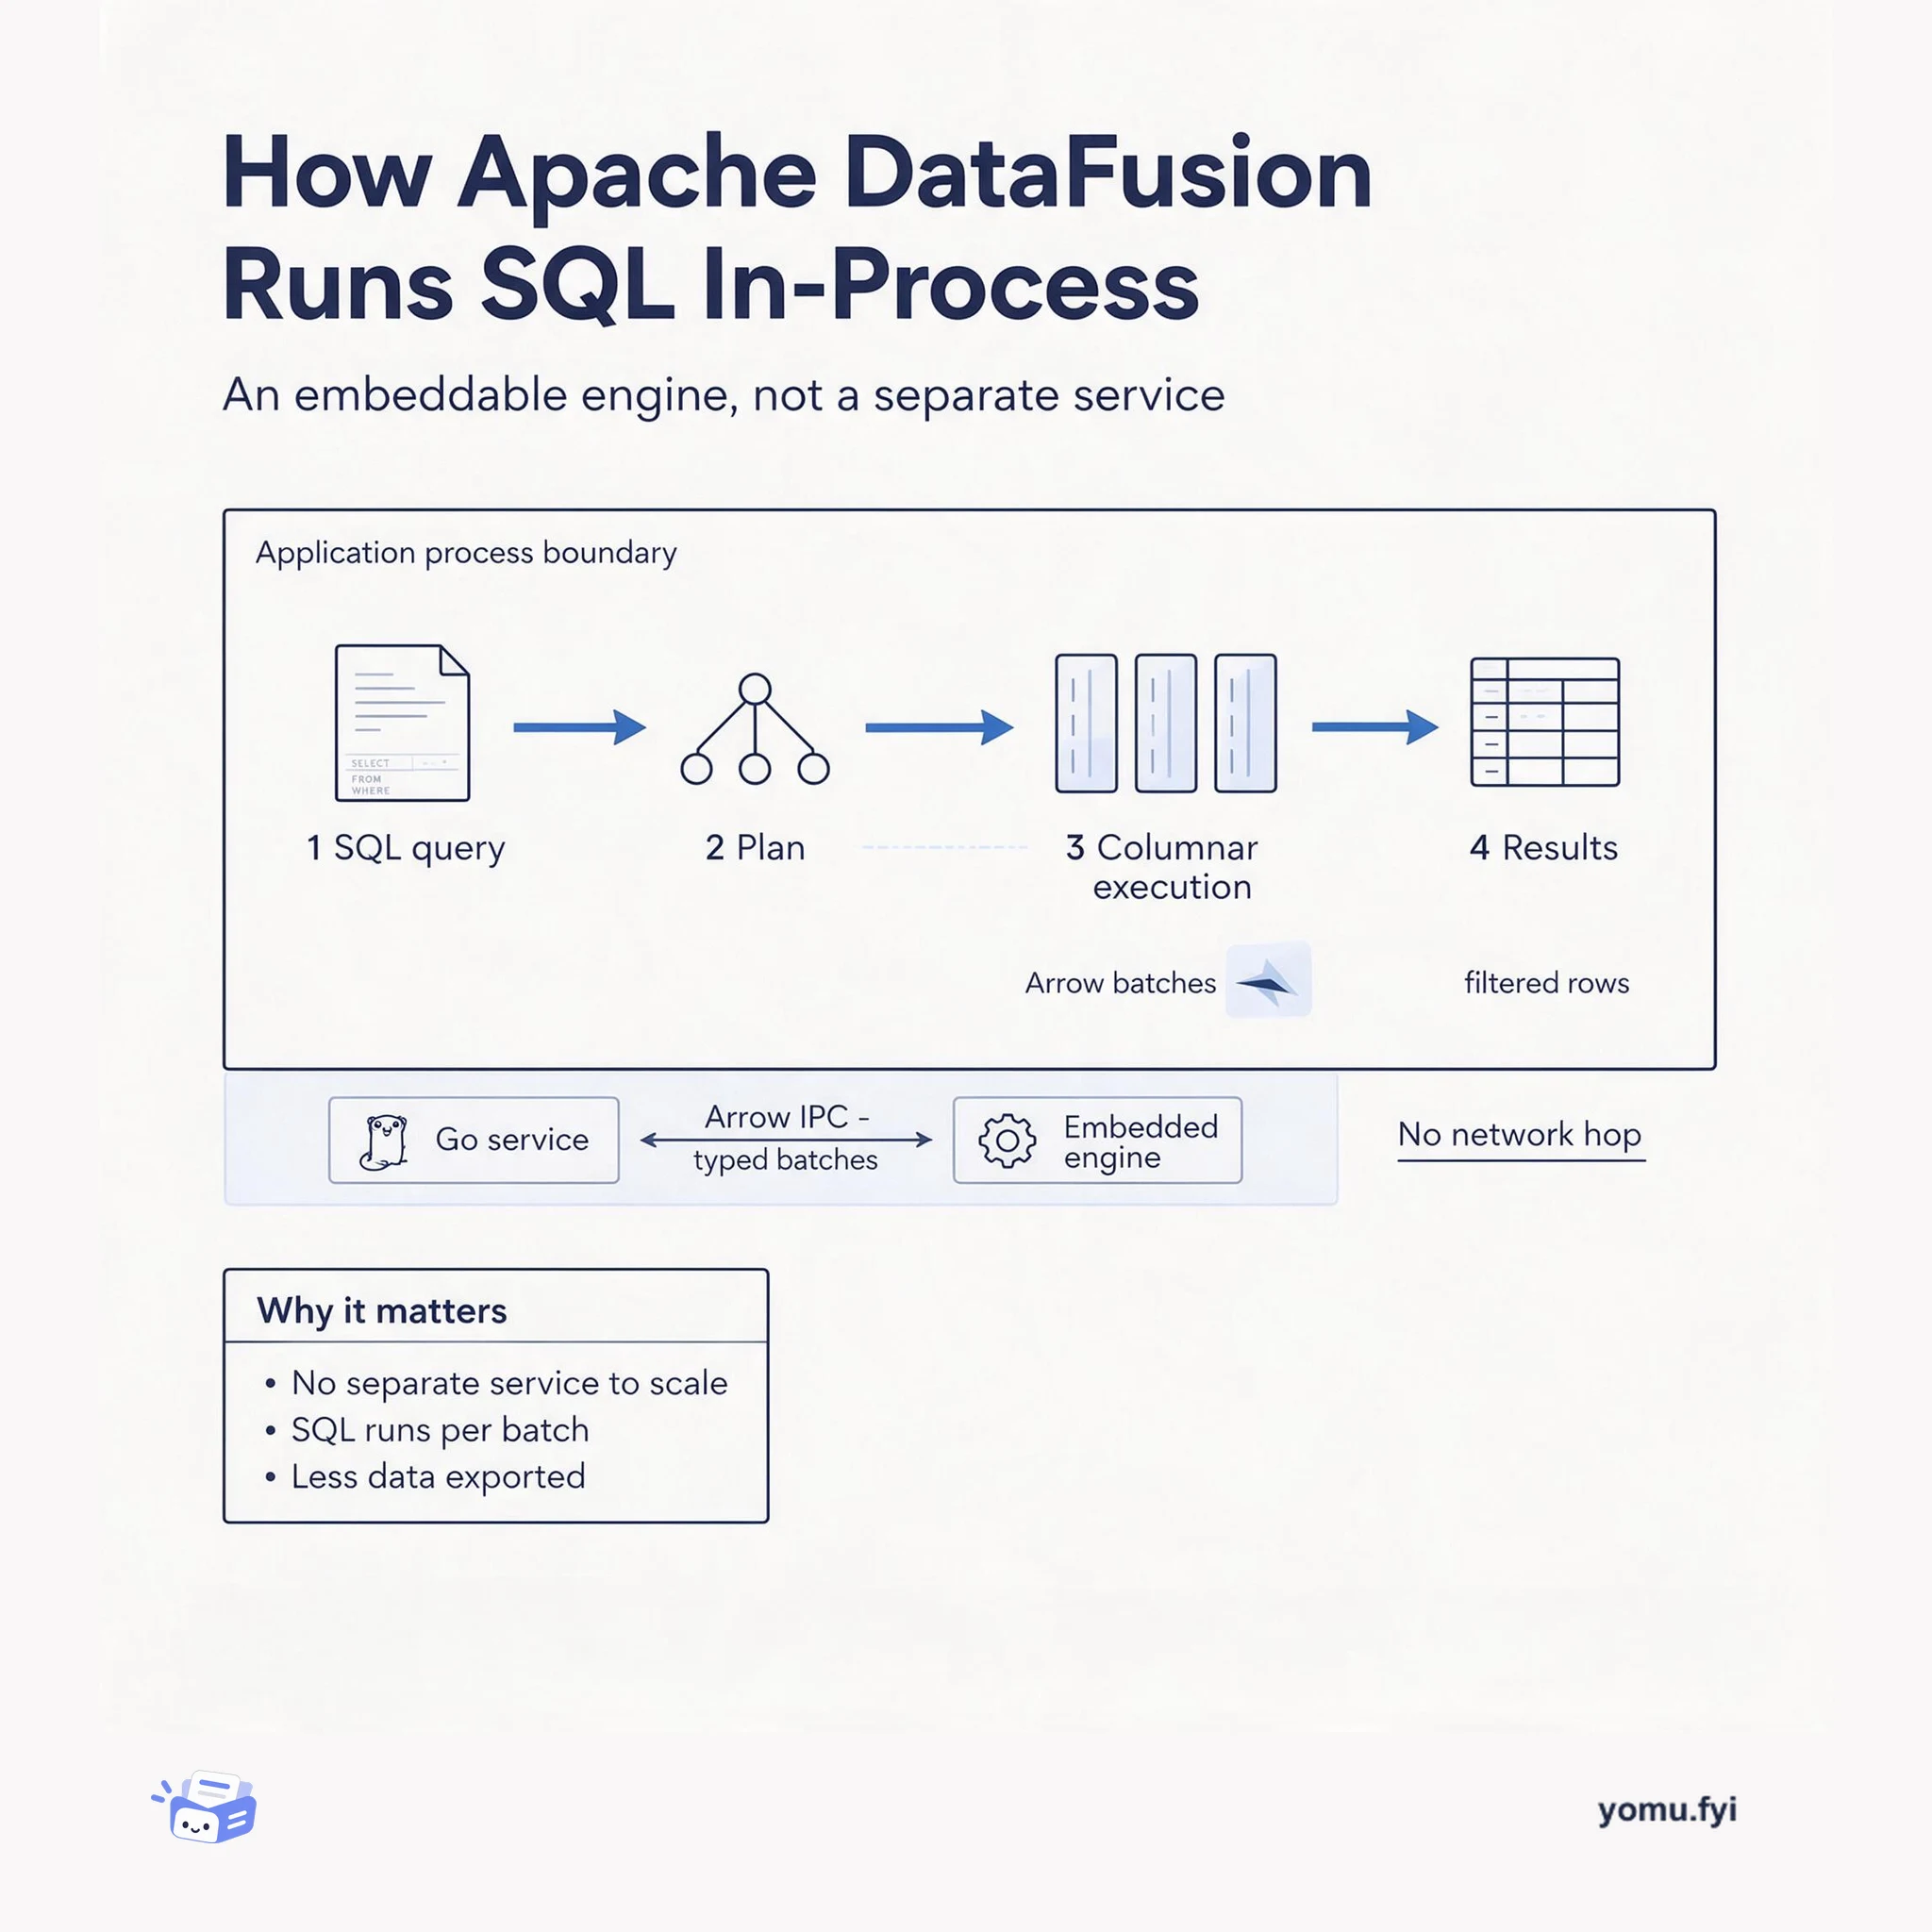
How Apache DataFusion Runs SQL In-Process
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
BYOK lets a system run on assets you supply — your model credential or your private knowledge — instead of the vendor's defaults. This walkthrough traces six steps from registration to an audited response.
BYOK is a custody pattern more than a feature: the platform keeps a reference to an asset you own, then resolves that reference inside the request path. Registration stores the reference — a secret for a credential, or a connector to a private knowledge source — and each incoming request carries a tenant identity that decides which asset is used. The platform then calls the model or retrieves from your knowledge store, composes the answer with retrieved context, and records lineage for the request. The payoff is that private material stays governed and auditable, while the cost is that rotation, permissions, and expiration become your operational responsibility.
Usually it keeps a reference, not the value. In the OpenShift Lightspeed example the header value lives in a Kubernetes Secret and the MCP server runs inside the cluster, while the governed data-sharing pattern publishes validated records to named recipients without centralizing raw records. The asset is resolved at request time rather than copied at setup time.
Track lineage to the source rather than moving raw records, as the county-profile platform does so every published number can be traced. Pair that with explicit access controls and markings plus audit lineage on shared records, and with a policy of reducing unnecessary data access while auditing third-party providers. Governance is what makes keeping custody workable instead of just private.
The posts behind it
 Databricks · · Explainer
The California Department of Health Care Services built the Behavioral Health Public County Profile on Databricks, a public dashboard consolidating behavioral health data from all 58 counties for nearly 40 million Californians. Launched on October 1, 2026, following the 2024 passage of Proposition 1, the dashboard supports the new Behavioral Health Services Act (BHSA) tying funding to statewide goals for outcomes, equity, and transparency. The platform uses Spark Declarative Pipelines and Lakeflow Connect for unified data ingestion, Semantic Views for standardized metrics across counties, and serverless compute to process data at scale without infrastructure management. It operates on a FedRAMP-authorized environment meeting federal security standards for health data, with data quality and lineage ensuring every number can be traced to its source. The County Profile enables public comparison of county plans, funding, service delivery, and performance measures, creating a feedback loop between policy intent and measurable outcomes for democratic oversight.
 Clickhouse · · Problem & solution
iSAM Funds, a UK-based systematic asset manager, built an options research platform on ClickHouse Cloud to handle the 10,000x data fan-out from underlying instruments to related options. Migrating from Postgres, the team achieved 35-50x compression and increased single-core ingestion from 8,000 to 800,000 rows per second, while ClickHouse’s native Apache Arrow support eliminated encoding reshuffling. ClickHouse’s columnar storage and vectorized execution made queries fast enough to run on demand, allowing the team to drop pre-computed rollups and materialized views and remove a layer of pipeline complexity. The managed service integrates with iSAM’s AWS footprint and enterprise authentication, pushes backups to iSAM’s own buckets for developer use, and lets them scale instances up for large backfills then down to control costs. The platform gives researchers fast, interactive access to full options history, shortening the time from hypothesis to tested strategy.
Databricks · · Problem & solutionThe Department of War cannot obtain cost transparency across its supply chain of over 200,000 suppliers due to reliance on manual data calls and fragmented spreadsheets. The proposed solution is a federated data exchange where each contractor publishes validated cost and pricing evidence from existing records to named government recipients using open-source sharing protocols. Databricks provides the platform, enforcing governance, access controls, CUI markings, and audit lineage without storing raw records centrally or requiring contractors to adopt Databricks. Small and mid-tier suppliers submit through validated intake forms that produce the same governed data contracts as large primes, requiring no new accounting systems. The reporting obligation already exists through CSDR, FlexFile, and DD Form 1921, so a pilot exchange can launch in months by defining two data contracts on a single program.
 Intercom · · Explainer
The post describes Intercom’s approach to maintaining app health in its App Store, inspired by a gardener tending individual plants in a Victorian garden. The main problem is that apps can become non-functional due to token expiration, third-party setting changes, or permission updates, all of which require customer action to fix. Intercom designed an app check system that requests the app’s status for each workspace, providing specific details about what is breaking and recommending two-click fixes to resolve the issue. Notifications to users with apps in unhealthy states are 2.5x more effective at generating active users than efforts to acquire entirely new app users. The key insight is that each app needs individual attention and tailored treatment, just as each plant in a garden requires unique care over time.
Intercom · · ExplainerGDPR is a major regulatory change affecting all companies with EU customers globally, standardizing data handling and requiring legal justification for processing and user data rights. A privacy ecosystem includes all vendors and integrations sharing customer data, and the weakest link determines overall security, as a breach anywhere damages trust. Companies must invest in security programs with penetration testing, continuous monitoring, vulnerability disclosure, staff training, and a healthy paranoia about risks to protect against external attacks and data breaches. They should track and reduce unnecessary data access, choose vendors with contractual assurances and mature security, audit third-party providers regularly, and establish developer guidelines for integrations. Active communication and transparency about data storage, retention, and deletion are crucial for customer trust, and properly trained sales and support teams can turn GDPR compliance into a marketing differentiator.
 Red Hat · · Tutorial
The article demonstrates extending Red Hat OpenShift Lightspeed by integrating the Red Hat Satellite MCP server and bring your own knowledge (BYOK). The Satellite MCP server exposes live operational data, such as kernel versions, CVEs, and errata, through the Model Context Protocol. BYOK enriches the assistant with private enterprise knowledge, enabling retrieval-augmented generation (RAG) to combine internal documentation with infrastructure data. The integration requires installing the OpenShift Lightspeed operator and deploying the Satellite MCP server in the openshift-lightspeed project. Authentication is handled by storing the header value in a Secret, and the MCP server expects clients to include appropriate Accept headers for the text/event-stream media type.
More like this
Apache DataFusion is an embeddable query engine: SQL goes in, runs as columnar Arrow batches inside your own process, and results come out without a separate service.
A model deployed on AKS is open by default. See how MaaS policies insert Authorino authentication and Limitador rate limits in front of vLLM, so bad keys and over-quota requests stop at the gate.
See how Caddy handles a request for a static site, from DNS resolution through container routing to file_server, and how TLS and redirects fit into the flow.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.